What Is AI Automation? Definition, Myths and Evidence

On this page
- Three architectures and who decides the next step
- The myth ledger and the sources behind each verdict
- Myth 1: AI automation means AI agents
- Myth 2: Rule-based automation is obsolete
- Myth 3: Everyone already uses AI, so you are late
- Myth 4: Ninety-five percent of AI projects fail
- Myth 5: AI has one hallucination rate
- Myth 6: Temperature 0 makes outputs repeatable
- Myth 7: AI automation means replacing staff
- Myth 8: The model is the big cost
- Myth 9: More autonomy means more value
AI & Automation
What is AI automation? It is a business process that runs when a trigger fires and contains at least one step where a language model reads, classifies, extracts, writes or decides; ordinary deterministic code handles the surrounding work. Once that model step enters the chain, reliability becomes a rate you measure: model outputs can vary, and errors can compound across steps.
The most useful first question is who decides what happens next. Code can prescribe every step while a model labels an email, or a model can choose tools and keep working until it considers a task complete. Those designs need different tests and permissions, even when a vendor sells both as an agent.
Three architectures and who decides the next step
Business AI automation describes a process, not a particular product. A scheduled invoice reader qualifies when its model extracts fields and code validates them, while a conventional form-to-CRM integration contains no model and remains ordinary workflow automation.
Anthropic distinguishes predefined code paths from systems where the model directs its own process and tool use. Its engineering guidance on workflows and agents recommends starting with the simplest workable solution, including a single model call when that is sufficient.
| Observable property | Deterministic workflow | Workflow with LLM steps | Tool-using agent |
|---|---|---|---|
| Who decides the next step | Code written in advance | Code written in advance; the model supplies a result | The model chooses tools and subsequent steps |
| Same input, same output | Yes, given unchanged state and dependencies | Not guaranteed | Not guaranteed |
| How you test it | Test each branch and integration | Label representative inputs and score each model step | Score complete runs and inspect actions |
| Typical failure | Changed input format breaks a rule or integration | A plausible wrong field passes downstream | Wrong actions, loops or excessive spending |
| Business example | A form submission creates a CRM contact | A model labels an email; code routes it | A model investigates an order and proposes a refund for approval |
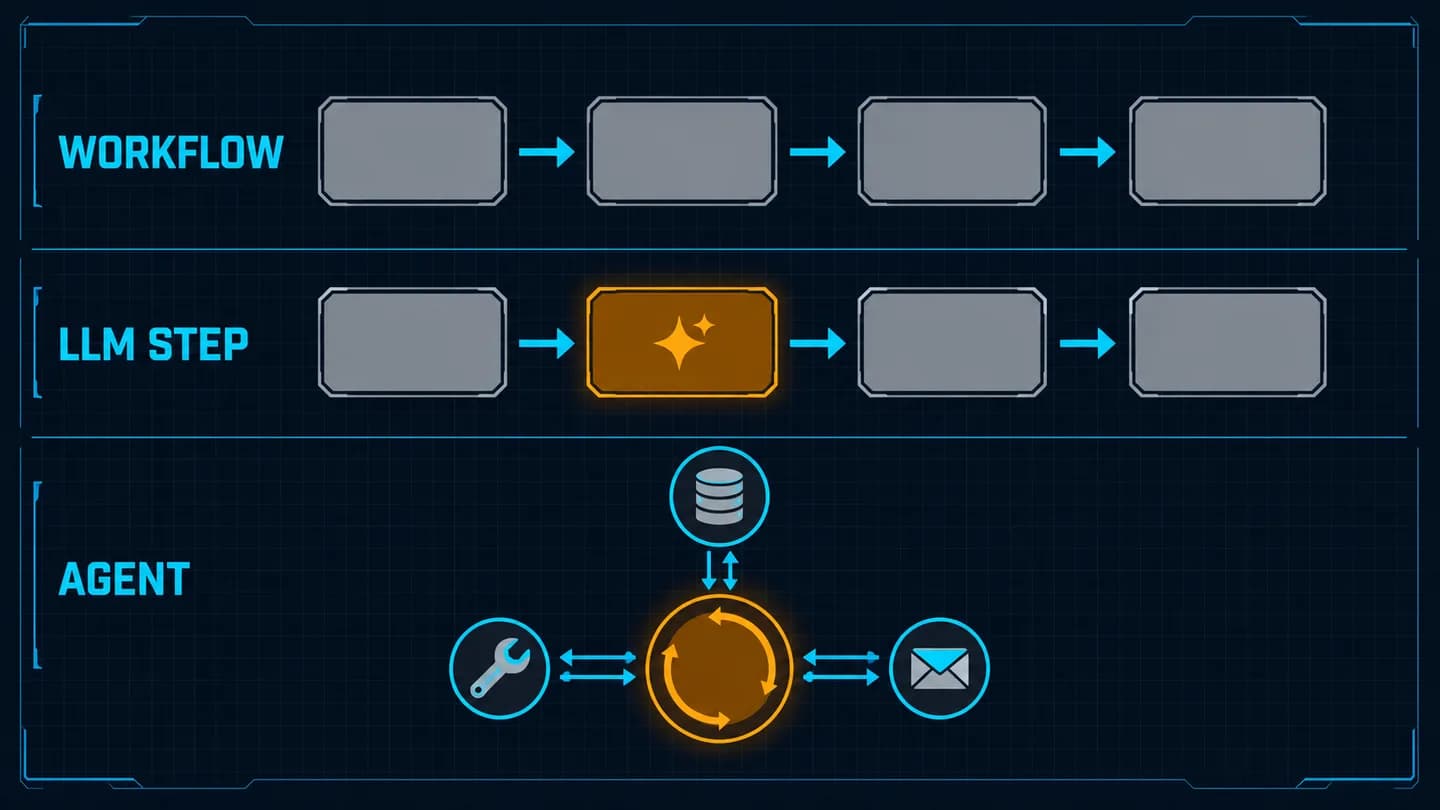
Follow who selects the next action. Adding a model inside a fixed path does not give it control over the whole process.
The myth ledger and the sources behind each verdict
The claims here mix architectural definitions with survey results and benchmark scores. Their verdicts depend on what the named source actually measured, not how confidently someone repeated the headline.
| Common claim | Verdict | Source that tests the claim |
|---|---|---|
| AI automation means AI agents | Wrong | Anthropic; OpenAI's practical agent guide |
| Rules are obsolete | Wrong | OpenAI's criteria for using agents |
| Everyone already uses AI | Overstated | Census BTOS; McKinsey survey coverage |
| Ninety-five percent of AI projects fail | Misquoted | MIT NANDA's preliminary report |
| AI has one hallucination rate | Task dependent | Vectara; SimpleQA; Stanford legal-tool study |
| Temperature 0 makes outputs repeatable | Wrong | Thinking Machines' inference experiment |
| AI automation means replacing staff | Overstated | Census working paper CES 26-25 |
| The model is the big cost | Workload dependent | Our hypothetical email-triage calculation |
| More autonomy means more value | Unproven | Vendor design guidance; whole-run evaluation |
Who answered? What counted as adoption or failure? Which time window did the question cover? How was the sample weighted?
Myth 1: AI automation means AI agents
Verdict: wrong. A model can perform a bounded step without controlling the workflow.
Anthropic's definition of a workflow puts LLMs and tools inside predefined code paths. Its agent definition gives the model control over its process and tool use, making the distinction about execution authority, not whether the interface has a chat box.
OpenAI's A practical guide to building agents defines agents as systems that independently accomplish tasks on your behalf. It explicitly excludes simple chatbots, single-turn model applications and sentiment classifiers when the model does not control workflow execution. A classifier can be useful AI automation without qualifying as an agent.
That distinction changes procurement. An email classifier needs permitted labels, a test set and a fallback for uncertain cases; an agent that can inspect orders and contact customers also needs limits on which tools it can call and when it must stop.
What to do about it
- Ask the supplier to show the execution path for one successful run and one failed run.
- Mark every point where code chooses the next step and every point where the model chooses it.
- Start with one narrow AI use case whose input, permitted output and success condition you can write down.
- Require a demonstration that an uncertain result reaches a review queue without triggering an external action.
Myth 2: Rule-based automation is obsolete
Verdict: wrong. Fixed rules remain appropriate wherever the decision can be specified and tested.
OpenAI's agent guide recommends agents for complex judgment, difficult-to-maintain rules or substantial unstructured data. It also says a deterministic solution may suffice when those criteria are absent. That is a fairly direct rebuttal from a company selling the models.
A language model can read an invoice description, but code should still check that the currency is permitted and the supplier identifier exists. A schema can verify that an amount is numeric; it cannot establish that the model copied the correct amount. Structural validity and factual correctness require separate checks.
My recommendation for a company with 10 to 200 people is to keep the process fixed wherever possible and insert a model at the language problem. Make the boundary visible: the model proposes a classification or extraction, then code checks whether that result is eligible to proceed.
What to do about it
- Write the existing branches as explicit conditions, including missing-data cases.
- Mark the steps that require interpreting language; leave calculations and permission checks in code.
- Validate required fields, allowed values and business constraints before accepting model output.
- Test duplicate triggers and retries to confirm they do not create duplicate records or payments.
Myth 3: Everyone already uses AI, so you are late
Verdict: overstated. Adoption varies with the business population, the question and the weighting.
The Census BTOS downloads report that 24.6% of US employer businesses used AI in any business function during the previous two weeks, for the reference period 21 September to 4 October 2026, published 22 October 2026. That is roughly one in four businesses, with a specific recall window.
McKinsey's The State of AI, published 25 August 2026, reports that nearly nine in ten respondents report regular use of AI in at least one business function. The survey ran from 4 May to 8 June 2026 and included 1,719 participants across 97 nations; 36% came from organizations with revenue above $1 billion. It is a respondent survey with substantial large-organization representation, not a count of US employer businesses.
Both results can be true. A manager reporting that one department uses a chat assistant answers a different question from a nationally representative business survey asking about use in the last two weeks.
| Measure | Population and window | Reported result |
|---|---|---|
| Latest Census BTOS reading | US employer businesses; 21 September to 4 October 2026 | 24.6% used AI |
| Census AI supplement, firm-weighted | Businesses; November 2025 to January 2026 | 18% used AI |
| Same supplement, employment-weighted | Same period, weighted by employment | 32% used AI |
| McKinsey survey | Global organizational respondents; 4 May to 8 June 2026 | Nearly nine in ten reported regular use |
Firm weighting gives each business representation; employment weighting gives larger employers more influence. The 18% and 32% results demonstrate how changing the denominator changes the answer without changing the underlying period.
There is also a break in the Census series. The old question asked about AI “in producing goods or services,” and reported use rose from 3.5% to 10% between September 2023 and November 2025. The broader question asks about any business function; its first reference period, 3 to 16 November 2025, recorded 17.3%.
A Census working paper on AI diffusion attributes the jump to the wording revision, adoption during the federal funding lapse and the second AI supplement. Its 18% supplement estimate is a separate measure, not the next point in a continuous old-wording series. The paper has not undergone the review accorded official Census publications.
Size also matters. Census's May 2026 story reported 37% use among firms with at least 250 employees, 32% among those with 100 to 249, and less than 20% among firms with four or fewer employees. Among adopting firms in the working paper, 57% used AI in three or fewer of 15 business functions.
What to do about it
- Record the source population and recall window beside any adoption figure used in a proposal.
- Check whether comparisons cross the Census wording change.
- Inventory your own AI use by business function, including individual chat-tool use.
- Require a measurable operational problem before approving a project; competitor adoption is not a baseline.
Myth 4: Ninety-five percent of AI projects fail
Verdict: misquoted. The figure concerns self-reported sustained business impact from task-specific enterprise GenAI tools. It is not a technical failure rate for AI projects generally.
MIT NANDA's The GenAI Divide reviewed over 300 public initiatives, interviewed representatives from 52 organizations and collected 153 senior-leader survey responses at four conferences. The research period was January to June 2025; that does not mean every project received six months of observation.
The executive summary of the hosted copy of the preliminary report says “95% of organizations are getting zero return” and states: “Just 5% of integrated AI pilots are extracting millions in value, while the vast majority remain stuck with no measurable P&L impact.” The headline comes from the report itself, and “95% of pilots” is close to its own framing. The unsupported jump is turning that claim into “95% of AI projects fail.”
Its task-specific GenAI funnel reports 60% investigated, 20% piloted and 5% successfully implemented. Success meant users or executives reported marked, sustained productivity and/or P&L impact. The report cautions that its figures are directional and interview-based, with varying sample sizes and success definitions.
General-purpose tools had a different funnel: 80% investigated, 50% piloted and 40% implemented. The report also gives about 83% pilot-to-implementation conversion for generic chatbots. Those results reinforce the need to keep the tool category and measured outcome attached to the percentage.
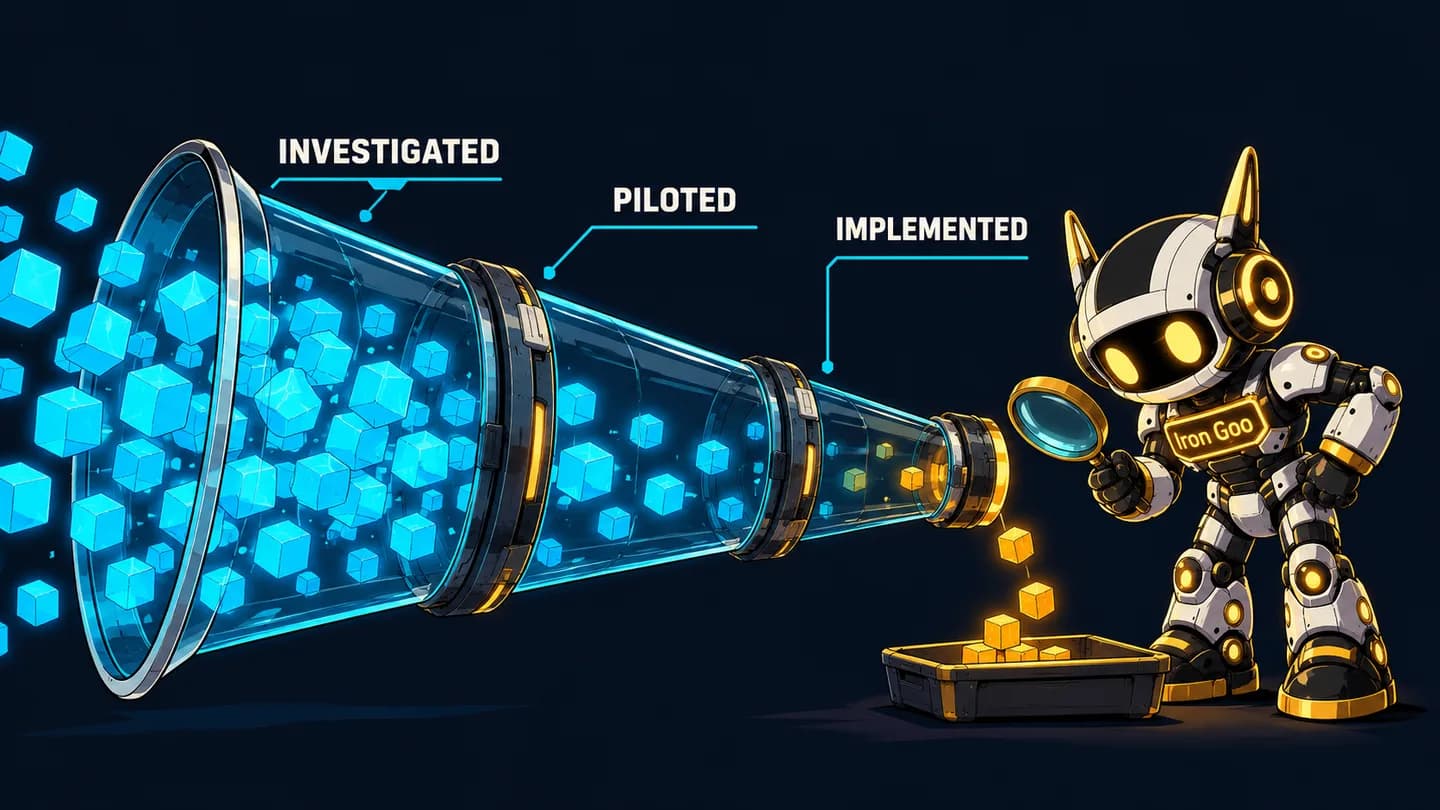
The 5% sits at the bottom of the task-specific enterprise-tool funnel. Success reflects reported sustained impact, not a technical pass rate for every AI project.
Other failure figures need the same treatment. RAND's The Root Causes of Failure for Artificial Intelligence Projects and How They Can Succeed cites “more than 80 percent” as an estimate from elsewhere; RAND's own research consisted of 65 interviews with experienced data scientists and engineers.
As reported, Gartner predicted that at least 30% of generative AI projects would be abandoned after proof of concept by the end of 2025. Its later prediction put cancellation above 40% for agentic projects by the end of 2027. Predictions are not observed failure rates.
An S&P Global Market Intelligence survey of more than 1,000 respondents in North America and Europe, reported by CIO Dive on 14 March 2025, found that 42% of companies abandoned most AI initiatives. The average organization scrapped 46% of proofs of concept before production. “Companies abandoning most initiatives” and “initiatives abandoned” are different measures.
RAND's reported interview findings offer a more useful diagnostic: misunderstood problems, unsuitable data, technology-first decisions, inadequate infrastructure and tasks beyond the system's capabilities. A working demo can survive all five problems long enough to impress a meeting.
What to do about it
- Write a success definition with a baseline, measurement owner and observation period.
- Separate technical correctness, production deployment and sustained financial impact in the project scorecard.
- Test access to representative data before approving the build.
- Record a stopping rule, such as review costs exceeding the value of the time saved.
Myth 5: AI has one hallucination rate
Verdict: task dependent. A summarization score cannot tell you the error rate of an invoice reader or a legal-research tool.
The Vectara Hallucination Leaderboard, updated 22 October 2026, showed rates from 1.8% to 24.2% across listed models. Its task is summarization faithfulness: whether a summary introduces unsupported facts, judged by Vectara's HHEM-2.3 model.
The dataset contains more than 7,700 articles, with source lengths from 50 to 24,000 words and models instructed to keep summaries within 20% of source length. The judge is itself a model, and a system that simply copies source text could score perfectly on this measure while producing an unhelpful summary. The leaderboard does not establish which vendor is most accurate overall.
| Evaluation | What it measures | Result |
|---|---|---|
| Vectara leaderboard | Unsupported facts in document summaries | 1.8% to 24.2% across listed models |
| SimpleQA, gpt-5-thinking-mini | Short factual answers, including abstentions | 52% abstention; 22% accuracy; 26% error |
| SimpleQA, o4-mini | Same task and categories | 1% abstention; 24% accuracy; 75% error |
| Stanford legal-tool benchmark | Reliability of answers from three legal-research products | 17% to 33% hallucination rates |
The SimpleQA numbers were reported in OpenAI's Why language models hallucinate post of 5 September 2025. Its associated paper argues that training and evaluation can reward guessing over admitting uncertainty. Here, answering nearly everything produced slightly more correct answers and many more wrong ones.
Retrieval does not remove the need to test. Stanford's study of legal-research tools, submitted 30 May 2024, evaluated Lexis+ AI, Westlaw AI-Assisted Research and Ask Practical Law AI. The tools hallucinated between 17% and 33% of the time on its benchmark despite claims associated with retrieval-based reliability.
A real automation has at least four error locations. The model can misread or invent a fact; retrieval can supply the wrong document; workflow code can accept an unchecked result; changed inputs can invalidate previous testing. Model benchmark scores do not measure all those failures.
For a hypothetical error-rate estimate, assume an expected error rate of 5%, a margin of plus or minus 3 percentage points and 95% confidence. The normal-approximation sample calculation is n = 1.96² × 0.05 × 0.95 / 0.03² = 202.75, so round up to 203 labeled items. This is planning arithmetic, not a guarantee for a biased sample.
Zero observed errors also needs interpretation. The rule of three puts the approximate 95% upper bound at 3/n: zero errors in 100 independent, representative items still permits a true error rate around 3%. A hundred clean examples are encouraging; they are not a warranty.
What to do about it
- Build a labeled sample from real input categories, including incomplete and unusual cases.
- Record unsupported answers separately from abstentions and correct answers.
- Inspect the source context and downstream action for each error.
- Measure review time as well as correctness, and retest when the input distribution changes.
Myth 6: Temperature 0 makes outputs repeatable
Verdict: wrong. Removing sampling randomness does not guarantee identical output from the entire serving system.
In its 10 September 2025 inference experiment, Thinking Machines ran 1,000 temperature-0 completions using Qwen3-235B-A22B-Instruct-2507 and the same Richard Feynman prompt. It obtained 80 unique outputs, identical through the first 102 tokens before diverging.
The cause was lack of batch invariance: server load changes batch size, and numerical kernels can change floating-point reduction order with it. This was not randomness in token sampling. With batch-invariant kernels, all 1,000 completions matched; the result does not establish identical behavior across every provider.
Repeatability and correctness are separate properties anyway. A system can repeat the same wrong answer perfectly, while a useful drafting system can produce different acceptable wording.
What to do about it
- Repeat important test inputs and score semantic correctness separately from exact text matches.
- Log the model identifier, prompt version, available inference settings and retrieved context for each run.
- Use fixed allowed outputs for classification and validate them in code.
- Rerun the evaluation after model or serving changes, even when the prompt stays unchanged.
Myth 7: AI automation means replacing staff
Verdict: overstated. Available firm reports show substantial task augmentation and much less reported employment reduction.
The Census working paper CES 26-25, analyzing the BTOS AI supplement for November 2025 to January 2026, found that 52% of AI-using firms reported no task effect. Among AI-using firms that reported a task effect, about 66% used AI only to augment tasks. AI-related employment decreases were reported by 2.0% of AI-using firms on a firm-weighted basis, or 2.4% employment-weighted. These are working-paper findings, not official statistics or a forecast that employment effects will remain small.
Task time is also different from removable headcount. Hypothetically, saving ten people 20 minutes each produces 200 minutes of capacity, but those minutes may sit across different roles and times of day. Review work and exception handling consume part of the saving.
Responsibility survives automation too. In Moffatt v. Air Canada, decided 14 February 2024, the BC Civil Resolution Tribunal found negligent misrepresentation after the website chatbot said a bereavement fare could be claimed retroactively.
The tribunal rejected the argument that the chatbot was responsible for its own statements. It awarded C$650.88 in damages plus interest and fees, about C$812 in total. For a customer-facing process, a wrong automated answer can become the company's problem.
What to do about it
- Measure net time saved after review, corrections and exception handling.
- Assign a named owner to customer-facing answers and policy changes.
- Send high-risk or irreversible actions to a person using explicit human oversight and guardrails.
- Verify that reviewers can inspect the evidence and stop the action before it happens.
Myth 8: The model is the big cost
Verdict: workload dependent. In a modest text workflow, platform billing and review labor can dwarf inference charges.
Our AI automation cost guide uses a hypothetical 3,000-email monthly triage example, with prices read 23 October 2026. Under its cache-hit assumptions, model charges are about $0.45, the platform costs $129, and human review costs $199.94.
Those listed recurring costs total $329.39. The model represents about 0.14% of that subtotal; the platform is roughly 287 times the model charge, and review about 444 times. These are arithmetic comparisons from one hypothetical setup, not a price promise for your workflow.
Long contexts, expensive models and repeated tool calls can change the balance. The useful unit is total cost per completed, accepted task, including the failed attempts and the person's correction time.
What to do about it
- List platform charges, inference, review labor and maintenance separately.
- Record retries and rejected outputs in the cost calculation.
- Divide total operating cost by accepted completed tasks.
- Check the review-time assumption against timed samples before forecasting savings.
Myth 9: More autonomy means more value
Verdict: unproven. Additional decision freedom needs to earn its cost through better completed outcomes.
Anthropic says agentic systems, including workflows and agents, often trade latency and cost for better task performance. Separately, it warns that the autonomous nature of agents means higher costs and the potential for compounding errors. OpenAI's practical guide recommends human intervention when failure thresholds are exceeded or actions are sensitive, irreversible or high stakes. Neither recommendation treats maximum autonomy as the objective.
A hypothetical chain makes the risk visible. Assuming independent steps with equal correctness probabilities, ten steps at 95% correctness each yield about 60% fully correct runs; ten at 99% yield about 90%.
p_run = p_step ^ n_steps 0.95 ^ 10 = 0.599 ≈ 60% 0.99 ^ 10 = 0.904 ≈ 90%
Real errors can be correlated, so this calculation is an illustration, not a production forecast. One bad retrieved document can contaminate several later decisions; conversely, a later validation step can catch an earlier mistake. You need to score the completed run to know what those interactions produce.
For a company of 10 to 200 people, my recommendation is to increase autonomy only after a fixed-path version exposes a specific limitation. A refund assistant that gathers evidence and proposes an action can deliver useful work while a person retains approval authority.
What to do about it
- Compare the agent with a fixed-path workflow on the same labeled cases and score accepted outcomes, elapsed time and cost.
- Set explicit maximum tool calls, retries and spending per run; test that execution stops at each limit.
- Restrict credentials to the actions the job requires and log every attempted external action.
- If you want the system built and operated for you, specify scoped permissions, action logging and human review as acceptance criteria.
- Test a failed run end to end: confirm that it stops, preserves its evidence and reaches a named reviewer without performing the blocked action.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.