AI automation use cases for small business: 19 job cards

On this page
- Inbox and documents: classify first, write after validation
- Finance: extract fields without handing over payment authority
- Sales: route quickly and protect commercial commitments
- Support: distinguish agent assistance from customer resolution
- Meetings: approve commitments before creating tasks
- Content: publish only claims you can substantiate
- Legal and people: keep the output advisory
- Order the shortlist by error class, then weekly volume
AI & Automation
About $0.45 in model fees and $199.94 in human review are monthly figures for the cost guide's hypothetical 3,000-email triage workload. AI automation use cases for small business pay first on high-volume jobs with cheap mistakes: email triage, document filing, meeting notes to tasks, invoice extraction with AP approval and order entry from POs. For a company of 10 to 200 people, use this starting threshold: weekly items = 300 / manual minutes per item. The human checkpoint usually decides whether the arithmetic survives.
| Job | AI step | Pays from, per week | Error class | Human checkpoint |
|---|---|---|---|---|
| Inbound email triage and routing | Classify intent, extract references | 200 emails | A | Exceptions and spot audit |
| Supplier invoice extraction | Extract invoice fields | 75 invoices | B | AP approval before payment |
| Receipt capture and expense coding | Extract receipt, suggest code | 150 receipts | B | Employee confirmation, finance checks |
| Bank reconciliation matching | Interpret unmatched references | 300 bank lines | B | Accountant accepts match |
| Order entry from PO emails and PDFs | Extract lines, map parts | 50 orders | B | Order desk releases order |
| Quote drafting from RFQs | Extract requirements, draft quote | 12 quotes | B as an assist (C if sent unreviewed) | Salesperson approves every quote |
| Lead qualification and routing | Classify fit and intent | 60 leads; speed value below this | A | Salesperson makes qualification call |
| CRM record enrichment | Turn website text into fields | 75 records | A | Rep checks on first contact |
| Meeting notes to tasks | Extract decisions and actions | 20 meetings | A | Owner approves actions before creation |
| Sales and support call summaries to CRM | Summarize, classify outcome | 60 calls | A | Rep edits CRM note |
| Website support chatbot | Answer from retrieved passages | 50 human-handled conversations | B; C for policy, price, refunds | Escalations and transcript review |
| Support reply assist | Suggest agent reply | About 55 hours of chat work | A, agent approves | Agent sends or ignores |
| Review responses | Draft specific reply | 75 reviews; rarely reached | B | Owner approves negative replies |
| Product description generation | Write from specifications | 15 new SKUs | B | Category manager checks batch |
| Contract clause extraction | Locate and quote clauses | 10 contracts | B as an assist (C if relied on unreviewed) | Signer reviews; lawyer handles deviations |
| HR policy Q&A | Answer from handbook passages | 60 questions | C for entitlements; B otherwise | HR handles sensitive questions |
| Collections reminder drafting | Draft chase, classify replies | 60 chases | B | Credit controller handles disputes |
| Inbound document classification and filing | Classify, extract filing reference | 300 documents | A | Exceptions queue |
| CV screening and ranking | Compare application with criteria | 100 CVs | C, regulated | Recruiter decides every rejection |
A: The mistake stays inside the company and can be undone in minutes.
B: The mistake reaches a customer, supplier or ledger but can be reversed before it costs money.
C: The mistake is irreversible or regulated, including a binding price, payment or employment decision. A C job enters only as an assist where a person approves every item before use, which makes it class B under the first-use-case guide's convention, except CV screening, which stays C because employment-decision rules apply whatever the review step.
The error classes, manual minutes and volume thresholds are our rules of thumb. The five-hours-a-week convention comes from choosing your first AI use case, which is also the next step after making a shortlist. Time 30 of your own items before trusting any threshold.
items_per_week = (5 * 60) / manual_minutes_per_item = 300 / manual_minutes_per_item
“Pays from” is a screening threshold, not a financial guarantee. It identifies five hours of existing work, before subtracting review time or adding maintenance costs; support assist uses a separate savings calculation. A job can clear the threshold and still lose money if every output needs extensive repair.
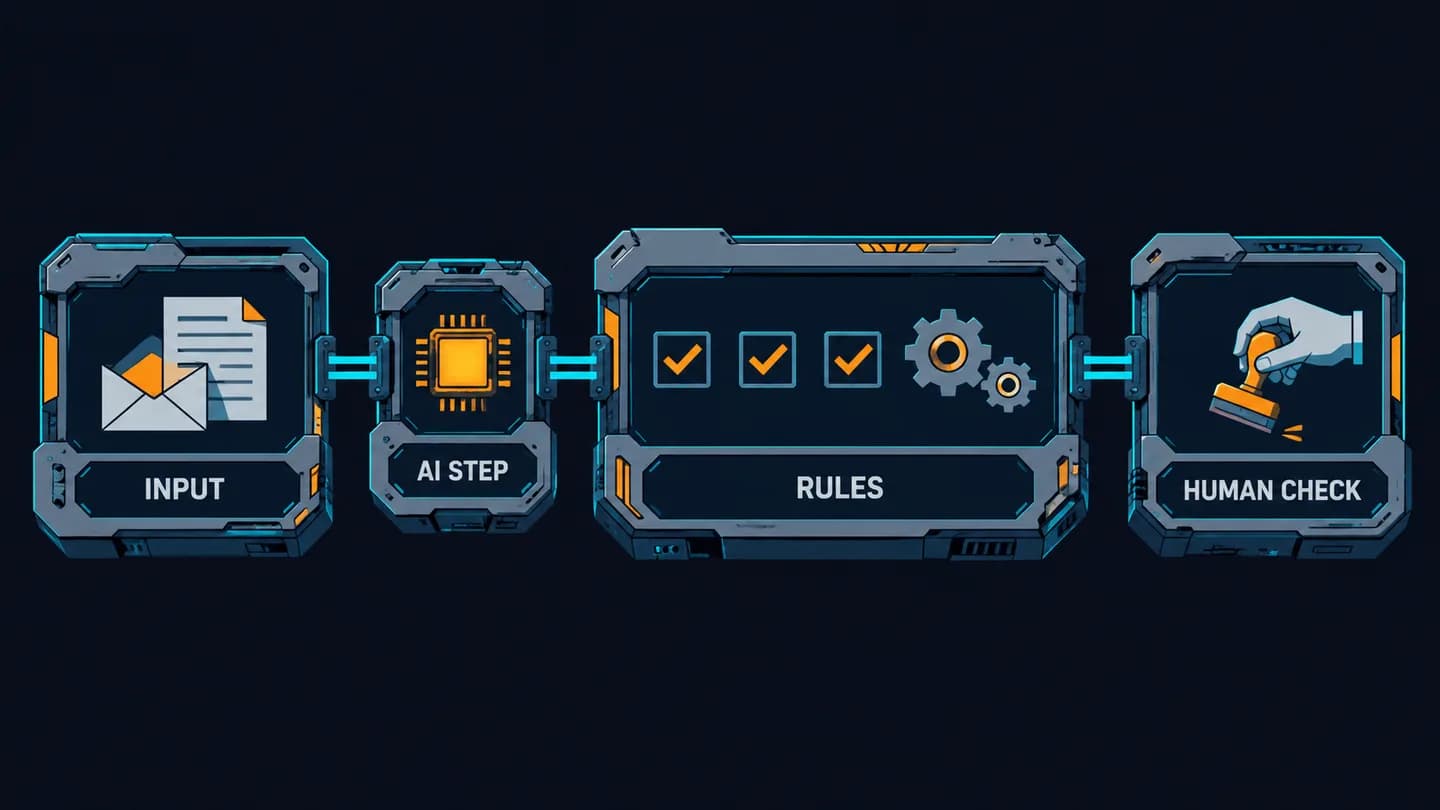
The model performs one bounded task. Look at the larger surrounding steps: they supply trusted data, check the output and control what happens next.
Inbox and documents: classify first, write after validation
Inbound email triage and routing
Inputs and output: Shared-inbox messages become labels, owners, priorities and extracted order or invoice references. The assumed manual time is 1.5 minutes per email, giving 200 emails a week.
AI step: Classify the newest message and return structured fields. Rules around it: Trigger on arrival, validate the output schema, look up references in the ERP or helpdesk, then apply a routing table.
Human checkpoint: Send uncertain or unrecognized messages to a queue and audit a sample. The opening cost example assumes 12% receive 45 seconds of review, plus a 2% audit taking two minutes each.
Tools: Front, Help Scout and Zendesk manage shared customer messages; Zapier or n8n can connect an inbox to a model API. Usually fails: Long quoted threads obscure the latest request, new message types lack a route, or the ownership table survives a reorganization unchanged.
Inbound document classification and filing
Inputs and output: Scanned mail and email attachments become a document type, client or job reference, filename and destination folder. One assumed manual minute gives a threshold of 300 documents weekly.
AI step: Identify the document type and extract its filing reference. Rules around it: Check that the reference exists, select the folder from a lookup table and construct the filename using a fixed naming rule.
Human checkpoint: Review missing references, unknown types and conflicting destinations. Keep an audit record of the original attachment and destination so a mistaken filing can be reversed.
Tools: Google Document AI offers document classification and splitting; n8n or Zapier can move validated files into document storage. Usually fails: One PDF contains several unrelated documents. Splitting must happen before filing, or the invoice and someone else's delivery note become permanent roommates.
Finance: extract fields without handing over payment authority
Supplier invoice extraction
Inputs and output: Supplier PDFs become AP drafts containing supplier, invoice number, dates, lines, tax, total and bank details. Four assumed minutes per invoice gives 75 weekly.
AI step: Read fields. Rules around it: Sum lines, check subtotal plus tax against total within 0.01, detect duplicate invoice numbers, match the PO and compare bank details with the vendor master.
Human checkpoint: AP approves every invoice before payment; changed bank details always reach a person. Tools and cost: Google Document AI's invoice parser lists $0.10 per count, with one count covering up to 10 pages; savings-plan tiers are lower. This parser price and the Intercom price quoted later were both read on 24 October 2026.
About $100 for 1,000 invoices is our arithmetic at that list price: 1,000 × $0.10, assuming every invoice is 10 pages or fewer. The cost guide's extracted-text examples cost about $0.21 to $0.42 per 1,000; neither figure includes human review. The gap comes from reading raw PDFs, including OCR and layout, in a purpose-built parser versus running a cheap model on text extracted beforehand.
Usually fails: Scans, credit notes and multipage tables. Evidence: Ardent Partners' analyst figures, reported on Bottomline's vendor page, put best-in-class processing at $2.78 per invoice versus $12.88 for others. These are team-level comparisons, not measured AI savings.
A cleanly extracted bank account can still belong to a fraudster. Hold the invoice and verify the change through your established supplier-verification process before updating the vendor master or authorizing payment.
Validation can pass ordinary extraction results automatically while failed checks enter the review tray. Passing those checks does not authorize payment; the AP approval remains a separate gate.
Receipt capture and expense coding
Inputs and output: Receipt photos and emailed receipts become merchant, date, amount, tax and a suggested general-ledger code. Two assumed minutes per receipt gives 150 weekly.
AI step: Extract the receipt fields and suggest a category. Rules around it: Check expense-policy limits, detect duplicates and match the receipt to the card feed before creating an accounting draft.
Human checkpoint: The employee confirms the expense; finance reviews exceptions and items above its chosen limit. A merchant name alone should not determine the accounting treatment.
Tools: Dext and Expensify SmartScan capture receipt data; Google Document AI's expense parser also extracts receipt fields. Usually fails: Faded thermal paper, tips and foreign tax formats. A hardware-store receipt might represent repairs, office supplies or inventory, so preserve uncertainty about the code.
Bank reconciliation matching
Inputs and output: Unmatched bank lines and remittance emails become proposed matches against open accounting entries. One assumed minute per line gives 300 weekly, counted only among lines requiring this additional work.
AI step: Interpret free-text references and remittance language. Rules around it: Use amount, date, currency and invoice references to constrain possible matches; retain the original bank transaction.
Human checkpoint: An accountant accepts each proposed match. Never let a plausible explanation override an amount mismatch without an explicit accounting treatment.
Tools: Xero and QuickBooks Online provide bank-feed match suggestions and user-written bank rules. Apply those first, then consider a model for unresolved text.
Usually fails: Partial payments and one transfer covering several invoices. Hypothetically, if existing rules already match 90% of lines, compare the remaining 10% with the threshold; the full feed exaggerates the available work.
Order entry from PO emails and PDFs
Inputs and output: Customer purchase orders become draft sales orders with SKUs, quantities and requested delivery dates. Six assumed minutes per order gives 50 weekly.
AI step: Extract customer requirements and propose mappings between customer part numbers and your SKUs. Rules around it: Confirm mappings against a maintained table, obtain prices from the price list, then run credit and stock checks.
Human checkpoint: The order desk confirms the draft before release, including delivery address and units of measure. Unmatched parts remain unresolved until someone supplies a valid mapping.
Tools: Google Document AI can extract document fields; n8n can pass validated data to an ERP API. Usually fails: A box becomes an individual unit, an unfamiliar part gets a confident match, or a changed delivery address passes unnoticed. Require explicit checks for all three.
Collections reminder drafting
Inputs and output: Aged receivables produce reminder drafts; customer replies produce statuses such as paid, disputed or awaiting information. Five assumed minutes per chase gives 60 weekly.
AI step: Draft wording and classify free-text replies. Rules around it: Accounting balances and the dunning schedule determine eligibility, amounts and timing. A paid or disputed response pauses the sequence for investigation.
Human checkpoint: The credit controller handles disputes and ambiguous payment claims. Confirm payment against the ledger before marking an invoice settled.
Tools: Xero or QuickBooks Online supplies accounting records and reminder functions; n8n can route reply classifications into a review queue. Usually fails: A reminder leaves after payment or during a dispute. The useful model step often sits in the reply inbox, because the reminder schedule itself is ordinary software.
Sales: route quickly and protect commercial commitments
Quote drafting from RFQs
Inputs and output: RFQ emails and specifications become draft quote lines and a cover note. At 25 assumed manual minutes, the threshold is 12 quotes weekly.
AI step: Extract requirements and propose relevant line items. Rules around it: Retrieve approved prices, discounts and lead times; enforce a margin floor and flag unsupported requirements.
Human checkpoint: A salesperson approves every quote before sending. Sending an unreviewed quote would be class C because it commits a binding price; as an assist where a salesperson approves every quote before it is sent, it is treated as class B under the first-use-case guide's convention. Place that gate after all pricing checks and before the outbound action, following the human approval and guardrail pattern.
Tools: A CPQ system supplies controlled configuration and pricing; n8n can assemble the draft from validated fields. Usually fails: An unusual specification resembles a standard product, or the model supplies an invented lead time. Treat missing commercial data as a blocked field, never an invitation to complete the sentence.
Lead qualification and routing
Inputs and output: Forms, emails and chats become intent categories, owners and acknowledgments. Five assumed minutes per lead gives 60 weekly, though response speed can justify lower volumes.
AI step: Classify expressed needs and fit. Rules around it: Validate required fields, apply territory routing, write the CRM record and send an approved acknowledgment or calendar link.
Human checkpoint: A salesperson makes the qualification call; review rejected leads weekly. Tools: HubSpot manages CRM records and routing; n8n can connect intake sources.
Usually fails: Guessed firmographics affect scores, and the hard part is the handoff. The instant acknowledgment must never quote prices or make promises, and every routed lead needs a named salesperson who calls it. A team can build and run lead classification, routing and the CRM handoff, including escalation to a person.
Evidence: HBR's The Short Life of Online Sales Leads by Oldroyd, McElheran and Elkington, published in March 2011, analyzed 1.25 million leads at 29 B2C and 13 B2B companies. Firms that tried to contact a lead within an hour were nearly seven times as likely to qualify it as those that tried even an hour later, and more than 60 times as likely as those that waited 24 hours or longer. Qualification meant having a meaningful conversation with a key decision maker. These findings are not evidence that AI qualification produces those gains.
CRM record enrichment
Inputs and output: New company or contact records receive proposed industry, size-band and business-description fields. Four assumed manual minutes gives 75 records weekly.
AI step: Summarize retrieved company text into a defined schema. Rules around it: Data-provider lookups supply source material, deduplication identifies existing records, and field-level rules prevent overwriting human edits.
Human checkpoint: The representative checks the record on first contact and corrects material errors. Retain the source and retrieval date so a surprising field can be investigated.
Tools: Clay combines data-provider lookups in tables; Apollo supplies contact data and enrichment; HubSpot Breeze Intelligence enriches HubSpot records. The provider lookup is separate from the model's interpretation.
Usually fails: Small businesses, renamed companies and similarly named entities receive confident but incorrect fields. An empty field is often cheaper than stale enrichment that silently replaces verified information.
Support: distinguish agent assistance from customer resolution
Website support chatbot
Inputs and output: Questions become source-linked answers or handoffs. Six assumed minutes per human conversation gives 50 weekly conversations a person would otherwise handle.
AI step: Answer from retrieved passages. Rules around it: Restrict retrieval, obtain order status through an API, log interactions and enforce escalation rules. Human checkpoint: Staff the queue and review transcripts weekly.
Tools: Intercom Fin provides an AI support agent at $0.99 per outcome. Usually fails: Stale policy, invented refunds and abandoned chats counted as successes.
Evidence: Gartner reported only 14% of issues fully resolved through self-service, rising to 36% for very simple issues; its survey covered 5,728 customers. That is broader self-service evidence, not a chatbot trial.
Klarna reported that its deployment handled two-thirds of chats and work equivalent to 700 agents, then resumed hiring humans in May 2025. A customer quote on Intercom's pricing page claims about 79% resolution. These company-reported and vendor-page claims use different settings and definitions.
Intercom's pricing FAQ counts an outcome when a customer confirms resolution, when they do not ask for more help after Fin responds, or when Fin completes a workflow, including handoffs. A billed outcome can therefore be a customer who went quiet; silence alone is never proof of resolution. For your own reporting, require a verified completed task or customer-confirmed answer without further help, and record unconfirmed silence as unknown status or abandonment where established.
Support reply assist
Inputs and output: An open chat becomes a suggested reply and documentation link shown to an agent. AI step: Draft the response. Rules around it: Fetch ticket context, display the suggestion inside the helpdesk and record whether it was used.
Human checkpoint: The agent edits, sends or ignores every suggestion. Tools: Zendesk provides agent-assistance functions within its helpdesk. Usually fails: Suggestions distract skilled agents or appear in situations unsupported by the available knowledge.
Evidence: NBER Working Paper 31161 studied 5,179 agents at one software firm: 14% more chats resolved per hour on average, 34% for the least skilled and experienced. The most skilled saw no productivity gain and small, statistically significant decreases in resolution rate and customer satisfaction.
Handle time fell 9%. Applying that saving gives 5 / 0.09 = 55.6 hours of weekly chat work to save five hours. This is our arithmetic, not a forecast; the study's tool could stay silent where training data was absent.
Meetings: approve commitments before creating tasks
Meeting notes to tasks
Inputs and output: Transcripts become summaries, decisions and proposed actions with owners and dates. Fifteen assumed manual minutes gives 20 meetings weekly.
AI step: Summarize and extract commitments. Rules around it: Match names to accounts and validate dates. Human checkpoint: The meeting owner approves the action list before task creation.
Tools: Teams, Google Meet, Otter and Fireflies offer transcription or summary functions; check plan availability. Usually fails: Crosstalk, names, recording consent and discussion mistaken for agreement.
Evidence: The DBT evaluation, a 1,000-licence pilot from October to December 2024, recorded self-reported diary savings of 0.7 hours per meeting-summary task. It found no evidence of improved productivity; 22% of respondents identified hallucinations.
The cross-government trial reported 26 minutes saved daily, self-reported from ranges across Copilot tasks. Separately, Vectara's summary-faithfulness benchmark measures unsupported additions, not meeting-action accuracy; a good benchmark score cannot authorize creating tasks.
Sales and support call summaries to CRM
Inputs and output: Recordings become CRM notes, objections, outcomes and next steps. Five assumed manual minutes gives 60 calls weekly.
AI step: Summarize the call and classify its outcome. Rules around it: Confirm recording permissions, match the call to the correct contact and write a clearly identified draft note.
Human checkpoint: The representative edits the note within the day, while the conversation is still familiar. A promised follow-up should retain a reference to the relevant transcript passage where available.
Tools: Gong records and analyzes sales calls and can push notes to a CRM; telephony platforms also offer built-in summaries. Usually fails: Wrong contact matches, unsupported commitments and notes nobody reads. Check that someone uses the output before buying a system to manufacture more of it.
Content: publish only claims you can substantiate
Review responses
Inputs and output: Google or marketplace reviews become specific reply drafts. Four assumed manual minutes gives 75 weekly, a threshold most companies will rarely reach.
AI step: Draft a response referring to the actual review. Rules around it: Pull reviews from the feed, prevent automatic posting to one- or two-star reviews and flag sensitive details.
Human checkpoint: The owner approves negative-review replies. Tools: Google Business Profile provides the review and reply surface; n8n can route drafts for approval. Usually fails: Repetitive wording, arguments and disclosure of customer information.
Evidence: Proserpio and Zervas found a 0.12-star average increase in TripAdvisor ratings after hotels began responding, measured against the same hotels' Expedia ratings. They attribute it to reviewer selection, not improved service. This supports responding consistently; it does not establish an advantage for AI-written Google replies.
Product description generation
Inputs and output: Specification sheets and product-information fields become descriptions, bullets and metadata. Twenty assumed manual minutes per new SKU gives 15 weekly.
AI step: Write from supplied facts. Rules around it: Require essential fields, block unsupported warranty or certification claims and verify that every output number appears in the input.
Human checkpoint: A category manager approves a sample per batch; unsupported claims block publication. Tools: Amazon Seller Central provides listing-generation tools; n8n can assemble approved product fields for a model.
Usually fails: Invented materials, plausible features and near-identical variant copy. Map factual claims to source fields, including claims without numbers.
Evidence: Google's AI-content guidance permits appropriate automation and targets content primarily intended to manipulate rankings. AI authorship alone does not establish an SEO violation; factual invention still creates a product-information problem.
Legal and people: keep the output advisory
Contract clause extraction
Inputs and output: Contracts become a clause table with quoted passages and page references. Thirty assumed manual minutes gives 10 contracts weekly.
AI step: Locate governing law, renewal, liability and termination provisions. Rules around it: Compare passages with your approved playbook, verify quotations against the document and hold calendar changes for confirmation.
Human checkpoint: The signer reads every flagged clause; a lawyer handles deviations. Relying on an unreviewed extraction would be class C; as an assist where the signer or a lawyer reviews every flagged clause before use, it is treated as class B under the first-use-case guide's convention. Tools: Google Document AI can prepare document text; a model API can propose clause locations.
Usually fails: Incorporated documents, definitions that change meaning and omitted exceptions. An empty result does not prove a clause is absent.
Evidence: The CUAD paper describes a dataset of 510 commercial contracts with over 13,000 annotations across 41 clause categories, framing the task as highlighting passages for human review. Separately, Stanford's legal-research-tools study found hallucinations between 17% and 33% on its benchmark. That study concerns legal research, not a measured contract-extraction error rate.
HR policy Q&A
Inputs and output: Employee questions become answers quoting a current handbook passage, or an HR referral. Five assumed manual minutes gives 60 questions weekly; a 50-person company will rarely sustain that volume.
AI step: Retrieve a relevant passage and explain it. Rules around it: Filter by country and contract type, enforce access controls, retain version information and log the source used.
Human checkpoint: HR answers questions about pay, leave entitlement, discipline or health. Tools: Teams can provide the employee interface; n8n can connect approved handbook sources and referral queues.
Usually fails: Old handbook versions and mixed jurisdictions produce convincing wrong answers. Moffatt v. Air Canada, concerning a customer-facing chatbot's incorrect fare policy, is a useful caution by analogy: company policy statements carry consequences. It is not an HR-bot precedent.
CV screening and ranking
Inputs and output: Applications become criterion-by-criterion summaries for a recruiter. Three assumed manual minutes gives 100 CVs weekly; use the volume only after assessing the legal exposure.
AI step: Summarize documented experience against explicit job criteria. Rules around it: Preserve source passages, separate missing evidence from failed requirements and prevent automatic rejection or hidden ranking-based exclusion.
Human checkpoint: The recruiter decides every rejection. Tools: An applicant tracking system stores applications and decisions; a model API can prepare summaries for review.
Usually fails: A summary turns into an unexamined score, qualifications are misread, or missing wording becomes evidence of inability. For occasional hiring, my judgment is that compliance and review work usually outweigh the time saving.
NYC Local Law 144 requirements include a bias audit within one year of use, publicly available audit information and candidate or employee notices for covered tools. The EU AI Act treats recruitment and selection uses as high-risk. A recruiter-facing summary with no automatic rejection is the more defensible design, but human involvement alone does not establish exemption.
Order the shortlist by error class, then weekly volume
Sort A before B before C, then compare the volume thresholds within each class. Use your measured minutes and actual eligible volume: total inbox traffic, bank-feed lines or website visits can greatly exceed the items the proposed system would handle.
The entries at the top still need an owner and a reversible write path. Jobs that would otherwise be class C enter only as assists with approval on every item: quote drafting and contract extraction become class B assists; CV screening stays C because employment rules apply whatever the review step. These assists and CV screening still sit at the bottom because approval time and consequences dominate the calculation.
| Usual position | Jobs | Observable condition before building |
|---|---|---|
| First checks | Email triage, document filing, meeting notes | Enough eligible volume; named reviewer; reversible outputs |
| Next checks | Invoice extraction, PO order entry | Trusted master data; validation rules; approval before release |
| Volume-dependent | CRM enrichment, call summaries, reply assist | Regular use of output; measured review time |
| Consistency projects | Review replies, lead routing | Explicit response target, even below the hours threshold |
| Last or assist only | CV screening, contract extraction, quote drafting | Qualified approval on every item before use; legal obligations assessed for CV screening |

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.