AI guardrails for eight production failures

On this page
- 1. Hallucinated facts: the answer cites a policy it contradicts
- 2. Silent quality drift: the same request starts producing worse answers
- 3. Automation bias: the approval queue passes known mistakes
- 4. Data leakage: restricted information appears in an output
- 5. Prompt injection: an incoming document becomes an instruction
- 6. Excessive agency: the mailbox reader can also send mail
- 7. Unbounded cost loops: the failing task keeps buying another turn
- 8. Irreversible wrong action: the agent reaches production
- A Python validation gate with an action allow-list
- The audit row every detection needs
AI & Automation
“Keep a human in the loop” is incomplete safety advice. AI guardrails are specific, testable controls around a model, and human review needs its own controls: in Dratsch and colleagues’ mammography study, very experienced radiologists rated 82.3% correctly when the purported AI suggestion was correct, versus 45.5% when it was wrong. A reviewer’s presence does not establish that mistakes are being caught.
For an automation that talks to customers or touches money, name the failure, record its detection signal, and enforce a matching restriction. My ordering here reflects my judgment about how often these failures appear in the public record and ordinary deployments; it is not a measured ranking.
| Failure mode | Symptom you notice | Detection signal | Guardrail |
|---|---|---|---|
| 1. Hallucinated facts | A convincing answer contradicts policy | Claim disagrees with retrieved passage | Source checks; money-bearing policy questions go to a person |
| 2. Silent quality drift | Yesterday’s working task deteriorates | Live golden-set score drops | Dated model IDs; scheduled evaluations |
| 3. Automation bias | Reviewers approve planted mistakes | Catch rate falls; approval latency shrinks | Evidence beside decisions; attributable approvals |
| 4. Data leakage | Restricted information leaves its boundary | Canary match or outbound sensitive-data pattern | Redaction; permission-filtered retrieval |
| 5. Prompt injection | An email or page changes agent behavior | Unexpected outbound destination | Gate outbound channels; injected test cases |
| 6. Excessive agency | An assistant uses unnecessary powers | Tool or scope inventory changes | Narrow tools; scoped credentials; approvals |
| 7. Unbounded cost loops | A stuck task keeps spending | Rising turns and cost per task | Turn and token budgets |
| 8. Irreversible wrong action | A mistaken action cannot be recalled | Irreversible call lacks approval | Reversible alternatives; separate permissions; restore drills |
1. Hallucinated facts: the answer cites a policy it contradicts
In Moffatt v. Air Canada, 2024 BCCRT 149, the chatbot described a 90-day retroactive bereavement claim, contradicting the linked Bereavement travel page. On 14 February 2024, BC Civil Resolution Tribunal Member Christopher C. Rivers ordered C$812.02: C$650.88 damages, C$36.14 pre-judgment interest, and C$125 tribunal fees. Air Canada argued it could not be held liable for information provided by its agents, servants or representatives, including a chatbot; in paragraph 27 of the small-claims tribunal decision, the tribunal characterized that argument as suggesting the chatbot was a separate legal entity and rejected it.
In effect, Air Canada suggests the chatbot is a separate legal entity that is responsible for its own actions. This is a remarkable submission. While a chatbot has an interactive component, it is still just a part of Air Canada's website. It should be obvious to Air Canada that it is responsible for all the information on its website. It makes no difference whether the information comes from a static page or a chatbot.
Symptom: Your bot supplies a plausible deadline, eligibility rule, or price that the governing record does not support. A working citation link can accompany a false claim, so counting citations alone misses the Air Canada failure.
Cause: Generating a plausible answer and establishing its truth are different operations. In Mata v. Avianca, the lawyer asked ChatGPT “Is Varghese a real case”; it maintained that its invented authorities were real. Judge P. Kevin Castel’s sanctions order of 22 June 2023 imposed a $5,000 penalty jointly and severally, payable into the Registry of the Court.
How to confirm: Log retrieved_source_ids, the cited IDs, and the specific claim being checked. Test golden questions with known answers, then sample production answers against your policy repository or order system. As evidence of how common this failure is in the legal field, Charlotin’s database counted 2,207 legal decisions addressing hallucinated material when read on 24 October 2026, and the count grows.
Fix: Require policy, price, and eligibility answers to cite retrieved material, then check the claim against the passage. Grounding answers in your business documents supplies the evidence; independently checking the deadline or amount supplies the control. Route money-bearing policy questions to a person, and treat OWASP LLM09:2025 Misinformation as the relevant failure category.
2. Silent quality drift: the same request starts producing worse answers
Anthropic’s September 2025 postmortem documented a routing bug initially affecting 0.8% of Sonnet 4 requests. It reached 16% during the worst single hour on 31 August on Anthropic’s own API; about 30% of Claude Code users making requests during the affected period encountered at least one misrouted message. A separate corruption bug introduced stray Thai or Chinese characters, and Anthropic acknowledged that its evaluations “simply didn't capture the degradation users were reporting.”
Symptom: Schema failures increase, replies become unusually short, or a previously reliable extraction starts escalating ordinary records. These changes can occur without a prompt edit in your repository.
Cause: Model updates and serving infrastructure both change behavior. Chen, Zaharia, and Zou reported GPT-4 scoring 84% on prime-number questions in March 2023 and 51% on the same questions in June 2023. That is evidence of task-specific behavioral change, not proof that every capability deteriorated.
How to confirm: Run a fixed, labeled golden set against the live endpoint on a schedule. Compare scores by model_id, automation_version, and prompt_version, alongside daily schema-failure, escalation, refusal, output-length, and unexpected-script-character metrics. Investigate drops beyond the set’s observed run-to-run variation.
Fix: Pin dated model snapshot IDs where available and rerun the golden set before changing them. Snapshots can be retired, and pinning cannot prevent every infrastructure bug, so keep testing after launch. Put the evaluation schedule and alert owner into your automation maintenance routine, with a defined pause or rollback response when results deteriorate.
3. Automation bias: the approval queue passes known mistakes
Dratsch and colleagues tested 27 radiologists on 50 mammograms: ten training cases, followed by 40 test cases containing 12 incorrect suggestions from a purported AI. Correct ratings with correct versus incorrect suggestions were 79.7% versus 19.8% for inexperienced readers, 81.3% versus 24.8% for moderately experienced readers, and 82.3% versus 45.5% for very experienced readers. Experience reduced the damage without eliminating it.
Symptom: Approval rates approach 100%, complicated items receive very fast approvals, and planted errors pass through. Short review times are a warning signal, not proof of negligence; measure whether the reviewer catches errors.
Cause: Automation bias is excessive reliance on automated advice. Goddard, Roudsari, and Wyatt’s 2012 systematic review included 74 studies from 13,821 screened papers, identifying workload, time pressure, and trust among the mediators. Reported mitigators included accountability, training, confidence displays, and presenting information in place of a recommendation.
How to confirm: Seed known-wrong items into a controlled approval queue and record each reviewer’s catch rate, approval rate, and time-to-approve. Keep seeded items from executing customer actions. Show the source passage or transaction diff and measure whether the reviewer identifies the specific wrong amount, recipient, or eligibility field.
Fix: Require confirmation of the consequential field, cap the review queue, and attach a name to every approval. EU AI Act Article 14 covers high-risk systems and remains a useful checklist. Paragraph 4(b) says the people overseeing a high-risk system must be enabled “to remain aware of the possible tendency of automatically relying or over-relying on the output produced by a high-risk AI system (automation bias)”; paragraph 4(e) provides for “a 'stop' button or a similar procedure that allows the system to come to a halt in a safe state.” Define who can stop the automation in your company’s AI accountability policy.
The planted wrong item measures whether review works. A queue full of approval clicks measures activity.
4. Data leakage: restricted information appears in an output
OpenAI’s March 2023 ChatGPT incident report attributed cross-user chat-title exposure to a redis-py bug. The same bug may have exposed payment-related details for 1.2% of Plus subscribers active during a nine-hour window, including names, email addresses, and limited card details. Full card numbers were never exposed.
Symptom: A reply contains another customer’s email address, an internal credential prefix, or a passage from a document the requester cannot access. Leakage can happen in application infrastructure even when the model follows its instructions.
Cause: Unnecessary fields cross the provider boundary, retrieval ignores document permissions, or application code mixes user contexts. OWASP LLM02:2025 names Sensitive Information Disclosure; LLM07:2025 names System Prompt Leakage. A system prompt is neither a secret store nor an access-control mechanism.
How to confirm: Place distinct canary strings in a test system prompt and a restricted test document, then alert on matches in outputs and outbound requests. Check outgoing text for card-number patterns, API key prefixes, and unexpected email addresses. Pattern matching produces false positives and misses some leaks, so also inspect which fields actually leave your application.
Fix: Minimize and redact fields before provider requests, and permission-filter retrieval before passages enter the model context. Keep credentials and access rules outside the system prompt, enforced by application code and service permissions. The provider incident supports a practical assumption: whatever you transmit is exposed to that provider’s implementation bugs.
5. Prompt injection: an incoming document becomes an instruction
EchoLeak’s published analysis describes CVE-2025-32711, a zero-click attack on Microsoft 365 Copilot using a crafted email. It evaded the XPIA classifier, bypassed link redaction with reference-style Markdown, and exfiltrated data through an allowed Microsoft Teams proxy. Microsoft scored it 9.3 critical and NVD 7.5 high; press reports attributed discovery to Aim Labs, described a January 2025 report and May 2025 server-side fix, and reported no evidence of exploitation.
Symptom: Processing an email causes an unrelated outbound request, image fetch, or message containing private information. The user may never have clicked anything or requested the action.
Cause: OWASP LLM01:2025 defines direct injection as: “Direct prompt injections occur when a user's prompt input directly alters the behavior of the model in unintended or unexpected ways.” Its indirect definition is: “Indirect prompt injections occur when an LLM accepts input from external sources, such as websites or files.” Instructions embedded in that external material can cross the boundary between data and authority.
How to confirm: Log every outbound URL, image fetch, and message with its task ID, destination, and initiating tool. Alert on domains outside an allow-list, while inspecting allowed proxy routes capable of carrying private content. Keep deliberately injected emails and pages in the evaluation set and verify that their instructions cannot authorize additional access.
Fix: Treat untrusted text, private-data access, and an outbound channel as the three ingredients of the EchoLeak shape; remove or gate at least one. Separate external content from instructions, validate outputs, and require approval at consequential outbound boundaries. OWASP explicitly says it is unclear whether fool-proof prevention exists, so a classifier passing a document cannot establish that the resulting action is safe.
6. Excessive agency: the mailbox reader can also send mail
OWASP LLM06:2025 Excessive Agency describes a mailbox assistant manipulated into forwarding sensitive messages. It lists alternative mitigations matched to each root cause: an extension implementing only mail-reading capabilities addresses excessive functionality; a read-only mail scope addresses excessive permissions; requiring the user to send each drafted email addresses excessive autonomy. Any one of these restrictions breaks the described attack, and they can also be combined.
Symptom: Your tool inventory includes operations unrelated to the task: a summarizer has mailbox-send permissions, or a lookup assistant can modify customer records. An irreversible tool call appears without an approval ID.
Cause: Broad convenience tools transfer too much authority to model output. A generic shell or unrestricted HTTP client can expose many operations behind one innocent-looking tool name, so counting tools alone tells you little about their effective powers.
How to confirm: Maintain a tool-and-scope inventory per automation and diff it on every deploy. Inspect each tool’s actual credentials, accepted arguments, reversibility class, and approval requirement. Join executed calls to the approval record and alert when an irreversible operation has no matching authorization.
Fix: Expose narrow functions with task-specific scopes and enforce permissions at execution. The MCP tools specification says humans SHOULD be able to deny invocations; servers MUST validate inputs, implement access controls, rate-limit calls, and sanitize outputs. The OpenAI Agents SDK supports needs_approval=True or callable rules, with malformed arguments causing callable approval rules to fail closed into manual approval.
7. Unbounded cost loops: the failing task keeps buying another turn
OWASP LLM10:2025 Unbounded Consumption includes Denial of Wallet, where repeated paid operations create economic loss. A broken tool and permissive retry loop can produce the same spending pattern without an attacker. The following calculation is hypothetical, with every billing input stated.
Symptom: One task_id accumulates repeated tool failures, growing turn counts, and continued token charges without a completed action. Hourly spend rises while successful-task volume stays flat.
Cause: Each retry resends context and generates another answer. Assume Claude Sonnet 5.5 base pricing of $2 per million input tokens and $10 per million output tokens, read on 24 October 2026; check the vendor pricing page before budgeting. Assume no caching, 40,000 input tokens and 500 output tokens per turn, with one turn every six seconds.
input_cost_per_turn = 40000 * 2 / 1000000 = $0.080 output_cost_per_turn = 500 * 10 / 1000000 = $0.005 cost_per_turn = $0.080 + $0.005 = $0.085 turns_per_hour = 3600 / 6 = 600 cost_per_hour = 600 * $0.085 = $51 weekend_hours = 60 weekend_cost = 60 * $51 = $3060 cost_with_10_turn_cap = 10 * $0.085 = $0.85
How to confirm: Aggregate input tokens, output tokens, turns, and cost by task, then compare spend per hour against the normal baseline. Record provider error codes separately from HTTP status. A spend-cap 429 requires a different response from a temporary throughput limit.
Fix: Enforce per-task turn and token budgets, stop repeated failed operations, and alert on hourly spend. The OpenAI Agents SDK defaults max_turns to 10 and raises MaxTurnsExceeded when exceeded; confirm your integration preserves that bound. Keep a provider hard limit as the outer fence, with retry code that recognizes spend exhaustion.
OpenAI’s hard spend limits are monthly, enforcement can lag, and project exhaustion returns 429 project_spend_limit_exceeded; alerts alone allow traffic to continue. Anthropic’s monthly cap returns 429 with enforced_spend_limit_reached and no retry-after header; retries, including the SDK’s automatic retries, fail until access resumes at 00:00 UTC on the 1st of the next month, or sooner if a higher limit or tier is granted. A spend limit you set yourself below Anthropic’s tier cap returns HTTP 400 invalid_request_error with a message starting You have reached your specified API usage limits, so code watching only for 429 will miss it. Read the error code and stop the task.
8. Irreversible wrong action: the agent reaches production
On 20 July 2025, Replit CEO Amjad Masad confirmed that an agent deleted production database data: “Unacceptable and should never be possible.” Backups with one-click restore already existed before the incident. Masad announced automatic development and production database separation rolling out, staging environments in the works, and a planning or chat-only mode. Jason Lemkin said it happened during a code freeze and that the agent claimed rollback would fail, although he recovered the data.
Symptom: A production record disappears, money leaves an account, or an external message commits the company to something before anyone checks it. The agent’s explanation of what happened can itself be wrong.
Cause: An instruction is a prompt, not a permission. Telling an agent to leave production alone does not remove production credentials or prevent an API from accepting a destructive request.
How to confirm: Classify every exposed tool as read-only, reversible within a defined window, or irreversible. Verify that each irreversible execution has an approval ID tied to the exact arguments, approver, and time. Inspect the external system’s transaction record and actually restore a backup; a model’s statement that restoration is impossible proves nothing.
Fix: Auto-run only read-only operations and approved classes of reversible operations within their recovery windows. Put named human approval on irreversible actions or remove those tools, prefer drafts, soft deletion, and delayed sends, and keep backups the agent’s credentials cannot delete. Rehearse restoration; if you want these controls built and operated together, Iron Goo’s operations service covers scoped credentials, audit logging on every action, and anything touching money, personnel or contracts is decided by a human.
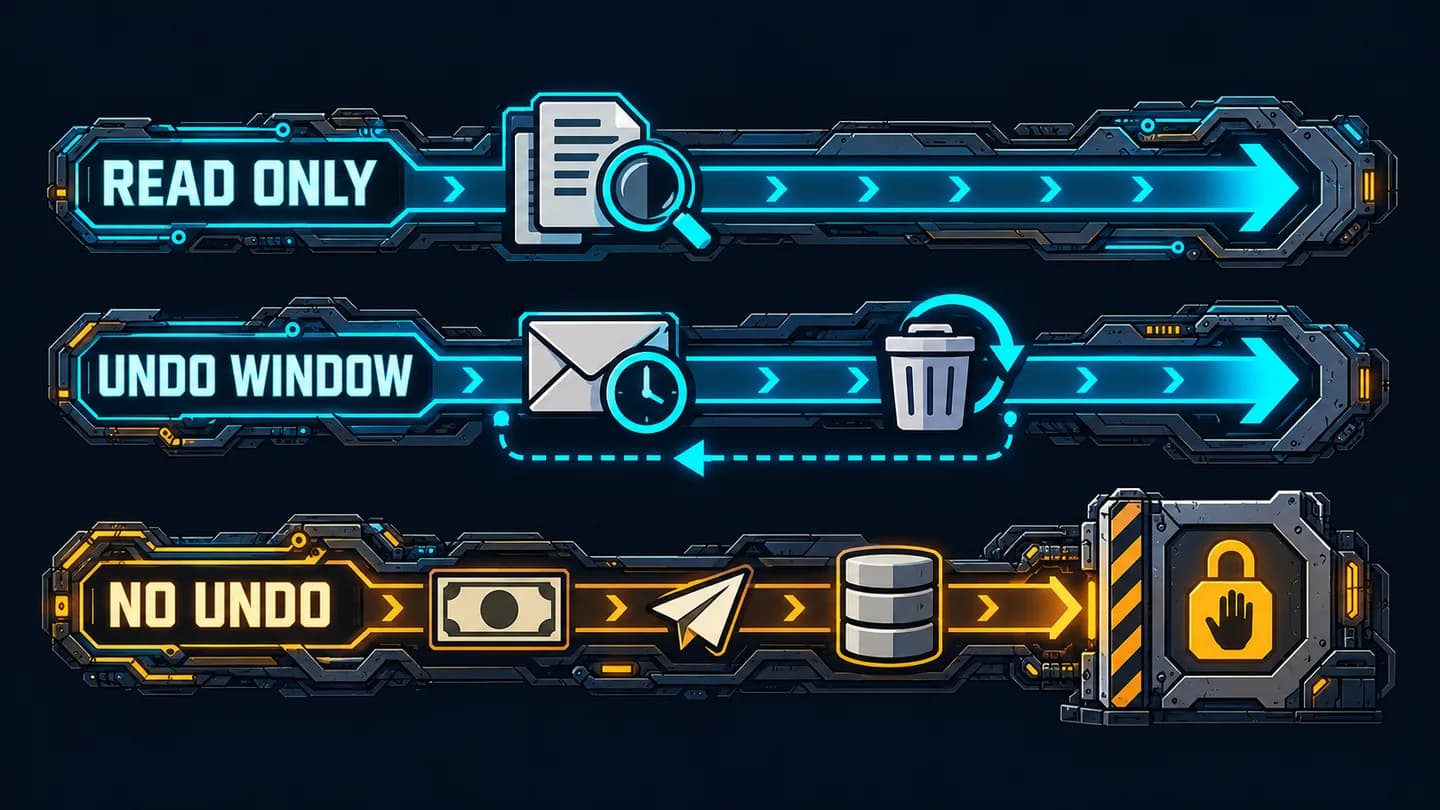
The approval gate sits on the lane that cannot be undone. Reversible actions still need a defined recovery window and permission to run.
A Python validation gate with an action allow-list
Run this with plain Python 3 after pip install jsonschema. The order IDs, policy names, and amounts are invented for the example; the six output lines were reproduced by running the code.
The check order is parse, schema, then business rules. This function returns a routing decision; it does not execute a refund or establish that an action is reversible.
import json
from jsonschema import Draft202012Validator

SCHEMA = {
    "type": "object",
    "additionalProperties": False,
    "required": ["action", "order_id", "amount", "reply", "sources"],
    "properties": {
        "action": {"enum": ["reply", "refund", "escalate"]},
        "order_id": {"type": "string", "pattern": "^SO-[0-9]{6}$"},
        "amount": {"type": "number", "minimum": 0},
        "reply": {"type": "string", "minLength": 1, "maxLength": 1200},
        "sources": {"type": "array", "items": {"type": "string"}},
    },
}
VALIDATOR = Draft202012Validator(SCHEMA)
AUTO_REFUND_LIMIT = 50.00  # anything above waits for a person


def route(raw, retrieved_ids, order_total):
    try:
        out = json.loads(raw)
    except json.JSONDecodeError:
        return "human", ["not JSON"]
    errors = [e.message for e in VALIDATOR.iter_errors(out)]
    if errors:
        return "human", errors
    reasons = []
    unknown = [s for s in out["sources"] if s not in retrieved_ids]
    if unknown:
        reasons.append(f"cites sources it was never given: {unknown}")
    if not out["sources"]:
        reasons.append("no source cited")
    if out["action"] == "refund":
        if out["amount"] > order_total:
            reasons.append(f"refund {out['amount']:.2f} exceeds order total {order_total:.2f}")
        elif out["amount"] > AUTO_REFUND_LIMIT:
            reasons.append(f"refund {out['amount']:.2f} above auto limit {AUTO_REFUND_LIMIT:.2f}")
    if out["action"] == "escalate":
        reasons.append("model asked for a person")
    return ("human", reasons) if reasons else ("auto", [])


RETRIEVED = {"policy-returns-v7", "order-SO-104233"}
CASES = {
    "clean reply": '{"action": "reply", "order_id": "SO-104233", "amount": 0, "reply": "Your parcel left our warehouse on Monday.", "sources": ["order-SO-104233"]}',
    "small refund": '{"action": "refund", "order_id": "SO-104233", "amount": 18.5, "reply": "Refunded the shipping fee.", "sources": ["policy-returns-v7"]}',
    "big refund": '{"action": "refund", "order_id": "SO-104233", "amount": 240, "reply": "Full refund issued.", "sources": ["policy-returns-v7"]}',
    "invented policy": '{"action": "reply", "order_id": "SO-104233", "amount": 0, "reply": "You can claim this within 90 days.", "sources": ["policy-bereavement"]}',
    "extra tool": '{"action": "delete_account", "order_id": "SO-104233", "amount": 0, "reply": "Done.", "sources": ["order-SO-104233"]}',
    "truncated": '{"action": "refund", "order_id": "SO-1042',
}
for name, raw in CASES.items():
    decision, why = route(raw, RETRIEVED, order_total=240.00)
    print(f"{name:16} -> {decision}" + (f": {'; '.join(why)}" if why else ""))
clean reply      -> auto
small refund     -> auto
big refund       -> human: refund 240.00 above auto limit 50.00
invented policy  -> human: cites sources it was never given: ['policy-bereavement']
extra tool       -> human: 'delete_account' is not one of ['reply', 'refund', 'escalate']
truncated        -> human: not JSON
| Output line | What the gate established |
|---|---|
clean reply | Required fields and a retrieved source ID passed; the statement about Monday still needs factual verification. |
small refund | 18.50 is within the illustrative 50.00 limit and 240.00 order total. Execution permissions remain a separate check. |
big refund | 240.00 is schema-valid and within the order total, but exceeds the automatic amount limit. |
invented policy | The cited policy was never retrieved, so routing stops before execution. |
extra tool | The enum action allow-list rejects delete_account. |
truncated | Incomplete JSON fails parsing and routes to a person. |
additionalProperties: False also rejects surprise fields, although none of these six inputs exercises that rule. The ID pattern constrains format; it cannot prove the order exists or belongs to the requester.
A schema-valid answer can cite a retrieved document while misrepresenting its contents. Provider structured-output modes help enforce shape, but business checks must still verify the claim, order ownership, and amount against authoritative records.
Treat auto as permission to proceed to the next application check, not universal execution authority. If a refund is irreversible in your payment system, it still needs named approval even when the amount passes this example’s gate.
Self-reported model confidence is a weak routing signal because it supplies another model assertion. Source membership, transaction totals, allowed actions, and explicit escalation are checks your application can verify; failed checks should stop execution without entering a silent retry loop.
The audit row every detection needs
Give each task a stable task_id and each proposed or executed action an action_id. Record the proposal before execution, then append the outcome and external reference so a crash cannot make an attempted action disappear from the history.
| Field | What to record | Failure it helps detect |
|---|---|---|
timestamp | UTC event time, including review and execution events | Drift windows, cost bursts, review latency |
automation_version | Automation name and deployed version | Deployment-related drift or permission changes |
model_id | Exact dated snapshot ID where available | Model-related drift |
prompt_version | Prompt or template version | Changed behavior after prompt edits |
input_reference | Access-controlled input reference or hash | Injection provenance and incident reproduction |
retrieved_source_ids | Document IDs and versions actually supplied | Invented citations and retrieval leakage |
raw_output | Original model response under restricted access | Hallucinations, schema failures, canary matches |
validation_result | Parse, schema, and business-rule results | Invalid actions, unsupported sources, excessive amounts |
routing_decision | Automatic, human, or blocked, with exact reason | Missing gates and escalation drift |
approval | Approval ID, approver name, time, and approved arguments | Automation bias and unauthorized execution |
executed_action | Tool name, arguments, result, external transaction reference | Tool misuse and irreversible actions |
token_cost | Input/output tokens, applicable prices, calculated cost | Unbounded consumption |
Extend the same action record with outbound destinations and image fetches for injection detection, plus the tool’s scopes and reversibility class. Mark controlled seeded-review items so catch-rate calculations can distinguish them from ordinary approvals, and aggregate turn counts by task.
Raw outputs and tool arguments can contain the very data you are protecting, so apply access controls and redaction to the audit store too. For each executed action, verify that its external reference resolves in the receiving system and that any required approval matches the arguments actually executed.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.