How to measure AI ROI from baseline to cash payback

On this page
- Stage 1: Time enough invoices to establish a baseline
- Stage 2: Keep a same-weeks manual holdout
- Stage 3: Count review, escalation and rework on the AI path
- Stage 4: Calculate payback across adoption shares
- Stage 5: Separate cash payback from capacity payback
- What measured productivity studies permit you to assume
- Reproduce the calculations with Python
- Keep an observable monthly measurement record
AI & Automation
85% of chatbot users reported putting saved time into other job tasks, while linked administrative records ruled out earnings effects larger than 2% two years after ChatGPT's launch. Those are findings from Humlum and Vestergaard's Danish study, not a contradiction. How to measure AI ROI: time a baseline, compare against a same-weeks holdout, count the AI path's own minutes, and convert only cash you stop spending into cash savings. Report freed capacity separately.
Norrbeck Plumbing Supply is a fictional 45-person plumbing wholesaler entering 900 supplier invoices a month into accounting. Every Norrbeck number that follows is an assumption or a calculation from assumptions, including the supposed measurements, logs and costs. The exercise follows five stages, ending with two defensible payback figures for the same automation.
Stage 1: Time enough invoices to establish a baseline
Norrbeck's proposed automation extracts supplier invoice fields and drafts an accounting entry. A clerk reviews every draft, and invoices requiring manual handling take an escalation path. Before buying anything, the company needs a credible measure of how long the existing job takes.
For this example, start timing when the clerk opens an invoice and stop when the entry is completed and filed. Include supplier lookups and active time spent asking colleagues questions; exclude idle gaps between invoices. Track waiting time separately if an unanswered question delays completion, because elapsed delay and labor minutes answer different questions.
Record the clerk, supplier and invoice type alongside the duration. Spread observations across days and people, including awkward invoices with credits or unfamiliar layouts. One clerk processing one supplier's cleanest PDFs does not represent the job.
System timestamps can reduce the burden where they capture actual handling time. Check what each timestamp means before subtracting them: an invoice left open during lunch can make a respectable spreadsheet very confidently wrong. People also change their behavior when timed, so keep observation light and spread it out.
If the job has no observable start, finish or output, revisit how to choose your first AI use case before treating an estimated saving as an investment case. A measurable baseline belongs in use-case selection.
The 12-invoice pilot determines how many observations to collect
The assumed pilot produces these handling times. These are individual observations, not averages for different invoice categories.
| Pilot invoice | Assumed minutes | Pilot invoice | Assumed minutes |
|---|---|---|---|
| 1 | 3.1 | 7 | 2.6 |
| 2 | 5.6 | 8 | 4.9 |
| 3 | 2.8 | 9 | 3.8 |
| 4 | 4.4 | 10 | 7.2 |
| 5 | 6.9 | 11 | 3.3 |
| 6 | 3.5 | 12 | 4.1 |
The pilot mean is 4.35 minutes, with a sample standard deviation of 1.53 minutes. That spread determines how much timing work is needed; choosing 30 observations because it sounds statistical does not.
Use N = (1.96 * s / (e * mean))^2, rounded up, where s is the standard deviation and e is the desired margin as a share of the mean. The NIST handbook's sample-size method uses a known standard deviation; substituting the pilot's sample standard deviation with z = 1.96 gives a slightly smaller sample than a t-based iteration would.
| Precision target for the example | Calculation using unrounded pilot values | Required total observations |
|---|---|---|
| 95% confidence, plus or minus 5% of mean | (1.96 * sd / (0.05 * mean))^2, rounded up | 190 |
| 95% confidence, plus or minus 10% of mean | (1.96 * sd / (0.10 * mean))^2, rounded up | 48 |
These are total sample sizes, not extra observations added to the pilot. Include the pilot observations if they followed the same timing convention and sampling plan. The calculation addresses sampling precision; it cannot repair a sample that excludes difficult invoices.
Norrbeck chooses the narrower target. Its assumed full baseline comprises 190 invoices handled by three clerks over two weeks, with a mean handling time of 4.20 minutes. That 4.20 is a separate assumption, not the 12-invoice pilot mean rounded differently.
Add downstream corrections and price the labor hour
An invoice entered incorrectly can look fast until someone repairs it. Norrbeck therefore combines initial handling with expected later correction time, keeping the correction rate and correction duration visible.
| Baseline input | Assumed example value | Assumed source or calculation |
|---|---|---|
| Employees | 45 | Company headcount |
| Supplier invoices per month | 900 | Accounting system count |
| Handling minutes per invoice | 4.20 | 190 timed invoices across three clerks |
| Later correction rate | 3.1% | Accounts payable correction log |
| Minutes per correction | 18 | Timed corrections |
| Expected correction minutes per invoice | 0.558 | 0.031 * 18 |
| Total labor minutes per invoice | 4.758 | 4.20 + 0.558 |
| Clerk wage | $26/hour | Payroll wage assumption |
| Loaded hourly rate | $37.14/hour | $26 / 0.70 |
The 70% wage share comes from the BLS private-industry compensation figures for June 2026, published on 17 September 2026 and checked on 24 October 2026. Employer costs averaged $46.89 per hour worked: $32.82 in wages and $14.07 in benefits.
Dividing wage by 0.70 is our approximation from that US private-industry average, which varies by firm. Use your actual employer costs when available. A loaded rate values labor capacity; it does not mean that every freed hour removes that amount from payroll.
Stage 2: Keep a same-weeks manual holdout
A before-and-after comparison gives the automation credit for everything else that changes. During Norrbeck's assumed launch window, a large supplier switches to a portal producing cleaner PDFs. Manual handling gets faster without any help from the automation.
For four weeks, route even-numbered invoices through the AI path and keep odd-numbered invoices manual. Preserve the assignment throughout the window, including awkward invoices. The manual half supplies the counterfactual: what the work would have cost during those same weeks without AI.
Check that invoice parity is unrelated to supplier or difficulty. Supplier numbering conventions could make even and odd groups systematically different; if they do, use another assignment rule unrelated to the work's difficulty. Compare supplier and invoice-type mixes before accepting the split.
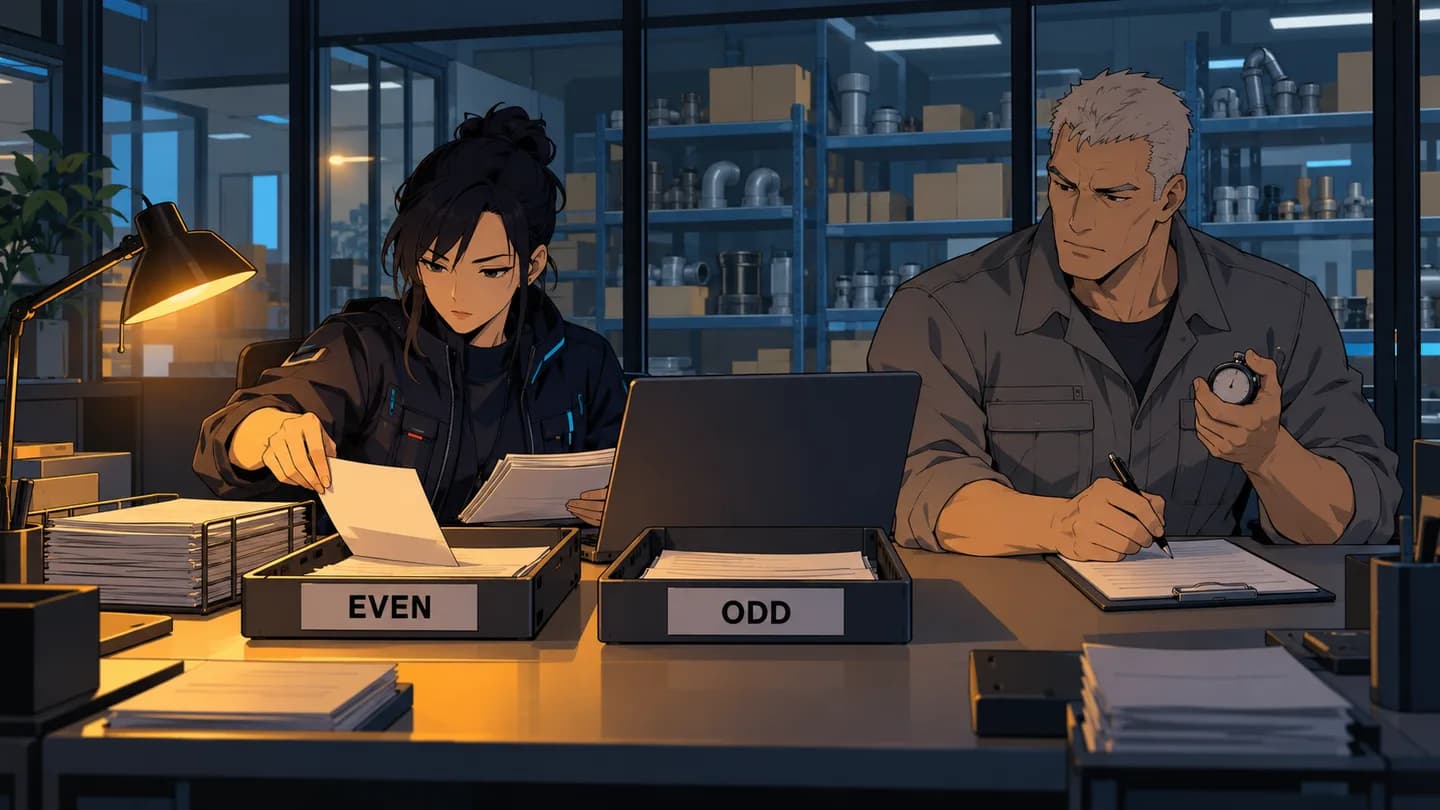
Both groups encounter the supplier-portal change during the same weeks. The manual invoices show how much handling time would have fallen without the automation.
In the example, manual handling falls from 4.20 to 3.90 minutes. Its correction rate stays at the assumed 3.1%, so the control path costs 3.90 + 0.031 * 18 = 4.458 minutes per invoice. The AI path costs 2.012 minutes, with its components measured in the next stage.
| Comparison | Assumed example calculation | Saving per AI-path invoice |
|---|---|---|
| Naive before/after | 4.758 - 2.012 | 2.746 minutes |
| Same-weeks controlled comparison | 4.458 - 2.012 | 2.446 minutes |
| Credit incorrectly assigned to AI | 2.746 - 2.446 | 0.300 minutes |
| Over-credit relative to controlled saving | 0.300 / 2.446 | About 12% |
The portal change explains the extra 0.300 minutes. Multiplying the naive saving by invoice volume would carry that mistake directly into the financial forecast. A perfectly calculated ROI can still have a bad counterfactual.
Use the four-week split to estimate the difference between paths, then model the intended ongoing adoption share separately. Half the invoices entering AI during the experiment does not establish that half will enter AI permanently.
Stage 3: Count review, escalation and rework on the AI path
The AI path does not cost zero labor minutes because extraction runs unattended. Someone reviews its draft, some invoices return to manual handling, and errors can surface after approval. Each branch needs its own denominator and timing convention.
Norrbeck assumes review happens on every AI-path invoice, including invoices subsequently escalated. Escalation adds triage and full manual entry; downstream correction time is added separately. If your workflow detects escalation before review, measure that actual sequence and change the calculation.
| AI-path component | Assumed example value | Assumed measurement source |
|---|---|---|
| Review per invoice entering AI | 1.1 minutes | Timed reviews |
| Share escalated | 12% | Escalated invoices divided by AI-path invoices |
| Manual handling per escalation | 3.90 minutes | Timed manual handling during holdout |
| Extra triage per escalation | 1.0 minute | Timed escalation work |
| Later correction rate across AI-path invoices | 1.8% | Correction log linked to original path |
| Minutes per later correction | 18 | Timed corrections |
| Expected review contribution | 1.100 minutes | Review happens on every invoice |
| Expected escalation contribution | 0.588 minutes | 0.12 * (3.90 + 1.0) |
| Expected rework contribution | 0.324 minutes | 0.018 * 18 |
| Total AI-path labor | 2.012 minutes | Sum of the three contributions |
ai_path_minutes = review_minutes + escalation_share * (manual_minutes + triage_minutes) + ai_error_rate * rework_minutes ai_path_minutes = 1.1 + 0.12 * (3.90 + 1.0) + 0.018 * 18 = 2.012
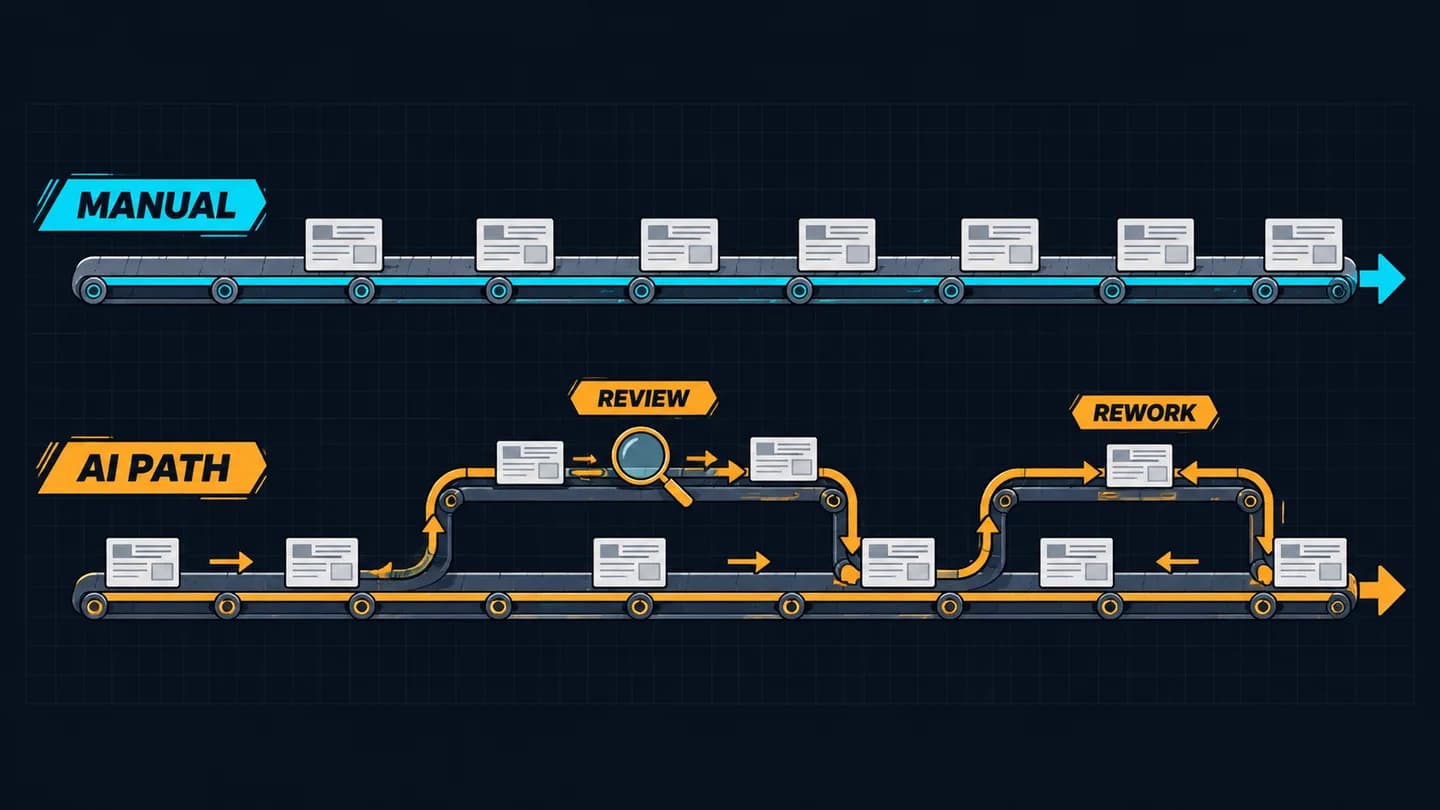
The AI path is shorter overall, but its branches consume labor. Count review on every draft and weight escalation and later rework by how often they occur.
Keep the original routing label when an invoice escalates. Moving difficult invoices into the manual category after escalation would make the AI path appear artificially clean and the control group artificially slow. Assignment and final handling method are different fields.
A 1.8% error rate needs hundreds of audited invoices
The assumed error improvement is the weakest measurement in this example. To estimate a 1.8% error rate within plus or minus 1 percentage point at 95% confidence, the approximate proportion calculation is N = 1.96^2 * 0.018 * (1 - 0.018) / 0.01^2, rounded up to 680 invoices.
With 100 audited invoices, the approximate margin is plus or minus 2.6 percentage points. That is wider than the supposed improvement from 3.1% to 1.8%. A small spot check cannot establish that reduction reliably.
The four-week AI half will not supply 680 observations at the assumed monthly volume. Carry the error-rate uncertainty in the ROI estimate and extend observation, or reconcile all eligible invoices against downstream corrections over a longer window. Use equal follow-up periods so older manual invoices do not have more opportunity to reveal errors.
Stage 4: Calculate payback across adoption shares
Adoption share means the proportion of all monthly invoices entering the AI path. The remaining invoices stay manual at the control cost. Escalation is already included inside AI-path minutes, so it must not be subtracted from adoption again.
The cost assumptions are $9,000 to build and $206.43 per month to run. Use the line-by-line AI automation cost breakdown to price these categories against an actual proposal.
| Cost input | Assumed example amount | Treatment |
|---|---|---|
| One-time build | $9,000 | Initial investment |
| Platform | $89/month | Recurring cost |
| Model API | $6/month | Recurring cost |
| Upkeep | 3 hours/month | Labor valued at loaded rate |
| Upkeep labor value | $111.43/month | 3 * ($26 / 0.70) |
| Total monthly run cost | $206.43 | Platform plus model plus upkeep |
These are example allowances, not quoted market prices. Upkeep remains in the model even when the workflow runs quietly; somebody still owns corrections and supplier-format changes. Budget that work using the maintenance requirements of running AI automations.
monthly_hours_saved = monthly_invoices * adoption_share * (control_minutes minus ai_path_minutes) / 60 monthly_capacity_value = monthly_hours_saved * loaded_hourly_rate net_monthly_benefit = monthly_capacity_value minus monthly_run_cost payback_months = build_cost / net_monthly_benefit roi_12_months = (12 * monthly_capacity_value minus (build_cost + 12 * monthly_run_cost)) / (build_cost + 12 * monthly_run_cost)
monthly_invoices = 900 control_minutes = 4.458 ai_path_minutes = 2.012 loaded_hourly_rate = 26 / 0.70 build_cost = 9000 monthly_run_cost = 89 + 6 + 3 * loaded_hourly_rate
at_80_percent_hours = 900 * 0.80 * (4.458 minus 2.012) / 60 = 29.352 at_80_percent_monthly_value = 29.352 * (26 / 0.70) = 1090.217... at_80_percent_net = 1090.217... minus 206.428... = 883.788... at_80_percent_payback = 9000 / 883.788... = 10.2 months at_80_percent_roi = (12 * 1090.217... minus (9000 + 12 * 206.428...)) / (9000 + 12 * 206.428...) = 14%
If net monthly benefit is zero or negative, there is no payback under those assumptions. These formulas assume constant monthly volume, adoption and cost from the start; a gradual rollout requires monthly cash flows. The table is a sensitivity analysis, not a promise about launch-month performance.
| Assumed adoption | Hours freed/month | Capacity value/month | Net capacity benefit/month | Capacity payback | 12-month capacity ROI |
|---|---|---|---|---|---|
| 100% | 36.7 | $1,363 | $1,156 | 7.8 months | 42% |
| 80% | 29.4 | $1,090 | $884 | 10.2 months | 14% |
| 60% | 22.0 | $818 | $611 | 14.7 months | -15% |
| 40% | 14.7 | $545 | $339 | 26.6 months | -43% |
| 20% | 7.3 | $273 | $66 | 136.1 months | -72% |
The curve bends because recurring costs remain while eligible volume falls. First-year ROI crosses zero between 80% and 60% adoption, moving from 14% to -15%. At 20%, nearly all monthly capacity value is consumed by run costs.
My judgment is to approve against a plausible adoption case and inspect the lower case before committing. A workflow requiring every supplier and clerk to cooperate immediately has a fragile investment case. Record why invoices bypass AI so a falling share can be traced to specific causes.
Stage 5: Separate cash payback from capacity payback
At 80% adoption, the example frees 29.4 hours per month. Norrbeck assumes it can stop paying 10 overtime hours at 1.5 times the $26 wage, removing $390 of monthly spending. The remaining 19.4 hours become available for other work.
Freed salaried hours create capacity while payroll can stay unchanged. Report cash savings only against spending that actually stops, and keep capacity value in a separately labeled calculation.
| At assumed 80% adoption | Capacity valuation | Cash-spending view |
|---|---|---|
| Monthly benefit before run costs | $1,090 | $390 |
| Benefit basis | 29.4 hours at loaded rate | 10 overtime hours at $39 |
| Monthly run-cost allowance | $206.43 | $206.43 |
| Net monthly benefit | About $884 | About $184 |
| Payback on $9,000 build | 10.2 months | 49.0 months |
The cash calculation is 9000 / (390 - 206.428...) = 49.0 months. It retains the full run-cost allowance, including valued upkeep labor, making it conservative if that upkeep uses existing salaried capacity without extra spending. Reconcile actual payments separately when reporting cash flow.
The other hours need an assigned destination and an observable result. For example, Norrbeck could use capacity to pursue early-payment discounts, recording discounts actually received, or absorb additional invoice volume while tracking whether extra staffing was avoided. Neither benefit belongs in the cash column before evidence exists.
Humlum and Vestergaard's March 2026 revision, titled Still Waters, Rapid Currents, explains why this distinction deserves attention. Adopters reported saving about 3% of work hours, yet linked administrative records showed precise null effects on earnings and recorded hours, ruling out effects larger than 2%. Adopters' own earnings estimates were only 0% to 0.5%.
The shares overlap, so 85% reallocating time to other job tasks, about 30% spending more time on the same tasks and fewer than 10% taking more breaks or leisure sum to more than 100%. Productive time can move around inside a job without changing its paid hours.
What measured productivity studies permit you to assume
Published results justify measuring your workflow; they do not supply its saving rate. Tasks, worker skill and tool design differ enough that transferring a headline percentage into Norrbeck's spreadsheet would replace one assumption with another.
Support agents and consultants gained unevenly
The 2023 NBER working paper found 14% more chats resolved per hour across 5,179 support agents, rising to 34% for the lowest skill quintile. The tool suggested replies that agents could ignore, and the staggered rollout let agents awaiting access serve as the comparison. This was assistance inside a human workflow.
For the most skilled agents, resolution rate and customer satisfaction showed small but statistically significant drops. An average throughput gain therefore cannot stand in for a quality check by worker group. Norrbeck should retain clerk and invoice-type fields for the same reason.
In the randomized study of 758 BCG consultants, tasks inside the tested frontier saw 12.2% more tasks completed, 25.1% faster completion and more than 40% higher quality. Outside that frontier, correctness was about 84.5% for the control group versus 60% and 70% for the AI groups, an average drop of 19 percentage points. The frontier has likely moved since 2023; the need to test task suitability remains.
Developer timing and worker surveys measure different things
METR's 10 July 2025 developer study involved 16 experienced developers completing 246 issues in familiar repositories. They forecast being 24% faster with AI, took 19% longer when allowed to use it, and afterward believed they had been 20% faster. Perceived improvement and measured duration pointed in opposite directions.
METR marks those results as out of date. Its 24 February 2026 follow-up says developers are likely faster with late-2025 tools, but selection effects make that only very weak evidence of how much. Neither result establishes the current saving for invoice entry.
Bick, Blandin and Deming's February 2025 St. Louis Fed post originally reported that users saved 5.4% of work hours, equivalent to 1.4% across all workers including non-users, using a November 2024 survey. Respondents estimated how many extra hours their work would have taken without generative AI, so these are self-reported counterfactuals. The Fed later reweighted its 2024 surveys, and a November 2025 update puts time saved at 1.6% of all work hours, pooling surveys from February to August 2025.
The MIT NANDA 95% figure has a specific definition
The preliminary MIT NANDA business report says 95% of organizations are getting zero return. Its methods appendix defines success as deployment beyond pilot with measurable KPIs, with ROI measured six months post-pilot. It also acknowledges that organizations may define success differently.
The report draws on 52 interviews with representatives of 52 organizations, 153 survey responses collected at four industry conferences, and a review of more than 300 public AI initiatives. Treat it as a warning about pilots without demonstrated operational results, not a measured probability that your own project will fail. Norrbeck's decision needs its invoices, costs and observed handling paths.
Reproduce the calculations with Python
Save the following as roi.py and run python3 roi.py; it uses only the Python standard library. Changing any input line reruns every table's dependent calculations, although a changed pilot sample must also be reflected in the observation table.
import math, statistics as st

# Norrbeck Plumbing Supply (fictional). Every input is an assumption.
pilot = [3.1, 5.6, 2.8, 4.4, 6.9, 3.5, 2.6, 4.9, 3.8, 7.2, 3.3, 4.1]  # minutes per invoice, 12 timed
mean, sd = st.mean(pilot), st.stdev(pilot)
for e in (0.05, 0.10):  # margin of error as a share of the mean, 95% confidence
    n = math.ceil((1.96 * sd / (e * mean)) ** 2)
    print(f"pilot mean {mean:.2f} min, sd {sd:.2f}: n for +/-{e:.0%} = {n}")

invoices = 900          # per month
rate = 26 / 0.70        # $26/h wage, wages are about 70% of employer cost
rework_min = 18         # minutes to fix one invoice error found later
before = 4.20 + 0.031 * rework_min    # baseline: 4.20 min, 3.1% errors
control = 3.90 + 0.031 * rework_min   # holdout, same weeks, still manual
ai = 1.1 + 0.12 * (3.90 + 1.0) + 0.018 * rework_min  # review, 12% escalated, 1.8% errors
print(f"\nminutes per invoice: before {before:.3f}  control {control:.3f}  ai {ai:.3f}")
print(f"saving per invoice: naive {before - ai:.3f}  vs control {control - ai:.3f}")
audit = math.ceil(1.96 ** 2 * 0.018 * (1 - 0.018) / 0.01 ** 2)  # error rate within +/-1 point
print(f"invoices to audit for the 1.8% error rate, +/-1 point: {audit}")

build, run = 9000, 89 + 6 + 3 * rate  # one-off build; platform + model + 3 h upkeep per month
print(f"loaded rate ${rate:.2f}/h, run cost ${run:.2f}/month\n")
print("adoption  hours/mo  value/mo  net/mo  payback mo  12-mo ROI")
for share in (1.0, 0.8, 0.6, 0.4, 0.2):
    hours = invoices * share * (control - ai) / 60
    net = hours * rate - run
    payback = f"{build / net:10.1f}" if net > 0 else "     never"
    roi = (12 * hours * rate - (build + 12 * run)) / (build + 12 * run)
    print(f"{share:7.0%}  {hours:8.1f}  {hours * rate:8.0f}  {net:6.0f}  {payback}  {roi:9.0%}")

hours = invoices * 0.8 * (control - ai) / 60   # planning case: 80% adoption
cash = 10 * 26 * 1.5                            # 10 overtime hours/month no longer paid
print(f"\nat 80%: {hours:.1f} h/month freed, cash saved ${cash:.0f}/month (overtime)")
print(f"cash payback: {build / (cash - run):.1f} months")
The output preserves unrounded values internally, so displayed rounded amounts should not be fed back into the formulas. Negative first-year ROI can coexist with positive monthly benefit because the initial build has not yet been recovered.
pilot mean 4.35 min, sd 1.53: n for +/-5% = 190
pilot mean 4.35 min, sd 1.53: n for +/-10% = 48

minutes per invoice: before 4.758  control 4.458  ai 2.012
saving per invoice: naive 2.746  vs control 2.446
invoices to audit for the 1.8% error rate, +/-1 point: 680
loaded rate $37.14/h, run cost $206.43/month

adoption  hours/mo  value/mo  net/mo  payback mo  12-mo ROI
   100%      36.7      1363    1156         7.8        42%
    80%      29.4      1090     884        10.2        14%
    60%      22.0       818     611        14.7       -15%
    40%      14.7       545     339        26.6       -43%
    20%       7.3       273      66       136.1       -72%

at 80%: 29.4 h/month freed, cash saved $390/month (overtime)
cash payback: 49.0 months
Keep an observable monthly measurement record
Assign someone to reconcile workflow logs with accounting corrections and actual spending. Retain counts beside percentages so a quiet month cannot masquerade as an improvement.
- Review minutes: retain open and submit timestamps, or time at least 30 reviews weekly and record the sample size.
- Escalations: count escalated invoices against all invoices entering AI, retaining the reason and additional handling minutes.
- Rework: link downstream corrections to original routing, with correction minutes and equal follow-up windows.
- Adoption: divide AI-path invoices by all eligible invoices and record why the remaining invoices stayed manual.
- Quality differences: report corrections by invoice type and clerk, with each group's denominator.
- Control results: retain manual and AI-path minutes from the same holdout weeks, noting concurrent supplier changes.
- Financial realization: reconcile removed overtime payments, run invoices and upkeep hours; assign any remaining freed capacity to named work.
If you need the automation built and run with these measurements, Iron Goo's operations service can include human review and monthly reports on escalations and what changed. Specify review minutes and downstream rework in the reporting requirements so the next month's ROI calculation has observable inputs.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.