
AI Automation for Small Businesses
The flagship pillar. How small and mid-sized businesses adopt AI in real operations: agents, automation, chatbots, and the discipline to run them.

Foundations
Building Your First Automation
The Operations Automation Playbook
AI automation for small business is a triggered business process with at least one step where a language model reads, classifies, extracts, writes or decides, with ordinary code handling the surrounding work. Once that model step enters the process, reliability becomes a rate you measure. Anthropic recommends starting with the simplest workable solution, which can mean a single model call inside a fixed workflow.
Consider a hypothetical operation triaging 3,000 emails a month: the model costs about $0.45 at a cache-hit baseline, against $129 for the platform and $199.94 for human review. Those assumptions use prices read on 23 October 2026; they are a worked example, not a price promise. The model is the smallest line on that bill. Choosing it carefully matters, but most of the work and money sit around it.
One job has four parts: JOB, MODEL STEP, CHECK, RECORD
The model I use has four parts, with the language model occupying only one. For an owner or operations lead at a company of 10 to 200 people, this gives each problem somewhere specific to go: scope belongs to the job, retrieval belongs around the model step, permission belongs to the check, and evidence belongs in the record.
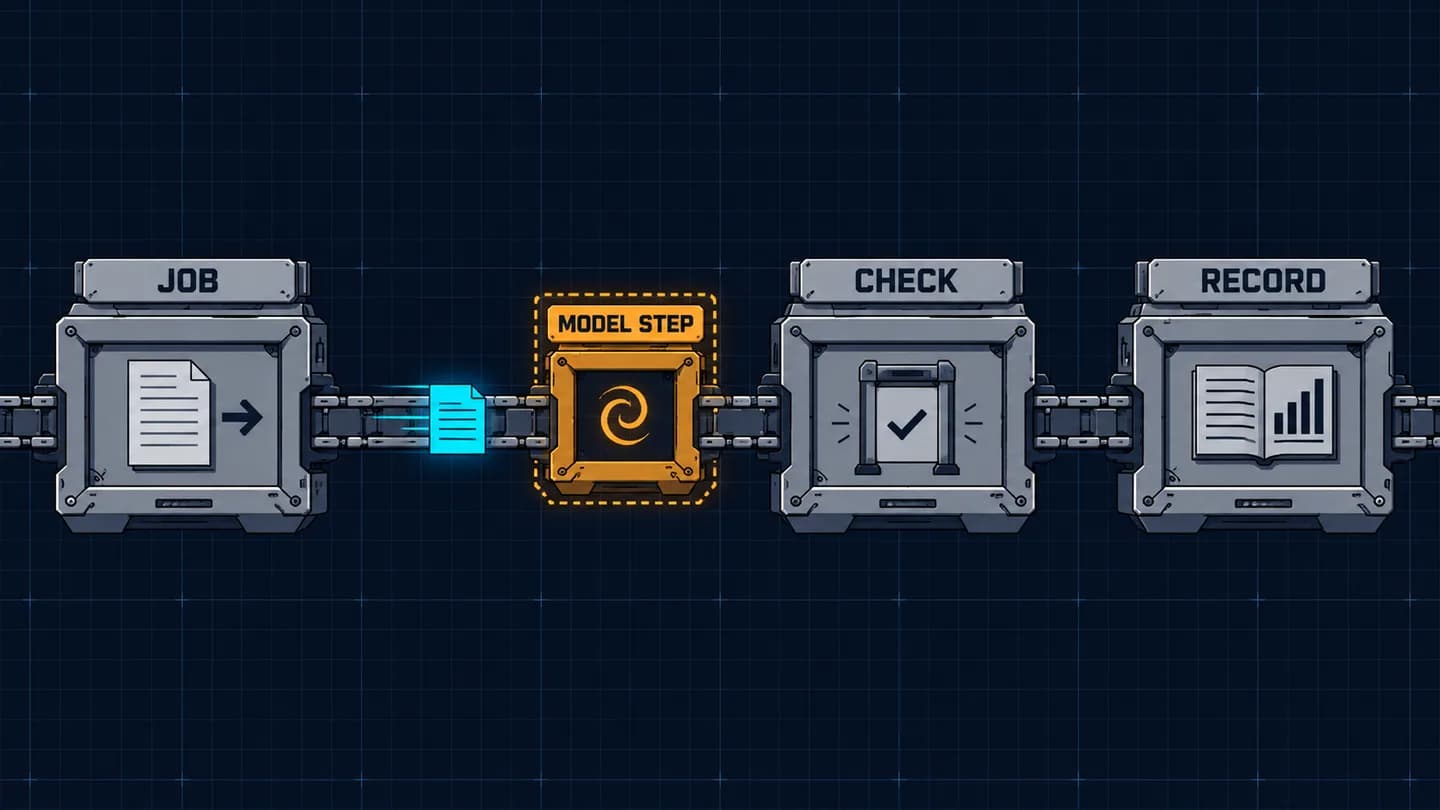
Notice how little of the chain belongs to the model. The surrounding parts define the work, control what happens and preserve the evidence needed to judge it.
- JOB: Specify the trigger, bounded scope and permitted actions, including where the job starts and finishes. Measure its baseline: volume, human minutes per item and the cost of an error.
- MODEL STEP: Give the language model the smallest language problem that needs solving, grounded on your business data. This is the probabilistic part, and model retirements or routing changes let a vendor change the answering model without you editing the workflow.
- CHECK: Validate required fields, allowed values and business rules in code. Restrict actions and spending, cap turns, and require human approval wherever mistakes are costly or irreversible.
- RECORD: Log which model answered, rerun evaluations when something changes, and measure results against the baseline. Keep cash savings separate from the value of freed capacity.
Keep the model step as small as the language problem. If an email needs a department label, ask for a department label; control subsequent actions through code. My operating rule is to fix a problem in the part where it lives: a better model cannot repair a missing document, a missing check or a missing baseline.
If you are choosing a first automation
Start at JOB, because a product demonstration does not establish which process deserves your budget. Follow the selection sequence before committing to a platform.
- How to Choose Your First AI Use Case: Four Gates settles which candidate survives the gates for weekly human hours, error cost, labeled examples and a measurable baseline, in that order, before you apply the score.
- AI automation use cases for small business: 19 job cards settles which jobs are plausible early investments at your volume and which human checkpoint each needs before its output becomes an action.
- AI readiness checklist for one job at a time settles whether the selected job passes our MUST requirements for a pilot, with any failed MUST stopping that job until the gap is addressed.
If you have a scored, bounded job and want someone else to build and run it, Iron Goo’s operations service provides scoped credentials, audit logging and human review. Bring the defined output and its judge; those give the implementation something testable to deliver.
If it is live and the output is drifting
Start at MODEL STEP, then inspect the surrounding evidence before changing a prompt. A successful request and a successful business task are separate events, so your investigation needs records of both.
- LLM monitoring in production: Retirements, evals and caps settles how to maintain a retirement calendar, compare requested and answering models, and detect task failures hidden inside successful HTTP responses.
- RAG pipeline architecture with defaults you can test settles how to investigate grounding, using our troubleshooting priority of inspecting ingestion, chunking, embeddings, the vector store and retrieval before changing the answering model.
- AI guardrails for eight production failures settles which detection signal and restriction fit a failure, including how to test whether a reviewer actually catches mistakes.
That retrieval sequence is a diagnostic priority, not a measured distribution of causes. Calendar checks also deserve an owner: OpenAI’s deprecation policy says preview models may retire with much shorter notice, such as two weeks. A model name in a configuration file is not a maintenance plan.
If the board, a client or an insurer asks about risk
Start at CHECK, identifying who may authorize actions and who can stop them. For a company this size, written decisions need a named owner with enough authority to enforce them.
- What Is AI Automation? Definition, Myths and Evidence settles which architecture you are buying by asking who chooses the next step, and what the widely repeated 95% figure actually measured.
- AI Governance for Small Business settles the five written records you need: an acceptable-use policy, tool inventory, data-to-tool rule, dated vendor sheet and incident runbook, with one owner who can say no.
- Build vs buy AI automation: 6 options, dated price matrix settles who builds and operates the job, where its data sits, and what actually transfers when you leave the supplier.
The preliminary MIT NANDA report behind the 95% claim concerns self-reported sustained productivity or profit-and-loss impact from task-specific enterprise GenAI tools. Its interview-based findings are directional; they do not establish a technical failure rate for AI projects generally. Ask for evidence about the proposed job before treating that percentage as a forecast.
If you need to prove the automation paid off
Start at RECORD, collecting the costs and work results that make a comparison possible. A time-saving claim needs a timed baseline, and a cash-saving claim needs spending that actually stops.
- How Much Does AI Automation Cost? Every Line Item settles the full monthly receipt, including why the hypothetical email job reaches $529.44 with cache writes and maintenance, alongside an assumed $7,400 build.
- How to measure AI ROI from baseline to cash payback settles how to compare a timed baseline with a same-weeks manual holdout, include review minutes and report cash payback separately from capacity payback.
- AI change management that gets tools used settles why staff with licenses may leave a tool unused and how to read usage separately from satisfaction and work results.
Agree on what counts as a completed item before comparing the two paths. An invoice extracted but waiting for correction still consumes work, and a free hour only becomes cash savings when an identifiable expense disappears.
Write one candidate job and count the work
- →Name the action, output and judge
Write a job such as route inbound email to a team, with a team label as the output. Name the person who can judge whether that label is correct.
- →Calculate weekly human hours
Use items per week × minutes per item ÷ 60. For a hypothetical queue of 600 emails taking 1.5 minutes each, the baseline is 15 human hours a week.
- →Count labeled past examples
Count past items with outputs the named judge accepts as correct. Under 5 human hours a week or under 50 labeled examples, park the candidate or combine genuinely related work; these are our working conventions, not research findings.
Ready to move?
Tell us where your business is today. A written assessment lands in your inbox within two business days.
Talk to us