How to Choose Your First AI Use Case: Four Gates

On this page
AI & Automation
You run a company of 10 to 200 people, have six suggested jobs for AI, and have budget for one. Here is how to choose an AI use case: pick the job that passes four gates and scores highest. Start with weekly human hours: items per week × minutes per item ÷ 60. Routing 600 emails at 1.5 minutes each consumes 15 hours a week, enough to investigate before buying anything.
The four gates are hours, error cost, labeled examples, and a measurable baseline, applied in that order. Then score the survivors and test the winner on real past work. Every selection threshold here is our working convention, not a research finding or a promise of return.
Four gates before you rank the jobs
Write each candidate as an action with an output: “route inbound email to a team” is testable; “improve communication” is not. Name the person who can judge that output and own the process after launch.
- →1. Count at least 5 human hours a week
Multiply items per week by current minutes per item, then divide by 60. Our first-build threshold is 5 hours a week: below that, park the job or combine it with a related process and recalculate.
- →2. Classify the consequence of one mistake
Use class A, B, or C, based on who sees the error and whether it can be undone. Class C fails as autonomous work: reframe it as an assist with human approval on every item, or park it.
- →3. Find at least 50 labeled past examples
Count inputs paired with known correct outcomes, not files sitting in a folder. Under our 50-example threshold, collect a test set before proceeding; a prompt does not remove the need to test.
- →4. Establish a baseline and definition of done
Use existing logs or time 30 real items, our quick measurement convention. If the baseline is only a guess, measure it before testing; if nobody can define a correct output, park the job and write that definition first.
The hours gate measures the size of the opportunity, not the hours AI will save. Ten to twenty hours a week is our preferred first-project band because there is room for a useful gain after review time; above twenty, plan for changes to someone’s responsibilities.
A low-volume monthly report can feel more burdensome than hundreds of small entries. Count both before making the choice. Annoyance is useful evidence about staff morale, but it is a poor unit of arithmetic.
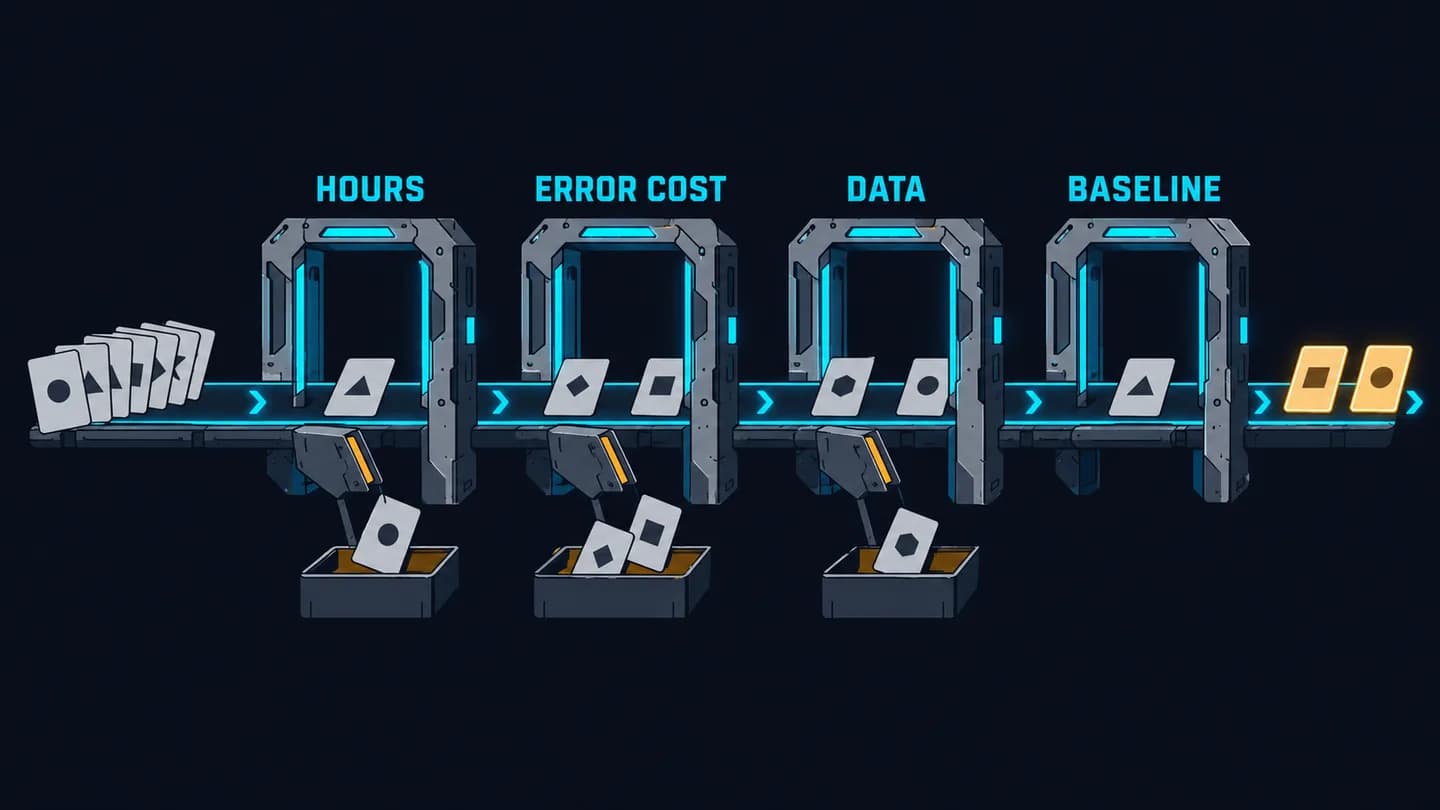
Apply the gates in order. Most candidates in the worked example need repair or a different scope before they reach scoring as eligible first projects.
Error classes separate visibility from reversibility
Class A means the mistake stays inside the company and can be undone in minutes. A misrouted internal email qualifies if someone can move it to the correct queue without losing the request.
Class B means the mistake reaches a supplier, customer, or ledger but remains reversible before financial loss. An incorrect invoice entry reviewed and corrected before the payment run belongs here. The workflow must enforce that review; a policy alone does not establish the control.
Class C means an irreversible or regulated consequence, such as a binding price sent to a customer. It can enter the shortlist only as an assist where a human approves every item before the consequential action. Use the human approval and guardrails guidance to place that control; park the job if its remaining risk is unsuitable for a first project.
Reclassifying a class C job to B requires a changed workflow that makes errors reversible before commitment. Calling the quote sender an “assistant” changes nothing; blocking every send until a salesperson approves the item changes the error path.
Labeled examples mean inputs with defensible answers
A labeled example contains the original input and an outcome a knowledgeable person accepts as correct. For routing, that might be an email and its verified destination; for invoices, the source document and approved accounting fields.
Our bands start at 50 examples, with 200 to 999 offering more material for prompt tuning and separate testing. At 1,000 or more, you have more room to inspect errors by category, although rare categories may still be poorly represented. These are planning conventions, not minimum training requirements: a prompted model need not be trained on your records.
A baseline records time and acceptable output
Record current handling time and whether each output meets a written definition of done. For invoice entry, that definition might require matching the supplier, invoice number, currency, total, and accounting destination before approval.
“Measured” means the system already logs usable data, such as accounts-payable timestamps. “Measurable” means you can time real items now; “rough” means you have only an estimate; “none” means the output itself lacks an agreed definition. Follow the automation ROI baseline method to establish the before number.
A rough baseline is a repairable weakness, not permission to skip measurement. If most candidates lack usable examples or agreed outcomes, work on company-wide AI readiness before debating which candidate wins.
Score five criteria using explicit bands
Use this AI use case scoring matrix after the gates. All bands are our conventions; the scores express a first-project preference, not a probability of success.
| Criterion | 0 points | 1 point | 2 points | 3 points |
|---|---|---|---|---|
| H: human hours/week | Under 5 | 5 to under 10 | 10 to under 20 | 20 or more |
| R: repeat share | Under 40% | 40% to under 60% | 60% to under 80% | 80% or more |
| E: error class | C | Unused | B | A |
| D: labeled examples | Under 50 | 50 to 199 | 200 to 999 | 1,000 or more |
| B: baseline | None | Rough | Measurable | Measured |
For repeat share, inspect 30 recent items and count how many followed the same written steps without a judgment call. That sample size is our quick-check convention, not a statistical guarantee. Below 40%, park or split the job into a routine portion and an exception queue.
Any zero means park the current design. With no zeros, a total of 11 or more earns “start here,” subject to the real-item test; lower totals mean fix the weakest criterion and rescore. Break ties by lower error cost, then prefer work where newer staff can benefit from documented expert practice.
An impact effort matrix can help display the shortlist, but “high impact” needs units. Hours provide those units; example availability and repeatability help expose implementation difficulty. Estimate build and operating costs separately before committing money, because this score does not calculate payback.
What measured studies imply for your shortlist
Customer support gains depended on skill and an assist design
The 2023 NBER working paper on customer support found that access to an assistant increased chats resolved per hour by 14% on average among 5,179 agents at one software company. Agents in the lowest skill quintile gained 34% on that measure.
The most skilled agents had no productivity gain, alongside small but statistically significant drops in resolution rate and customer satisfaction. This supports prioritizing repeat work where less skilled employees can use established practice. It gives little reason to assume your best expert’s hardest task will improve.
The GPT-family tool was further trained on the firm’s conversations labeled with outcomes. It suggested replies that agents could ignore and withheld suggestions where it lacked sufficient training data. That is the human-controlled assist design required here for consequential work, although the study does not establish the safety of any particular class C process.
The caveat is one firm, one task type, and an earlier model generation. For planning, treat an assist as a possible partial improvement in the job’s time; 15 existing hours do not become 15 saved hours because the interface has a chat box.
GPT-4 helped inside its frontier and harmed accuracy outside it
The BCG and Harvard experiment randomized 758 consultants across control and AI conditions. On tasks inside the model’s capabilities, AI users completed 12.2% more tasks, worked 25.1% faster, and produced work rated more than 40% higher in quality.
On a deliberately selected outside-frontier task, control participants were about 84.5% correct, while the two AI groups were 60% and 70% correct. The working paper reported an average decline of 19 percentage points. Plausible assistance can make the answer worse.
The experiment used GPT-4 in 2023, selected consultants, and researcher-designed tasks. The frontier has likely moved since 2023; use the testing method, not its task list as a permanent catalog of what AI can do.
METR measured a gap between feeling faster and finishing faster
In METR’s randomized developer study, 16 experienced open-source developers worked on 246 real issues in repositories they knew. They expected a 24% speedup beforehand and believed afterward that AI had made them 20% faster, but measured completion time increased by 19%.
METR marks the 2025 results as out of date. Its 24 February 2026 follow-up says developers are likely faster with late-2025 tools, but selection effects, including developers declining to work without AI, make this only very weak evidence of how much faster. The small earlier sample does not establish that AI slows most developers; the gap between perceived and measured speed shows why perceived speed is an inadequate baseline.
The MIT NANDA figure uses a specific success definition
MIT NANDA’s The GenAI Divide: State of AI in Business 2025 reported that 95% of organizations were getting zero return. Its evidence included review of more than 300 public initiatives, 52 structured interviews, and surveys of 153 senior leaders at four industry conferences.
The report’s methods appendix defines success as deployment beyond pilot with measurable KPIs, with ROI measured six months post-pilot. The report calls itself preliminary and says success definitions may differ across organizations. The small interview and conference-recruited samples limit generalization. Treat the figure as a warning to define deployment and measurable benefit, not a measured failure rate for every AI automation.
Test 20 to 30 real items before committing
Take 20 to 30 past items with known correct outcomes and run the proposed tool on them. Our acceptance convention is about eight in ten outputs needing no edits; below that, split the task, repair the inputs, or park the design.
Reserve these items from prompt tuning, include routine exceptions, and have the process owner grade against the written definition of done. Record correction time as well as acceptance, because an output that takes longer to repair than to produce has failed the practical test.
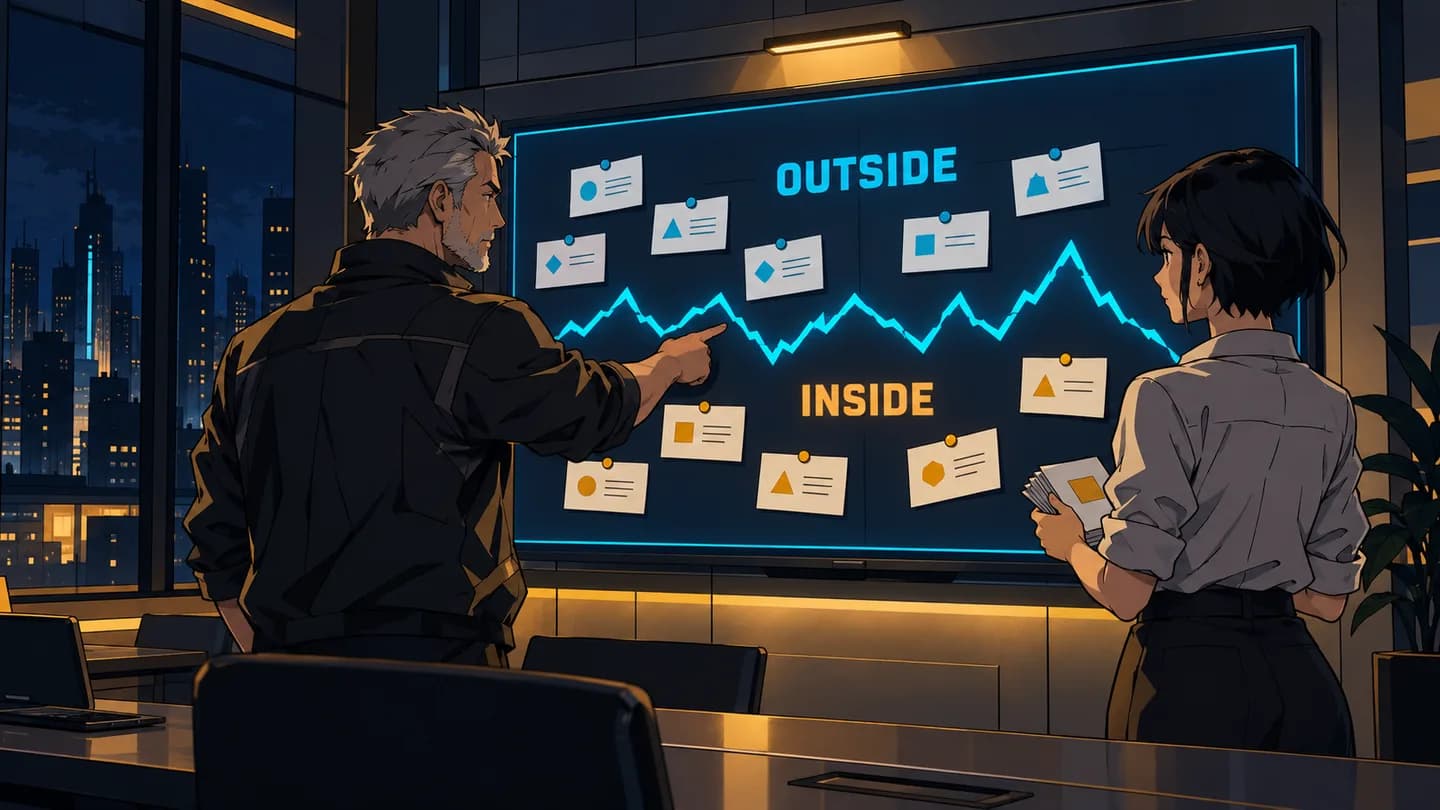
Apparent difficulty does not reliably locate a task inside the model’s capabilities. Test your actual items before committing to the workflow.
Eight in ten is a screening threshold, not an acceptable error rate for releasing money or binding prices. A passing assist still requires every approval promised by its design. Run a timed trial with that review included before calculating savings.
Six jobs at a lighting distributor, with every input shown
Halvorsen Fixtures is an openly fictional, 60-person commercial lighting distributor. Every input here is an assumption; repeat shares are approximate planning estimates for the proposed 30-item review, not exact observed fractions.
| Job | Items/week | Minutes/item | Hours/week | Repeat share | Error class | Labeled examples | Baseline |
|---|---|---|---|---|---|---|---|
| Route inbound email | 600 | 1.5 | 15 | 85% | A | 5,000 | Measurable |
| Key supplier invoices | 180 | 4 | 12 | 90% | B | 9,000 | Measured |
| Draft quotes from RFQs | 40 | 25 | 16.7 | 50% | C | 800 | Measurable |
| Write new SKU descriptions | 30 | 20 | 10 | 70% | A | 400 | Rough |
| Monthly sales commentary | 0.25 | 180 | 0.75 | 30% | A | 12 | Rough |
| Approve warranty claims | 25 | 15 | 6.25 | 40% | C | 30 | Measurable |
Email labels are assumed verified from mailbox folders; invoice entry is reviewed before payment; SKU copy stays internal until publication approval. Quotes currently include sending a binding price, and warranty approval can release money. Monthly commentary is one report a month, entered as 0.25 items per week so it shares the weekly unit.
Only email routing and invoice entry clear the gates without repair. Scoring all six is still useful diagnostically: zeros show why a current design is parked, while a rough baseline identifies work needed before testing.
Run the CSV and Python scoring template
Save these inputs as candidates.csv.
job,items_per_week,minutes_per_item,repeat_share,error_class,labeled_examples,baseline
Route inbound email,600,1.5,0.85,A,5000,measurable
Key supplier invoices,180,4,0.90,B,9000,measured
Draft quotes from RFQs,40,25,0.50,C,800,measurable
Write new SKU descriptions,30,20,0.70,A,400,rough
Monthly sales commentary,0.25,180,0.30,A,12,rough
Approve warranty claims,25,15,0.40,C,30,measurable
Save this as score.py and run python3 score.py candidates.csv with Python 3; it uses only the standard library.
import csv, sys

def hours_score(h):
    return 0 if h < 5 else 1 if h < 10 else 2 if h < 20 else 3

def repeat_score(r):
    return 0 if r < 0.4 else 1 if r < 0.6 else 2 if r < 0.8 else 3

ERROR = {"A": 3, "B": 2, "C": 0}  # A internal and reversible, B reversible but seen outside, C irreversible or regulated

def data_score(n):
    return 0 if n < 50 else 1 if n < 200 else 2 if n < 1000 else 3

BASELINE = {"measured": 3, "measurable": 2, "rough": 1, "none": 0}

rows = []
for r in csv.DictReader(open(sys.argv[1])):
    hours = float(r["items_per_week"]) * float(r["minutes_per_item"]) / 60
    s = [hours_score(hours), repeat_score(float(r["repeat_share"])), ERROR[r["error_class"]],
         data_score(int(r["labeled_examples"])), BASELINE[r["baseline"]]]
    total = sum(s)
    if 0 in s:
        verdict = "park"
    elif total >= 11:
        verdict = "start here"
    else:
        verdict = "fix weakest, rescore"
    rows.append((r["job"], hours, s, verdict))

print(f"{'job':28} {'hrs/wk':>6}  H R E D B  total  verdict")
# rank: parked jobs last, then total, then the lower error cost wins a tie
for job, hours, s, verdict in sorted(rows, key=lambda x: (0 in x[2], -sum(x[2]), -x[2][2])):
    print(f"{job:28} {hours:6.1f}  {' '.join(map(str, s))}  {sum(s):5}  {verdict}")
Compare your terminal output with this exact result. The script prints one decimal place, so it shows 6.2 and 0.8 where the inputs table shows 6.25 and 0.75.
job                          hrs/wk  H R E D B  total  verdict
Route inbound email            15.0  2 3 3 3 2     13  start here
Key supplier invoices          12.0  2 3 2 3 3     13  start here
Write new SKU descriptions     10.0  2 2 3 2 1     10  fix weakest, rescore
Draft quotes from RFQs         16.7  2 1 0 2 2      7  park
Monthly sales commentary        0.8  0 0 3 0 1      4  park
Approve warranty claims         6.2  1 1 0 0 2      4  park
For Excel or Google Sheets, paste the CSV text into column A and use Split text to columns in Google Sheets or Text to Columns in Excel to populate columns A through G, then enter each formula in its named cell and fill down; in locales using a comma as the decimal separator, values like 0.85 will not parse as numbers.
H2  =B2*C2/60
I2  =IF(H2<5,0,IF(H2<10,1,IF(H2<20,2,3)))
J2  =IF(D2<0.4,0,IF(D2<0.6,1,IF(D2<0.8,2,3)))
K2  =IF(E2="A",3,IF(E2="B",2,0))
L2  =IF(F2<50,0,IF(F2<200,1,IF(F2<1000,2,3)))
M2  =IF(G2="measured",3,IF(G2="measurable",2,IF(G2="rough",1,0)))
N2  =SUM(I2:M2)
O2  =IF(MIN(I2:M2)=0,"park",IF(N2>=11,"start here","fix weakest, rescore"))
The sheet scores an unknown error class or baseline word as 0, while the script stops with a KeyError.
Email routing and invoice entry both score 13. Routing wins on lower error cost: its E score is 3 against invoice entry’s 2, even though invoices have a better baseline.
SKU descriptions score 10, so measure the current workflow before reconsidering them. Monthly commentary fails hours, repetition, and examples; warranty approval fails error cost and examples. Neither becomes a good first project through a more enthusiastic prompt.
The quote job deserves a scope change: sales must approve every quote before sending. Assuming that control makes errors reversible before commitment, the assist becomes class B, raising E from 0 to 2 and the total from 7 to 9.
Its revised verdict is “fix weakest, rescore.” Repetition is the weakest criterion at 1; separate standard RFQs from requests needing bespoke commercial judgment, then remeasure the narrower job’s volume and repeat share. Do not retain the original hours after removing work from scope.
Choose the next action from the result
For Halvorsen, the next action is to time email routing and test its outputs, with invoice entry held second. A scored winner earns a bounded trial, not an immediate autonomous deployment.
If you want the winning workflow built and operated with human review, Iron Goo’s operations service can take the defined job into implementation. Bring the sample inputs, score, and approval boundary so the work starts from an observable process.
| Situation or result | What to do next |
|---|---|
| Under 5 human hours per week | Park it or combine related work, then recalculate volume and time. |
| Class C consequence | Require human approval on every item; park it if the assist still carries unsuitable risk. |
| Fewer than 50 labeled examples | Collect inputs with verified outcomes before testing. |
| Nobody can define correct output | Write the definition of done before choosing a tool. |
| Baseline is rough | Time current work and record quality before the AI trial. |
| Any score is zero | Park the current design; repair that criterion before ranking it as eligible. |
| No zeros, total below 11 | Fix the weakest criterion and rescore the actual revised scope. |
| Eligible candidates tie | Choose lower error cost; if still tied, prefer suitable work done by newer staff. |
| Total at least 11 | Test 20 to 30 held-out real items against known outcomes. |
| Fewer than about eight in ten need no edits | Split the task, repair inputs, or park it; repeat the test after a material change. |
| Test passes with required approvals | Run a timed trial including review and correction, then price the build against measured savings. |

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.