How Much Does AI Automation Cost? Every Line Item

On this page
- Model prices belong beside the token counts
- How many tokens is a word in an email or invoice?
- Platform pricing changes what one item costs
- Receipt 1: inbound email triage at 3,000 emails per month
- Receipt 2: invoice extraction at 1,500 invoices per month
- Receipt 3: a support chatbot at 2,000 conversations per month
- Where the cost curve bends with volume
- Maintenance costs arrive as events on a calendar
- Agency prices are asking prices with weak market evidence
AI & Automation
AI automation usually costs more for human review and the workflow platform than for the model: a hypothetical 3,000-email monthly workload has a $0.45 cache-hit model baseline, a $129 platform subscription and $199.94 of review time. Those lines have a ratio of roughly 1:287:444. How much does AI automation cost once you include cache writes and maintenance? The email receipt here totals $529.44 per month, plus an assumed $7,400 build.
Your bill depends on how many items reach a person, which platform actions are billable and what someone must maintain. Model selection still deserves testing, but saving half of a fifty-cent model bill has limited career potential.
Model prices belong beside the token counts
These prices were read on 23 October 2026. They are a dated snapshot: check the vendor page before relying on them, including the exact model identifier and billing tier.
All entries are US dollars per one million tokens at standard rates. Cached input is a separate category, and its price does not include cache writes or storage.
| Provider and model | Input, USD/1M tokens | Cached input, USD/1M tokens | Output, USD/1M tokens |
|---|---|---|---|
OpenAI gpt-6-luna | $0.10 | $0.01 | $0.50 |
OpenAI gpt-6.1-sol | $2.00 | $0.10 | $10.00 |
OpenAI gpt-6-astra | $10.00 | $1.00 | $50.00 |
| Claude Haiku 5.5, prompts up to 100,000 tokens | $0.10 | $0.01 | $0.50 |
| Claude Sonnet 5.5 | $2.00 | $0.10 | $10.00 |
| Claude Opus 5.5 | $4.00 | $0.20 | $20.00 |
| Gemini 2.5 Flash-Lite | $0.10 | $0.01 | $0.40 |
| Gemini 3.1 Flash-Lite | $0.25 | $0.025 | $1.50 |
| Gemini 3.5 Flash-Lite | $0.30 | $0.03 | $2.50 |
| DeepSeek Flash, peak | $0.30 | $0.006 | $1.20 |
| DeepSeek Flash, off-peak | $0.15 | $0.003 | $0.60 |
The receipts use OpenAI's API prices, with comparisons against Anthropic's model pricing and Google's Gemini pricing. OpenAI, Anthropic and Google batch services halve standard token prices. DeepSeek has no batch tier; its separate off-peak window provides the discount.
Caching needs its own calculation. OpenAI GPT-5.6 and later charge 1.25 times normal input for default 30-minute cache writes, or 2.5 times for 12-hour retention; automatic caching starts at 1,024 tokens. Claude requires cache_control, with a 512-token minimum on most Claude 5.x models, but 1,024 tokens on Claude Sonnet 5.
Claude's five-minute writes cost 1.25 times base input, and one-hour writes cost twice base input. Gemini also charges $1.00 per million cached tokens per hour for storage. A cheap cache read is useful only when something actually reads the cache.
cost_per_item = (uncached_input_tokens * input_rate + cached_input_tokens * cached_rate + output_tokens * output_rate) / 1000000 + (cache_write_cost + platform + hosting + monitoring + review_labor + maintenance) / monthly_items
Use USD-per-million-token rates in that formula. Cache-write tokens belong in cache_write_cost, so exclude them from the ordinary input categories to avoid counting them twice.
How many tokens is a word in an email or invoice?
The familiar English estimate is approximately 0.75 words per token, or 1.33 tokens per word. That is a starting estimate for prose, with poor predictive value for invoice references and JSON.
A small illustrative measurement using tiktoken 0.14.0 and o200k_base produced these results on purpose-written samples. They describe those samples, not an average across business documents.
| Sample | Whitespace-separated words | Tokens | Tokens per word |
|---|---|---|---|
| Business email with references | 173 | 246 | 1.42 |
| Invoice rendered as text | 139 | 343 | 2.47 |
| Schema instruction with two examples | 169 | 371 | 2.20 |
| JSON output | 30 | 145 | 4.83 |
Numbers, punctuation and identifiers split differently from ordinary words. Counting JSON by words is especially unhelpful because whitespace determines the apparent word count.
Count 20 representative items before budgeting. Include long email threads and the invoices that make your accounting team sigh; the demonstration document is rarely the expensive one.
from pathlib import Path
import tiktoken

text = Path("invoice.txt").read_text()
encoding = tiktoken.get_encoding("o200k_base")

print({
    "words": len(text.split()),
    "tokens": len(encoding.encode(text)),
})
Use the selected provider's token counter for the final estimate, then reconcile it against response usage fields. Anthropic says its Claude 4.7 and later tokenizer produces approximately 30% more tokens for the same text than earlier Claude models; counts from one tokenizer do not automatically transfer to another.
Platform pricing changes what one item costs
A workflow run is not a universal billing unit. Three successful actions can mean three Zapier tasks, roughly three ordinary Make credits or one n8n execution.
| Platform | Billing unit | Subscription basis |
|---|---|---|
| Zapier | Successful billable action; AI model tier, code runtime and connector type can change consumption | 750 tasks: $19.99/month; 10,000: $129/month; 100,000: $489/month, all annual-billing rates |
| Make | Most ordinary module actions use one credit; provider-managed AI can consume credits by token | Reported Core price around $9/month annually for 10,000 credits, unconfirmed |
| n8n Cloud | One execution is a run of the entire workflow, regardless of step count | Starter: EUR 20/month annually for 2,500 executions; Pro: EUR 50/month annually for 10,000 |
Zapier triggers and utilities such as Filter, Formatter, Paths and Delay do not count as tasks. Failed actions do not count either; an MCP tool call uses two tasks, while Code by Zapier runtime beyond 30 seconds on Pro and Team adds a task per additional 30-second block.
Every Zapier receipt here assumes the AI action calls the model vendor directly with your own API key and consumes one task. AI by Zapier can consume several tasks depending on model tier, so substituting that action changes the calculation.
The selected Zapier line is a tier covering each example's volume. Price the smallest tier covering your actual monthly task count on Zapier's pricing page, then compare billing cycles: the 10,000-task tier is $193.50 per month when billed monthly, versus $129 per month annually.
Zapier over-limit tasks carry a higher per-task rate depending on plan and billing cycle. Usage stops at three times the plan's task limit, so overage is not an unlimited capacity arrangement.
Make's credit rules are documented in its Credits help page, but its pricing page could not be read. Its reported free allowance of 1,000 credits per month is unconfirmed, as are reported annual-billing prices around $16 per month for Pro and $29 per month for Teams; these are planning clues, not confirmed quotes.
Is self-hosted n8n free?
Self-hosted n8n Community Edition has a free license for internal use under the Sustainable Use License. The n8n license FAQ restricts hosting n8n as a service where clients build workflows.
The server and its operator still cost money. Hetzner lists Regular Performance shared-vCPU hosting from EUR 6.49 per month excluding VAT; backups and suitable capacity still need specifying.
For a hypothetical EUR 45 hourly internal engineering cost, one upkeep hour makes that EUR 51.49 per month. Compare that with n8n Cloud Pro's EUR 50 monthly annual-billing rate using cloud_fee > server_fee + upkeep_hours * hourly_rate; your upkeep assumption decides the result.
Receipt 1: inbound email triage at 3,000 emails per month
Assume a company routes 3,000 inbound emails monthly. Each request uses a 1,500-token shared instruction prefix, a 600-token email and a 150-token JSON response.
On GPT-6-Luna, perfect cache hits cost $0.000150 per email: (600 × $0.10 + 1,500 × $0.01 + 150 × $0.50) / 1,000,000. That produces the $0.45 monthly benchmark in the opening, before cache writes.
For the actual receipt, assume 300 prefix writes and 2,700 prefix reads during the month. This is a budgeting assumption about traffic timing, not a promised cache-hit rate.
| Monthly line | Every input | Monthly cost, USD |
|---|---|---|
| Email input | 3,000 × 600 tokens × $0.10/1M tokens | $0.18000 |
| Prefix cache reads | 2,700 × 1,500 tokens × $0.01/1M tokens | $0.04050 |
| Default prefix cache writes | 300 × 1,500 tokens × $0.125/1M tokens | $0.05625 |
| JSON output | 3,000 × 150 tokens × $0.50/1M tokens | $0.22500 |
| Zapier tier covering 9,000 tasks | 3,000 emails × 3 actions; 10,000-task annual-billing tier | $129.00 |
| Low-confidence review, assumed | 3,000 × 12% × 45 seconds / 3,600 × $30.76/hour | $138.42 |
| Spot audit, assumed | 3,000 × 2% × 2 minutes / 60 × $30.76/hour | $61.52 |
| Maintenance allowance, assumed | 2 hours/month × $100/hour | $200.00 |
| Monthly operating total | Rounded after addition | $529.44 |
The three platform actions are the vendor API call, a label or move, and a CRM or messaging post. This receipt assigns review and audit time separately, so an audited exception can consume both allowances.
The $30.76 hourly labor assumption comes from the US Bureau of Labor Statistics customer-service median wage of $21.53 per hour divided by 0.70. That loading uses the June 2026 private-industry wage share of total compensation; it is a broad estimate, not your company's payroll calculation.
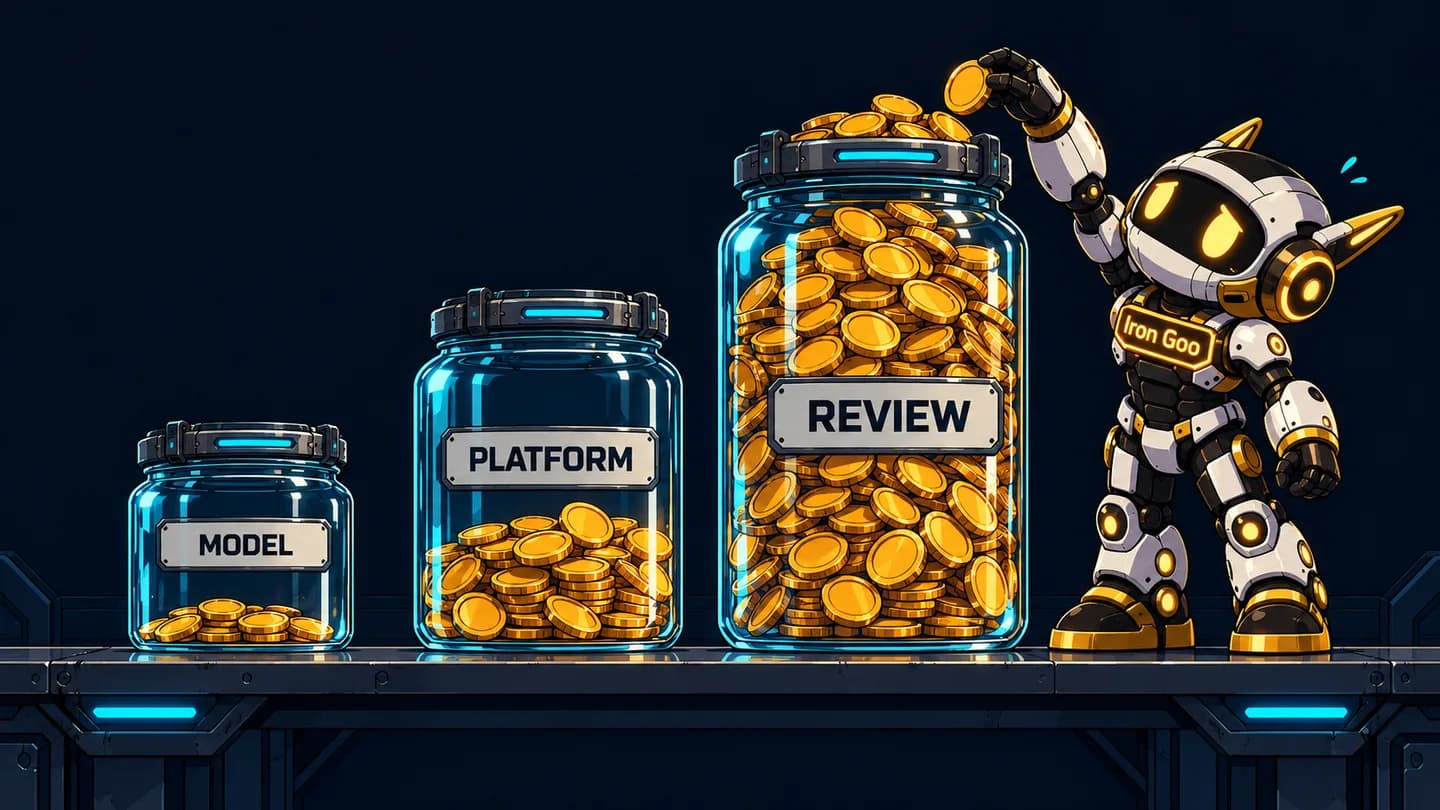
The $0.45 cache-hit model benchmark is a sliver beside $129 of platform charges and about $200 of review. Allowing for cache writes raises the model estimate to approximately $0.50.
Without caching, the model bill would be $0.855 per month: 3,000 × (2,100 × $0.10 + 150 × $0.50) / 1,000,000. Cache optimization saves cents here; reducing unnecessary reviews saves paid time.
For a separate one-time build budget, assume 40 hours at $185 per hour, or $7,400. Those hours must include integration testing and review-queue behavior, not just writing the classification prompt.
Receipt 2: invoice extraction at 1,500 invoices per month
Assume 1,500 born-digital supplier invoices monthly, with two pages per invoice. The text route uses an 800-token instruction, 450 extracted tokens per page and a 500-token JSON response; scanned documents need an OCR route priced separately.
GPT-6-Luna standard pricing gives (1,700 × $0.10 + 500 × $0.50) / 1,000,000 = $0.00042 per invoice. Batch halves that to $0.00021, assuming the workflow can wait for asynchronous processing.
| Monthly line | Every input | Monthly cost, USD |
|---|---|---|
| Model input, batch | 1,500 × 1,700 tokens × $0.05/1M tokens | $0.1275 |
| Model output, batch | 1,500 × 500 tokens × $0.25/1M tokens | $0.1875 |
| Text extraction | Assumed local pdftotext -layout on existing capacity | $0 incremental |
| Zapier tier covering 4,500 tasks | 1,500 invoices × 3 actions; 10,000-task annual-billing tier | $129.00 |
| Approval glance, assumed | 1,500 × 20 seconds / 3,600 × $34.34/hour | $286.17 |
| Exception investigation, assumed | 1,500 × 10% × 4 minutes / 60 × $34.34/hour | $343.40 |
| Maintenance allowance, assumed | 2 hours/month × $100/hour | $200.00 |
| Monthly operating total | Rounded from unrounded calculations | $958.88 |
The platform assumption is one vendor batch API action, one approval-queue action and one accounting write per invoice. Submission and result collection must use that action budget; polling or extra retrieval actions increase it.
Every invoice receives the approval glance, and exceptions receive extra investigation. The $34.34 loaded hourly rate uses the BLS financial-clerk median wage of $24.04 divided by 0.70; time 30 actual reviews before accepting either duration assumption.
Native PDF input changes the model receipt
Claude processes PDF text and page images. Assume 2,000 text tokens per page, within its documented typical range of 1,500 to 3,000, plus US-letter pages rendered at an assumed 150 dpi.
That rendering produces 1,275 by 1,650 pixels. Using Claude's 28-pixel image patches gives ceil(1,275 / 28) × ceil(1,650 / 28) = 2,714 image tokens per page, making invoice input 800 + 2 × (2,000 + 2,714) = 10,228 tokens.
| Route | Model input/output per invoice | Model cost, USD/1,000 invoices |
|---|---|---|
| Haiku 5.5, native PDF | 10,228 / 500 tokens, standard | $1.2728 |
| Sonnet 5.5, native PDF | 10,228 / 500 tokens, standard | $25.456 |
| Haiku 5.5 or GPT-6-Luna, extracted text | 1,700 / 500 tokens, standard | $0.42 |
| Haiku 5.5 or GPT-6-Luna, extracted text | 1,700 / 500 tokens, batch | $0.21 |
Those routes have different access to page layout, so price alone cannot choose the winner. Test extraction accuracy on representative invoices, particularly tables that text extraction scrambles.
Use deterministic checks before asking a person to investigate: line totals must reconcile with the subtotal, tax must reconcile with the total, and invoice numbers must pass duplicate checks. A bank-account change against the supplier master always needs human approval; successful extraction does not authorize payment.
Assume 60 build hours at $185 per hour, or $11,100 upfront. This example's recurring cost is about $0.64 per invoice including approval and maintenance, while its model fee is $0.00021 per invoice.
Receipt 3: a support chatbot at 2,000 conversations per month
Assume six turns per conversation, a 1,200-token system prompt and five retrieved chunks of 300 tokens per turn. Each user message contains 60 tokens, each answer contains 220 tokens, and retrieved chunks remain in conversation history.
Turn one sends 2,760 input tokens. Each later turn adds the previous 220-token answer and another 1,560 tokens of retrieval and user text.
| Turn | Input tokens sent |
|---|---|
| 1 | 2,760 |
| 2 | 4,540 |
| 3 | 6,320 |
| 4 | 8,100 |
| 5 | 9,880 |
| 6 | 11,660 |
| Conversation total | 43,260 |
The conversation sends 15.7 times the input tokens of turn one, plus 1,320 output tokens. Pricing one prompt and calling it a conversation understates this particular design substantially.
The receipt uses uncached GPT-6-Luna pricing, avoiding an assumed cache-hit rate. Three Zapier actions per turn cover the direct vendor API call, transcript write and routing action; application serving and retrieval have a separate hosting allowance.
| Monthly line | Every input | Monthly cost, USD |
|---|---|---|
| Model input, uncached | 2,000 × 43,260 tokens × $0.10/1M tokens | $8.652 |
| Model output | 2,000 × 1,320 tokens × $0.50/1M tokens | $1.320 |
| Zapier tier covering 36,000 tasks | 2,000 conversations × 6 turns × 3 actions; 100,000-task annual-billing tier | $489.00 |
| Application hosting allowance, assumed | $20/month budget, not a vendor quote | $20.00 |
| Pinecone Builder | $20/month flat subscription | $20.00 |
| Langfuse Core | $29/month subscription | $29.00 |
| Escalations, assumed | 2,000 × 15% × 6 minutes / 60 × $30.76/hour | $922.80 |
| Knowledge-base upkeep, assumed | 8 hours/month × $30.76/hour | $246.08 |
| Technical maintenance, assumed | 2 hours/month × $100/hour | $200.00 |
| Monthly operating total | Rounded after addition | $1,936.85 |
Langfuse estimates need traces, observations and scores counted separately. An assumed four units per turn produces 48,000 units monthly, close to Hobby's 50,000-unit allowance; Core provides 100,000 units.
Initial embeddings are almost invisible at this size. Assuming 300 pages, 600 words per page and 1.4 tokens per word gives 252,000 tokens; text-embedding-3-small at $0.02 per million tokens costs $0.00504 once.
An idealized cache-read calculation would reduce the model subtotal from $9.97 to $3.87 monthly, before write charges. It assumes 9,360 uncached and 33,900 cached input tokens per conversation; actual cache writes must be added before treating that as a budget.
For the build, assume 100 hours at $185 per hour, or $18,500 upfront. Ground answers about prices and policy in retrieved source text, with escalation when the source is missing; cheap generation does not make an unsupported answer cheap.
Where the cost curve bends with volume
Review labor grows with volume under a fixed review policy. Platform subscriptions move in steps, while longer conversations can increase model input faster than conversation count.
This sensitivity table holds the email workflow's assumptions constant. It uses three tasks per email, annual-billing Zapier rates, the $0.000150 ideal cache-hit model baseline and $0.0666467 review labor per email; cache writes and maintenance are excluded.
| Emails/month | Tasks/month | Zapier tier covering volume | Platform USD/month | Model baseline USD/month | Review USD/month | Subtotal USD/month |
|---|---|---|---|---|---|---|
| 200 | 600 | 750 tasks | $19.99 | $0.03 | $13.33 | $33.35 |
| 3,000 | 9,000 | 10,000 tasks | $129.00 | $0.45 | $199.94 | $329.39 |
| 30,000 | 90,000 | 100,000 tasks | $489.00 | $4.50 | $1,999.40 | $2,492.90 |
| 300,000 | 900,000 | 2 million tasks | $3,389.00 | $45.00 | $19,994.00 | $23,428.00 |
These are covering tiers from the quoted price points, not a claim that each is the cheapest available purchase. The platform's effective cost falls as you fill a tier, then jumps when capacity runs out.
Review policy has a larger effect. At 3,000 emails, reducing low-confidence review from 12% to an assumed 8%, while preserving the audit sample, saves 1.5 hours or $46.14 monthly; whether that reduction is acceptable requires labeled test results.
Model pricing has thresholds too. Haiku 5.5 charges five times its lower input and output rates when a request's prompt exceeds 100,000 tokens, including cached tokens in the threshold count; Gemini Pro models also have higher pricing above 200,000 tokens.
Set history limits and measure their effect on answer quality before crossing those thresholds. Then compare the complete operating receipt with the value calculation for AI automation ROI, using actual time released and errors avoided.
Maintenance costs arrive as events on a calendar
A maintenance allowance buys response capacity; it does not explain the work. Budget named changes as events per year × hours per event × hourly rate / 12, then add routine monitoring.
| Event or condition | Observable consequence | Assumed work allowance |
|---|---|---|
| Sonnet 4.5 retirement on November 30, 2026 | Requests to the retired model fail | 4 to 8 hours for replacement evaluation and prompt adjustments |
Adoption of Anthropic API version 2026-10-21 | Requests containing temperature, top_p or top_k return HTTP 400 | 1 to 2 hours for removal and regression checks |
| DeepSeek search billing starts November 1, 2026, Beijing time | Previously free agent-tool search/fetch usage becomes billable | 1 to 2 hours to inventory calls and update budgets |
| Gemini 4 Argon prices double December 1, 2026 | Input rises from $2 to $4/1M tokens; output from $10 to $20/1M | 2 to 4 hours to reprice and evaluate alternatives |
| Gemini 3.8 Flash prices double January 1, 2027 | Input rises from $0.75 to $1.50/1M tokens; output from $3.75 to $7.50/1M | 2 to 4 hours to reprice and evaluate alternatives |
Anthropic promises at least 60 days' notice for publicly released model retirements in its model deprecation documentation. The parameter change is tied to adopting an API version, not a universal calendar cutoff: earlier API versions reject non-default values on Claude 4.7 and later models.
Retirement and pricing dates create specific maintenance appointments. The API parameter change applies when you adopt the named version, so schedule its testing with that upgrade.
A stable identifier can hide a changing model. DeepSeek says legacy deepseek-v4-flash names remain accepted while requests are served by DeepSeek-V4.1-Flash-1017; output monitoring must detect behavior changes that produce no HTTP error.
Keep a labeled evaluation set and rerun it during migrations. The operating checks in running and maintaining AI automations give those events an owner; review time, escalations and maintenance can also be handed to Iron Goo's operations team.
Agency prices are asking prices with weak market evidence
An AI consultant hourly rate is useful only alongside estimated hours and acceptance criteria. The BetonAI rate card reports a survey of 68 consultants but publishes no methodology, so treat its figures as self-reported.
| Published offer category | Reported price basis |
|---|---|
| Generalist consultant | $75 to $140/hour |
| Implementation specialist | $140 to $225/hour; reported median $185/hour |
| Strategy and build consultant | $225 to $375/hour; reported strategy median $275/hour |
| Codewave small-business pilot | $1,500 to $8,000 per implementation |
| Codewave mid-market multi-system build | $10,000 to $50,000 per implementation |
The agency bands come from Codewave's implementation pricing page. They are the vendor's own ranges, not an independently measured market distribution.
The three upfront budgets here use $185 per hour as an explicit assumption, not an endorsement of a universal rate. Compare the deliverables and ownership obligations using the build-versus-buy decision, especially who maintains integrations after acceptance.
Before accepting a quote, require observable answers:
- A task count computed from monthly items and billable actions.
- Token counts from representative documents, including output.
- Review minutes measured on 30 items.
- A labeled evaluation set and a stated acceptance threshold.
- An owner for model retirement notices and failed runs.
- A maintenance rate with included hours and excess-hour pricing.
- Separate approval rules for bank details, payments and unsupported policy answers.
Ask the supplier to reproduce your monthly receipt with your volumes. A price that cannot survive multiplication is not ready for a purchase order.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.