RAG pipeline architecture with defaults you can test

On this page
- Part 1: Ingestion and parsing, with a source inventory first
- Part 2: Chunking, with structure before overlap
- Part 3: Embeddings, with dimensions checked before purchase
- Part 4: The vector store, with approximate recall measured
- Part 5: Retrieval, with hybrid ranking and calibrated cutoffs
- Part 6: The prompt and citations, with claim-level support
- Part 7: Refusal, with gates before and after generation
- Part 8: Evaluation, with retrieval measured before prose
- Part 9: Permissions, with access enforced during retrieval
AI & Automation
A RAG pipeline is the machinery that lets a model answer from your own documents, grounding its answers in retrieved evidence. Its nine parts turn source files into searchable passages, retrieve relevant passages, and produce a cited answer or a refusal. The most useful first check is whether the document containing the answer actually entered the index.
My diagnostic rule is to inspect the first five parts before changing the answering model. Missing documents, flattened tables, and discarded matches can all produce confident nonsense. Almost every wrong answer deserves that inspection first; this is a troubleshooting priority, not a measured failure distribution.
| Part | Starting default | Usual failure | Observable test |
|---|---|---|---|
| 1. Ingestion | Inventory sources for 20 questions | Answer document never indexed | Find every source ID in the index |
| 2. Chunking | 200 to 500 tokens for FAQ text, zero overlap | Labels separated from answers | Retrieve complete answer passages |
| 3. Embeddings | Compare a low-cost model first | Queries and documents embedded in different spaces or with different dimension counts | Verify the model family (or documented compatible series) and dimension count match |
| 4. Vector store | HNSW ef_search = 40 | Approximate search loses neighbors | Compare indexed and exact top-k |
| 5. Retrieval | Fetch 20 to 50, rerank to 5 to 10 | Vocabulary mismatch or bad cutoff | Measure recall and sweep thresholds |
| 6. Prompt and citations | Numbered source labels | Valid-looking unsupported citation | Check ID membership and supporting text |
| 7. Refusal | Two gates | Similar passage mistaken for an answer | Ask deliberately unanswerable questions |
| 8. Evaluation | 30 to 100 labeled questions | Fluent answers conceal retrieval misses | Record recall@k, MRR, faithfulness |
| 9. Permissions | Access filter in every retrieval query | Unauthorized chunks enter context | Zero restricted chunks in retrieval logs |
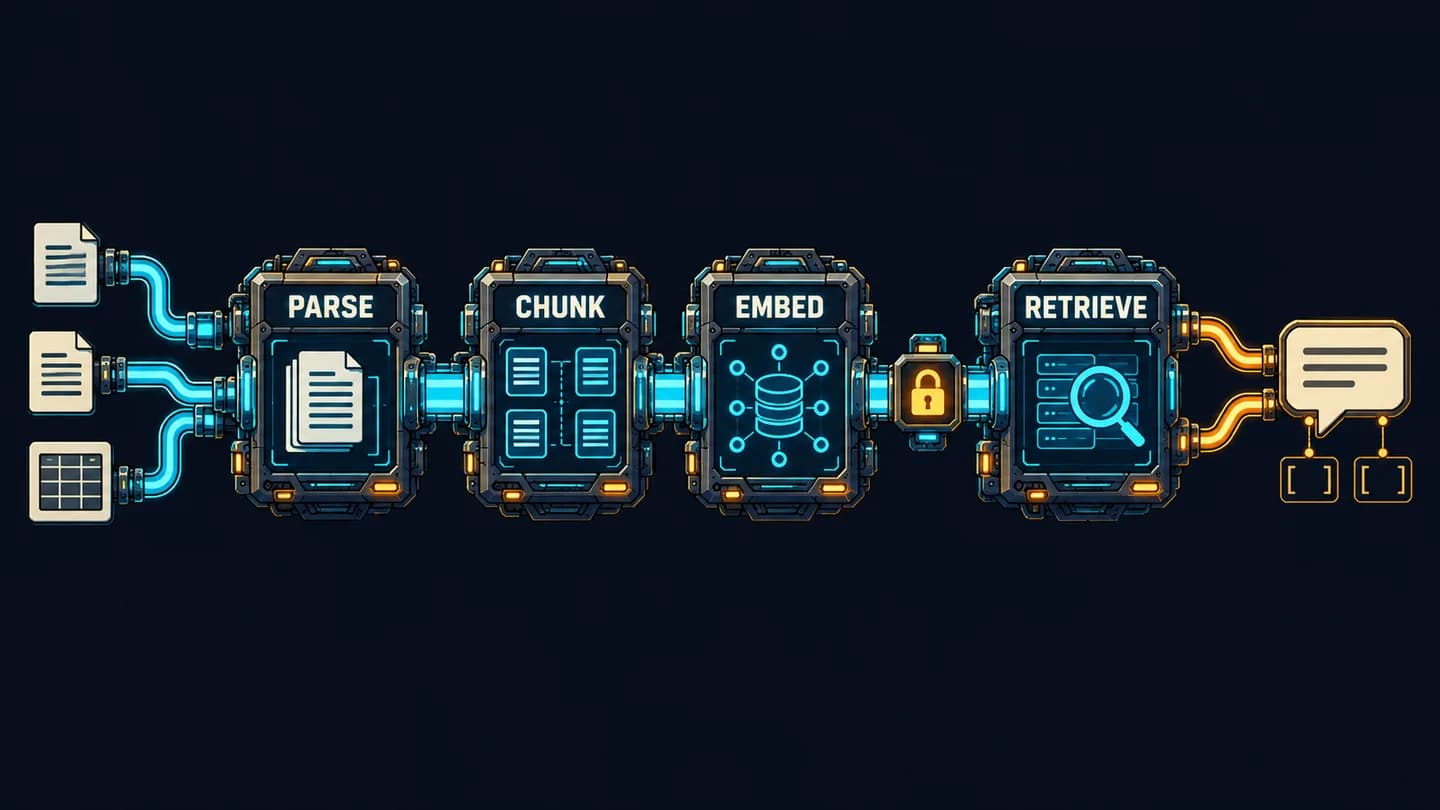
Follow the documents into the index, then the question into retrieval and generation. Permissions gate retrieval before any source text reaches the answering model.
Part 1: Ingestion and parsing, with a source inventory first
Ingestion loads documents and preserves their source identity. Start with the documents a person would consult to answer your 20 most common questions, then verify each source ID exists in the index. An unsupported file type, a JavaScript-rendered page, or an unconfigured folder can leave the answer entirely absent.
Docling is an open-source parser supporting layout analysis, reading order, table recognition, and OCR. Its codebase is MIT-licensed; its models have their own licenses. Scanned PDFs need OCR when they lack a text layer, so flag extracted text under roughly 100 characters per page for inspection.
Tables need a separate test. Select 10 tables and ask one single-cell question per table; the retrieved chunk must contain the correct value beside its row and column labels. A stream of prices without product labels is an expensive random-number generator.
Preserve document version, page or section, and source URL through parsing. If the source material contradicts itself or has expired, fix the documents before preparing them for AI; retrieval cannot decide which unsigned policy revision management intended.
Default: Inventory the sources needed for 20 real questions.
Common failure: The expected source ID is absent, or OCR produced almost no text.
Test: Check source IDs, inspect short extractions, and verify 10 table-cell answers.
Part 2: Chunking, with structure before overlap
Chunking determines what evidence travels together. Keep headings with their paragraphs and table values with their labels; begin with roughly 200 to 500 tokens for FAQ-like material, or pages and 512 to 1,024 tokens for long reports. These are starting points to measure, not universal optima.
Chroma's chunking evaluation used text-embedding-3-large and five retrieved chunks. Its RecursiveCharacterTextSplitter results measured token-level retrieval, averaged across corpora:
| Size / overlap, tokens | Recall, % | Precision, % | IoU, % |
|---|---|---|---|
| 800 / 400 | 85.4 | 1.5 | 1.5 |
| 400 / 200 | 88.1 | 3.3 | 3.3 |
| 400 / 0 | 89.5 | 3.6 | 3.6 |
| 200 / 0 | 88.1 | 7.0 | 6.9 |
Overlap did not improve these runs: 400/0 beat 400/200 on recall and precision. OpenAI file search still defaults to 800 tokens with 400 overlap; allowed sizes are 100 to 4,096 tokens, with overlap capped at half the chunk size. A vendor default is a configuration choice, not evidence that duplication helps your documents.
NVIDIA's five-dataset study measured answer accuracy. Page-level chunking led on average at 0.648, with standard deviation 0.107; token-based approaches averaged 0.603 to 0.645. Dataset winners differed: FinanceBench favored 1,024 tokens at 0.579, while Earnings favored 512 at 0.681.
Those results plausibly differ because token retrieval precision and completed-answer accuracy reward different things. Qu, Tu, and Bao's Is Semantic Chunking Worth the Computational Cost? also found no consistent performance gains justifying semantic chunking's computational expense. Start with document structure and zero overlap, then measure.
Iron AI, the assistant on this site, packs whole Markdown paragraphs into chunks of about 500 estimated tokens without overlap. Content hashes determine which chunks need re-embedding when sources change.
Context can also be added before indexing. Anthropic's contextual retrieval experiment prepended 50 to 100 tokens explaining each chunk's document context. Failure rates, defined as one minus recall@20, moved from 5.7% to 3.7% with contextual embeddings, then 2.9% with contextual BM25, and 1.9% with reranking: 67% fewer failures overall.
Anthropic estimated a one-time contextualization cost of $1.02 per million document tokens with prompt caching, assuming 800-token chunks, 8,000-token documents, 50 tokens of context instructions, and 100 tokens of context per chunk. It also suggests putting the entire knowledge base into the prompt when it is under 200,000 tokens, approximately 500 pages. Check that simpler architecture before building retrieval machinery.
Default: Structure-aware chunks, 200 to 500 tokens for FAQ text, zero overlap.
Common failure: A chunk contains the value but loses the heading that explains it.
Test: Compare chunk settings on the same labeled questions and answer-completeness checks.
Part 3: Embeddings, with dimensions checked before purchase
Embeddings convert text into vectors used to compare meaning. Queries and documents must share one embedding space and the same dimension count. Normally that means using one model and re-embedding the corpus when you switch models, though vendors can document cross-model compatibility: Voyage's embeddings documentation states, “All embeddings created with the 4 series are compatible with each other.” Maximum input length is an API limit, not a recommended chunk size.
Prices were read on 24 October 2026; check the vendor page before relying on them. Sources are OpenAI pricing, Google pricing, and Voyage pricing.
| Model | Price per million tokens | Default dimensions | Other dimensions | Maximum input tokens |
|---|---|---|---|---|
| text-embedding-3-small | $0.02 | 1,536 | Shortened with dimensions | 8,192 |
| text-embedding-3-large | $0.13 | 3,072 | Including 1,024 and 256 | 8,192 |
| gemini-embedding-2 | $0.20 standard; $0.10 batch, text | 3,072 | 128 to 3,072 | 8,192 |
| voyage-4-large | $0.12 | 1,024 | 256, 512, 1,024, 2,048 | 32,000 |
| voyage-4 | $0.06 | 1,024 | 256, 512, 1,024, 2,048 | 32,000 |
| voyage-4-lite | $0.02 | 1,024 | 256, 512, 1,024, 2,048 | 32,000 |
For a hypothetical corpus, the inputs are 2,000 documents × 10 pages × 500 tokens = 10 million tokens. One embedding pass costs $0.20 with 3-small, $0.60 with voyage-4, $1.30 with 3-large, or $2.00 with Gemini standard pricing ($1.00 batch). The voyage-4 amount falls within its listed 200-million-token free allowance.
These calculations exclude overlap, contextual prefixes, and subsequent edits. Parsing and evaluation work can easily outweigh this initial API bill, so choose using retrieval results. Iron AI, the assistant on this site, uses text-embedding-3-small at 1,536 dimensions with Postgres and pgvector.
Default: Benchmark a low-cost model using identical questions and chunks.
Common failure: A migration mixes incompatible embedding spaces or dimension counts; equal vector lengths alone do not prove compatibility.
Test: Record the model, compatible model family or embedding space, dimension count, and content hash for every embedding batch. Verify that query and document batches share the embedding space and dimension count.
Part 4: The vector store, with approximate recall measured
The store holds vectors alongside text and metadata. pgvector's documented defaults are HNSW m = 16, ef_construction = 64, and hnsw.ef_search = 40. IVFFlat defaults to ivfflat.probes = 1; its starting guidance is rows / 1000 lists up to one million rows, then sqrt(rows), with probes starting around sqrt(lists).
Indexed vector values support up to 2,000 dimensions; indexed halfvec supports 4,000. A default 3,072-dimensional embedding therefore needs shortening or a compatible representation such as halfvec. Raw vector storage is 4 * dimensions + 8 bytes: 1,536 dimensions consume 6,152 bytes, or about 154 MB for 25,000 chunks, excluding indexes and other columns.
The following synthetic experiment uses 20,000 random 64-dimensional vectors around 200 centers and 50 queries. It needs only Postgres with pgvector and uses temporary tables; exact top-10 neighbors are established before indexing.
-- Synthetic test of IVFFlat recall versus ivfflat.probes.
-- 20,000 vectors (64 dimensions) scattered around 200 topic centres, 50 queries.
-- Needs Postgres with pgvector; uses temporary tables only.
SELECT setseed(0.42);
CREATE TEMP TABLE centres AS
  SELECT c AS id, array(SELECT random() - 0.5 FROM generate_series(1, 64) WHERE c > 0) AS v
  FROM generate_series(1, 200) c;
CREATE TEMP TABLE items AS
  SELECT i AS id,
         array(SELECT x + 0.6 * (random() - 0.5) FROM unnest(c.v) x)::real[]::vector(64) AS v
  FROM generate_series(1, 20000) i
  JOIN centres c ON c.id = 1 + (i % 200);
CREATE TEMP TABLE queries AS
  SELECT q AS id,
         array(SELECT x + 0.6 * (random() - 0.5) FROM unnest(c.v) x)::real[]::vector(64) AS v
  FROM generate_series(1, 50) q
  JOIN centres c ON c.id = 1 + ((q * 7) % 200);

-- Ground truth: exact top 10 by cosine distance, computed before any index exists.
CREATE TEMP TABLE truth AS
  SELECT q.id AS qid, t.id
  FROM queries q
  CROSS JOIN LATERAL (SELECT id FROM items ORDER BY v <=> q.v LIMIT 10) t;

CREATE INDEX ON items USING ivfflat (v vector_cosine_ops) WITH (lists = 20);  -- rows / 1000
ANALYZE items;
SET enable_seqscan = off;

CREATE TEMP TABLE result (probes int, recall numeric);
DO $$
DECLARE p int;
BEGIN
  FOREACH p IN ARRAY ARRAY[1, 2, 4, 8, 20] LOOP
    PERFORM set_config('ivfflat.probes', p::text, true);
    INSERT INTO result
    SELECT p, round(100.0 * count(*) / 500, 1)
    FROM queries q
    CROSS JOIN LATERAL (SELECT id FROM items ORDER BY v <=> q.v LIMIT 10) a
    JOIN truth t ON t.qid = q.id AND t.id = a.id;
  END LOOP;
END $$;
SELECT probes, recall AS recall_at_10_pct FROM result ORDER BY probes;
 probes | recall_at_10_pct
--------+------------------
      1 |             93.6
      2 |             96.4
      4 |             99.6
      8 |            100.0
     20 |            100.0
(5 rows)
This pinned run recovered 93.6% of exact neighbors at one probe and 99.6% at four. Rebuilding the index changes the numbers because IVFFlat's k-means build samples randomly: four builds ranged from 88.4% to 93.6% at one probe and 96.2% to 99.6% at four. Other builds can fall outside that range: a separate check got 86.8% to 93.4% at one probe. Twenty probes searches all 20 lists and matched exact search every time.
Managed alternatives change the operating responsibility. Pinecone lists a free Starter tier with 2 GB storage and a $50 monthly minimum for Standard; Qdrant Cloud's free node has 0.5 vCPU, 1 GB RAM, and 4 GB disk. OpenAI file search lists $2.50 per 1,000 Responses API tool calls and $0.10 per GB per day after the first free GB.
My starting decision rule: if you already operate Postgres and expect fewer than a few million chunks, evaluate pgvector first. A managed service earns its fee when database operation exceeds your team's skills or scale requirements justify it.
Default: Inspect SHOW hnsw.ef_search; or SHOW ivfflat.probes;.
Common failure: Approximate neighbors are treated as exact neighbors.
Test: Compare indexed top-k against exact search with index scans disabled.
Part 5: Retrieval, with hybrid ranking and calibrated cutoffs
Retrieval selects the evidence the answering model receives. Vector search helps with synonyms; lexical search preserves exact identifiers such as part numbers. Elasticsearch's BM25 defaults are k1 = 1.2 and b = 0.75, controlling term-frequency saturation and document-length normalization.
Reciprocal rank fusion combines ranked lists without pretending their raw scores share a scale. With ranks starting at one and the paper's constant of 60, a document receives one contribution from each list containing it.
score = sum of 1 / (60 + rank)
The plumbing-supply distributor used for these experiments is hypothetical. The hybrid SQL ran on its eight chunks, embedded with text-embedding-3-small; its keyword ranking uses Postgres ts_rank_cd, which is not BM25. Run it in psql after loading the chunks, with \set qvec containing the question embedding and \set qtext containing its text.
-- Hybrid retrieval: vector lane + full-text lane, merged with reciprocal rank fusion (k = 60).
-- Table: chunks(id text, content text, embedding vector). In psql: \set qvec '[...]' and \set qtext '...'
WITH vec AS (
  SELECT id, row_number() OVER (ORDER BY embedding <=> :'qvec'::vector) AS r
  FROM chunks
  ORDER BY embedding <=> :'qvec'::vector
  LIMIT 20
),
kw AS (
  SELECT id, row_number() OVER (ORDER BY ts_rank_cd(to_tsvector('english', content), q) DESC) AS r
  FROM chunks, websearch_to_tsquery('english', :'qtext') q
  WHERE to_tsvector('english', content) @@ q
  ORDER BY ts_rank_cd(to_tsvector('english', content), q) DESC
  LIMIT 20
)
SELECT id, vec.r AS vector_rank, kw.r AS keyword_rank,
       round(COALESCE(1.0 / (60 + vec.r), 0) + COALESCE(1.0 / (60 + kw.r), 0), 4) AS rrf
FROM vec FULL OUTER JOIN kw USING (id)
ORDER BY rrf DESC
LIMIT 3;
qtext: how do I get a refund
    id     | vector_rank | keyword_rank |  rrf
-----------+-------------+--------------+--------
 returns-1 |           1 |              | 0.0164
 returns-2 |           2 |              | 0.0161
 account-1 |           3 |              | 0.0159
(3 rows)

qtext: freight over 150 lb
     id     | vector_rank | keyword_rank |  rrf
------------+-------------+--------------+--------
 shipping-2 |           1 |            1 | 0.0328
 pricing-2  |           2 |              | 0.0161
 shipping-1 |           3 |              | 0.0159
(3 rows)
For the refund question, the keyword lane is empty: websearch_to_tsquery requires both “get” and “refund,” and no chunk contains “refund.” Vector search puts the “full credit” answer first. For freight, both lanes rank shipping-2 first, producing 1/61 + 1/61 = 0.0328.
A sensible reranking experiment retrieves 20 to 50 candidates, then retains 5 to 10. Voyage lists rerank-3 at $0.05 per million tokens and rerank-3-lite at $0.02. Put the strongest evidence first: Lost in the Middle found that relevant information often works best near the beginning or end of context, with performance dropping in the middle.
Similarity cutoffs require separate calibration for each model and corpus. This package-free Python sweep uses a hypothetical 12-question labeled set with invented scores.
# Hypothetical labelled set: top-1 cosine similarity for 12 test questions,
# and whether that top-1 chunk really answers the question.
# "off" = the documents do not contain the answer (the bot should refuse).
LABELLED = [
    (0.74, "right"), (0.71, "right"), (0.66, "right"), (0.61, "right"),
    (0.58, "right"), (0.55, "right"), (0.52, "right"), (0.47, "wrong"),
    (0.44, "right"), (0.38, "off"),   (0.31, "off"),   (0.22, "off"),
]

print("cut-off  right kept  right dropped  wrong or off let through")
for cut in (0.30, 0.35, 0.40, 0.45, 0.50, 0.60, 0.70):
    kept = [label for score, label in LABELLED if score >= cut]
    right_kept = kept.count("right")
    right_dropped = sum(1 for s, l in LABELLED if l == "right") - right_kept
    let_through = len(kept) - right_kept
    print(f"{cut:7.2f}  {right_kept:10d}  {right_dropped:13d}  {let_through:24d}")
cut-off  right kept  right dropped  wrong or off let through
   0.30           8              0                         3
   0.35           8              0                         2
   0.40           8              0                         1
   0.45           7              1                         1
   0.50           7              1                         0
   0.60           4              4                         0
   0.70           2              6                         0
At 0.70, six of eight answerable questions are discarded. At 0.40, all eight correct matches survive alongside one wrong match; at 0.50, the wrong match disappears along with one correct answer. These invented scores demonstrate the tradeoff, not a recommended production threshold.
The hypothetical wrong match scores 0.47, while a correct match scores 0.44. No top-1 cutoff can keep that correct match while rejecting the wrong one; generation needs its own evidence check.
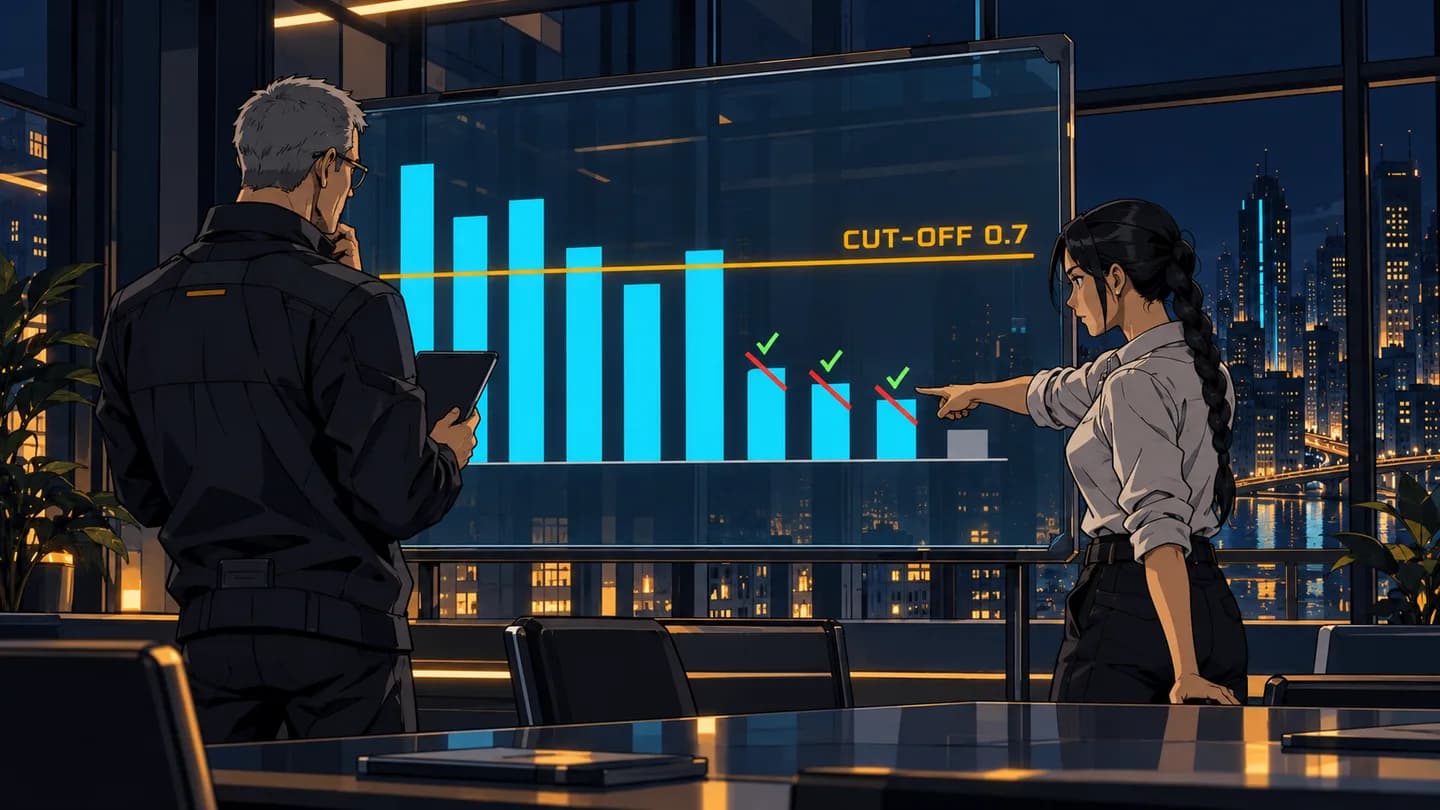
The correct matches below the line are still correct. Raising the cutoff removes unsupported matches at the cost of answerable questions.
Default: Retrieve 20 to 50 candidates; test reranking down to 5 to 10.
Common failure: A tutorial's 0.7 cutoff becomes an untested production rule.
Test: Sweep cutoffs on 30 to 100 labeled questions and inspect both error types.
Part 6: The prompt and citations, with claim-level support
The prompt packages retrieved evidence for generation. Give every chunk a numbered label, source URL, and page or section; require a citation immediately after each factual claim. Iron AI uses numbered source labels with source URLs.
Validate citations in two passes. First reject or flag any source ID absent from the supplied context; then inspect whether the cited passage supports the claim, including qualifications and exceptions. A valid identifier proves membership in the context, not factual support.
For example, a passage allowing returns of unopened items cannot support “all installed parts are refundable.” Keep the cited passage with the answer in your evaluation record so a reviewer can check that distinction without repeating retrieval.
Default: One numbered source label per chunk, with citations after factual claims.
Common failure: A real source ID decorates a claim its passage never supports.
Test: Reject unknown IDs and audit claim-to-passage support.
Part 7: Refusal, with gates before and after generation
Refusal must be engineered. The Sufficient Context paper found that larger models answered well with sufficient context but often produced incorrect answers when context was insufficient; selective generation improved correctness among answered queries by 2 to 10%.
Use two gates. Before the model call, refuse when retrieval returns no eligible evidence or fails your calibrated threshold. During generation, instruct the model to answer only from numbered sources and return the exact string I don't know from the available documents. when those sources cannot support an answer.
Check for that exact response and route it consistently. The cutoff sweep explains why the second gate matters: a wrong passage can score higher than a correct one. Similarity measures resemblance, which is an awkward substitute for proof.
Make 20 to 30% of your evaluation questions deliberately unanswerable from the corpus. Measure refusal on those questions and false refusal on answerable questions separately, then define the human handoff and guardrails for cases requiring a decision.
Default: Retrieval gate plus the exact generation refusal string.
Common failure: A related passage passes retrieval without containing the requested answer.
Test: Measure unanswerable-question refusal and answerable-question false refusal.
Part 8: Evaluation, with retrieval measured before prose
Start with 30 to 100 real questions and label the answering document or chunk. Recall@k measures whether relevant evidence appears among the first k results; with one gold chunk per question, MRR averages its reciprocal rank, assigning zero when absent. Measure retrieval before judging the generated answer.
This Python script needs no packages. Replace bm25.search with any function returning ranked chunk IDs to evaluate vector or hybrid retrieval using the same questions.
import math, re
from collections import Counter

CHUNKS = {
    "returns-1": "Unopened items can be returned within 30 days of delivery for a full credit to the original payment method.",
    "returns-2": "Opened or installed parts are not returnable. Defective parts are replaced under the manufacturer warranty.",
    "shipping-1": "Orders placed before 2 pm ship the same business day. Standard ground delivery takes 3 to 5 business days.",
    "shipping-2": "Freight orders over 150 lb ship on a pallet and need a delivery appointment.",
    "pricing-1": "Trade accounts get 12 percent off list price on all valves and fittings.",
    "pricing-2": "Prices on the website exclude sales tax and freight.",
    "warranty-1": "Water heaters carry a 6 year tank warranty and a 1 year parts warranty.",
    "account-1": "To open a trade account, send a copy of your contractor license and a resale certificate.",
}

EVAL = [  # (question, id of the chunk that answers it)
    ("how many days do I have to return an unopened item", "returns-1"),
    ("can I return a part I already installed", "returns-2"),
    ("when will my order ship", "shipping-1"),
    ("do heavy orders need an appointment", "shipping-2"),
    ("what discount do contractors get", "pricing-1"),
    ("is tax included in the price", "pricing-2"),
    ("how long is the tank warranty on a water heater", "warranty-1"),
    ("how do I get a refund", "returns-1"),
]

def tokens(text):
    return re.findall(r"[a-z0-9]+", text.lower())

class BM25:
    def __init__(self, docs, k1=1.2, b=0.75):
        self.ids = list(docs)
        self.tf = {i: Counter(tokens(t)) for i, t in docs.items()}
        self.len = {i: sum(c.values()) for i, c in self.tf.items()}
        self.avg = sum(self.len.values()) / len(self.len)
        df = Counter(w for c in self.tf.values() for w in c)
        n = len(docs)
        self.idf = {w: math.log(1 + (n - d + 0.5) / (d + 0.5)) for w, d in df.items()}
        self.k1, self.b = k1, b

    def search(self, query, k):
        scores = {}
        for i in self.ids:
            s = 0.0
            for w in tokens(query):
                f = self.tf[i].get(w, 0)
                if f:
                    norm = 1 - self.b + self.b * self.len[i] / self.avg
                    s += self.idf[w] * f * (self.k1 + 1) / (f + self.k1 * norm)
            if s > 0:
                scores[i] = s
        return sorted(scores, key=scores.get, reverse=True)[:k]

def evaluate(search, k):
    hits, rr, misses = 0, 0.0, []
    for question, gold in EVAL:
        ranked = search(question, k)
        if gold in ranked:
            hits += 1
            rr += 1 / (ranked.index(gold) + 1)
        else:
            misses.append((question, ranked))
    return hits / len(EVAL), rr / len(EVAL), misses

bm25 = BM25(CHUNKS)
for k in (1, 3):
    recall, mrr, misses = evaluate(bm25.search, k)
    print(f"recall@{k} = {recall:.3f}   MRR@{k} = {mrr:.3f}")
    for question, ranked in misses:
        print(f"  miss: {question!r} -> {ranked}")
recall@1 = 0.625   MRR@1 = 0.625
  miss: 'can I return a part I already installed' -> ['returns-1']
  miss: 'when will my order ship' -> ['shipping-2']
  miss: 'how do I get a refund' -> ['pricing-1']
recall@3 = 0.875   MRR@3 = 0.750
  miss: 'how do I get a refund' -> ['pricing-1', 'account-1', 'shipping-2']
Recall@3 of 0.875 means seven of eight questions retrieved the correct chunk within three results. The installed-part miss exposes missing stemming: “return” does not match “returned” or “returnable,” and “part” does not match “parts.” The wrong chunk wins on “can” and “a.”
The shipping miss is also morphological: “order” does not match “orders,” although everything is lowercased. Both shipping chunks match “ship,” and BM25 length normalization favors the shorter freight passage. An English stemming analyzer addresses these word-form mismatches.
The refund miss requires a different remedy: the scorer never matches “refund” because the answer says “full credit,” and pricing-1 ranks first on “get.” The answer chunk, returns-1, scores about 0.62 solely through the stopword “a,” placing fifth among chunks with a positive score and outside recall@3. Running evaluate(bm25.search, 5) gives recall@5 = 1.0 and MRR@5 = 0.775. A larger k retrieves it by accident through a stopword, without matching the refund concept; the vector lane ranks it first in the hybrid experiment.
Once retrieval works, measure RAGAS faithfulness against the actual retrieved context. Its FaithfulnesswithHHEM variant uses Vectara's HHEM-2.1-Open classifier to assess support.
faithfulness = supported claims in the response / total claims in the response
RAGAS, DeepEval, and promptfoo offer evaluation tooling; retain human review for disputed support judgments. Make the labeled set part of automation maintenance and rerun it after every parser, chunker, embedding, index, or prompt change.
If you want a retrieval-grounded chatbot with citations built and operated for you, Iron Goo's operations service is the relevant implementation route. Keep the evaluation set as an acceptance artifact so the delivered behavior remains reviewable.
Default: Track recall@5 and MRR, then faithfulness and refusal.
Common failure: Answer fluency conceals a missing gold chunk.
Test: Save ranked IDs, supplied context, answer, and metric results for every question.
Part 9: Permissions, with access enforced during retrieval
Permissions are presented last because they constrain every earlier component. OWASP LLM08:2025 identifies unauthorized access and cross-context leakage among vector and embedding risks. Copy each document's access list onto its chunks during ingestion and synchronize later permission changes.
Apply authorization inside the retrieval query, including both hybrid lanes. Postgres row-level security can enforce database access rules; a prompt instruction cannot retract confidential text already sent to a model. Source inventory and retrieval logs must preserve enough identity to audit which document supplied each chunk.
Distinguish authorization from index execution order. pgvector applies filters after approximate index scans: a filter matching 10% of rows with default HNSW ef_search = 40 returns about four matching rows on average. Authorized evidence can therefore be missed even when the filter is correct.
For pgvector 0.8.0 and later, test iterative scans such as hnsw.iterative_scan = strict_order; hnsw.max_scan_tuples defaults to 20,000. Partial indexes or tenant partitions can also help narrow searches. Compare recall under each actual permission group, since unrestricted recall can hide these losses.
Create five to ten permission probes per group. Log in as someone denied access to a known document and ask a question only that document answers; expect refusal and zero chunks from that document in the retrieval log. Repeat after revoking access to verify that existing chunks receive the changed permissions.
Default: Enforce document access in every retrieval query and synchronize chunk ACLs.
Common failure: Restricted evidence reaches generation, or filtering starves authorized retrieval.
Test: Require zero restricted chunks in logs, including after an access revocation.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.