LLM monitoring in production: Retirements, evals and caps

On this page
- Procedure 1: Maintain a retirement calendar with migration deadlines
- Procedure 2: Compare the requested model with the answering model
- Procedure 3: Size the eval set around the decisions it must support
- Procedure 4: Diff model versions before switching production
- Procedure 5: Count failures inside successful HTTP responses
- Procedure 6: Export model and prompt identity through OpenTelemetry
- Procedure 7: Version prompts and verify rollback propagation
- Procedure 8: Test spend controls as availability controls
- Procedure 9: Refresh source data and rebuild retired embedding indexes
- Procedure 10: Make scheduled-job failures reach an owner
- Procedure 11: Contain incidents before changing prompts or models
AI & Automation
Preview models, identified by preview in the model name, may be retired with much shorter notice, such as 2 weeks.
LLM monitoring in production means checking that your automation still produces acceptable work, within budget, on supported models. The OpenAI deprecation policy makes the operational constraint explicit: a preview model can disappear with two weeks' notice. Treat every model as having an eventual retirement date, even when the vendor has not announced it.
A successful HTTP request proves very little about the completed business task. You need a retirement calendar, repeatable regression checks and an owner who can stop the automation when its output becomes unsafe.
Procedure 1: Maintain a retirement calendar with migration deadlines
Model retirement is scheduled maintenance imposed by someone else's calendar. Record the exact model ID and hosting platform, because Anthropic-operated services, Amazon Bedrock and Google-managed Claude can have different retirement schedules.
Run the documented OpenAI check:
curl -s https://api.openai.com/v1/models \
  -H "Authorization: Bearer $OPENAI_API_KEY" \
  | jq -r '.data[] | select(.shutdown_date != null) | "\(.shutdown_date)  \(.id)"' \
  | sort
Every model with a returned shutdown date has an owner, replacement candidate and migration ticket. Every model used in traces also appears in your inventory, including embeddings.
The application calls a model absent from the inventory, or a shutdown date has no assigned work. An empty command result is treated as proof that nothing will retire.
The command was tested against the documented response shape, not against the live API. An absent or null shutdown_date means no shutdown has been announced through that field; it does not promise indefinite availability. Read Anthropic's and Google's deprecation pages manually because the pages checked document no equivalent field.
OpenAI gives at least six months for generally available models and three months for specialized variants, unless safety or compliance requires faster action. Anthropic's policy gives active deployments at least 60 days' notice for publicly released models. Google's dates are earliest possible shutdown dates; preview models get at least two weeks' notice, and breaking changes behind latest get two weeks' email notice.
The following calendar was checked on 24 October 2026. Distinguish completed shutdowns from future deadlines and retirement floors:
- 23 October 2026OpenAI legacy snapshots shut down
Announced on 22 April 2026, this shutdown included gpt-3.5-turbo-0125, with gpt-5.6-terra as its substitute, and o1 and o1-pro, with gpt-5.6-sol as their substitute. The gpt-4o-2024-05-13 snapshot also shut down.
- 31 October 2026OpenAI Evals becomes read-only
Existing evals become read-only before the platform closes. Export cases and move execution to a replaceable harness; OpenAI's migration guidance points to Promptfoo.
- 17 November 2026Earliest possible Google preview TTS shutdown
Google lists this earliest possible date for gemini-3.1-flash-tts-preview, gemini-2.5-flash-preview-tts and gemini-2.5-pro-preview-tts. The named replacements are gemini-3.8-flash-tts or gemini-3.8-flash-lite-tts.
- 24 November 2026Claude Opus 4.5 retirement floor
Anthropic lists retirement for claude-opus-4-5-20251101 as not sooner than 24 November 2026. This is a floor, not a scheduled retirement; the model remains Active.
- 30 November 2026Claude Sonnet 4.5 retires
claude-sonnet-4-5-20250929 retires on Anthropic-operated platforms. The listed replacement is claude-sonnet-5-5.
- 30 November 2026OpenAI Evals and reusable prompts shut down
The Evals dashboard and API close; migrate execution to another harness. The v1/prompts API also closes; OpenAI directs developers to move prompt content into application code.
- 11 December 2026Older GPT-5 and o3 snapshots shut down
Announced on 11 June 2026, this shutdown covers older GPT-5, GPT-5 mini, GPT-5 nano, GPT-5 pro, o3 and o3-pro snapshots. Replacements are gpt-5.6-sol, gpt-5.6-terra or gpt-5.6-luna, depending on the model.
- 6 January 2027OpenAI text-to-speech models shut down
tts-1, tts-1-hd and gpt-4o-mini-tts shut down. The listed replacement is gpt-realtime-2.1-mini.
- 14 January 2027Further GPT snapshots shut down
Listed GPT-4o, GPT-4o mini, GPT-4.1 and GPT-4.1 mini snapshots shut down, with gpt-6-luna as the replacement. Fine-tuned versions follow their base model's schedule.
Our operating rule is a monthly calendar review and an internal migration deadline 30 days before shutdown. Anthropic's “Not sooner than” dates are floors, not booked retirements: the 15 October 2026 floor for Claude Haiku 4.5 had passed while the model remained Active. Put floors in a review column, separate from confirmed shutdowns.
Procedure 2: Compare the requested model with the answering model
Pinning reduces uncontrolled changes, but naming conventions differ across vendors. From Claude's 4.6 generation onward, every model ID is a pinned snapshot, including dateless IDs; earlier aliases resolve to dated IDs.
Record both identities on every completed call, using the provider response or SDK metadata for the answering model. This illustrative trace record deliberately shows a routing difference:
{
  "gen_ai.provider.name": "gcp.gemini",
  "gen_ai.request.model": "gemini-3.5-flash",
  "gen_ai.response.model": "gemini-3.6-flash",
  "expected_response_model": "gemini-3.6-flash",
  "model_identity_ok": true
}
The response model matches the approved snapshot or an explicitly approved routing mapping. A changed answering model triggers review before consequential work continues.
Only the request string is logged, or a dashboard reports a family name such as GPT-4o without identifying the snapshot. An unexpected answering model passes unnoticed.
Google explicitly says the gemini-3.5-flash endpoint automatically routes requests to gemini-3.6-flash. Its latest aliases are hot-swapped with new releases, while its model guidance recommends specific stable models for most production applications. Compare against an approved mapping so an intentional routing arrangement does not create permanent alert noise.
OpenAI snapshots within one family can have different shutdown dates. gpt-4o-2024-05-13 shut down on 23 October 2026, while gpt-4o-2024-08-06 is scheduled to remain available until 14 January 2027. A row labeled “GPT-4o” cannot tell you which deadline applies.
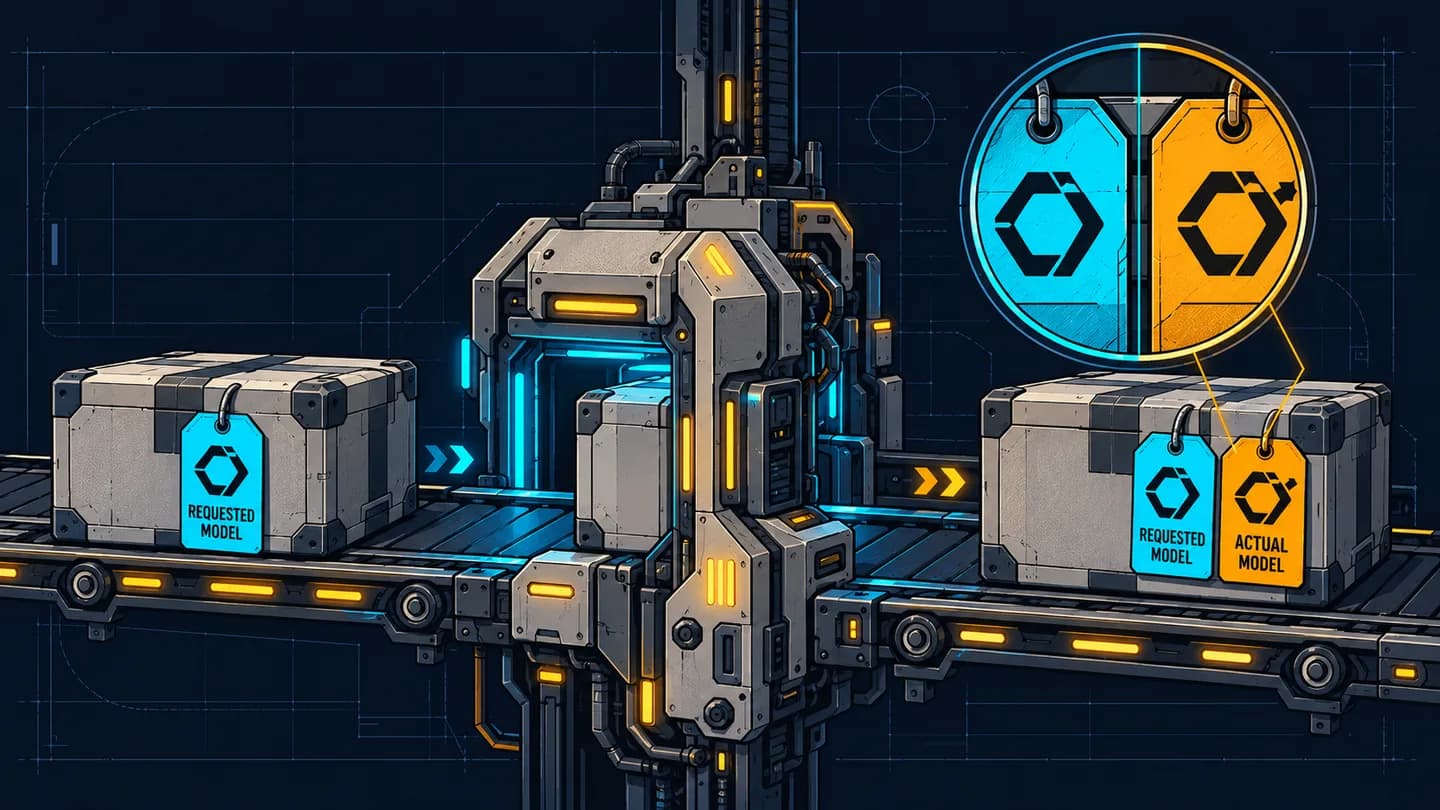
Compare the outgoing model label with the answering model label. An unchanged request string can conceal a different model behind an alias or routed endpoint.
When output changes without an application deployment, inspect model identity first, then prompt version, input mix and knowledge-base version. Generation can also vary between calls; pinning does not make every response identical.
Procedure 3: Size the eval set around the decisions it must support
A small eval set can reveal a specific defect, but it cannot establish a low failure rate with much precision. Keep real task proportions alongside deliberately difficult inputs, and tag cases where one regression must block release.
Check case coverage and calculate uncertainty before treating an average as a release gate:
| Cases | Approximate 95% CI half-width at a 90% pass rate |
|---|---|
| 50 | 8.3 percentage points |
| 100 | 5.9 percentage points |
| 200 | 4.2 percentage points |
| 400 | 2.9 percentage points |
Cases have stable IDs, expected outcomes and critical-case tags. The release decision includes uncertainty and individual regressions, with representative routine inputs and explicit edge cases.
Thirty easy examples are described as proof of reliability. A perfect score on 100 cases is reported as a zero failure rate.
These half-widths are approximate binomial calculations, not guarantees about future traffic. With zero observed failures, the exact 95% upper bound is 1 - 0.05^(1/n): 100 cases give an upper bound of about 2.95% on the failure rate; 300 cases give an upper bound of about 0.99%. “Nothing failed” still leaves a measurable amount of uncertainty.
Our opinion: start with 150 to 300 graded cases for a company automation, including 10 to 20 critical cases involving money, legal consequences or consequential customer output. Include absent source data, long documents, ambiguous instructions and irrelevant inputs. Keep the cases as JSONL in your repository so the harness can be replaced when its own retirement notice arrives.
Run the same cases through both models. The paired exact test examines changed outcomes: zero fixed versus five broken gives p=0.0625; zero versus six gives p=0.031; one versus six gives p=0.125. Statistical significance is not permission to break an invoice total.
Independent samples require much more data: detecting a decline from 95% to 90% at 80% power takes about 435 cases per arm. Preserve pairing whenever you can, and read every flipped case regardless of its p-value.
Procedure 4: Diff model versions before switching production
Two averages can hide the cases your business cannot afford to lose. Run baseline and candidate with the same case IDs and prompt content, then compare correctness alongside schema validity and operating cost.
Save this as eval_diff.py and run it against nonempty JSONL files:
#!/usr/bin/env python3
"""Compare two eval runs of the same cases (old model vs candidate).
Each file is JSONL, one case per line:
{"id": "inv-017", "pass": true, "schema_ok": true, "refusal": false,
 "cost_usd": 0.0021, "latency_ms": 1840, "critical": false}
Usage: python3 eval_diff.py baseline.jsonl candidate.jsonl
Exit code 1 means: do not switch yet."""
import json, sys
from math import comb

def load(path):
    with open(path) as f:
        return {r["id"]: r for r in map(json.loads, filter(str.strip, f))}

def p95(values):
    v = sorted(values)
    return v[min(len(v) - 1, int(0.95 * len(v)))]

def mcnemar_p(fixed, broke):
    # exact two-sided binomial test on the cases that changed outcome
    n, k = fixed + broke, min(fixed, broke)
    if n == 0:
        return 1.0
    return min(1.0, 2 * sum(comb(n, i) for i in range(k + 1)) / 2 ** n)

old, new = load(sys.argv[1]), load(sys.argv[2])
ids = sorted(old.keys() & new.keys())
missing = sorted(old.keys() ^ new.keys())
broke = [i for i in ids if old[i]["pass"] and not new[i]["pass"]]
fixed = [i for i in ids if new[i]["pass"] and not old[i]["pass"]]

def rate(run, key):
    return sum(bool(run[i][key]) for i in ids) / len(ids)

def cost(run):
    return sum(run[i]["cost_usd"] for i in ids) / len(ids)

print(f"cases compared: {len(ids)}  missing from one run: {len(missing)}")
for label, key in (("pass rate", "pass"), ("schema ok", "schema_ok"), ("refusals", "refusal")):
    print(f"{label:<10} {rate(old, key):7.1%} -> {rate(new, key):7.1%}")
print(f"cost/item  ${cost(old):.5f} -> ${cost(new):.5f}")
print(f"p95 ms     {p95([old[i]['latency_ms'] for i in ids])} -> {p95([new[i]['latency_ms'] for i in ids])}")
print(f"flips      fixed {len(fixed)}, broke {len(broke)}, exact p = {mcnemar_p(len(fixed), len(broke)):.3f}")
for i in broke:
    print(f"  BROKE {i}{'  (critical)' if new[i].get('critical') else ''}")

critical = [i for i in broke if new[i].get("critical")]
worse_schema = rate(new, "schema_ok") < rate(old, "schema_ok")
sys.exit(1 if critical or missing or worse_schema or len(broke) > len(fixed) else 0)
Exit code 0 means this gate found no blocking condition. You still inspect every regression and apply your own cost and latency limits before approving a controlled rollout.
Exit code 1 means do not switch yet: a critical case broke, cases are missing, schema validity fell, or more cases broke than were fixed. A cheaper candidate does not override those conditions.
The following output comes from hypothetical, synthetic test data. Cost per item fell, p95 latency rose, and six cases broke, including two critical cases; this run exits 1.
cases compared: 200  missing from one run: 0
pass rate    89.5% ->   86.5%
schema ok   100.0% ->   99.5%
refusals      0.0% ->    0.5%
cost/item  $0.00251 -> $0.00201
p95 ms     2360 -> 2940
flips      fixed 0, broke 6, exact p = 0.031
  BROKE case-013
  BROKE case-040  (critical)
  BROKE case-057
  BROKE case-088
  BROKE case-140  (critical)
  BROKE case-171
Validate unique IDs before running: the loader stores cases in a dictionary, so duplicate IDs would overwrite earlier rows. After a passing review, our suggested rollout is a 10% canary for a week, with the old model retained for rollback while it remains available.
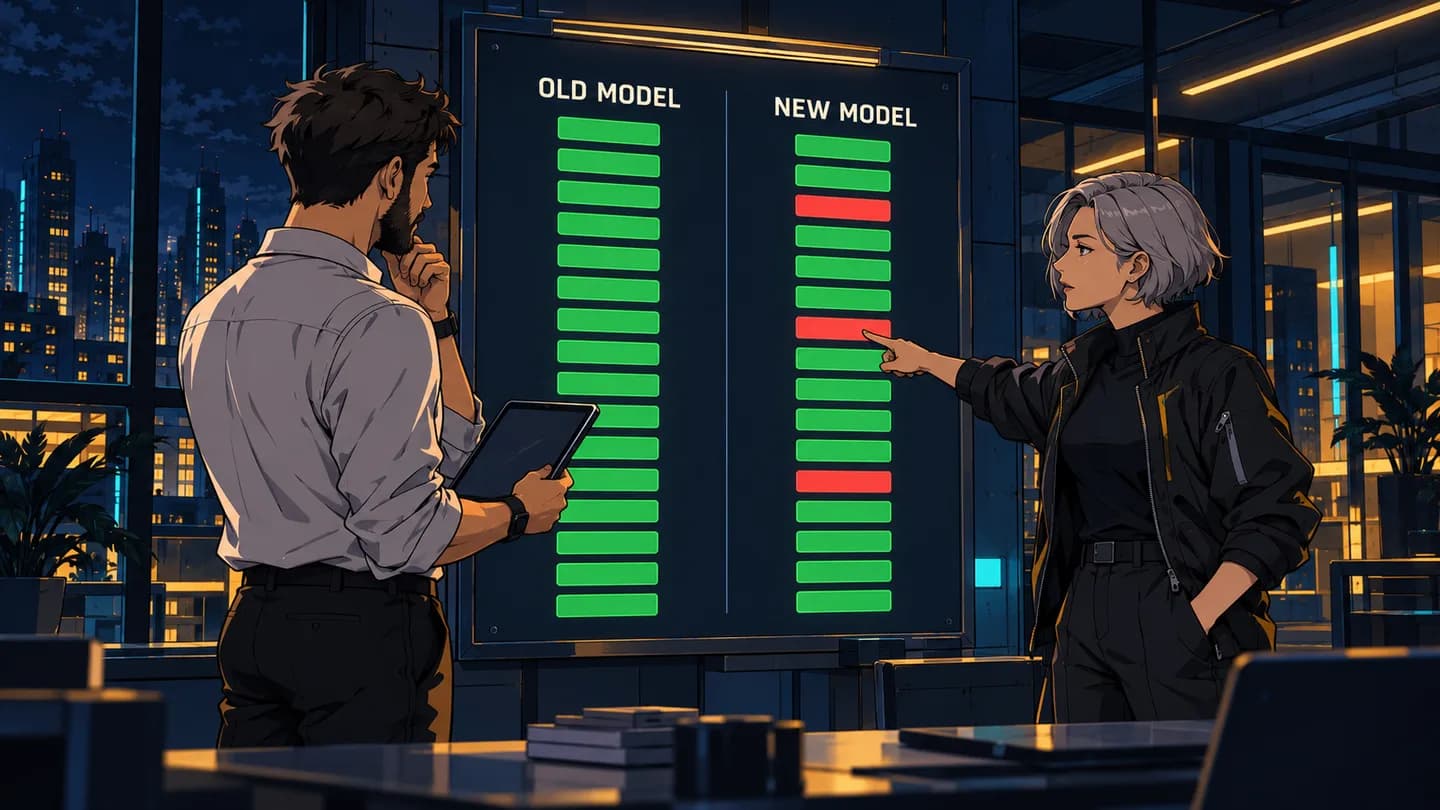
Read the individual cards that changed from pass to fail. Two aggregate scores cannot tell you whether the regression affects a harmless wording preference or a critical business rule.
Procedure 5: Count failures inside successful HTTP responses
Transport availability and task success require separate counters. Anthropic returns refusals as HTTP 200, and OpenAI documents refusals that may not follow the supplied schema, plus incomplete output caused by token limits.
Check application outcomes after parsing the provider response. These are our starting alert thresholds, chosen for investigation; they are not vendor rules:
| Signal | Exact measurement | Our starting alert |
|---|---|---|
| Error rate | (non-2xx + timeouts) / calls, hourly | Over twice trailing seven-day rate; minimum 20 calls |
| Refusals | stop_reason=refusal or refusal field, divided by calls | Above eval baseline; over 1% is suspicious for internal back-office work |
| Schema failures | Validator failures divided by processed items | Over 0.5% daily, or any failure on critical fields |
| Truncation | length, max_tokens, or incomplete response | Sustained nonzero rate |
| Cost per item | Total execution cost divided by completed items | Seven-day median over 1.25 times 28-day median |
| p95 latency | Duration per automation step | Over twice baseline for 30 minutes |
| Model identity | Answering model compared with approved identity | Any unexpected identity |
| Spend versus cap | Month-to-date spend divided by cap | 50% and 80% |
A refusal, truncated answer or invalid schema increments its own counter and prevents the item from being marked complete. The alert includes a case or trace ID.
Every HTTP 200 increments the success count. Repeated attempts increase cost while the dashboard still reports normal service.
For Anthropic, inspect stop_reason and, for refusal context, stop_details. For OpenAI, inspect the refusal field and status: "incomplete" with incomplete_details.reason: "max_output_tokens". Valid JSON alone does not establish schema adherence or correct business values.
Compute cost at the completed-item boundary:
cost_per_item = total_cost_of_all_attempts_and_steps / completed_business_items
Say a hypothetical batch costs $12 across 1,000 attempts but completes only 800 items. Its cost per completed item is $12 / 800 = $0.015, including expenditure on unsuccessful attempts; if nothing completes, report an outage and the accumulated cost. Use the AI automation cost breakdown to price the underlying lines.
Procedure 6: Export model and prompt identity through OpenTelemetry
A useful trace connects a business item to the model call and its outcome. The OpenTelemetry GenAI inference conventions provide shared attribute names, but remain in Development status in the semantic-conventions-genai repository.
Inspect one exported span for each production path. This illustrative OpenAI span shows the fields to preserve:
{
  "name": "chat gpt-4o-2024-08-06",
  "kind": "CLIENT",
  "attributes": {
    "gen_ai.operation.name": "chat",
    "gen_ai.provider.name": "openai",
    "gen_ai.request.model": "gpt-4o-2024-08-06",
    "gen_ai.response.model": "gpt-4o-2024-08-06",
    "gen_ai.prompt.name": "invoice-extraction",
    "gen_ai.prompt.version": "17",
    "gen_ai.response.finish_reasons": ["stop"],
    "gen_ai.usage.input_tokens": 1200,
    "gen_ai.usage.output_tokens": 180
  }
}
The backend receives request and response identities, resolved prompt version, token counts and finish reasons. Failed operations carry error.type, and traces can be joined to business-item records.
Only duration and a prompt nickname arrive. A dashboard cannot distinguish two prompt versions or identify which answering model produced a failed item.
Use inference counters gen_ai.client.inference.usage.input_tokens and gen_ai.client.inference.usage.output_tokens. Record duration with gen_ai.client.inference.duration, and streaming first-chunk time with gen_ai.client.inference.time_to_first_chunk. Our reading of the current docs is that these inference metrics replace older token-counter naming; pin your instrumentation dependency so a convention change is reviewed.
Langfuse and LangSmith both accept OTLP traces. Langfuse exposes HTTP OTLP at /api/public/otel, with traces at /api/public/otel/v1/traces; gRPC is not supported. LangSmith uses an OTLP endpoint ending in /otel, an x-api-key header and an optional Langsmith-Project header.
Plan facts read on 24 October 2026: Langfuse Hobby costs $0 with 50,000 monthly units and 30 days of data access. Core costs $29 monthly with 100,000 units, then $8 per extra 100,000 units; Pro costs $199 monthly, and Langfuse says you can self-host all core Langfuse features for free.
LangSmith Developer costs $0 per seat with 5,000 monthly base traces; Plus costs $39 per seat monthly with 10,000. Base retention is 14 days, extended retention 180 days. Units and traces are different billing measures: compare a representative workload before choosing.
Procedure 7: Version prompts and verify rollback propagation
A prompt edit is a production change even when no application code moves. Store immutable versions, promote them through a label, and log the resolved version in gen_ai.prompt.version.
For Langfuse, move the production label to the approved version, then check each worker's next trace:
prompt_name=invoice-extraction
requested_label=production
resolved_version=17
gen_ai.prompt.version=17
Each worker reports the intended resolved version after refresh. The previous version remains available, with a documented label move for rollback.
Traces contain only production, so different prompt contents look identical. Operators assume changing the label updates every cached worker immediately.
Langfuse returns the prompt labeled production by default. Its SDK caching documentation gives a default TTL of 60 seconds; Python uses cache_ttl_seconds, JavaScript uses cacheTtlSeconds, and zero disables caching. After expiry, the SDK serves stale content while refreshing in the background, so 60 seconds is not a guaranteed rollback deadline.
For urgent containment, stop consequential work while verifying propagation across workers. Keep a fallback prompt for an empty cache when the prompt service is unreachable, and record which fallback version executed.
OpenAI's v1/prompts API shuts down on 30 November 2026. Export prompt content and version history before that date, then verify the application works without fetching from the retiring store. The prompt store needs an exit plan just as the model does.
Procedure 8: Test spend controls as availability controls
An enforced spending limit stops work, so its error path belongs in the availability runbook. Budget alerts require a different response because a notification can arrive while requests continue accruing cost.
Check the billing configuration, alert delivery and application handling of these documented Anthropic and OpenAI responses:
Tier cap:
HTTP 429
error.type = rate_limit_error
error.details.error_code = enforced_spend_limit_reached
retry-after header = absent

Your configured lower limit:
HTTP 400
error.type = invalid_request_error
message begins: You have reached your specified API usage limits

OpenAI organization limit:
HTTP 429
code = organization_spend_limit_exceeded

OpenAI project limit:
HTTP 429
code = project_spend_limit_exceeded
Cap responses stop automatic retries and route pending work to a bounded queue. An owner receives spending warnings before enforcement and can choose whether to authorize more usage.
The retry loop treats every 429 as temporary congestion. Budget exhaustion produces repeated failing calls while scheduled work accumulates without an owner.
Anthropic's tier caps, read on 24 October 2026, are $500 monthly for Start, $1,000 for Build and $200,000 for Scale; Custom has no tier cap. Reaching a tier cap pauses usage until 00:00 UTC on the first day of the next month unless you request a higher limit sooner. Retries, including SDK automatic retries, fail until access resumes.
You can configure a lower limit in Billing. Anthropic also supports workspace spend and rate limits; spend limits cannot be set on the default Workspace, which matters when several automations share an organization.
OpenAI documents hard spend limits at both organization and project level, with the distinct 429 codes shown above. Enforcement is not instantaneous, so recorded spend can slightly exceed the configured amount. Raising or removing the limit lets traffic resume after the update propagates; otherwise, the limit resets at the start of the next monthly cycle.
OpenAI's Terraform spend documentation describes alerts that notify your team without stopping requests. Its threshold_amount uses cents, so 20000 represents $200; spend alerts only notify and never block traffic. Our suggested 50% and 80% warnings need a named recipient and a decision about which work can pause.
Procedure 9: Refresh source data and rebuild retired embedding indexes
A functioning retrieval service can return obsolete policy text with excellent latency. Track source changes separately from model changes, and treat an embedding-model migration as an index rebuild.
Check each indexed document against a source manifest:
{
  "source_id": "returns-policy",
  "source_revision": "approved-17",
  "indexed_revision": "approved-17",
  "source_content_hash": "sha256:example",
  "indexed_content_hash": "sha256:example",
  "embedding_model": "gemini-embedding-2",
  "index_generation": "kb-0042"
}
Changed approved documents trigger re-indexing, removed documents disappear from retrieval, and query embeddings use the model assigned to that index generation.
The index contains an old revision or deleted policy. Query vectors come from a new embedding model while stored document vectors still come from the previous one.
Trigger refreshes from approved source changes, with a periodic reconciliation to catch missed events. Test retrieval with known questions after updates, including a question whose answer changed and one whose source was deleted. The business-data grounding procedure explains how the retrieval layer is built.
Google marks text-embedding-004 as shut down on 14 January 2026, with gemini-embedding-2 as the replacement. It lists 14 May 2028 as the earliest possible shutdown date for gemini-embedding-001. That future date is a retirement floor and requires checking against subsequent notices.
Vectors from different embedding models cannot be assumed comparable, even if their dimensions match. Re-embed the corpus, build a separate index generation and test query embeddings against it before switching. For a hypothetical 20,000 chunks averaging 400 tokens, that means 8,000,000 tokens to re-embed; multiply eight million by the applicable per-token price before scheduling the rebuild.
Procedure 10: Make scheduled-job failures reach an owner
A scheduled automation needs to report that it failed, including failures hidden inside shell pipelines. Iron Goo runs its own scheduled jobs with systemd timers and an OnFailure template that emails the owner the failed unit's last 40 journal lines plus a plain-English explanation.
The invoice batch here is a reusable example of that pattern. Check the unit's failure wiring and pipeline behavior:
[Unit]
Description=Nightly invoice extraction batch
OnFailure=ops-alert@%n.service

[Service]
Type=oneshot
WorkingDirectory=/opt/invoice-bot
ExecStart=/bin/bash -o pipefail -c 'python3 run_batch.py | tee -a batch.log'
A controlled nonzero exit in a test unit activates the alert template. A failing Python command remains a failed job even when tee successfully writes its output.
The pipeline reports tee's successful exit and hides the Python failure. The service remains successful, so OnFailure never activates.
Systemd activates OnFailure units when the service enters the failed state; %n supplies the full unit name. Without pipefail, a shell pipeline normally reports its final command's status. Logging the error is not enough if the service still exits zero.
Iron Goo's scheduled-post publish job runs under flock so two runs never overlap; only that job uses flock. Several of its timers have Persistent=true so a missed trigger runs after downtime. Deliberately best-effort steps can use || true, but each such exception should have an explicit reason. Test the alert route with a disposable unit, and inspect timer history for jobs that never started.
Procedure 11: Contain incidents before changing prompts or models
An incident response should preserve evidence while stopping consequential errors. Prepare the off-switch and manual queue before launch, using the controls in human oversight and guardrails.
Check that one alert can be followed through this ordered response, including a verified return to service:
- →1. Capture the failing item and configuration
Record the trace ID, business-item ID, request and response models, resolved prompt version and index generation. Preserve the input and outcome within your data-handling rules.
- →2. Check identity and recent changes
Compare the answering model with its approved mapping. Inspect recent prompt promotions and index updates before changing another variable.
- →3. Check provider availability and cap errors
Read the provider status page and inspect the actual error body. Anthropic returns
enforced_spend_limit_reachedwith HTTP 429 and noretry-afterheader; OpenAI returnsorganization_spend_limit_exceededorproject_spend_limit_exceededwith HTTP 429. Treat any of these as budget exhaustion; repeated retries cannot repair it. - →4. Stop consequential actions and queue work
Use the off-switch for writes or outbound actions. Route pending items to the manual queue, preserving item IDs so recovery does not duplicate completed work.
- →5. Roll back the identified change
Move the production prompt label to the prior version, restore the approved index, or select a still-supported model. Verify resolved versions across workers before resuming.
- →6. Reproduce, test and reopen gradually
Add the failing input to the eval set and rerun the release gate. Resume a controlled slice, inspect completed items, and record the cause and corrective action.
The problematic action is contained, queued items have owners, and the previously failing input passes a repeatable check. Recovery includes verified output and queue reconciliation.
HTTP errors stop, so work resumes without checking correctness. A rollback points to a retired model, or replay creates duplicate business actions.
If nobody in your company wants to own the retirement calendar, eval runs and on-call response, assign that responsibility through Iron Goo's operations service. Whether the owner is internal or external, put their name and escalation route beside the runbook.
For each recovered incident, retain the failing input as a regression case with an observable expected result. Verify the manual queue is reconciled before closing the incident: every item should be completed, deliberately discarded with a reason, or assigned to a named person.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.