How has SEO changed? The updates behind today's rules

On this page
- The dated changes behind today's SEO rules
- Links and indexing: PageRank survives, Caffeine changed freshness
- Meaning: Hummingbird, RankBrain and BERT weakened keyword formulas
- Quality: Panda and helpful content became core responsibilities
- The 2024 disclosures: attributes revealed possibilities, the court established click use
- AI answers: retrieval continues while the click opportunity changes
- Which Google systems are named, absorbed or outside general ranking?
- Old advice and the dated change that undermined it
- Diagnose a traffic drop against update dates
- Current rules for a business website, with observable checks
SEO
From Google Search's perspective, optimizing for generative AI search is optimizing for the search experience, and thus still SEO.
How has SEO changed? It has accumulated systems for interpreting meaning, evaluating quality and presenting answers on top of its original links and index. The most useful specific: Google requires a page to be indexed and eligible for a search snippet before it can appear as a supporting link in its generative AI features.
Modern SEO means improving your site's presence across those connected systems. Google's generative AI optimization guidance makes the continuity explicit: AI answers draw on core Search ranking and quality systems.
The dated changes behind today's SEO rules
The dates distinguish announcements from changes already running, and ranking changes from indexing infrastructure. A familiar update name can disappear from Google's current list while its underlying work continues inside core systems.
- 9 January 1998PageRank patent filed
Leland Stanford Junior University, the assignee, filed the patent application naming Lawrence Page as inventor, with priority dated 10 January 1997. Patent US 6,285,999 was granted on 4 September 2001; evolved PageRank remains part of Google's core ranking systems.
- 9 June 2010Caffeine indexing announced
Google announced its completed indexing system and claimed 50 percent fresher results. This changed infrastructure, not the ranking criteria that made one page preferable to another.
- 24 February 2011Panda targets low-quality sites
Google announced a change affecting 11.8% of queries, aimed at low-value and copied content. Panda became part of core ranking in 2015 and is now listed as retired.
- 24 April 2012Penguin targets webspam
The announcement targeted practices including keyword stuffing and link schemes, affecting about 3.1% of English queries. Penguin later entered core ranking in 2016.
- August 2013Hummingbird changes overall ranking
Google dates the change to August 2013; its public announcement followed on 26 September 2013. Hummingbird is now listed as retired as the overall systems continued evolving.
- 2015RankBrain introduces deep learning
Google dates RankBrain's launch to 2015 and describes it as its first deep learning system in Search. It remains named in the current ranking-systems guide.
- 23 September 2016Penguin becomes real-time
Google announced that Penguin data refreshes in real time. Penguin devalues spam through more granular ranking adjustments rather than affecting the ranking of the whole site.
- 2018Neural matching arrives
Google introduced a system that considers an entire query or page to match concepts. Neural matching remains a named ranking system.
- 25 October 2019BERT improves query interpretation
Google said BERT would help it understand one in 10 US English searches. The launch emphasized conversational queries and the meaning carried by prepositions.
- 18 May 2021MUM is introduced
Google introduced its multilingual, multimodal model, trained across 75 languages. Its current systems guide says MUM is not used for general Search ranking.
- 18 August 2022Helpful content system announced
Google announced a new site-wide signal; rollout began on 25 August 2022. The separately named system became part of core ranking in March 2024.
- 15 December 2022Experience joins E-E-A-T
Google added experience to its quality-rater framework. This clarified the value of firsthand knowledge without introducing a public E-E-A-T score.
- 5 March 2024Core quality changes and new spam policies
Google began a core update and announced policies covering scaled content abuse, site reputation abuse and expired domain abuse. Helpful content assessment became part of core systems.
- 14 May 2024AI Overviews begin US rollout
Google began rolling AI Overviews out to everyone in the United States. Generated summaries added another presentation layer to Search.
- 27 May 2024Leaked documentation becomes public
Published analysis described 14,014 attributes in internal API documentation. The material exposed field names and descriptions without supplying ranking weights.
- 5 August 2024Court opinion documents NavBoost
Judge Amit P. Mehta's opinion described query-document click memory trained on 13 months of user data. Before 2017, that window had been 18 months.
- 5 March 2025 and 20 May 2025AI Mode moves from Labs to US rollout
AI Mode began as a Labs experiment on 5 March 2025. On 20 May 2025, Google announced US rollout without a Labs sign-up requirement.
- 15 May 2026Google publishes its generative AI optimization guide
The guide's first publication already said optimizing for generative AI search is still SEO. It says Google Search ignores llms.txt, there is no requirement to chunk content, and no special schema.org markup is needed for generative AI search. It was last updated on 10 July 2026.
Links and indexing: PageRank survives, Caffeine changed freshness
PageRank supplied a way to use the web's link structure as evidence about pages. The original Brin and Page search-engine paper appeared in 1998; the patent's formal title was “Method for node ranking in a linked database.” Google still names an evolved version of PageRank among its core ranking systems.
For a business site, the practical distinction is between publishing a claim and having other sites provide evidence that the page deserves attention. A relevant editorial link can help users discover a resource and connects it to the wider web. Counting links without considering where they come from loses that context.
Caffeine addressed another problem: keeping the searchable index fresh as the web changed. Google's announcement on 9 June 2010 claimed results were 50 percent fresher than its previous index. That was an indexing claim, not a promise that freshly dated pages would outrank better answers.
These mechanisms answer different questions. Crawling and indexing make a page available for retrieval; ranking systems decide how it compares with alternatives. Changing a publication date cannot repair an inaccessible page or supply the evidence missing from its content.
Penguin made the link distinction expensive to ignore. Its announcement on 24 April 2012 targeted webspam, including link schemes, and put the effect at about 3.1% of English queries. Purchased link volume had become a particularly poor substitute for earning attention.
The important later change came on 23 September 2016. Google's Penguin core announcement said its data refreshed in real time and that it devalued spam through more granular ranking adjustments, rather than affecting the ranking of the whole site.
My practical reading: routine disavow work for unsolicited junk links is usually a low priority for an ordinary company website. That follows from devaluation; it is not a guarantee that every harmful link is ignored. A manual action for participating in link schemes remains a separate problem requiring attention.
Rule it left: Make important pages accessible, earn relevant links and check for actual manual actions before treating every strange inbound link as an emergency.
Meaning: Hummingbird, RankBrain and BERT weakened keyword formulas
Google's own date for Hummingbird is August 2013. The announcement happened on 26 September 2013, which explains the September launch date repeated in many histories. Contemporary reporting attributed an effect on about 90% of searches to Amit Singhal; that is a reported figure, not a measurement supplied by Google's current systems guide.
Hummingbird represented a major improvement to overall ranking, commonly associated with interpreting whole queries and conversational meaning. The business implication was a weakening case for separate pages targeting tiny wording variations. A useful page could address a subject without repeating every searcher's exact phrasing.
RankBrain extended concept matching through deep learning when it launched in 2015. Google's explanation uses a query about the consumer at the highest level of a food chain to illustrate recognizing the concept “apex predator.” The system can retrieve relevant material even when some of the query's exact words are missing from the page.
A Bloomberg interview published on 26 October 2015 reportedly described RankBrain as the third-most-important signal. Treat that as a historical description from an interview, not a current weighting chart. Google's current documentation still names RankBrain, which is the useful answer to whether it remains in use.
Neural matching followed in 2018, considering an entire query or page to understand concepts. BERT's announcement on 25 October 2019 focused on language relationships, especially conversational searches where words such as “for” and “to” change the request. Google initially said BERT would help interpret one in 10 US English searches.
BERT is not an instruction to sprinkle related vocabulary across a page. It helps explain why clear sentences and explicit relationships matter: a visa requirement for a traveler going to a country is different from a requirement for someone coming from it. Both BERT and neural matching remain named systems.
For a business, building topical authority around a defined subject means organizing useful answers and supporting detail around actual customer decisions. It does not require a separate URL for each reordered phrase. The editorial question is whether the next page answers a distinct need.
MUM needs a separate label. Introduced on 18 May 2021, it was described as multilingual and multimodal, trained across 75 languages, with Google claiming it was 1,000 times more powerful than BERT. Those model claims do not establish a ranking update: Google says MUM is not currently used for general ranking, while naming specific applications.
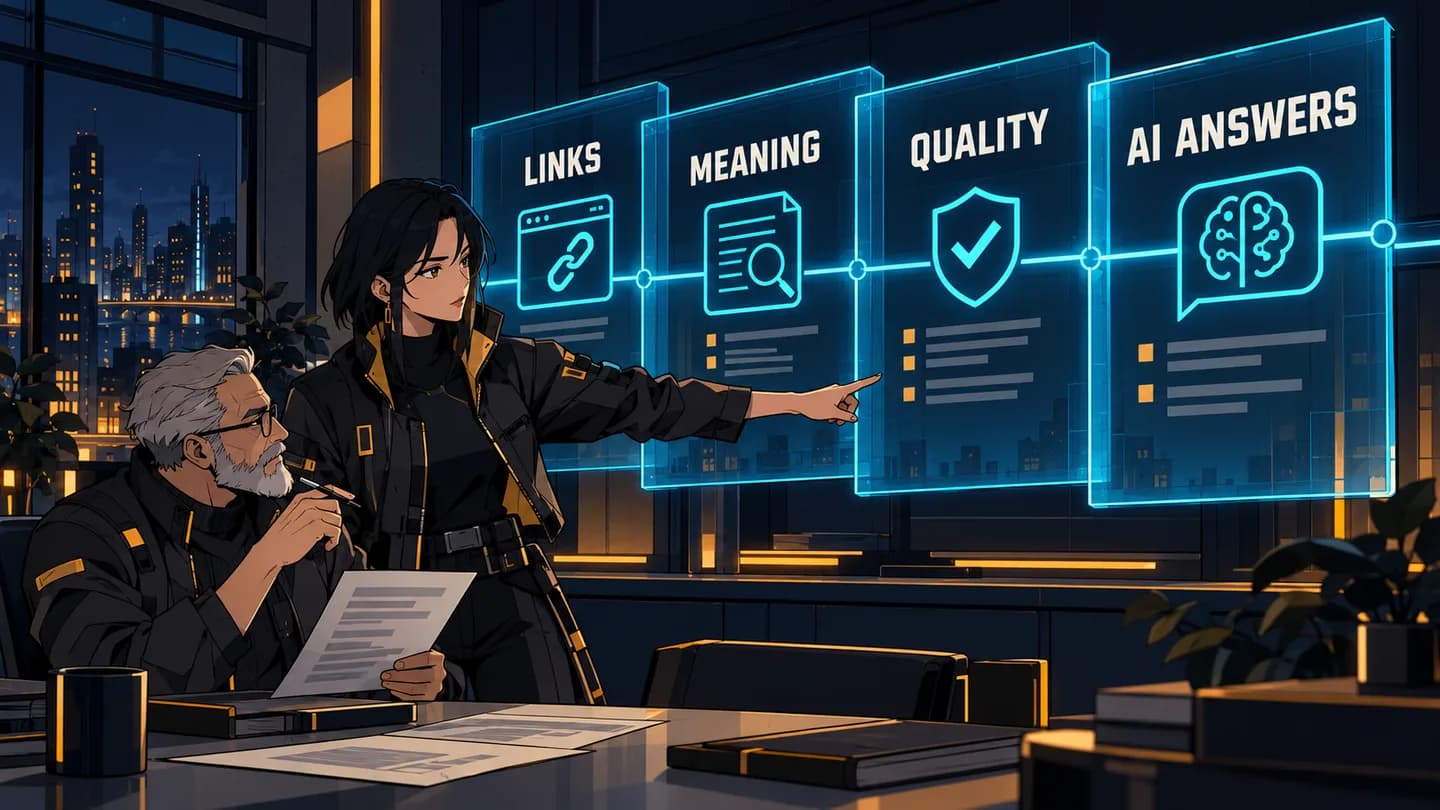
The eras overlap because interpreting language did not remove link analysis, and AI answers did not remove quality assessment. Each added capability works alongside earlier mechanisms.
Rule it left: Give each page a distinct purpose, explain relationships clearly and cover the customer's question without manufacturing URLs for keyword variants.
Quality: Panda and helpful content became core responsibilities
Panda's announcement on 24 February 2011 explicitly targeted low-quality sites, including copied material and pages adding little value. Google said the change noticeably affected 11.8% of queries. The site-level wording matters: a large weak section was not safely isolated just because the sales pages were competent.
Google now says Panda evolved into core ranking in 2015. That retires the separately named system, not the need to evaluate weak content. Buying a “Panda recovery” package today gives an old label to work that needs a current diagnosis.
The helpful content announcement on 18 August 2022 again described a site-wide signal identifying content with little value or limited added value. Rollout began on 25 August 2022, with later rounds beginning on 5 December 2022 and 14 September 2023. In March 2024, the system became part of core ranking.
E-E-A-T entered this history through quality-rater guidance. Google added the extra E for experience on 15 December 2022. A rater framework provides a way to assess quality; it does not give your website a public score that a plugin can raise.
The practical questions are concrete: who produced the content, how was it produced, and why does it exist? Firsthand evidence might include an actual process, documented limitations or an explanation of how a result was obtained. For health or financial subjects, firsthand experience cannot excuse inaccurate advice or disagreement with established expert consensus.
The core update beginning on 5 March 2024 combined quality changes with new spam policies. Its rollout lasted 45 days; Google said it completed on 19 April 2024. In an update published on 26 April 2024, Google reported 45% less low-quality, unoriginal content in results, exceeding its initial 40% expectation.
That is Google's aggregate assessment. It does not mean every search improved by 45%, or that any individual site's visibility should move by that amount. Using a platform-wide claim as your recovery forecast would be ambitious accounting.
The accompanying policies named scaled content abuse, site reputation abuse and expired domain abuse. Google's scaled content abuse definition centers on generating many pages primarily to manipulate rankings without helping users, “no matter how it's created.” Its February 2023 guidance had already said appropriate AI or automation use was not against its guidelines.
Rule it left: Audit whole sections for original value, document who knows the subject and judge production methods by the usefulness of their output.
The 2024 disclosures: attributes revealed possibilities, the court established click use
The documentation publicized on 27 May 2024 contained 14,014 attributes across 2,596 modules, according to the published analyses. Reported examples included siteAuthority, hostAge and click-related fields such as goodClicks, badClicks and lastLongestClicks. Those names deserved investigation, not instant conversion into ranking instructions.
A field can exist for storage, experimentation or a purpose the reader cannot establish. Even the analysis discussing siteAuthority acknowledged uncertainty about how it was computed or used. The distinction between a stored attribute and an active ranking contribution is substantial.
The leak does not establish a field's production use, weight or direction of effect. Google's statement to The Verge cautioned against assumptions based on out-of-context, outdated or incomplete information.
Google's response reported by The Verge on 29 May 2024 supplies a necessary limit. Neither “the documentation proves nothing” nor “the ranking recipe is public” is a defensible reading. It reveals implementation vocabulary while leaving major causal questions unanswered.
The court record provides firmer evidence for one consequential mechanism. The memorandum opinion dated 5 August 2024, in United States v. Google, describes NavBoost as pairing queries and documents by memorizing user click data. It remembers which documents people clicked after entering a query.
The opinion gives the training window: Google trained NavBoost on 18 months of user data before 2017 and on 13 months of user data since then. That directly answers whether Google uses clicks in ranking, while providing no universal click-through-rate target for your pages. Training on months of query-document interactions is quite different from a short burst of purchased traffic.
My interpretation is that accurate titles and pages that satisfy the chosen query are the defensible response. The click-related fields reported in the leak suggest distinctions among interactions, making raw click volume an inadequate model. Neither source establishes a reliable recipe for click schemes.
Search Console CTR can identify a title or query mismatch, but it does not expose NavBoost's internal judgments. Analytics engagement also cannot tell you whether a particular visit became a positive ranking signal. Measure those things as business diagnostics and preserve that evidentiary boundary.
Rule it left: Make the search result promise accurate and the landing page useful; do not turn hidden click mechanisms or leaked field names into purchased signals.
AI answers: retrieval continues while the click opportunity changes
AI Overviews began rolling out to everyone in the United States on 14 May 2024. AI Mode entered Labs on 5 March 2025 and began its wider US rollout on 20 May 2025. These are dated product changes, not announcements that the searchable web had become unnecessary.
AI Mode's query fan-out issues multiple related searches concurrently across subtopics and data sources. Google's generative AI documentation describes grounding answers in retrieved information and core Search systems. A narrowly phrased user question can therefore lead to retrieval across several related needs.
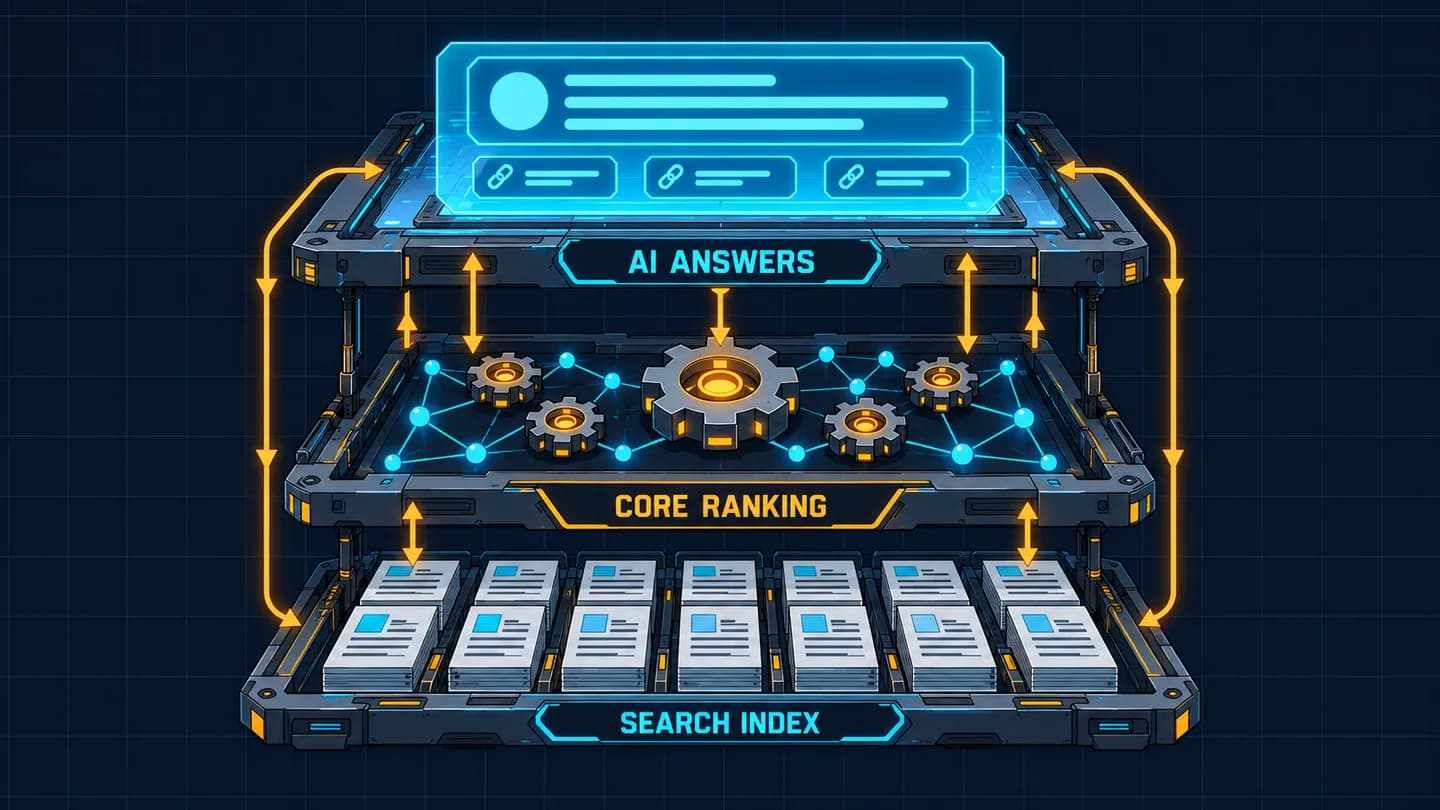
The generated answer sits above retrieval and ranking. Eligibility and useful source material remain necessary even when the user sees an AI response first.
The commercial consequence is a changed distribution of clicks. Pew Research's study published on 22 July 2025 analyzed March browsing data from 900 US adults. Users clicked a traditional result in 8% of visits with an AI summary, compared with 15% without one.
Links inside the summary received clicks in 1% of visits. Browsing ended on 26% of pages with a summary, compared with 16% without one. These are observed groups of visits, not a controlled experiment proving every difference was caused by the summary.
Google separately claimed on 21 May 2025 that clicks from AI Overview pages were higher quality, with users more likely to spend longer on the site. That remains Google's claim; it does not cancel Pew's lower click frequency. Whether SEO still pays when AI answers absorb some clicks depends on the queries you reach and the business value of the visits you retain.
Google's guidance updated on 10 July 2026 says to ignore several proposed tactics for Google Search:
- llms.txt: Google Search itself does not use it.
- Artificial chunking: reorganizing content into supposed AI-sized pieces is unnecessary.
- Rewriting purely for AI: you do not need to write in a specific way just for generative AI search.
- Inauthentic mentions: manufactured references are not a sound visibility strategy.
- Special AI schema: no special schema.org markup is required for generative AI search.
Those statements apply to Google Search. ChatGPT and Perplexity are separate systems, so Google's position cannot establish their requirements.
Google also warns that pages created for every fan-out variation primarily to manipulate rankings or generated responses violate its scaled content abuse policy. The sensible response to broader retrieval is useful coverage of genuine subquestions. Manufacturing another keyword doorway changes its label without improving its purpose.
SEO is therefore still operating, but rankings alone describe less of the commercial outcome. Your measurement needs to connect visibility to visits and useful actions. A citation without a visit may provide exposure, but it cannot be booked as an inquiry.
Rule it left: Preserve Search eligibility, publish information worth retrieving and measure the business result of the traffic that reaches you.
Which Google systems are named, absorbed or outside general ranking?
Google's ranking-systems guide, last updated on 10 December 2025, distinguishes current systems from retired names. Retirement often means integration or continued evolution, so the old problem has not necessarily disappeared.
| System | Google's listed status | Practical consequence |
|---|---|---|
| PageRank | Live and named, evolved within core | Relevant links still deserve attention. |
| RankBrain | Live and named | Exact query wording is not required for relevance. |
| Neural matching | Live and named | Whole-page and whole-query meaning matter. |
| BERT | Live and named | Write relationships and conditions clearly. |
| Passage ranking | Live and named | Make useful explanations identifiable within longer pages. |
| Reviews system | Live and named | Reviews require attention to their substantive quality. |
| Spam detection systems | Live and named | Manipulative production and promotion remain risky. |
| Panda | Retired; incorporated into core in 2015 | Evaluate low-value sections through current quality guidance. |
| Penguin | Retired; incorporated into core in 2016 | Understand real-time devaluation when assessing links. |
| Hummingbird | Retired; overall systems continued evolving | Meaning-based matching outlasted the update name. |
| Helpful content system | Retired; incorporated into core in March 2024 | Helpful content assessment continues inside core. |
| MUM | Not currently used for general ranking | Do not commission a general MUM ranking optimization project. |
Caffeine belongs to indexing infrastructure; E-E-A-T belongs to quality assessment guidance. NavBoost is established by the court record discussed earlier, while the leak is documentation evidence. Putting everything into one list of “algorithm factors” erases distinctions you need for diagnosis.
Old advice and the dated change that undermined it
Historical advice can survive long after its assumptions fail. Use the mechanism and date to decide whether a recommendation still addresses your actual problem.
| Advice still circulating | Dated correction | Better action |
|---|---|---|
| Hit a fixed keyword density | Hummingbird, August 2013; BERT announcement, 25 October 2019 | Explain the subject clearly without a repetition quota. |
| Publish one page for every phrase variation | RankBrain, 2015; scaled content abuse policy, 5 March 2024 | Separate pages by distinct user needs. |
| Wait for the next Penguin refresh | Penguin core announcement, 23 September 2016 | Assess current links and manual actions. |
| Disavow every unsolicited junk link | Penguin's devaluation change, 23 September 2016 | Prioritize evidence of an actual link problem. |
| Diagnose a new Panda penalty | Panda entered core in 2015 | Investigate current core quality and technical causes. |
| Optimize general rankings for MUM | Introduced 18 May 2021; current guide excludes general ranking use | Work on documented Search requirements. |
| Treat AI authorship as an automatic violation | AI guidance, February 2023; spam policies, 5 March 2024 | Assess purpose, scale and added value. |
| Buy clicks because Google uses clicks | NavBoost documented in the opinion of 5 August 2024 | Improve query fit without assuming raw clicks equal satisfaction. |
| Install llms.txt or special schema for Google AI answers | Guidance updated 10 July 2026 | Check indexing, snippet eligibility and source quality. |
Diagnose a traffic drop against update dates
Start with the affected pages and queries, not the update name attracting attention. A dashboard date gives you a possible relationship; your own technical and performance evidence must establish what changed.
- →Check technical changes first
Inspect affected URLs and review migrations, redirects, robots rules and indexing directives. Record whether the drop coincided with a deployment or a loss of indexability.
- →Separate visibility from clicking
In Search Console Performance, compare 28 days before and after the drop with consistent filters. Inspect impressions, clicks, CTR and average position by query and page; similar visibility with lower CTR suggests a different problem from falling positions.
- →Overlay the complete update window
Open the Google Search Status Dashboard history and record each relevant update's start date and duration. The core update beginning on 5 March 2024 lasted 45 days, so comparing only its announcement day misses most of the rollout.
- →Match the hypothesis to the affected pages
A broad position decline during a core rollout makes quality worth investigating; a templated section falling near a spam update makes policy review sensible. Stable positions with lower informational-query CTR justify inspecting current results for AI answers, but timing and averages prove neither cause.
- →Record a repair and measure its result
Write down the affected page group, evidence and proposed repair before making changes. Use the full measurement and repair loop to distinguish sustained improvement from ordinary movement.
The dashboard history lists, among others, core updates beginning on 27 March 2026 and 21 May 2026, plus a spam update beginning on 24 September 2026. Read the relevant entry's full duration before assigning a loss to it. For ongoing work, measuring SEO and fixing decay connects diagnosis to repairs and follow-up measurement.
Current rules for a business website, with observable checks
For a company with 10 to 200 people, my priority order starts with eligibility and useful pages. Elaborate attribution is poor compensation for a service page Google cannot index or a hundred articles that repeat the same advice.
-
Make important pages indexed and snippet-eligible.
Check: URL Inspection reports “URL is on Google” for each priority URL, and the page has nonosnippetrestriction. Confirm the indexed URL is the version you intend customers to reach. -
Verify access to Google's generative AI features.
Check: Confirm the site is included in “Search generative AI features” in Search Console. Use the Generative AI performance report named in Google's July guidance when assessing that visibility. -
Organize pages around distinct customer needs.
Check: Put each indexable page beside its intended question in a spreadsheet. When several thin pages answer the same question, plan a merge; when an established site needs that structural repair, our SEO service rebuilds keyword-era sites around topics. -
Require a specific contribution from every important page.
Check: Identify the original evidence, explanation or practical detail a reader gains. Verify that the author and review process match the subject, with support for consequential claims. -
Repair weak sections as sections.
Check: Group pages by template or editorial purpose and identify those lacking distinct value. Assign each an improvement, merge or removal decision, accounting for useful existing traffic and links. -
Make titles and landing pages agree.
Check: Compare Search Console CTR by query alongside position, then open the result and page together. Confirm the promised answer is present and easy to locate; CTR is a diagnostic, not a NavBoost score. -
Pursue relevant links and investigate real violations.
Check: Review Search Console's Manual actions report and sample important referring pages. Distinguish earned recommendations from links your company arranged primarily to manipulate rankings. -
Connect visibility to commercial outcomes.
Check: Track inquiries or other meaningful actions alongside search clicks. Treat branded search demand as a useful business indicator; its value as a deliberate ranking strategy remains an inference, not a documented formula. -
Date your diagnoses.
Check: Keep deployment dates, Search Status Dashboard rollout windows and page-group performance in the same record. Require supporting evidence before labeling a loss an update effect. -
Keep Google AI work tied to documented requirements.
Check: Every proposed task should name its observable benefit, such as indexability, clearer information or valid rich-result markup. If the deliverable is llms.txt, artificial chunks or special AI schema solely for Google Search visibility, ask for the documented requirement before allocating the budget.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.