Topical authority without the guesswork

On this page
- Is topical authority a Google ranking factor?
- What is Google's topic authority system?
- What do siteFocusScore and siteRadius actually mean?
- Does smallPersonalSite mean Google boosts small businesses?
- Does Google's website representation vector patent prove topical authority exists?
- How can a small website outrank big websites?
- Does topical authority replace backlinks?
- How many articles do you need for topical authority?
- What should a small company publish first?
- Does publishing off-topic content hurt rankings?
- Does AI-generated content build topical authority?
- How do you measure topical authority without a paid tool?
- How long does it take to build topical authority?
- What did John Mueller say about topical authority?
SEO
Topical authority is a search engine's evidence that a site reliably resolves the questions inside one defined subject. Its less obvious consequence concerns sections: Google says it can measure an independent or starkly different section as a standalone site, so an off-topic section does not automatically inherit its host's strength. That gives a small, focused company an opening against a much larger domain.
Google described that section treatment in November 2024, separately from its site reputation abuse policy. The useful implication is that you should assess the actual competing section and the questions it answers. Comparing your entire company website with a national publisher's entire domain tells you surprisingly little about whether either has a useful answer to a particular question.
Is topical authority a Google ranking factor?
There is no published general web ranking factor with a disclosed formula called topical authority. Google has a named news topic authority system, while leaked documentation describes topic-related fields intended for scoring; neither gives you a public score for a company website.
The practitioner term describes a reasonable objective: become a dependable source within a defined subject. Trouble starts when evidence about news publishing, stored data and general relevance gets combined into one imaginary meter.
| Claim | Where it comes from | What it actually proves |
|---|---|---|
| News topic authority system | Google's May 2023 Search Central post | Google describes a system for identifying expert sources for news queries. |
| Good site-wide signals do not make everything rank | Google's ranking systems guide | Site-wide signals contribute to page assessment without guaranteeing every page's performance. |
siteFocusScore and siteRadius exist | Content Warehouse documentation | Google stores descriptions of topical focus and page deviation, without disclosed weights or thresholds. |
siteAuthority is applied in Qstar | Content Warehouse documentation | An authority field has a documented scoring connection; its calculation is undisclosed. |
| Website representation vectors can classify sites | Patent application US20200050707A1 | Google documented an approach in an abandoned application; deployment is unproven. |
| Topical authority is relevance by another name | Search Engine Journal's 13 November 2023 report of a Reddit exchange | Mueller endorsed that interpretation in a particular exchange. |
Google's ranking systems guide says its systems work at page level and also use site-wide signals and classifiers. Its wording explicitly rejects the assumption that good site-wide signals make all content rank highly, or that poor ones make all content rank poorly.
The ranking systems guide does not list topic authority as a named general web ranking system. It does list local news systems, which fits the narrower news post.
The three uses of the name support different claims. Evidence that a news system exists does not establish how a commercial service page is scored.
What is Google's topic authority system?
Google's topic authority system helps identify expert sources for news queries in specialized areas such as health, politics and finance. Jen Granito, Group Product Manager, Search, explained the system Google developed in a Search Central post dated 23 May 2023.
The post names three prominent signals:
- Notability for a topic or location. People seeking Nashville high school football coverage often turn to The Tennessean.
- Influence and original reporting. Google considers how other publishers cite original reporting; the post also references the Highly Cited label introduced in 2022.
- Source reputation. A history of high-quality reporting, recommendations from expert sources and journalistic awards can provide evidence of reputation.
Google says topic authority has been an important signal for better serving local news queries in Top Stories and other news features. Local publishers are more likely to show up more often for news events they cover in their area.
The Search Central post on news topic authority describes news queries only. Applying its explanation directly to a maintenance service page would extend the evidence beyond the post's stated scope.
Publishers looking for success with topic authority should do exactly what their publications would normally do: provide great coverage about the areas and topics they know well.
For a company website, that is sensible editorial advice. It does not establish that the same news system evaluates your quotation request page.
What do siteFocusScore and siteRadius actually mean?
siteFocusScore describes how focused a site is on one topic, and siteRadius describes how far page embeddings deviate from a site embedding. Their documentation supplies no scoring direction, weight or threshold.
The module QualityAuthorityTopicEmbeddingsVersionedItem contains five fields. Its descriptions are short enough to reproduce without interpretive decoration:
siteEmbedding: "Compressed site/page embeddings."siteFocusScore: "Number denoting how much a site is focused on one topic."siteRadius: "The measure of how far page_embeddings deviate from the site_embedding."pageEmbedding: a string field with no description.versionId: an integer field with no description.
The versioned topic-embedding documentation records these fields. Embeddings are numerical representations that can support similarity comparisons, but the descriptions do not identify the embedding model.
In CompressedQualitySignals, topicEmbeddingsVersionedData has this description: "Versioned TopicEmbeddings data to be populated later into superroot / used directly in scorers." The same module describes siteAuthority as "site_authority: converted from quality_nsr.SiteAuthority, applied in Qstar."
Those scoring-related field descriptions establish intended scoring connections. They do not reveal a ranking formula.
Specifically, the descriptions do not say:
- How much any field contributes.
- Whether higher focus helps, or higher radius hurts.
- Which thresholds matter.
- Whether “site” means a domain, host or section.
- Which embedding model produces the values.
- Which query classes, if any, use these values in ranking.
Google confirmed the documents were authentic, while cautioning against conclusions drawn from incomplete context. A field name cannot tell you whether deleting a page will improve another page's rankings.
Google spokesperson Davis Thompson told The Verge: "We would caution against making inaccurate assumptions about Search based on out-of-context, outdated, or incomplete information." That caution about the leaked documents belongs beside any confident claim that a radius value proves an off-topic penalty.
Does smallPersonalSite mean Google boosts small businesses?
No: smallPersonalSite describes personal-site promotion, with a reference to personal blogs. Nothing in its description establishes a boost for company websites or businesses of a particular size.
Its exact description is "Score of small personal site promotion go/promoting-personal-blogs-v1". A 20-person manufacturer's website is not automatically covered by a field whose wording names personal blogs.
The same QualityNsrNsrData module contains isElectionAuthority, described as "Bit to determine whether the site has the election authority signal, as computed by go/election-authority". That is evidence of a narrow authority flag for a particular topic.
It does not follow that every commercial subject has an equivalent switch. Treat both fields as evidence of specific documented concepts, with their actual boundaries intact.
Does Google's website representation vector patent prove topical authority exists?
The patent application documents a way to classify websites using representation vectors; it does not prove Google deployed that method. Application US20200050707A1, titled “Website representation vector,” is marked Abandoned.
Filed on August 10, 2018, with Yevgen Tsykynovskyy named as inventor, it describes comparing a site's representation vector with composite representations of already-classified groups inside a knowledge domain. Its examples distinguish sites authored by experts such as doctors, apprentices such as medical students, and laypersons.
The website representation vector application is useful evidence that this classification approach was documented. It provides no published scoring weights and no proof that the described approach operates in current Search.
A patent is a technical document, not a receipt for production deployment. You can use the idea to understand possible mechanisms without turning it into an optimization requirement.
How can a small website outrank big websites?
A small website can compete by answering useful, specific questions that a larger site's relevant section does not resolve. Google's section-level assessment and site diversity system also limit the assumption that a large domain automatically controls every related result.
On November 19, 2024, Google explained that its systems can treat independent or starkly different sections as standalone sites. Those sections may stop benefiting from site-wide signals because Google measures them independently.
The same announcement defines site reputation abuse as publishing third-party pages to exploit the host's ranking signals. These are related issues with different tests: independent section assessment is a ranking mechanism, while site reputation abuse concerns a particular publishing practice.
Google's explanation of independent section assessment therefore gives a more useful competitive question: what strength does the competing section have on its own? A famous masthead does not answer that question.
There is also a limit on result ownership. Google's site diversity system generally avoids showing more than two web page listings from one site in its top results, generally counting subdomains with the root domain.
Neither mechanism guarantees your placement. Your opportunity is a question where you have a useful answer and the larger competitor has a weak answer or no relevant page.
Does topical authority replace backlinks?
No, focused coverage does not establish that links have stopped contributing to rankings. The available evidence keeps citation, anchors and quality-related signals in the picture.
Reported trial exhibits describe Anchors, Body and Clicks contributing to a topicality signal called T*, alongside a separate PageRank-related quality signal called Q*. These reported descriptions are not a complete scoring formula, but they contradict a simple claim that subject coverage replaces links.
Google's news system is more explicit about outside recognition. Its influence signal considers citations of original reporting, while source reputation can include recommendations from expert organizations.
My practical judgment is to build pages that deserve relevant references while keeping acquisition work connected to the subject you actually serve. A large article inventory does not, by itself, establish reputation with anyone.
How many articles do you need for topical authority?
There is no sourced universal article count that establishes topical authority. The required coverage depends on the questions inside your subject and whether existing pages answer them adequately.
Numbers such as 15 to 20 articles for a niche or 50 or more for a broad subject circulate without a supporting study. They are publishing targets dressed as thresholds.
Google's helpful-content guidance gives an explicit “No” to a preferred word count. It also rejects adding lots of content primarily to make a site appear fresh.
Your planning unit should be a real question assigned to a URL. Several related questions may belong on one page when a reader reasonably expects their answers together; splitting each variation into a separate article can create repetitive pages.
Start with a topic map of clusters and their questions, then inspect what existing URLs already answer. Count unresolved questions before commissioning new pages.
What should a small company publish first?
Publish specific questions your company can answer accurately, with one clear URL responsible for each question. My preferred practice is to publish those pages before the broad head-term page, because they establish useful material for the eventual hub.
That publishing order is a working method, not a Google rule. It gives you observable checks: each cluster has a written question list, each question has one assigned URL, and no URL is responsible for two separate clusters.
Use Search Console queries, sales calls and support tickets to identify questions with a real audience. Record the evidence beside the question so an editor can distinguish customer demand from a keyword tool's suggestions.
Each new cluster page should link to its hub, and the hub should link back. Service pages should receive links from pages discussing the problems those services solve; a deliberate internal linking architecture makes those relationships explicit.
The head-term page can then explain the subject and direct readers toward useful details. A hub with empty destinations is mostly a table of contents awaiting a book.
Does publishing off-topic content hurt rankings?
Off-topic content does not have a documented automatic penalty based on a disclosed radius threshold. Google does warn against scattered publishing for search traffic, and it may assess a starkly different section independently.
A useful editorial test is whether the section would look like another company's website if you removed the logo. If it would, decide whether it belongs on a separate property or should be dropped.
Google's helpful-content questions ask whether a site has a primary purpose and an intended audience. They also flag entering a niche without real expertise mainly because it looks like a source of search traffic.
Poor usefulness is a separate problem from topical distance. In its August 2022 helpful-content announcement, Google said removing unhelpful content could help other pages; the former helpful content system became part of core ranking systems in March 2024.
Audit thin pages for an actual missing answer before deciding their fate. Repair pages that serve a real customer question, and remove pages whose only reason to exist is an old traffic forecast.
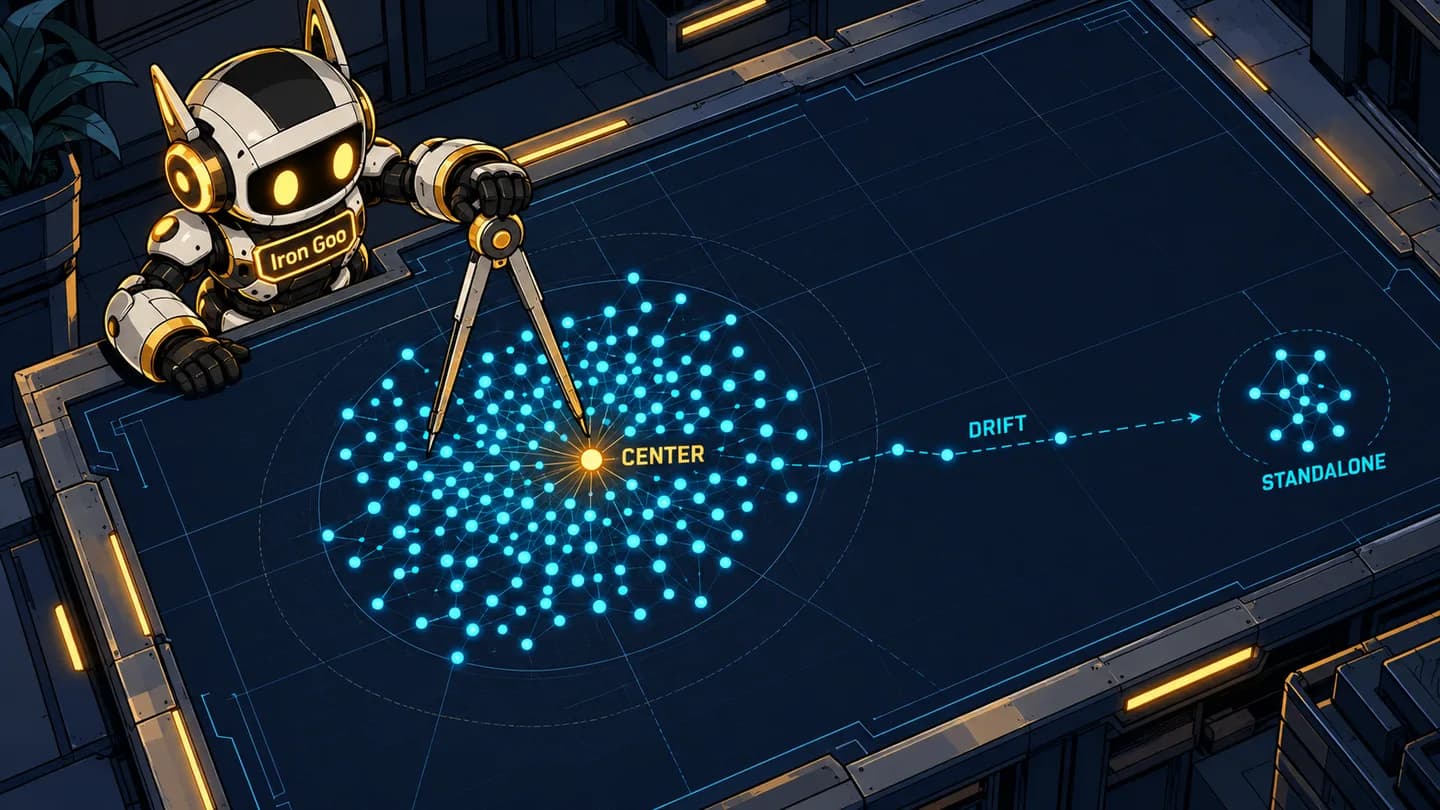
Distance can suggest a page to inspect, while a separate section may need assessment around its own center. Neither picture establishes a penalty threshold.
Does AI-generated content build topical authority?
AI-generated content can contribute useful answers, but its production method does not establish authority. Google's scaled content abuse policy concerns many pages created primarily to manipulate rankings without helping users, regardless of how they are created.
The policy explicitly includes generating many pages with generative AI tools without adding value for users. Human production does not excuse the same underlying behavior.
For a company website, assign a knowledgeable reviewer who can verify the actual answer. Check whether the page resolves a real question, whether its technical claims are supportable and whether its advice matches the service you provide.
Then apply the same test to the whole publishing plan. Fifty individually readable pages across unrelated subjects can still reflect a search-first strategy.
The observable failure is a growing inventory without useful coverage. Publishing software can multiply pages much more easily than a company can acquire expertise.
How do you measure topical authority without a paid tool?
You cannot read Google's internal topical fields, but you can measure question coverage and visibility using a topic list plus Search Console. Pair that with a crude page-distance check to find pages worth reviewing, while keeping both measurements separate from Google's scores.
Choose a consistent date range and search type in the Performance report. Export Queries.csv, then compare it with topic_map.csv, which needs the columns query,cluster.
Define visible share as mapped questions with impressions divided by all mapped questions. Define top 10 share as mapped questions whose exported average position is 10 or better, divided by all mapped questions.
How do I calculate coverage from a Search Console export?
This script counts mapped questions, visible questions and questions with average position at or above the top 10 cutoff for each cluster. Save it as coverage.py and run python coverage.py topic_map.csv Queries.csv.
The column names Top queries, Impressions and Position come from an English-language Search Console export, whose header is Top queries,Clicks,Impressions,CTR,Position. Non-English interfaces translate the headers and may write decimals with commas, so adjust the names in COLS and the matching row[...] lookups to match your file, and adapt number parsing to its decimal format. If a required column is missing, the script stops with a message naming it and showing the headers it found.
import csv, sys
from collections import defaultdict

# topic_map.csv: query,cluster   Queries.csv: the Search Console Performance export
# Column names below are from an English-language export; rename them if yours differ.
COLS = ("Top queries", "Impressions", "Position")

mapped = {}
with open(sys.argv[1], newline="") as f:
    for row in csv.DictReader(f):
        mapped[row["query"].strip().lower()] = row["cluster"]

seen = {}
with open(sys.argv[2], newline="", encoding="utf-8-sig") as f:
    reader = csv.DictReader(f)
    missing = [c for c in COLS if c not in (reader.fieldnames or [])]
    if missing:
        sys.exit(f"Queries.csv lacks columns {missing}; found {reader.fieldnames}")
    for row in reader:
        q = row["Top queries"].strip().lower()
        seen[q] = (int(row["Impressions"].replace(",", "")), float(row["Position"]))

stats = defaultdict(lambda: [0, 0, 0])  # mapped, with impressions, top 10
for q, cluster in mapped.items():
    s = stats[cluster]
    s[0] += 1
    if q in seen and seen[q][0] > 0:
        s[1] += 1
        if seen[q][1] <= 10:
            s[2] += 1

print("cluster,mapped,visible,top10,visible_share")
for cluster, (m, v, t) in sorted(stats.items()):
    print(f"{cluster},{m},{v},{t},{v / m:.0%}")
Read visible_share as the share of your written question list observed in that export, and calculate top 10 share as top10 / mapped. Matching is exact after lowercasing, so wording variations and missing query rows reduce observed coverage.
If your clusters show low visible share and you want the topic map built and shipped, Iron Goo's SEO service is a fit for that implementation work. The useful starting artifact is the gap list produced by your own calculation.
The Performance report's table and export show at most 1,000 rows, and some queries are anonymized for privacy. Both limitations make observed visibility a floor: a missing row does not prove the site never appeared for that question.
For larger datasets, the Search Analytics API accepts rowLimit from 1 to 25,000, defaults to 1,000, and supports pagination with startRow. Request query and page dimensions when you also need to investigate which URL appears; adapt that data into the expected input before using this script.
Say a made-up, 14-person company repairs commercial kitchen refrigeration in one metro area. Its five-cluster map contains 60 questions; a national appliance retailer's competing section contains 12 product category pages.
| Cluster | Mapped | Visible | Top 10 |
|---|---|---|---|
| Walk-in cooler repair | 14 | 11 | 6 |
| Reach-in repair | 12 | 8 | 4 |
| Ice machines | 13 | 9 | 3 |
| Refrigerant rules | 10 | 7 | 5 |
| Maintenance contracts | 11 | 4 | 1 |
| Total | 60 | 39 | 19 |
These are hypothetical coverage numbers, not a measured result. Visible share is 39 / 60 × 100 = 65%; top 10 share is 19 / 60 × 100 = 31.7%, or about 32%.
The plausible opportunity is diagnosis, repair cost, regulatory and contract questions that the retailer's category pages do not answer. That reasoning does not predict a win for “buy reach-in refrigerator.”
How do I check whether pages drift away from the site's topic?
This script builds TF-IDF vectors from page text and compares each with their shared center. Save it as radius.py and pass one plain-text file per URL. It stops with a message if you supply fewer than two pages or if the pages share all their words, leaving nothing to compare.
import math, re, sys
from collections import Counter
from pathlib import Path

# usage: radius.py page1.md page2.md ...   (one file of plain text per URL)
docs = {p: Counter(re.findall(r"[a-z]{3,}", Path(p).read_text().lower())) for p in sys.argv[1:]}
df = Counter(t for c in docs.values() for t in c)
n = len(docs)
if n < 2:
    sys.exit("Pass at least two pages.")

def unit(counts):
    v = {t: (1 + math.log(c)) * math.log(n / df[t]) for t, c in counts.items() if df[t] < n}
    norm = math.sqrt(sum(x * x for x in v.values())) or 1.0
    return {t: x / norm for t, x in v.items()}

vecs = {p: unit(c) for p, c in docs.items()}
centroid = Counter()
for v in vecs.values():
    centroid.update(v)
cnorm = math.sqrt(sum(x * x for x in centroid.values()))
if cnorm == 0:
    sys.exit("The pages share all their words; there is nothing to compare.")

for p, v in sorted(vecs.items(), key=lambda kv: sum(x * centroid[t] for t, x in kv[1].items())):
    sim = sum(x * centroid[t] for t, x in v.items()) / cnorm
    print(f"{1 - sim:.3f}  {p}")  # bigger number = farther from the site's center
Larger distances appear first, but rare specialist vocabulary can push a useful page far from the center. A distant page is a question to investigate, never a verdict about quality or Google's siteRadius.
Use comparable text inputs and inspect the pages behind the numbers. Sentence embeddings can provide a better semantic proxy, but they still cannot reproduce an undisclosed Google metric.
Rerun coverage monthly with consistent filters and record changes to the question list. Use a process for measuring SEO and repairing decline to track cluster visibility and top 10 share over time.
How long does it take to build topical authority?
There is no evidence-backed universal timetable for building topical authority. Google's own guidance on reassessing improved content ranges from a few days to several months, with some sites potentially waiting for the next core update.
That wording describes recognition of improvements, not a promise that a newly published cluster will rank within a particular interval. Google's core update guidance says its systems may need time to confirm that a site produces helpful, reliable content over the long term.
The August 2022 helpful-content announcement similarly described its signal applying over a period of months. That is historical context for a former standalone system, not a current stopwatch.
The frequently repeated six-to-twelve-month estimate has no supporting study in the cited material. Use monthly coverage observations to judge progress without presenting an estimate as a Google requirement.
The leaked hostAge description concerns sandboxing fresh spam at serving time. It does not establish a mandatory waiting period for every new company website.
What did John Mueller say about topical authority?
According to Search Engine Journal's 13 November 2023 report of an undated Reddit exchange, Mueller replied “This” to a comment calling topical authority relevance by another name. SEJ reports that he followed up by saying, “Don't worry about it.”
The reported Mueller exchange does not establish that subject relevance is irrelevant. It supports being cautious about treating an industry label as a separate Google score.
For an actual publishing decision, replace the label with observable questions. Does the page answer something your intended customer asks, does someone qualified verify the answer, and does the surrounding section help that customer resolve related problems?
Keep those answers beside the URL in your topic map. When a proposed article has no real customer question or qualified reviewer, leave it out of the publishing queue.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.