How to build a topical map

On this page
SEO
You have a blank spreadsheet, a Search Console login and forty unconnected blog posts. Here is how to build a topical map: assign each planned URL one query cluster, separate services you sell from questions buyers research, then specify link directions and publishing order. Use three shared top-10 ranking URLs as our starting threshold for grouping queries. Shared results suggest that two searches may express one need; they do not prove it.
A topical map in SEO is that URL ownership plan. Its useful output is a decision about what each page should answer, which existing posts belong together and what gets written next. A spreadsheet containing 400 keywords still needs those decisions.
The running example is Brightline Pest Services, a hypothetical 30-person commercial pest control company serving restaurants, food plants and warehouses in one metro area. Every search volume and planning score used for Brightline is invented for illustration. The company sells recurring contracts, with a site inspection request as the conversion.
Define the business boundary before collecting queries
Step 1: Write one source context sentence
Source context states what the business sells, who buys it, where it operates and what the website should cause a buyer to do. It is a planning constraint, not a Google setting. Put the sentence above the first row of your spreadsheet.
For hypothetical Brightline, use this:
Brightline sells recurring commercial pest control contracts to restaurants,
food plants and warehouses in one metro area; the conversion is a site
inspection request.
Check every existing post against that sentence. Ask whether the page helps someone who could sign that contract, then record the connection in a column called buyer_use. “Gets traffic” does not explain a buyer use.
A restaurant pest inspection checklist passes. Advice about ants in a home garden fails because the audience and purchase differ. Do not delete a failing page automatically: mark it for review, including any useful links or conversions it already receives.
Google's helpful content self-assessment asks whether your site has a primary purpose or focus and flags producing content across many topics in hopes of search traffic. That supports a disciplined boundary. It does not prescribe a particular spreadsheet or page count.
Expected output: One sentence and a buyer-use decision for every existing post.
Bad result: A sentence broad enough to justify any article containing the word pest.
Step 2: Choose the central entity and test the collected vocabulary
The central entity is the subject that connects the map. For hypothetical Brightline, it is commercial pest control; direct types include rodent control, cockroach control and fly control. Keep the business sentence separate: the entity names the subject, while source context identifies the commercial purpose.
Check planned titles by inserting the entity or a direct type naturally. “Commercial pest control logbook template” passes, as does “How rodent control bait stations work.” “Best accounting software for restaurants” shares an audience but fails the subject test.
Our rule of thumb is that at least two thirds of collected queries should contain the entity or a direct type. Count semantically recognizable types, not just exact text matches. If fewer qualify, inspect whether collection drifted or the chosen entity excludes legitimate services.
For an invented 300-query collection, that means at least 200 should pass. Keep excluded queries in a review tab so the boundary remains inspectable. The relationship between subjects and attributes is developed further in entities and their attributes in SEO.
The leaked Content Warehouse API documentation from 2024 contains siteFocusScore, described as “Number denoting how much a site is focused on one topic,” and siteRadius, described as “The measure of how far page_embeddings deviate from the site_embedding.” Those descriptions appear in the leaked topic embeddings model documentation.
The leaked documentation shows that these fields exist. It does not establish their ranking weights or how Google uses them. Treat tighter subject boundaries as a planning judgment, not a promise that pruning pages changes a measurable Google score.
Expected output: One central entity, a short list of direct types and a recorded boundary check.
Bad result: Titles fit only after stretching the entity to mean every problem your audience has.
Step 3: Separate core pages from outer pages
Use an observable test: does the proposed page map to a service, contract or commercial decision the company handles? If yes, place it in the core section. If it answers something a buyer researches while evaluating or managing that service, place it in the outer section.
For hypothetical Brightline, restaurant pest control and warehouse pest control are core pages. Contract pricing also belongs there because it supports buying the contract. A page about mice in a restaurant is outer content when its query cluster calls for practical guidance.
Every outer page must name exactly one parent core page. Assign the mice question to restaurant pest control and bait station guidance to the rodent service page. A topic with no defensible parent returns to the review tab.
Other guides call these pillar and cluster pages. The names matter less than the commercial test and the recorded parent relationship. A long article can still be an outer page.
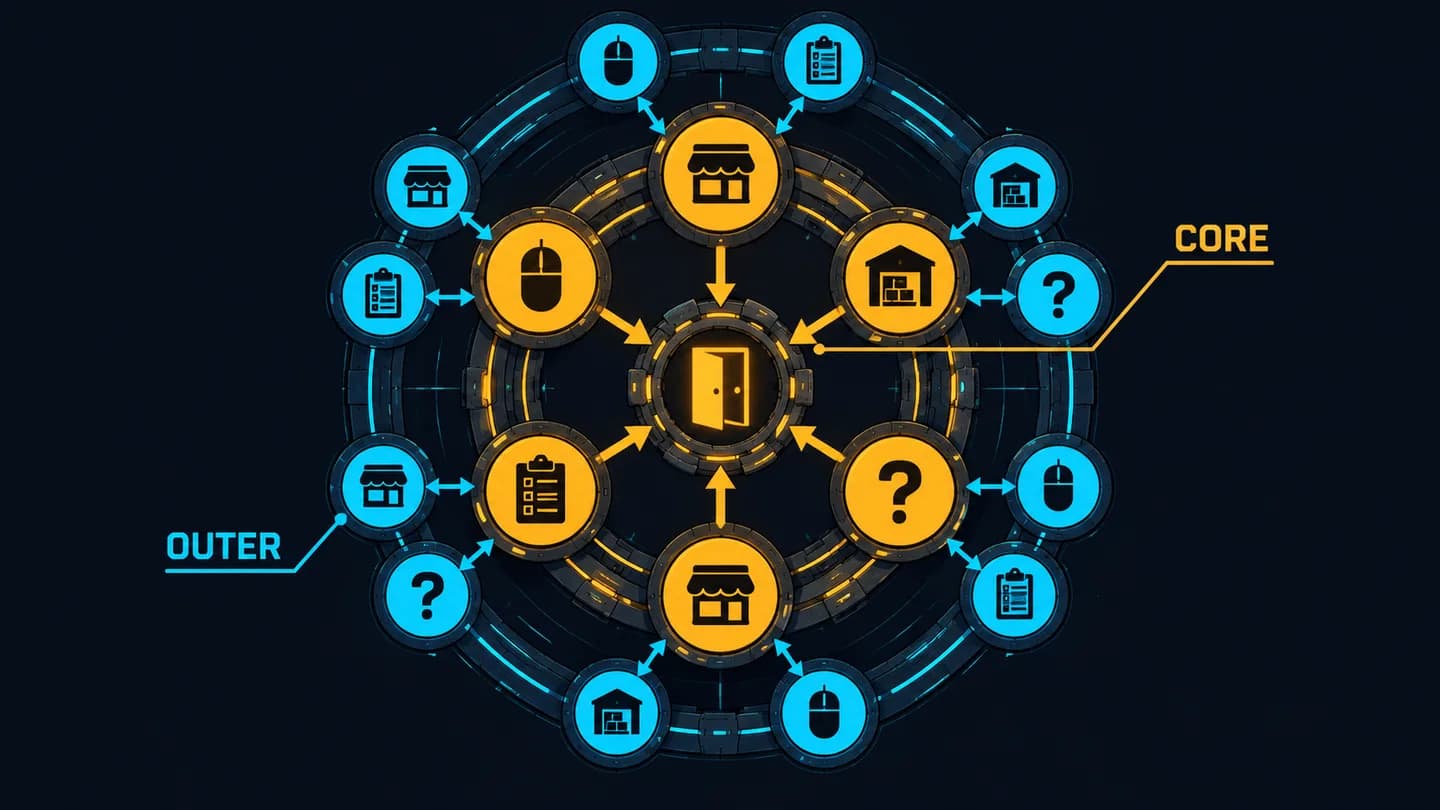
Follow the arrows inward: every outer page has one parent core page. Core pages then connect readers to the inspection request.
Expected output: Every planned page has a core or outer label; every outer page has one parent.
Bad result: Every broad keyword becomes core content, while outer pages have no commercial destination.
Collect queries and turn shared results into page decisions
Step 4: Collect queries with their source limits attached
Open Search Console's Performance report and select Search results. Change the default three-month date range to the full available range, record the dates and search type, then export the Queries tab. Preserve the original export separately from your cleaned sheet.
For question discovery, choose the query filter's Custom (regex) option and enter this RE2 expression:
^(how|what|why|when|which|can|does|is|should)\b
Matching is case-sensitive unless you add (?i) at the beginning. Run an unfiltered export too: the question filter excludes commercial searches such as “restaurant pest control.” It is a collection aid, not a complete definition of buyer research.
| Source | What it gives you | Limit or qualification |
|---|---|---|
| Search Console UI | Queries already earning impressions for your site | Export maximum: 1,000 rows; anonymized queries omitted |
| Search Analytics API | Query data with dimensions such as page and date | Default 1,000 rows; maximum 25,000 per request; ceiling 50,000 rows per day per site per search type; completeness not guaranteed |
| Autocomplete | Search phrasings influenced by language, location and trends | No volume figure; predictions are not an exhaustive query inventory |
| People Also Ask | Related questions, with further questions appearing as you expand answers | No volume figure or complete inventory; record the triggering query |
Google defines anonymized queries as searches not issued by more than a few dozen users over two to three months. Its explanation of Performance data filtering and limits documents both this omission and the export ceilings. For a small site, useful buyer questions may therefore be missing even when the export has fewer than 1,000 rows.
For larger exports, use the API with query and page dimensions, rowLimit set to 25000, and zero-based startRow pagination. The Search Analytics query reference warns that the API returns top rows and does not guarantee all rows. Page each day's request until it returns no rows, while respecting the 50,000 rows per day per site per search type ceiling.
{
  "startDate": "2026-10-01",
  "endDate": "2026-10-01",
  "type": "web",
  "dimensions": ["query", "page"],
  "rowLimit": 25000,
  "startRow": 0
}
Supplement this with autocomplete in the target language and location. Type the entity followed by a space and each letter from a to z, then try question words such as how, what and cost. Google's description of autocomplete supports treating a prediction as evidence that a phrasing is searched, not as a volume estimate.
Expand relevant People Also Ask questions and record their wording verbatim alongside the search that produced them. Some belong as headings inside an existing page; others may justify an outer page after clustering. The box growing on click is not an instruction to publish everything it offers.
For hypothetical Brightline, combine the sources into columns query, source, volume and notes. Deduplicate collection rows by lowercase text and normalized whitespace, retaining multiple source labels where needed. Leave unknown volumes blank; an absent estimate is not zero demand.
Expected output: One deduplicated query sheet with provenance, dates and unknown volumes preserved.
Bad result: A 1,000-row export described as all queries, or autocomplete predictions assigned invented measured volumes.
Step 5: Cluster queries by SERP overlap
Pull the top ten organic results for every query on the same day, using the same location, language and device. Compare ranking URLs, not similar words. Two differently phrased searches can share seven results, while two searches containing the same noun may need separate pages.
Our starting threshold is three shared top-10 URLs against the seed query. Keyword Insights documents a default of three shared URLs; LowFruits documents 40 percent overlap against the highest-volume keyword. With ten results, the latter means four shared URLs, so the defaults differ.
Seed-based clustering compares candidates with one seed, making it order-dependent. All-pairs clustering requires every member to meet the overlap threshold with every other member, producing tighter groups. The script uses the seed-based method so each cluster has a clear proposed target query.
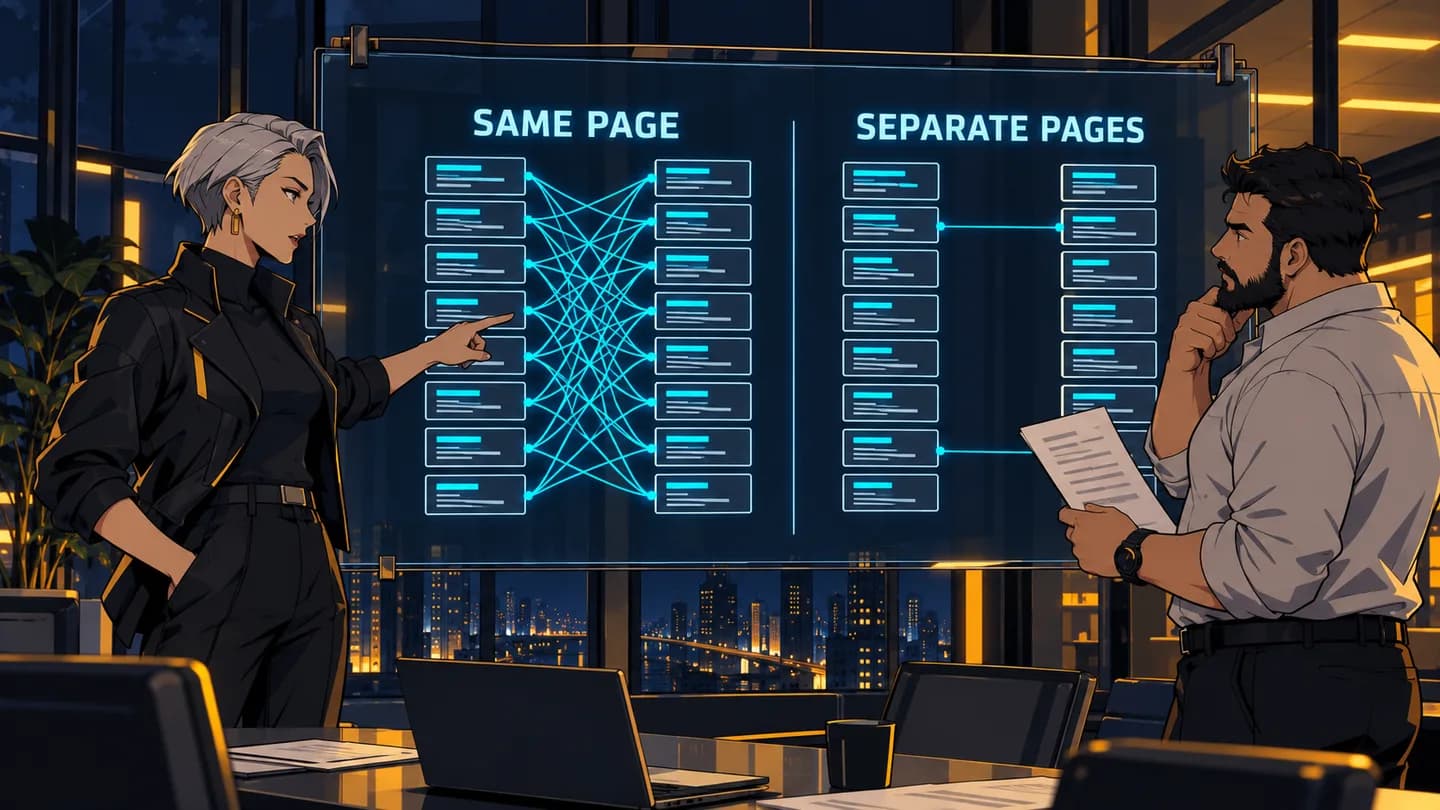
Count shared ranking pages, not matching words in the queries. Many shared results support one URL; sparse overlap calls for separate pages or manual review.
At DataForSEO's Google Organic SERP API prices, read on 24 October 2026, Standard queue costs $0.0006 per SERP, Priority $0.0012 and Live $0.002. One SERP contains up to ten organic results. Location, language and device do not change those prices.
For an openly hypothetical 400-query pull, the Standard calculation is 400 × 1 × $0.0006 = $0.24. Live costs 400 × 1 × $0.002 = $0.80. Those are retrieval costs; someone still has to inspect questionable clusters.
Save one CSV row per ranking URL. These are the exact first lines of the tested example; its full test fixture contains nine keywords and 90 ranking rows. The .example domains are deliberately fake.
keyword,volume,position,url
restaurant pest control,880,1,https://acme-pest.example/restaurants
restaurant pest control,880,2,https://bigchain.example/commercial/restaurants
restaurant pest control,880,3,https://pestnews.example/restaurant-guide
Save the following as serp_clusters.py and run it against your complete CSV. It requires Python 3.9 or later and was tested with Python 3.12.3 on 24 October 2026. The three sample rows illustrate the format; they cannot reproduce the full fixture's output.
#!/usr/bin/env python3
"""Group keywords into page-sized clusters by top-10 SERP overlap.

Input CSV columns: keyword,volume,position,url  (one row per ranking URL)
usage: python3 serp_clusters.py serps.csv --min-shared 3 --ignore-common 0.5
"""
import csv, argparse
from collections import defaultdict
from urllib.parse import urlsplit, parse_qsl, urlencode

DROP = {"ref", "gclid", "fbclid"}

def norm(url):
    p = urlsplit(url.strip())
    host = p.netloc.lower().removeprefix("www.")
    query = sorted((k, v) for k, v in parse_qsl(p.query)
                   if not (k.lower().startswith("utm_") or k.lower() in DROP))
    return host + p.path.rstrip("/") + ("?" + urlencode(query) if query else "")

ap = argparse.ArgumentParser()
ap.add_argument("csv")
ap.add_argument("--min-shared", type=int, default=3)
ap.add_argument("--ignore-common", type=float, default=0.5)
a = ap.parse_args()

serps, volume = defaultdict(set), {}
for row in csv.DictReader(open(a.csv, newline="", encoding="utf-8")):
    if int(row["position"]) <= 10:
        serps[row["keyword"]].add(norm(row["url"]))
        v = row["volume"].strip()
        volume.setdefault(row["keyword"], int(v) if v else None)  # blank = unknown

# URLs that rank for a large share of all keywords (directories, big encyclopedias)
# say little about intent, so they are dropped before comparing.
seen = defaultdict(int)
for urls in serps.values():
    for u in urls:
        seen[u] += 1
common = {u for u, n in seen.items() if n / len(serps) > a.ignore_common}

clusters, assigned = [], set()
# Seeds: known volumes, highest first; unknown volumes last, in first-seen order.
order = sorted(serps, key=lambda k: (volume[k] is None, -(volume[k] or 0)))
for seed in order:
    if seed in assigned:
        continue
    base = serps[seed] - common
    members = [seed] + [k for k in order if k not in assigned and k != seed
                        and len(base & (serps[k] - common)) >= a.min_shared]
    assigned.update(members)
    clusters.append(members)

print(f"ignored as too common: {sorted(common) or 'none'}")
for i, members in enumerate(clusters, 1):
    known = [volume[k] for k in members if volume[k] is not None]
    unknown = len(members) - len(known)
    note = f", {unknown} unknown" if unknown else ""
    print(f"cluster {i}: {members[0]}  [{len(members)} kw, {sum(known)}/mo{note}]")
    for k in members[1:]:
        shared = len((serps[members[0]] - common) & (serps[k] - common))
        print(f"    {k}  [{shared} shared]")
Normalization prevents tracking variants from masquerading as different pages. Only the scheme and host are case-normalized, and the scheme is then omitted from the comparison key; the host loses a leading www.. Paths and query values stay case-sensitive, with trailing path slashes removed.
Parameter names are matched case-insensitively when dropping utm_*, ref, gclid and fbclid. Other parameters remain and are sorted, so ?a=1&b=2 matches ?b=2&a=1. Keeping meaningful parameters prevents different resources from collapsing into one URL.
Known volumes determine seed order, highest first. Blank volumes remain unknown and come last in first-seen CSV order; a cluster with one unknown-volume keyword can print [1 kw, 0/mo, 1 unknown]. The displayed zero is a known-volume subtotal, not an estimate for that keyword.
Run python3 serp_clusters.py serps.csv against the full test fixture. Its exact output is:
ignored as too common: ['citypages.example/pest-control']
cluster 1: restaurant pest control  [3 kw, 1440/mo]
    pest control for restaurants  [7 shared]
    commercial kitchen pest control  [5 shared]
cluster 2: warehouse pest control  [2 kw, 430/mo]
    pest control for warehouses  [7 shared]
cluster 3: rodent control for business  [2 kw, 470/mo]
    commercial rodent control  [7 shared]
cluster 4: commercial pest control contract cost  [1 kw, 170/mo]
cluster 5: how to get rid of mice in a restaurant  [1 kw, 140/mo]
Run python3 serp_clusters.py serps.csv --ignore-common 1.0 to disable common-URL removal. The exact output becomes:
ignored as too common: none
cluster 1: restaurant pest control  [4 kw, 1580/mo]
    pest control for restaurants  [8 shared]
    commercial kitchen pest control  [6 shared]
    how to get rid of mice in a restaurant  [3 shared]
cluster 2: warehouse pest control  [2 kw, 430/mo]
    pest control for warehouses  [7 shared]
cluster 3: rodent control for business  [2 kw, 470/mo]
    commercial rodent control  [7 shared]
cluster 4: commercial pest control contract cost  [1 kw, 170/mo]
The directory URL appears in six of nine SERPs, about 67 percent. Counting it pushes the mice question from two shared results to three, merging practical guidance into a service cluster. Removing it preserves the question as a separate outer-page candidate.
Review every pair at two shared results manually. Our tie-break rule is to merge when the top three results in both SERPs consistently share the same page type, such as service pages; otherwise split. Inspect removed common URLs too, because popularity alone does not make a result irrelevant.
Expected output: Mostly small clusters, often one to six queries, whose members describe one need.
Bad result: A giant cluster consumes a third of the list, or nearly every query stands alone without a clear intent difference.
Step 6: Assign each reviewed cluster to one URL
Use one cluster per URL, with its seed naming the proposed URL and title. Other members become headings or natural phrasings on that page. For hypothetical Brightline, “commercial kitchen pest control” shares five filtered results with the restaurant seed, so it becomes material on the restaurant service page.
The rodent seed is “rodent control for business,” because the invented volumes put it ahead of “commercial rodent control.” Preserve that decision in the ledger even if editorial wording later changes. Cluster subtotals are planning estimates, not guaranteed incremental traffic.
Merge existing pages when their main queries form one reviewed cluster and no separate buyer need remains. Split when a distinct attribute combination has its own cluster and demand. A different keyword spelling alone does not justify another URL.
For cannibalization review, group the query-plus-page export by query and flag queries receiving impressions on two or more URLs. Inspect those pages' main queries and SERP overlap before acting: multiple visible pages are a diagnostic signal, not an automatic error. Record keep, merge_into or split for each affected URL.
Expected output: One owner URL per reviewed cluster and explicit decisions for overlapping existing posts.
Bad result: Separate pages target restaurant pest control and pest control for restaurants despite seven shared results.
Specify links and publish complete commercial blocks
Step 7: Record link directions before drafting
Give each outer page a contextual link to its named parent core page. Each core page should link to the inspection request, with anchor wording that identifies the destination. For hypothetical Brightline, the mice article links to restaurant pest control, which links to the inspection form.
Add sibling links only within a cluster and only when they help the reader continue the task. Because one cluster normally owns one URL, these will often be section links within that page; do not create extra sibling URLs merely to populate a diagram. The outer article's main structural relationship remains its parent.
Use about three contextual links per page as a working cap, then judge each link's usefulness. This is a practitioner planning constraint, not a Google number. Google's crawlable links guidance recommends at least one inbound link from another site page for every page you care about and says there is no magical ideal link count.
Check the rendered pages after publication. Confirm that planned links exist as crawlable anchors, resolve successfully and point to the intended canonical destinations. Use the internal linking architecture audit for the PageRank explanation and a fuller inspection method.
Expected output: A link ledger with source URL, destination URL, anchor purpose and a verified inbound link for every mapped page.
Bad result: Outer pages lack parent links, or every page links to every other page regardless of task.
Step 8: Score business value and winnability, then assign blocks
Our prioritization rule is business value × winnability. Score the proposed page's role and the actual top ten results separately. Record the supporting observation beside each number so another person can repeat the judgment.
| Score | Business value | Winnability |
|---|---|---|
| 3 | Directly sells a contract | At least three top-ten results are small or independent business sites |
| 2 | Supports a core page | One or two top-ten results are small or independent business sites |
| 1 | Awareness only | No top-ten results are small or independent business sites, whatever the other results are |
Hypothetical Brightline's restaurant service page scores 3 × 3 = 9, assuming three qualifying business sites in its invented SERP assessment. Its mice article could score 2 × 3 = 6. Keep the inspected result URLs and observation date with the scores; a number without evidence is spreadsheet decoration.
Publish each core page in the same block as its outer pages. Put contract pricing in the restaurant block because it helps the purchase decision, even though its standalone score might place it elsewhere. Operational dependencies can override descending score order.
Publishing support before or alongside a competitive head-query page reflects practitioner consensus, not an established A/B result. The commercial page still needs to exist when buyers arrive. Interpret “head query later” as sequencing investment and expectations, not withholding the purchase route.
Expected output: Evidence-backed scores and publishing blocks containing each core page with its support.
Bad result: The highest-volume keyword consumes the budget while supporting pages remain undrafted.
If you want the map built and the pages shipped with internal linking and schema, Iron Goo's SEO service connects those tasks. The intended benefit is focused coverage buyers can use; topical authority for a company website explains that objective without treating page count as a ranking guarantee.
Finished Brightline map and the six-month review trigger
This is the hypothetical Brightline map after clustering and editorial review. Rows marked as proposed need their own SERP checks before drafting; only the five clusters in the script output have demonstrated overlap here. Paths are proposed website paths, not existing pages.
| URL | Section | Seed query | Member queries | Parent core page | Block |
|---|---|---|---|---|---|
/restaurant-pest-control/ | Core | restaurant pest control | pest control for restaurants; commercial kitchen pest control | Self | 1 |
/commercial-pest-control-contract-cost/ | Core | commercial pest control contract cost | None in test | Self | 1 |
/guides/mice-in-restaurants/ | Outer | how to get rid of mice in a restaurant | None after filtering | /restaurant-pest-control/ | 1 |
/guides/restaurant-pest-inspections/ | Outer | what a health inspector checks for pests | Proposed; validate | /restaurant-pest-control/ | 1 |
/rodent-control-for-business/ | Core | rodent control for business | commercial rodent control | Self | 2 |
/guides/commercial-bait-stations/ | Outer | how bait stations work | Proposed; validate | /rodent-control-for-business/ | 2 |
/guides/signs-of-commercial-rodents/ | Outer | signs of rodents in commercial premises | Proposed; validate | /rodent-control-for-business/ | 2 |
/warehouse-pest-control/ | Core | warehouse pest control | pest control for warehouses | Self | 3 |
/guides/warehouse-pest-prevention/ | Outer | warehouse pest prevention | Proposed; validate | /warehouse-pest-control/ | 3 |
/food-plant-pest-control/ | Core | food plant pest control | Proposed; validate | Self | 4 |
/guides/pest-control-logbook/ | Outer | pest control logbook template | Proposed; validate | /food-plant-pest-control/ | 4 |
Set a six-month re-audit date as a practitioner working cadence. Repeat the query-plus-page export and refresh SERPs using consistent collection settings, then compare cluster membership and page types. Review earlier if several URLs in a cluster lose visibility or its queries begin appearing against competing site pages.
Repair the cluster as a unit: inspect its core page, outer pages and links together. Record whether the cause calls for refreshed content, a merge or a split, then update ownership and link destinations in the map before changing the pages.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.