Crawl budget: verify the bots, then fix the right problem

On this page
- Establish whether crawl capacity is actually the constraint
- Verify crawler identities before calculating anything
- Read Search Console as a diagnosis, not a score
- Test the HTML and the rendering path
- Correct response codes and control URL inventory
- Maintain discovery signals and change notifications
- Separate AI training, search and user-requested fetching
- Remove obsolete settings and keep the limits nearby
SEO
Our reading of Google's guidance is that crawl budget is rarely the constraint on sites under roughly 10,000 pages, although Google sets no minimum size below which it never matters. Crawl budget is how much crawling Google can and wants to do: server capacity supplies one limit, crawl demand supplies another. Google's guidance primarily addresses million-page sites changing weekly or sites of 10,000 or more pages changing daily. For most sites, Google says an accurate sitemap and regular checks of the Page Indexing report are adequate.
That distinction changes your work order. A fast server receiving few Googlebot visits needs a different investigation from a server returning overload errors, and neither investigation works if half your supposed Googlebot traffic is an impostor.
Establish whether crawl capacity is actually the constraint
Check 1: Match your site to Google's site-size descriptions
Count unique URLs you actually want indexed, then estimate how frequently their substantive content changes. Google's crawl-budget guidance describes large sites with about one million or more unique pages changing moderately often, roughly weekly, and medium or larger sites with 10,000 or more unique pages changing rapidly, roughly daily. These are rough site descriptions, not counts of URLs you must update each day.
Google also includes sites with a large share of URLs marked Discovered - currently not indexed. A 400-page company site can therefore need investigation, even though enterprise crawl-budget tactics are unlikely to be its first useful intervention.
Separate the two limits before changing anything:
| Limit | What determines it | Evidence to inspect |
|---|---|---|
| Crawl capacity | How much connection time your server can reliably provide | Response times, connectivity failures, 5xx and 429 responses |
| Crawl demand | Google's perceived URL inventory, popularity and staleness | Discovery, internal links, duplicates and which pages receive repeat visits |
Our own irongoo.com logs illustrate the distinction. Across about 14.8 days, from 9 to 23 October 2026, there were 369 verified Google crawler requests, including 98 Googlebot-Image requests. Web Googlebot alone made 271 requests, about 18 a day; approximately half were requests for robots.txt.
Verified Googlebot fetched 54 of 389 sitemap URLs, about 14%, during that window. A separate homepage measurement on 23 October 2026 returned a time to first byte of about 0.12 seconds. This combination suggests limited crawl demand, although one response-time measurement cannot rule out intermittent server trouble.
A quick response does not create demand for another page. Read the response time alongside verified crawl volume and sitemap coverage before assigning work to infrastructure.
Good result: You can distinguish a healthy server receiving little crawling from a server actively slowing Google down. Bad result: The only diagnosis is a low daily request count, with no status-code or connectivity evidence.
Verify crawler identities before calculating anything
Check 2: Match Googlebot IPs against the published ranges
Filter requests by user agent to produce candidates, then verify their source IPs. In our logs, 813 requests carried a Googlebot user agent; 444, about 55%, failed the published common-crawler range check. Of those impostor requests, 361 came from Google Cloud VMs with forward-confirming names ending in bc.googleusercontent.com.
The trap is in Google's generic reverse-DNS instructions: they accept googlebot.com, google.com or googleusercontent.com. Following those steps literally lets these Google Cloud VMs through. The same page's narrower common-crawler masks are crawl-***-***-***-***.googlebot.com and geo-crawl-***-***-***-***.geo.googlebot.com; use the published IP ranges or those narrower masks when identifying common Google crawlers.
This standard-library script accepts candidate IPs as command-line arguments:
import ipaddress
import json
import sys
import urllib.request

url = "https://developers.google.com/static/crawling/ipranges/common-crawlers.json"
with urllib.request.urlopen(url, timeout=20) as response:
    data = json.load(response)

networks = [
    ipaddress.ip_network(p.get("ipv4Prefix") or p["ipv6Prefix"])
    for p in data["prefixes"]
]

for candidate in sys.argv[1:]:
    address = ipaddress.ip_address(candidate)
    verified = any(address in network for network in networks)
    print(candidate, "verified" if verified else "unverified")
Download the range file once per analysis run, retain its timestamp, and apply it to every candidate address. This checks membership against the current list; it is not proof of historical membership months earlier.
All verified Googlebot requests in our window came from addresses between 192.178.4.32 and 192.178.4.38. None came from 66.249.x.x, although those ranges remain in Google's current list. Familiar-looking addresses are a poor verification method.
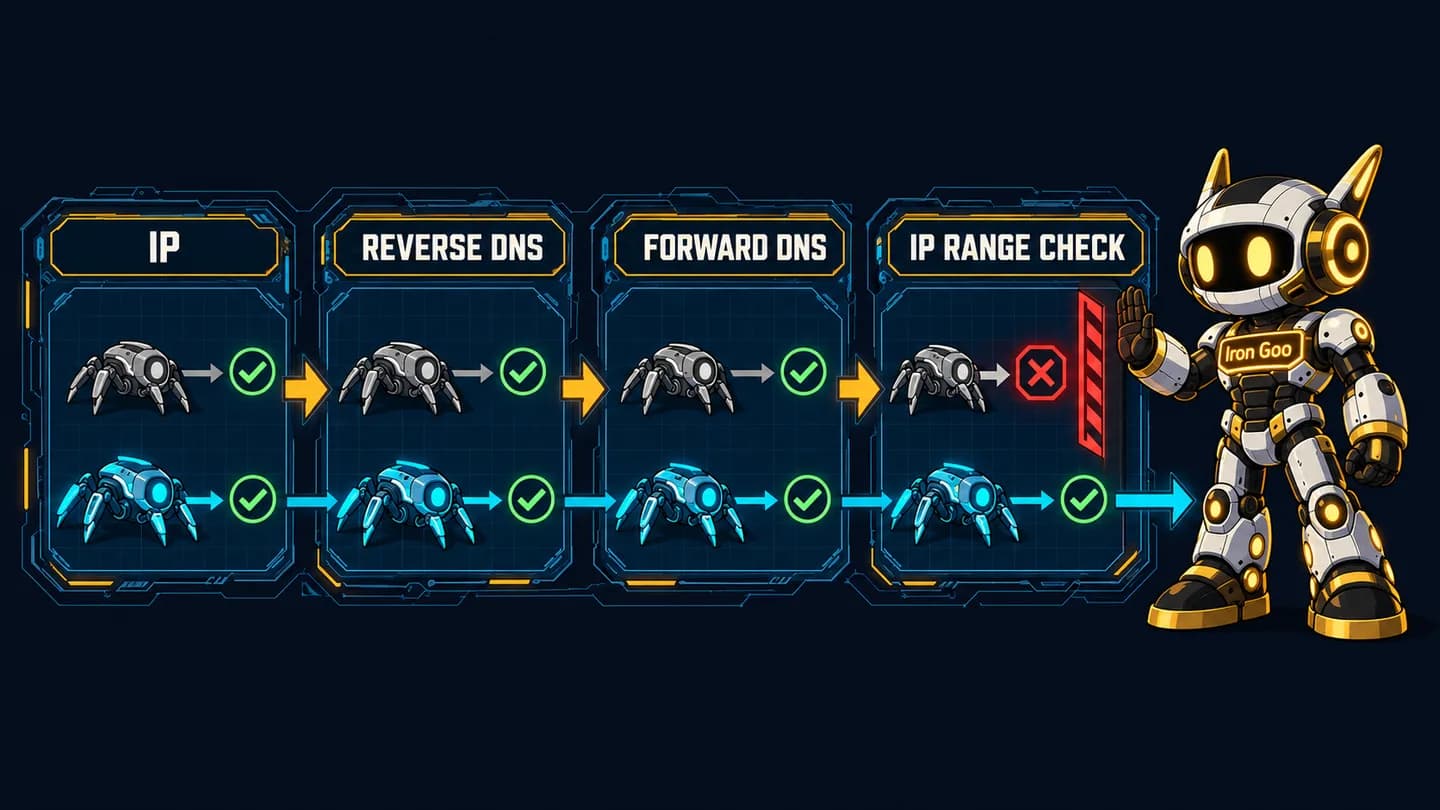
A forward-confirming Google-owned hostname identifies infrastructure ownership. Matching the common-crawler ranges distinguishes the documented crawler infrastructure from a rented Google Cloud VM.
Good result: Every request counted as Googlebot passes the appropriate operator range check. Bad result: A user-agent string or broad googleusercontent.com suffix is the entire verification process.
Check 3: Read verified log records and calculate useful totals
These are two real records from our own nginx access logs. The source address belongs to Google's documented crawler ranges, so it remains visible here:
192.178.4.38 - - [22/Oct/2026:10:00:05 +0000] "GET / HTTP/1.1" 200 13540 "-" "Mozilla/5.0 (Linux; Android 6.0.1; Nexus 5X Build/MMB29P) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/153.0.8010.52 Mobile Safari/537.36 (compatible; Googlebot/2.1; +http://www.google.com/bot.html)"
192.178.4.38 - - [22/Oct/2026:10:00:07 +0000] "GET /_next/static/chunks/d1bf37cc5b8a6bfe.css HTTP/1.1" 200 12901 "https://irongoo.com/" "Mozilla/5.0 (Linux; Android 6.0.1; Nexus 5X Build/MMB29P) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/153.0.8010.52 Mobile Safari/537.36 (compatible; Googlebot/2.1; +http://www.google.com/bot.html)"
Read the fields as follows:
| Field | First record | Interpretation |
|---|---|---|
| Client IP | 192.178.4.38 | Address to verify |
| Ident and authenticated user | Both unset | No supplied identity |
| Time | 22/Oct/2026:10:00:05 +0000 | Request timestamp with UTC offset |
| Request | GET / HTTP/1.1 | Method, requested path and protocol |
| Status | 200 | Successful HTTP response |
| Body bytes | 13540 | Logged response-body size |
| Referer | Unset | No referring URL supplied |
| User agent | Googlebot with Chrome/153 | Claimed identity, requiring verification |
The second record requests CSS two seconds later and supplies the homepage as its Referer. That is consistent with rendering-related resource fetching; it does not prove every part of the page rendered successfully.
Write verified web Googlebot records to a separate file before using simple summaries:
# Input contains only range-verified web Googlebot records.
awk -F'"' '{split($3,a," "); print a[1]}' verified-web.log |
  sort | uniq -c

awk '{print $7}' verified-web.log | sort | uniq -c | sort -nr

awk '{print $7}' verified-web.log |
  awk 'index($0, "?") {n++} END {print n+0}'
Calculate sitemap coverage from distinct matching page URLs, excluding resources and repeated visits: 54 / 389 × 100 = 13.9% in our window. A high robots.txt share can simply mean little other crawling occurred; it is not evidence that robots fetching needs suppression.
Good result: Your totals distinguish page visits, resources, robots checks and repeat requests. Bad result: Scanner requests for secret configuration files dominate a chart labeled Googlebot errors.
Read Search Console as a diagnosis, not a score
Check 4: Inspect Crawl Stats fields together
Open Settings → Crawl stats in a root-level Search Console property. Google's Crawl Stats help says sites with fewer than about 1,000 pages should not need this report. Use it when an indexing problem or server symptom gives you a specific question.
| Field or breakdown | Exact check | Investigate when |
|---|---|---|
| Total crawl requests | Compare daily volume with publishing and deployments | Requests fall alongside errors or slower responses |
| Total download size | Compare bytes with request volume | Similar request counts transfer substantially more data |
| Average response time | Inspect trends, then individual endpoints in logs | Response time rises while crawling falls |
| Host status | Open robots.txt, DNS and server-connectivity details | Any recent fetch or connectivity failure appears |
| By response | Separate 200/304, redirects, 404, 429 and 5xx | Overload errors recur or redirect failures grow |
| By file type | Compare HTML with script and other resources | Resource fetching grows without corresponding page discovery |
| By purpose | Compare Discovery with Refresh | New publishing produces little discovery |
| By Googlebot type | Separate Smartphone, Image and Page resource load | Resource fetching explains an apparent page-crawl increase |
Host status distinguishes no problems in the past 90 days, problems more than a week ago, and problems within the past week. Google's DNS example flags more than 5% failed requests on a day. Example URLs are sampled, so use logs for complete counts.
There is no universal healthy percentage for Discovery or JavaScript requests. An established site with unchanged content may reasonably receive mostly Refresh visits, while a new release can temporarily require many resource requests.
To increase crawl rate, first remove recurring 5xx and 429 responses and fix slow endpoints. When those checks are clean, improve discovery and eliminate redundant inventory; a higher request count is not itself a ranking benefit.
Good result: You can connect a crawl change to response behavior, resource fetching or discovery. Bad result: You interpret the request chart alone as Google's opinion of the entire site.
Check 5: Diagnose the two currently not indexed states separately
Discovered - currently not indexed means Google knows the URL but has not crawled it. Google's Page Indexing help says this typically happens when crawling was expected to overload the site, so Google rescheduled the fetch and left the last-crawl date empty.
Check host status and overload responses first. If those are clean, inspect links from already crawled pages, click depth and repetitive templates; Google's public commentary has also associated persistent discovery problems with thin-content patterns. Use internal linking architecture to give valuable pages direct discovery paths from relevant, established pages.
Crawled - currently not indexed means Google fetched the URL but has not indexed it. Google says it may or may not index the page later and that resubmitting it for crawling is unnecessary.
Inspect the Google-selected canonical in URL Inspection first. If another URL represents the same content, decide whether to consolidate; if the page deserves separate indexing, make its purpose and substantive content distinct.
Sample by template because example tables stop at 1,000 rows. Validation typically takes up to about two weeks, which is a report-processing expectation, not a promise that edited pages will enter the index.
Good result: Discovered URLs receive capacity and discovery checks; crawled URLs receive canonical and content checks. Bad result: Every excluded URL gets another indexing request without a diagnosed change.
Test the HTML and the rendering path
Check 6: Fetch the page without executing JavaScript
Save the initial response body and headers, then search for a distinctive sentence from the main content. curl does not execute JavaScript, so this isolates what a non-rendering fetcher receives.
curl -sS --compressed \
  -D /tmp/page-headers.txt \
  -o /tmp/page.html \
  https://example.com/page

rg -F 'A distinctive sentence from the main content' /tmp/page.html
wc -c /tmp/page.html /tmp/page-headers.txt
grep -bo 'rel="canonical"' /tmp/page.html | head -1
grep -bo '<h1' /tmp/page.html | head -1
Inspect where the match appears. A sentence embedded only inside serialized script data is different from readable article markup containing paragraphs and links. Changing the user agent does not reproduce an assistant's fetching pipeline.
Google does render JavaScript. Its documented process separates crawling, rendering and indexing; a page can wait in the rendering queue, and non-200 responses may skip rendering. An initial noindex can also prevent execution, so removing it with JavaScript is unreliable.
The Vercel and MERJ study, published on 31 July 2024 using April data, examined more than 100,000 Googlebot fetches on nextjs.org, with supplemental data from monogram.io and basement.io. Its matched dataset comprised over 37,000 fetch/render pairs on nextjs.org; 100 percent of the HTML pages in that analysis resulted in full-page renders, with these delays:
| Percentile | Crawl-to-render delay |
|---|---|
| 25th | At most 4 seconds |
| 50th | 10 seconds |
| 75th | 26 seconds |
| 90th | About 3 hours |
| 95th | About 6 hours |
| 99th | About 18 hours |
Query-string URLs had a slower tail: about 31 minutes at the 75th percentile and 8.5 hours at the 90th. These are observations, not a Google service guarantee.
A separate Onely experiment from 2022 reportedly reached the seventh JavaScript-linked page after about 313 hours, compared with 36 hours through HTML links. It used a fresh test subdomain; the Vercel sample included a highly popular domain. My reading is that demand and discovery conditions help explain the difference, although those experiments do not isolate every cause.
Good result: Main content and usable links exist in the initial HTML, with rendering adding functionality. Bad result: Essential text appears only after interaction, stored browser state or a successful client-side request.
Check 7: Locate important content before Google's byte cutoff
Googlebot's text-fetch limit is 2MB of uncompressed data, including HTTP headers. Google's fetch-limit explanation says the response is truncated and passed to indexing systems and the Web Rendering Service as though complete. A successful 200 does not prove Google received the entire document.
Use the saved body to locate content near the end:
python3 - <<'PY'
from pathlib import Path

body = Path("/tmp/page.html").read_bytes()
headers = Path("/tmp/page-headers.txt").read_bytes()
print("Body bytes:", len(body))
print("Saved header bytes:", len(headers))

for marker in (b'rel="canonical"', b"<h1", b"A sentence near the end"):
    print(marker.decode(), "body offset:", body.find(marker))
PY
The saved headers provide a practical check, although intermediaries can produce a different response for Google. Allow headroom and test important content positions, not just total transfer size.
One of our guide pages measured on 23 October 2026 contained 182,267 uncompressed HTML bytes, compared with 28,140 bytes under Brotli compression. Inline scripts occupied 100,681 bytes, about 55%; the canonical appeared at byte 2,679 and the H1 at byte 21,750. Those are measurements of that page's previous version, not measurements of the document you are reading.
Each referenced resource has its own byte counter. Keep metadata and essential structured data in the HTML template near the beginning, while avoiding needless duplication of article content in inline payloads.
Good result: Essential metadata and article content fit comfortably within the uncompressed fetch allowance. Bad result: Your size check reports compressed transfer bytes while important content sits beyond the text cutoff.
Correct response codes and control URL inventory
Check 8: Test real pages, missing pages and retired URLs
Request one known page, one invented path and one retired URL. Check both status and body, because a convincing error message delivered with 200 can become a soft 404.
curl -sS -o /tmp/known.html -w '%{http_code}\n' \
  https://example.com/known-page

curl -sS -o /tmp/missing.html -w '%{http_code}\n' \
  https://example.com/nonexistent-audit-path

curl -sS -L -o /dev/null \
  -w 'status=%{http_code} redirects=%{num_redirects}\n' \
  https://example.com/retired-page
Return 404 or 410 for genuinely removed content; Google treats those statuses alike. Redirect to a relevant replacement when one exists, using 301 or 308 for a permanent move. Google may treat unrelated redirects to the homepage as soft 404s.
Inspect empty templates too. A valid service page needs substantive content; a nonexistent product combination should return 404, not a successful empty catalog shell.
Content available only through client-side JavaScript, incorrect status codes and parameter junk generated by an old CMS usually require template or infrastructure work. Those are concrete reasons to commission a website foundation rebuild.
Good result: Existing pages return useful content with 200, missing pages return 404 or 410, and permanent moves reach relevant replacements. Bad result: Every path returns the same successful shell or redirects to the homepage.
Check 9: Choose robots.txt, noindex or canonical by the intended outcome
Use noindex to exclude a crawlable page from indexing. Use robots.txt to prevent crawling of unwanted URL spaces, and use redirects or canonical annotations to consolidate duplicates.
| Goal | Control | Observable check |
|---|---|---|
| Exclude a page from indexing | Crawlable noindex | Google can fetch and read the directive |
| Exclude a PDF from indexing | X-Robots-Tag: noindex | Response header contains the directive |
| Suppress facet crawling | robots.txt rules | Representative parameter URLs match the intended rules |
| Consolidate duplicates | Redirect or rel="canonical" | Target is consistent across links and sitemap |
| Remove nonexistent content | 404 or 410 | HTTP status matches the page state |
A robots block prevents Google from reading a page's noindex; the URL may still appear in search without its content. A canonical is a consolidation signal and does not prevent the fetch.
This robots.txt example is adapted from Google's faceted-navigation example, with a general user-agent group and sitemap declaration:
User-agent: *
Disallow: /*?*products=
Disallow: /*?*color=
Disallow: /*?*size=
Allow: /*?products=all$

Sitemap: https://example.com/sitemap.xml
Test URLs with parameters in different orders and combinations. If filtered pages deserve indexing, keep filter ordering consistent, use & separators and return 404 for zero-result combinations.
Good result: Each URL class has a defined indexing or crawling policy that matches its directives. Bad result: Important pages are simultaneously blocked, marked noindex and listed as preferred sitemap URLs.
Maintain discovery signals and change notifications
Check 10: Verify sitemap contents and lastmod accuracy
Compare sitemap URLs against final response codes, canonical targets and intended indexability. Remove redirected URLs and excluded pages, then inspect several <lastmod> values against actual substantive edits.
Google uses <lastmod> when it is consistently and verifiably accurate. Generating the sitemap today does not mean every page changed today, and a copyright-date update is not a significant content change.
<url>
  <loc>https://example.com/service-page</loc>
  <lastmod>2026-10-21</lastmod>
</url>
That date is a hypothetical example: it belongs there only if the page materially changed on 21 October 2026. Google ignores <priority> and <changefreq>, so spending time tuning those fields produces no Google scheduling benefit.
Good result: Sitemap entries resolve to preferred indexable pages and dates correspond to real changes. Bad result: Every URL receives the generation timestamp, including pages untouched for months.
Check 11: Use IndexNow for participating engines
Google does not appear among IndexNow participants, so an accepted notification is not a Google indexing request. Use IndexNow to notify participating engines, including Bing, when URLs change.
Host the ownership key, then send changed URLs in a JSON request. The endpoint accepts batches of up to 10,000 URLs; the key must contain 8 to 128 permitted characters.
curl -sS -i https://api.indexnow.org/indexnow \
  -H 'Content-Type: application/json; charset=utf-8' \
  --data '{
    "host": "example.com",
    "key": "replace-with-your-valid-key",
    "keyLocation": "https://example.com/replace-with-your-valid-key.txt",
    "urlList": ["https://example.com/changed-page"]
  }'
A 200 is successful receipt; 202 is accepted with key validation pending. A 429 indicates rate limiting or potential spam, not a successful notification.
The IndexNow FAQ advises avoiding repeat submissions of the same URL within five minutes. After 429, check Retry-After and wait at least ten minutes before resubmitting that URL. Submission never guarantees indexing.
Good result: Real changes produce accepted submissions with a working ownership key. Bad result: A scheduled job repeatedly resends the entire site or treats IndexNow as a Google submission API.
Separate AI training, search and user-requested fetching
Check 12: Set policy per agent and test readable content
AI crawler names describe different purposes. A training opt-out and search visibility are separate decisions, while user-requested fetching can follow different robots behavior.
| Operator | Training | Search | User-triggered |
|---|---|---|---|
| OpenAI | GPTBot | OAI-SearchBot | ChatGPT-User |
| Anthropic | ClaudeBot | Claude-SearchBot | Claude-User |
| Perplexity | PerplexityBot is described as search, not foundation-model training | PerplexityBot | Perplexity-User |
OpenAI's bot documentation separates these agents and also lists OAI-AdsBot for advertising landing-page checks. It says robots rules may not apply to ChatGPT-User; Perplexity similarly says its user agent generally ignores robots rules for user-requested fetches. Anthropic says its agents honor robots.txt and respect Crawl-delay where appropriate.
Google-Extended is a robots.txt control token, with no separate HTTP user agent. It controls Gemini training and grounding, so blocking it declines a search-like use as well as training; Google says the token does not affect Google Search inclusion or ranking.
For a policy that declines OpenAI training and Gemini training/grounding while allowing OpenAI search:
User-agent: GPTBot
Disallow: /

User-agent: OAI-SearchBot
Allow: /

User-agent: Google-Extended
Disallow: /
Keep useful content in server HTML despite changing rendering capabilities. Vercel's December 2024 network study observed no JavaScript execution by the examined OpenAI, Anthropic or Perplexity crawlers, although some fetched JavaScript files. A separate controlled test reported in August 2026 also found several major assistants returning a raw-HTML decoy over a JavaScript-only value.
Our own verified logs complicate the absolute claim that they never execute JavaScript. OAI-SearchBot made 447 ?_rsc= requests out of 578 verified requests; GPTBot made 35 and ClaudeBot 93. These Next.js client-router prefetch URLs were absent from the HTML.
My inference is that some fetch paths now execute page JavaScript, potentially using cached assets. This is a single-site observation, not proof of dependable rendering across those agents.
Verification remains necessary: all 394 requests claiming Claude-User or Claude-SearchBot and all 177 claiming Perplexity-User failed verification in our window. If you want assistants to retrieve and cite your material deliberately, AI search visibility work should connect crawler policy with readable pages and citation checks.
Good result: Policy distinguishes training, search and user fetches, with content readable without rendering. Bad result: One blanket bot rule expresses several incompatible goals, and unverified user agents supply your evidence.
Remove obsolete settings and keep the limits nearby
Check 13: Delete retired controls from the audit checklist
Search implementation notes and scheduled jobs for obsolete crawl controls. The Search Console crawl-rate limiter was retired on 8 January 2024, and the URL Parameters tool was retired in 2022. Google's sitemap ping endpoint was deprecated in June 2023 and now returns 404.
Google ignores crawl-delay; it supports user-agent, allow, disallow and sitemap in robots.txt. Google also revised its resource-hosting advice on 6 December 2024 to discourage moving critical JavaScript or CSS to another hostname solely to shift crawling, because extra connections can hurt performance.
For genuine overload, temporary 503 or 429 responses with Retry-After can slow Google down. Reserve this for operational protection: prolonged errors can reduce crawling and remove URLs from the index.
Good result: Every operational control maps to a supported behavior. Bad result: Your recovery plan depends on a missing Search Console setting or a robots directive Google ignores.
| Limit or behavior | Current reference | Date checked |
|---|---|---|
| Googlebot HTML and supported text fetch | First 2MB uncompressed, including headers; excess truncated | 23 October 2026 |
| Googlebot PDF fetch | 64MB | 23 October 2026 |
| Crawlers without a specific fetch limit | Default 15MB | 23 October 2026 |
| Referenced resources | Separate per-URL byte counters | 23 October 2026 |
| General web redirect following | Up to 10 hops | 23 October 2026 |
| robots.txt size | 500 KiB; excess ignored | 23 October 2026 |
| Normal robots.txt caching | Usually up to 24 hours | 23 October 2026 |
| robots.txt server errors | Initial 12-hour crawl pause; last good copy usable for up to 30 days | 23 October 2026 |
| Web Rendering Service resource cache | JavaScript and CSS may remain cached for up to 30 days | 23 October 2026 |
| Sitemap file | Up to 50,000 URLs or 50MB uncompressed | 23 October 2026 |
| Page Indexing example table | Up to 1,000 rows | 23 October 2026 |
| IndexNow batch | Up to 10,000 URLs | 23 October 2026 |
| IndexNow key | 8 to 128 characters: letters, digits or hyphens | 23 October 2026 |
| Google common-crawler range snapshot | 317 prefixes; refresh before verification | 23 October 2026 |

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.