How to get cited by AI search with AEO

On this page
- 1. The question becomes several retrieval queries
- 2. Retrieval reaches four different indexes
- 3. Eligibility gates decide what the crawler can read
- 4. Passage selection supplies the answer's evidence
- 5. Source selection weighs competing evidence
- 6. Citation display determines what the reader sees
- 7. Measurement exposes only parts of the machine
SEO
How to get cited by AI search: be retrievable in each engine's index for its generated sub-questions, provide a passage that answers one independently, and earn recognition across the wider web. There is no separate AEO switch: Google explicitly says AI Overviews and AI Mode have no additional requirements or special optimizations. Answer engine optimization (AEO) means making your information accessible and useful to answer systems; the work changes with each system's retrieval machinery.
| Part of the machine | Google AI Overviews / AI Mode | ChatGPT search | Perplexity | Claude | What you control |
|---|---|---|---|---|---|
| Question becomes queries | Documented fan-out; no sub-query count published | Generated searches may differ from the prompt; Ahrefs says the actual prompt may never be searched | Hybrid lexical and semantic retrieval over the query | Claude decides when to search; API max_uses caps searches per request | Coverage of specific sub-questions |
| Index retrieval | Google Search index; page must be indexed and snippet-eligible | OAI-SearchBot index plus third-party providers, including Bing (reported); mix undisclosed | Own index tracking over 200 billion URLs | Claude-SearchBot; Brave backend reported, unconfirmed by Anthropic | Accessible, indexable URLs |
| Eligibility gate | nosnippet, data-nosnippet, max-snippet, noindex; Google-Extended does not control AI Overviews | OAI-SearchBot for search; GPTBot for training; robots.txt rules may not apply to ChatGPT-User (user-initiated fetches) | PerplexityBot for search; Perplexity-User generally ignores robots.txt | Claude-SearchBot, ClaudeBot and Claude-User all honor robots.txt | Bot rules and server HTML |
| Passage selection | Core ranking systems retrieve pages; no requirement to chunk content | Not documented by OpenAI | Document and sub-document scoring; cross-encoder rerankers | API cited_text contains up to 150 characters | Clear, self-contained sections |
| Source selection | Core Search ranking systems | Not documented | Ranking stages documented; final citation-selection rules not documented | Not documented | Evidence and authentic recognition |
| Citation display | Only 13.7% citation overlap between the two features in Ahrefs' study | utm_source=chatgpt.com on referral URLs, per OpenAI's FAQ (reported) | API answers carry numbered [1] references mapped to search results | API citations carry url, title and cited_text | Identifiable pages and claims |
| Measurement | Search Console generative AI views show impressions | Verified OAI-SearchBot and ChatGPT-User fetches; tagged referral sessions | Verified PerplexityBot fetches | Verified Claude-SearchBot and Claude-User fetches | Consistent records and checks |
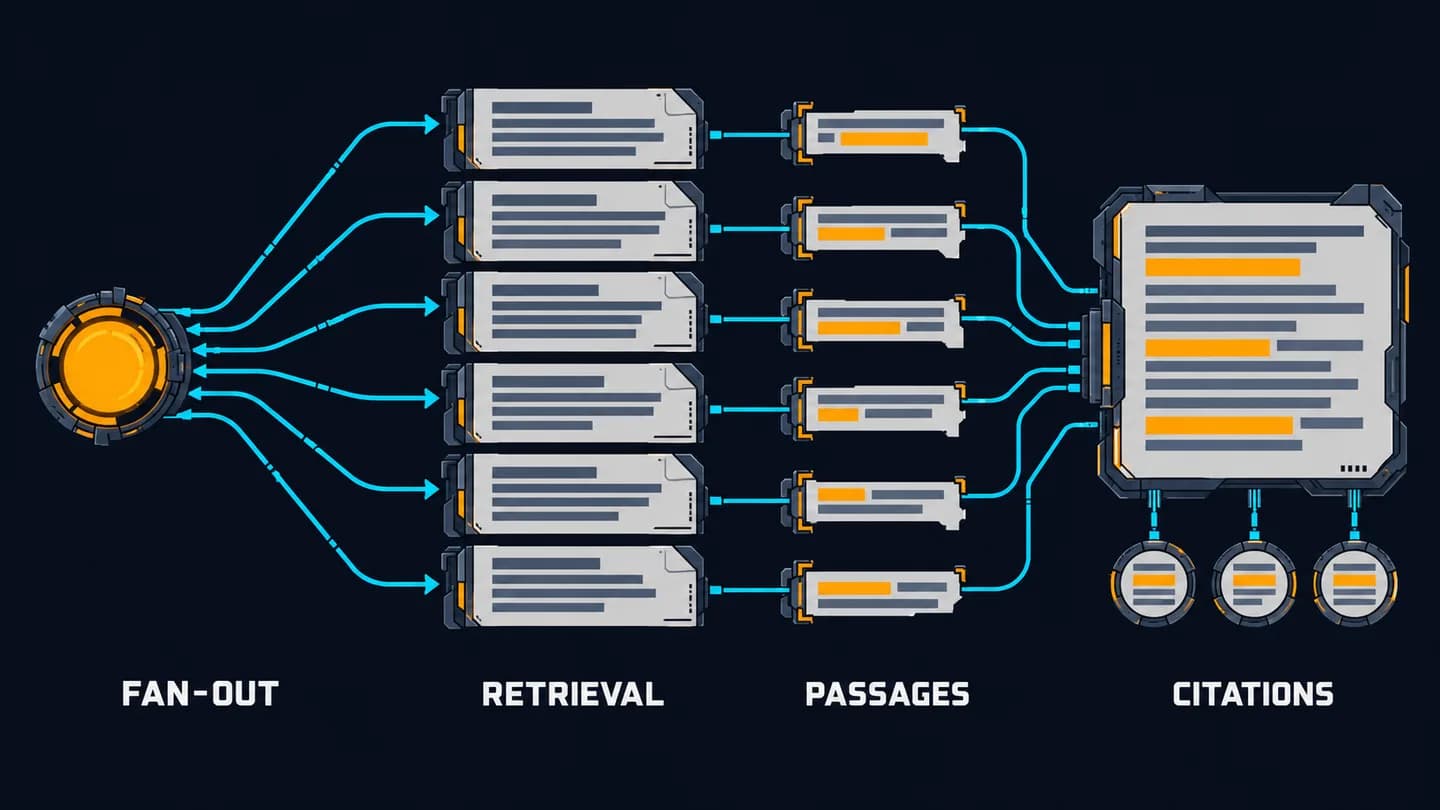
The typed question is only the entrance. Each transition can change which pages survive to the answer, and a retrieved passage can disappear before citation display.
1. The question becomes several retrieval queries
Query fan-out means generating related searches to collect information for an answer. Your page can therefore match a sub-question the user never typed, while the page ranking first for the original wording supplies nothing useful.
Google's AI Mode launch post, published March 5, 2025, describes concurrent searches across subtopics and multiple data sources. Its May 20, 2025 update describes breaking questions into subtopics and issuing queries simultaneously. Search Central says AI Overviews and AI Mode may use fan-out; Google publishes no standard sub-query count. The statement that Deep Search can issue hundreds of searches is not a default for ordinary AI Mode.
Google's patent application US20240289407A1, titled Search with stateful chat, describes generating synthetic queries from model output and selecting search-result documents. The application was published August 29, 2024, and Google has not tied it to AI Mode. It describes a possible method, not a disclosed production blueprint.
Say someone asks which appointment system suits a five-location clinic. Hypothetical retrieval questions might concern migration, permissions or scheduling integrations. Those are illustrative sub-questions, not an observed Google trace; their value is showing why a detailed permissions page could compete with a broad software comparison.
What you can change before retrieval starts
Write down the questions a buyer must resolve to make the decision. Give each substantial question an answer with its conditions attached, such as which integrations exist and what requires custom work.
Prioritize questions you can answer with evidence. A company with 10 to 200 employees usually has more to gain from publishing its actual service constraints than from generating dozens of near-identical question pages.
Inspect an approximation with Gemini's search tool
The Gemini API Google Search documentation provides a way to inspect executed queries. Send a POST request to https://generativelanguage.googleapis.com/v1beta/interactions, with headers x-goog-api-key: $GEMINI_API_KEY and Content-Type: application/json, and this JSON body: {"model": "gemini-3.8-flash", "input": "Who won the euro 2024?", "tools": [{"type": "google_search"}]}.
Read google_search_call.arguments.queries; url_citation annotations associate answer spans with source URLs. Replace the example question with a buyer question and record which executed queries your existing pages answer. This is an approximation of production fan-out: Google does not say the API reproduces AI Mode.
Prices read on October 24, 2026: for Gemini 3 and newer, billing counts executed search queries, with the first 5,000 search requests per month free and subsequent usage at $14 per 1,000. A user question can produce several searches, so record executed queries when estimating cost.
2. Retrieval reaches four different indexes
Google retrieves relevant pages from its Search index using core ranking systems. A page must be indexed and eligible for a Search snippet to qualify for its AI features. Ranking for the original question remains useful, but it does not establish eligibility for every generated sub-question.
Ahrefs' March 2, 2026 analysis found 37.9% of AI Overview citation URLs within the first ten SERP blocks, down from about 76% in July 2025. A block includes features such as ads, snippets and People Also Ask, so this is not simply the first ten organic links. The analysis covered 863,000 keyword results and four million cited URLs; Ahrefs also improved its parsing between studies, complicating a direct comparison.
ChatGPT has OAI-SearchBot for its search features. OpenAI's help center reportedly names Bing among the third-party search providers it uses, but the provider mix is undisclosed. Calling ChatGPT a wrapper around Bing gives a misleadingly tidy picture.
Seer's February 2025 study found more than 87% overlap between SearchGPT citations and Bing's top 20 across roughly 100 questions and more than 500 citations. Ahrefs' August 2025 study of 15,000 long-tail prompts found only 8.1% overlap between ChatGPT in-text citations and Bing's top ten, with 8.0% for Google. Different samples, result depths and dates prevent a direct comparison; generated searches can also differ from the submitted prompt.
Perplexity's published architecture describes an index tracking over 200 billion URLs and processing 200 million daily queries. It merges lexical and semantic candidates, filters clearly unresponsive or stale material, and applies cross-encoder rerankers. It scores both documents and smaller sub-document units.
Claude has Claude-SearchBot for improving search responses. Its web-search backend is reported to use Brave, based on Simon Willison's investigation of citations and implementation clues; Anthropic has not confirmed that provider relationship. Claude's API lets developers limit searches through max_uses, so tool configuration can also affect what an answer retrieves.
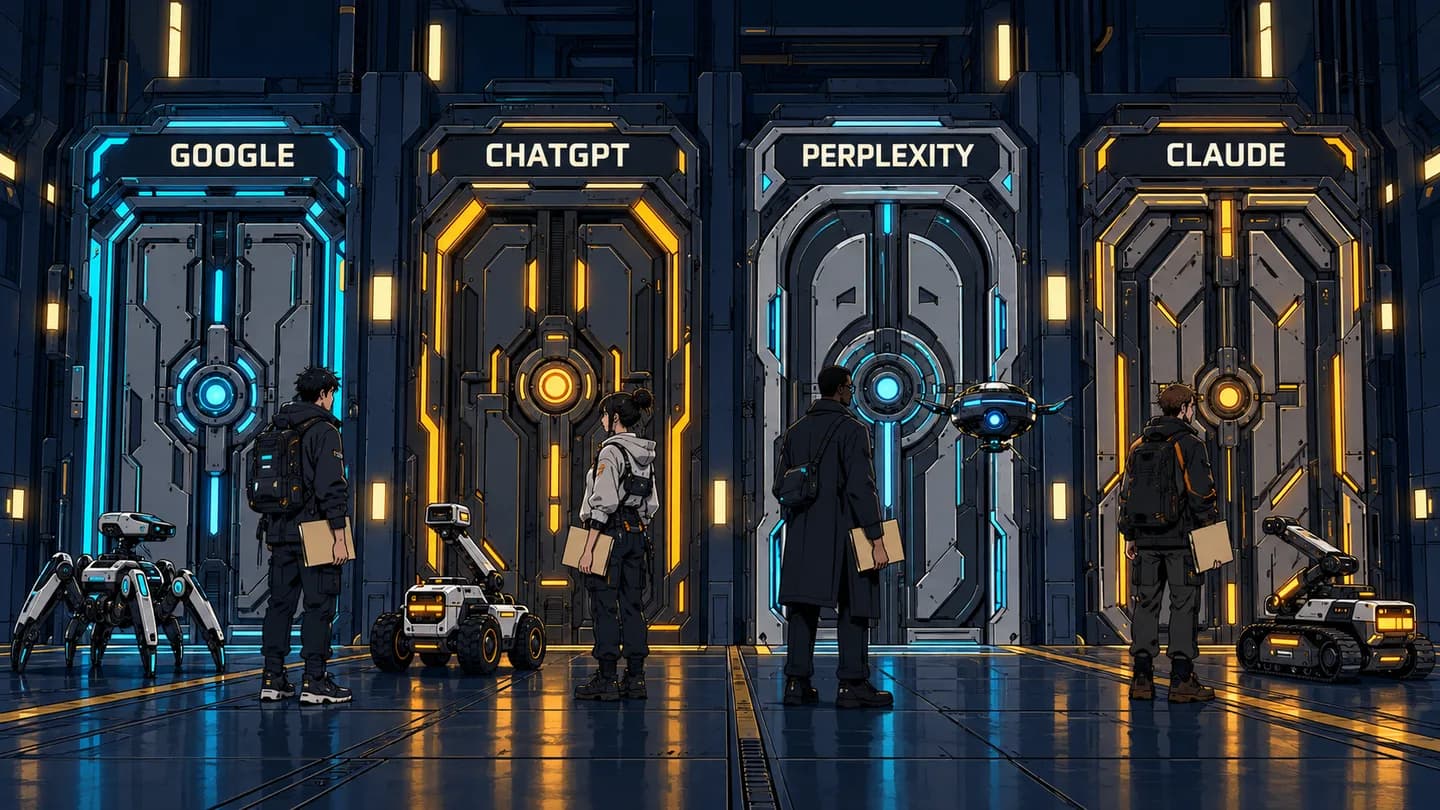
Each archive has its own entrance and crawler. Inclusion in Google's index does not establish that another assistant has indexed the same page.
Make your important URLs discoverable in each system
Keep useful pages accessible through ordinary internal links, with stable URLs and accurate titles. Check Google and Bing indexing separately, then inspect verified search-crawler requests for the other systems.
My priority for an established company is its service, product and evidence pages. An indexed page that explains a real purchasing constraint is more useful than an elaborate content calendar built around interchangeable definitions.
Check indexing and crawler access separately
Use Search Console URL Inspection and Bing Webmaster Tools URL Inspection for index status. Use server logs for OAI-SearchBot, PerplexityBot and Claude-SearchBot access, verifying IP addresses before counting requests.
An HTTP 200 proves that a request succeeded. It does not prove indexing, passage selection or eventual citation, and the reporting sheet should keep those states separate.
3. Eligibility gates decide what the crawler can read
Training permission and search permission are separate controls. OpenAI's bot documentation assigns OAI-SearchBot to surfacing websites in ChatGPT search; blocking it excludes sites from search answers, although navigational links can remain. Robots.txt changes take approximately 24 hours to propagate.
GPTBot concerns possible foundation-model training. ChatGPT-User handles user-initiated visits; OpenAI says robots.txt rules may not apply, and this fetcher does not determine search inclusion. Allowing GPTBot is therefore not a documented requirement for ChatGPT search.
Anthropic separates ClaudeBot for possible training, Claude-SearchBot for search relevance and accuracy, and Claude-User for user-requested fetches. All three honor robots.txt, and Anthropic supports the nonstandard Crawl-delay directive. PerplexityBot surfaces and links websites in search results and is not used for foundation-model training; Perplexity-User supports user actions and generally ignores robots.txt. Perplexity says rule changes can take up to 24 hours.
This example allows the named search crawlers while declining the named training crawlers. Adapt the paths and merge it carefully with existing rules; training permission is a business choice with no documented search-inclusion benefit.
User-agent: OAI-SearchBot
Allow: /

User-agent: Claude-SearchBot
Allow: /

User-agent: PerplexityBot
Allow: /

User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /
For Google, Google-Extended does not control AI Overviews. Search controls are nosnippet, data-nosnippet, max-snippet and noindex: they stop text snippets entirely, exclude particular text, constrain snippet length or prevent indexing respectively. nosnippet also keeps the content out of direct input for AI Overviews and AI Mode. A crawler must be allowed to fetch a page to discover its noindex instruction.
JavaScript introduces another gate. Vercel and MERJ reported in December 2024 that the major non-Google AI crawlers they examined did not render JavaScript; Google's infrastructure could render it. Treat that as a dated observation, while putting essential answers in the server's HTML remains a sensible compatibility rule.
Our own logs complicate the historical finding. Of 524 verified OAI-SearchBot requests, 399 fetched Next.js data URLs containing _rsc=, 55 fetched robots.txt, 40 fetched images, and 30 were other page fetches: 20 HTML pages and ten /raw Markdown endpoints. Those data URLs normally arise from client routing, so rendering or replay is our own inference from our own logs, explicitly untested.
Change permissions and the HTML response
Decide search and training permissions separately, then check CDN or firewall rules for accidental blocks. Put the useful answer outside script payloads in the server response.
The technical SEO and crawl-cost checks connect crawler verification, robots.txt and server-rendered HTML. These are prerequisites you can inspect directly, without guessing what a model prefers.
Test visibility without executing JavaScript
Replace the URL and expected phrase in this command. It removes script blocks before counting, because a phrase appearing only inside a Next.js script payload would give a false positive for its presence in page content outside scripts.
curl -sL https://example.com/page \
  | python3 -c "import sys,re,html; t=re.sub(r'(?is)<script.*?</script>',' ',sys.stdin.read()); print(html.unescape(re.sub(r'<[^>]+>',' ',t)))" \
  | grep -c "the figure you expect"
A zero means the phrase is absent from server-rendered markup outside scripts. Redirects, access challenges or changed wording can also explain a zero, so inspect the response before diagnosing a rendering problem.
4. Passage selection supplies the answer's evidence
Retrieval finds candidates; grounding uses retrieved material to support generated statements. A whole page can be relevant while containing no passage that clearly supports the particular statement being assembled.
Google's AI optimization guidance says there is no requirement to divide content into tiny pieces. Microsoft describes assistants parsing content into smaller structured pieces, while Perplexity documents sub-document scoring. These statements fit together: retrieval systems can split pages themselves, while writers preserve enough context for the extracted material to make sense.
Consider a hypothetical maintenance service. “Response within four business hours for covered equipment in the contracted service area” carries conditions that “fast response” omits. Keep those conditions beside the claim, including any definition of business hours that changes its meaning.
Claude's API citations include url, title and cited_text, with the latter containing up to 150 characters of cited content. That is a citation-field limit, not a recommended paragraph length. OpenAI does not document ChatGPT's passage-selection algorithm.
Google says Search ignores llms.txt and similar AI text files: they neither harm nor help visibility or rankings. Schema remains useful for rich results and entity clarity when it matches visible text, but Ahrefs' matched-control test found no citation lift. Neither is a documented citation lever.
Ahrefs compared 1,885 pages that added schema with matched controls. AI Mode's 2.4% increase and ChatGPT's 2.2% increase were indistinguishable from zero; AI Overview citations declined 4.6%, with the cause unclear. The study examined pages already cited in AI Overviews, so it does not establish what happens to previously uncited pages.
Ahrefs also found that 97% of llms.txt files in its study received no requests during May 2026, across a sample of 137,000 domains. No major AI search provider documents reading llms.txt for its answer system. Our own functioning /llms.txt received 14 requests during the log window, none from an OpenAI, Anthropic, Perplexity, Google or Bing user agent; that observation applies to our site.
Write passages with their conditions attached
Make each substantial section answer one identifiable sub-question. Keep units, dates and qualifications close to the claim they modify, and use tables when comparison depends on fixed attributes.
Use the guidance on sections that earn snippets and citations when revising explanations that depend on surrounding paragraphs. The objective is a passage that remains accurate when extracted, without turning every page into fragments.
Check an extracted passage against its claim
Copy a candidate paragraph into a blank document and read it without the page title. Check whether the subject is identifiable and whether its conditions survive.
For Claude API results, inspect cited_text beside the sentence it supports. For other interfaces, open the cited URL and locate the supporting passage manually; a citation chip alone does not demonstrate that the answer represented the page accurately.
5. Source selection weighs competing evidence
Several pages may answer the same sub-question adequately. Google identifies its core ranking systems as part of retrieval, but the other vendors do not publish a complete rule for deciding which eligible sources receive final citations.
Ahrefs' study of 75,000 brands found a Spearman correlation of 0.664 between branded web mentions and brand mentions in AI Overviews. The corresponding figures were 0.527 for branded anchors, 0.392 for branded search volume and 0.218 for backlinks. These are correlations, not evidence that buying mentions produces citations.
Google warns that seeking inauthentic mentions is less helpful than it may seem. My judgment is to prioritize legitimate places where buyers already evaluate your company: relevant directories, partner documentation and credible coverage of work you can substantiate. Manufactured repetition gives you no reliable evidence that a source-selection mechanism changed.
The distinction also prevents a common measurement error. An assistant naming your company and an assistant citing one of your pages are different events; a useful technical page can support an answer that never discusses your company.
Publish evidence other sources can reference
Make factual claims easy to verify and attribute. Publish specifications, explicit service boundaries and original material you can support, then keep business descriptions consistent across legitimate profiles.
Choose evidence that helps an actual buying decision. A precise integration requirement has a clearer purpose than another page announcing that your company values innovation.
Compare cited competitors at the claim level
For a fixed buyer question, record the cited URL and the exact claim it supports. Check whether the competing page supplies evidence your page lacks, such as a documented limitation or an explicit comparison.
Keep observations separate from explanations. “Their page was cited for compatibility” is observable; “the assistant chose them because they have more backlinks” requires evidence the interface does not provide.
6. Citation display determines what the reader sees
A citation is a source reference, not necessarily a brand recommendation or a visit. The final interface can show supporting material while giving the source company very little attention.
Ahrefs found only 13.7% citation overlap between AI Overviews and AI Mode across 540,000 query pairs using September 2025 US data. The separate 730,000-pair sample concerned content similarity, including 86% semantic similarity. Similar answers can therefore lead readers to substantially different sources.
Pew Research's browsing study found clicks on links inside AI summaries on about 1% of visits to results pages containing a summary. The research covered 900 US adults and 68,879 searches during March 2025. Traditional-result clicks occurred on 8% of visits with a summary and 15% without one; those observations do not predict an individual site's conversion rate.
Semrush's June 9, 2026 ghost-citation study, conducted with Kevin Indig and Growth Memo, examined 3,981 domain appearances across 115 prompts in 14 countries. Across ChatGPT, AI Overviews, Gemini and AI Mode, 61.7% were ghost citations: a source link appeared, but the brand was never named in the answer. That makes citation counts an incomplete measure of recognition.
Perplexity API answers use numbered references mapped to search results. Claude API citations expose source metadata and cited text; OpenAI's publishers FAQ reportedly says ChatGPT referral URLs carry utm_source=chatgpt.com. The tagging claim is reported because that FAQ could not be fetched directly.
Make the cited destination useful to a visitor
Give the destination an accurate title and an immediately recognizable answer. A visitor following a technical citation should be able to verify the claim before deciding whether your service is relevant.
Use the distinction between visibility and visits when assessing whether SEO still works with AI answers. Keep citation presence, explicit brand mentions and referral sessions as separate measures.
Record the answer and its citation together
Save the prompt, date, engine and cited URL alongside whether the answer names your company. Record the answer text or a screenshot so later checks can distinguish a changed answer from a changed source link.
In analytics, inspect sessions carrying utm_source=chatgpt.com and relevant referral hosts. Those sessions measure arrivals; they cannot count people who saw a citation and never clicked.
7. Measurement exposes only parts of the machine
Free first-party tools now show more than ordinary referral analytics. Search Console's generative AI performance announcement, published in June 2026, describes dedicated impression views for generative Search features including AI Overviews and AI Mode. Do not describe those impressions as separately measured AI clicks.
Bing Webmaster Tools AI Performance, announced in public preview in February 2026, includes Total Citations, Average Cited Pages and Grounding queries. Grounding queries are phrases used to retrieve cited content, and the data represents a sample of citation activity. The announcement lists no click metric.
Server logs expose access, provided you verify the caller. Our own irongoo.com nginx logs contain 88,066 requests over 14 full days, October 10 through October 23, 2026. We matched user-agent tokens and checked IP addresses against vendor ranges downloaded October 24, 2026.
| Claimed crawler | Verified requests | Claimed requests outside vendor lists |
|---|---|---|
| OAI-SearchBot | 524 | 195 |
| GPTBot | 513 | 219 |
| ClaudeBot | 568 | 170 |
| Claude-SearchBot | 0 | 199 |
| PerplexityBot | 110 | 187 |
| bingbot | 753 | 173 |
| Googlebot web, excluding Image/Video | 264 | 443 |
| ChatGPT-User | 6 | 188 |
| Perplexity-User | 0 | 177 |
| Claude-User | 0 | 193 |
The 199 requests claiming Claude-SearchBot came from 13 Google Cloud addresses and mostly probed for secret configuration files. Of those, 189 returned 404; every Claude-SearchBot claim in this window was an impostor. A persuasive user-agent string costs the sender nothing.
This genuine OAI-SearchBot request came from an address in OpenAI's published range. It records a successful response of 41,233 bytes, with no referrer supplied.
74.7.228.202 - - [23/Oct/2026:01:54:00 +0000] "GET /guides/analytics-data/data-hygiene-for-small-teams HTTP/1.1" 200 41233 "-" "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36; compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot"
Establish a small weekly measurement routine
Choose a fixed set of real buying questions and repeat them weekly with the same wording, recording engine, search mode and account context. Track cited pages separately from brand mentions, and compare repeated observations before changing the site.
SparkToro's research involved 600 volunteers, 12 prompts and 2,961 runs. It found less than a 1-in-100 chance that ChatGPT or Google's AI, asked the same prompt 100 times, would give the same list of brands in any two responses. A single missing citation is weak evidence of a meaningful decline.
For a tested written picture of what ChatGPT, Claude, Perplexity, Gemini, AI Overviews and Copilot currently say about your company, an AI visibility assessment can document who gets cited in your place. That is a defined research task, without a promised citation count.
Verify requests before adding them to the report
Save this script as verify_bots.py and run python3 verify_bots.py access.log. It verifies the three named search bots, not every crawler in the table; behind a CDN, restore the real client IP in the log first.
import ipaddress, json, sys, urllib.request

LISTS = {"OAI-SearchBot": "https://openai.com/searchbot.json",
         "PerplexityBot": "https://www.perplexity.com/perplexitybot.json",
         "Claude-SearchBot": "https://claude.com/crawling/bots.json"}

def ranges(url):
    req = urllib.request.Request(url, headers={"User-Agent": "Mozilla/5.0 (log-check)"})
    prefixes = json.load(urllib.request.urlopen(req))["prefixes"]
    return [ipaddress.ip_network(p.get("ipv4Prefix") or p.get("ipv6Prefix")) for p in prefixes]

nets = {bot: ranges(url) for bot, url in LISTS.items()}
for line in open(sys.argv[1], errors="ignore"):
    for bot, nlist in nets.items():
        if bot + "/" in line:
            ip = ipaddress.ip_address(line.split()[0])
            verdict = "REAL" if any(ip in n for n in nlist) else "FAKE"
            print(verdict, bot, line.split('"')[1])
Keep the downloaded range files with each analysis so the verification date remains auditable. Pair verified fetch counts with Search Console impressions, Bing citation activity and the weekly prompt records; each measures a different observable event, and none alone proves the whole path from question to customer.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.