Internal linking strategy for service business sites

On this page
- A hypothetical 30-page site with the wrong priorities
- Internal linking architecture modeled five ways
- Why equal links do not imply equal weight
- What the leaked anchor fields actually establish
- Measured results that qualify the model
- An evidence ledger for common internal-linking rules
- Audit the actual graph before editing templates
- Check JavaScript-only links before trusting the crawl
- Turn the findings into a fixed state
SEO
0.50% is all an orphan page receives in the hypothetical 30-page PageRank model used here: its random-jump allowance, with nothing arriving through links. An internal linking strategy decides which pages receive links, from where, and with what descriptions. For a small service website, the most useful first check is whether every core service has a direct homepage link and relevant links from other pages.
Yes, PageRank flows through internal links. The awkward part is that adding links can redistribute importance toward pages you never intended to prioritize, including whichever article happens to be newest.
A hypothetical 30-page site with the wrong priorities
Consider fictional Northfield Maintenance, an openly hypothetical commercial maintenance company. Its website has exactly 30 pages, and its five services have equal business priority for this example. There are no actual traffic results or client observations attached to it.
| Page group | Count | Starting internal link structure |
|---|---|---|
| Homepage | 1 | Header links to all services and the blog |
| Service pages | 5 | Header links, no contextual links from posts |
| About and contact | 2 | Included in the header |
| Blog index | 1 | Lists all 20 posts |
| Privacy | 1 | Linked from every footer |
| Blog posts | 20 | Each links to the three newest posts |
| Total | 30 | Same header and privacy footer throughout |
The header contains home, all five services, about, contact and the blog index. Each service has four matching posts by topic, although those posts initially point readers toward recent articles. This is a realistic template mistake: publication date has become the organizing principle for a service business.
Before changing links, decide which pages deserve central positions. If two service pages answer effectively the same need, link adjustments cannot settle their responsibilities; a topical map that assigns a clear purpose to each page supplies that decision.
For hypothetical Northfield Maintenance, the intended hierarchy is simple: the five services are permanent destinations, and posts answer narrower questions that can lead to those services. That does not require every article to contain a sales link. It requires a relevant next step when the service actually answers the reader's need.
Internal linking architecture modeled five ways
The calculation uses damping of 0.85, 100 power iterations and even redistribution of dangling-page mass. The original PageRank model assigns about 15% to random jumps; with 30 pages, each page's baseline allowance is (1 - 0.85) / 30 = 0.005, or 0.50%.
Two weighting regimes expose how sensitive the result is to assumptions. The uniform version gives header and content links equal weight, with footer links at half the header weight. The second gives navigation links a weight of 0.3, content links 1, and footer links half the navigation weight.
Those weights are modeling choices. Google does not publish its current link weights, and these percentages are shares of a simulated site's PageRank, not predicted traffic changes.
| Scenario on the hypothetical site | Service 1, uniform weighting | Service 1, navigation weighted at 0.3 |
|---|---|---|
| A: Posts link sideways to the three newest posts | 8.43% | 7.59% |
| B: Posts link to their matching service and one sibling post; services also link to their four matching posts | 7.84% | 7.05% |
| C: Posts link to their matching service and one sibling post; services do not link down to posts | 8.77% | 8.60% |
| D: Same as C, except service 1 leaves the sitewide header on every page except the homepage, which still links to it; its only other inbound links are its four matching posts | 1.72% | 2.15% |
| Orphan variant: Service 5 has zero inbound links | Service 5: 0.50% | Service 5: 0.50% |
Header membership changes the distribution most before orphaning
Moving from A to C increases service 1's score from 8.43% to 8.77% under uniform weighting, approximately 4% relative. Under discounted navigation weighting, the increase is approximately 13%, from 7.59% to 8.60%. Contextual links help in both versions, but the service already receives links throughout the header.
Removing that header presence in D creates the largest architecture drop short of orphaning. Compared with C, service 1 falls from 8.77% to 1.72% in the uniform model, despite retaining its homepage link and four relevant post links. The zero-inbound-link variant falls furthest, reaching the 0.50% floor.
This supports a practical priority for hypothetical Northfield Maintenance: preserve clear access to its core services before spending hours adjusting article anchors. It does not establish that Google's live systems value a header link at either modeled weight.
Service-to-post links have a measurable cost inside the model
B and C differ only in whether services link down to their four matching posts. Adding those links lowers service 1 from 8.77% to 7.84% under uniform weighting, and from 8.60% to 7.05% under discounted navigation weighting. The service distributes its outgoing flow across more destinations.
B also finishes below A, but that comparison changes the posts' linking pattern too. It cannot isolate service-to-post links as the sole cause of the difference. Controlled comparisons are less exciting than convenient explanations, but considerably more useful.
Keep a service-to-post link when the article helps someone make a decision. A detailed inspection checklist might belong on a maintenance service page; four links added automatically because four posts exist have a weaker justification.
A latest-post widget concentrates flow on publication order
In A's weighted model, the newest post receives 4.33%, while the oldest receives 0.81%. Repeated links to recent posts produce that concentration even though publication date says nothing about commercial importance.
For hypothetical Northfield Maintenance, the repair is to choose related destinations by subject. A sibling article can answer the next question, while a service link can offer the appropriate action. The modeled benefit is redistribution; any relevance benefit remains plausible but unmeasured here.
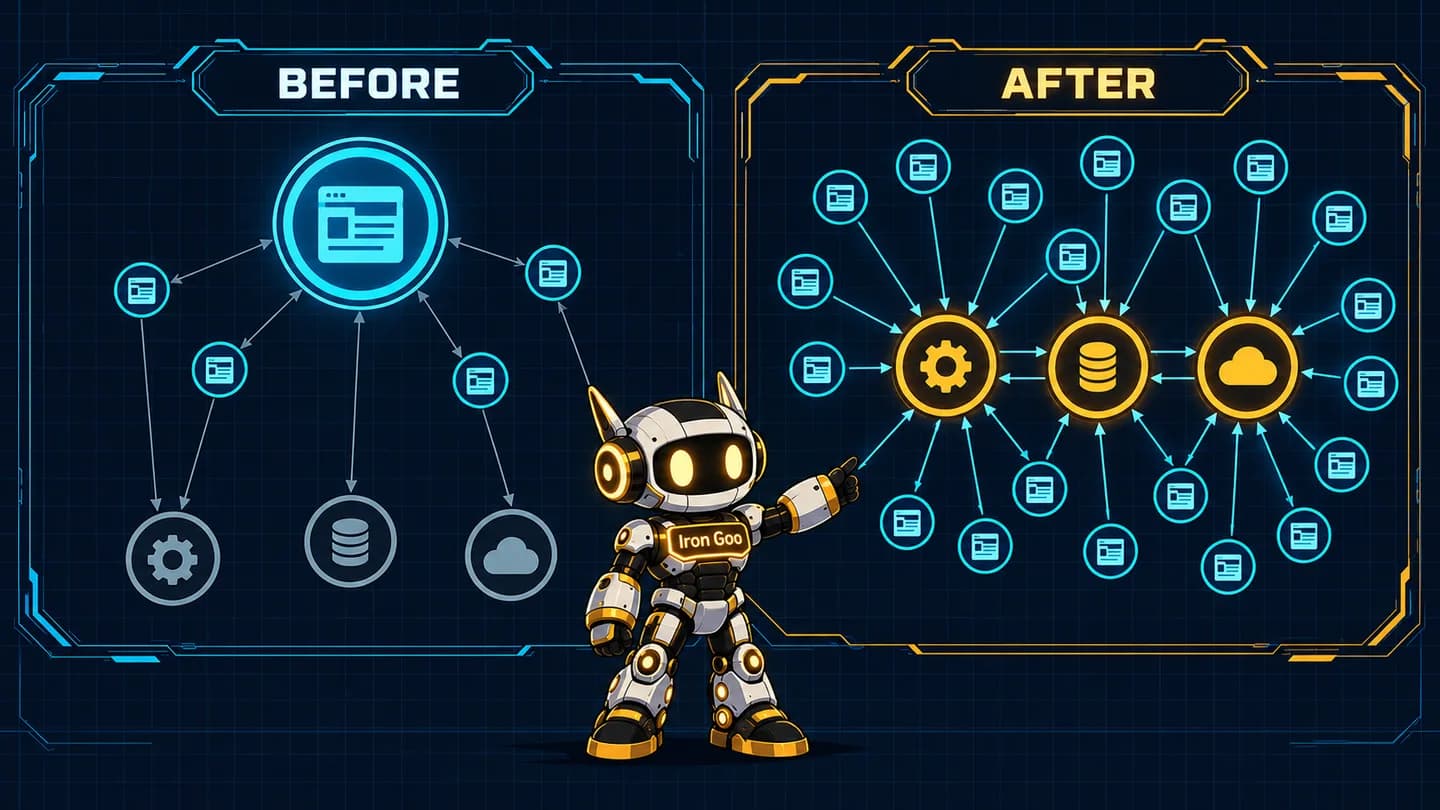
In the hypothetical model, repeated latest-post links concentrate flow on recent content. Relevant service links redistribute it, while removing a service from most header menus sharply reduces its share.
Why equal links do not imply equal weight
The uniform calculation is useful accounting, but it is an incomplete description of how Google could evaluate links. The reasonable surfer patent family describes different probabilities for following different links, using features of the link and its placement.
The relevant parent is US 7,716,225, granted on 11 May 2010, followed by child US 8,117,209, granted on 14 February 2012. The reasonable surfer patent description names features including position within running text or lists, footer placement, anchor font size, anchor words, surrounding words and whether a link stays on the same domain.
A prominent link in an explanatory paragraph and a subdued footer link need not receive identical treatment. The patent also describes learning from user behavior, so dividing by a page's raw outgoing-link count is only a simplifying assumption.
The patent is evidence of a described mechanism, not a published specification of current search rankings. It provides no defensible conversion such as “one paragraph link equals seven menu links,” however convenient that would make a spreadsheet.
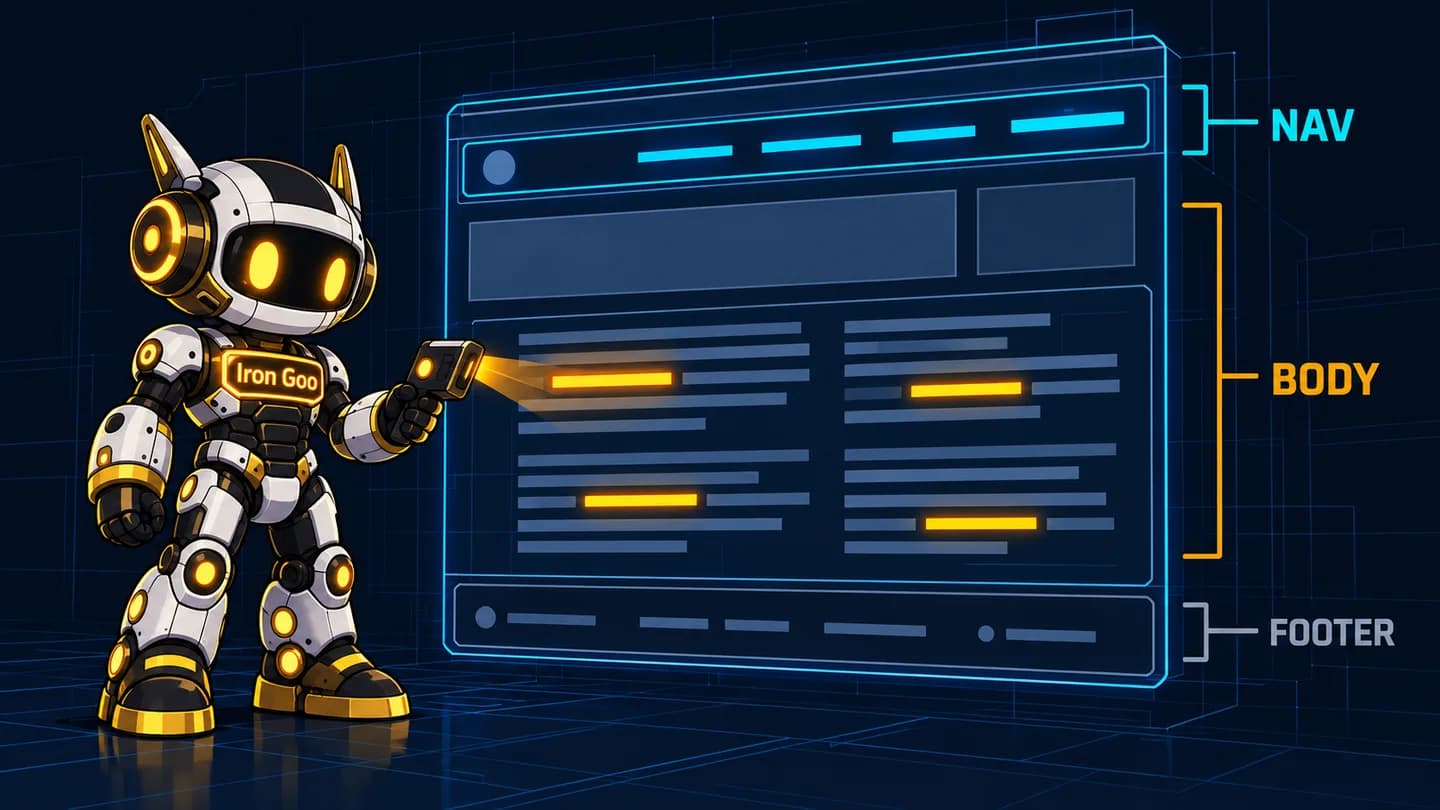
Notice how position and surrounding text distinguish links on the same page. The patent describes those features; Google's current weights are unknown.
What the leaked anchor fields actually establish
The leaked AnchorsAnchor documentation records link text and context-related fields. Their existence supports inspecting more than link counts, without revealing a ranking formula.
| Field | Documented information | Limit |
|---|---|---|
fontsize | Name and integer type only; no description | No documented size preference |
offset | Byte position used to recover link order | No first-link-only rule |
context2 | Hash of nearby terms | No disclosed relevance weight |
fullLeftContext, fullRightContext | Stored context fields | No disclosed scoring formula |
isLocal | Rough same-domain indicator | No internal-link multiplier |
weight, pagerankWeight | Weight fields; weight has a 0 to 127 range | No public calculation |
parallelLinks | Additional links to the same target domain; unpopulated for local links | No answer about repeated internal links |
The leak shows that these fields exist. It does not establish their current use, their relative influence, or whether changing one improves rankings.
For hypothetical Northfield Maintenance, a sensible edit is a descriptive service anchor inside a relevant explanation. Anchor text and surrounding language may matter for relevance, even when the model shows only modest PageRank movement. Increasing font size solely because a field exists would be an unusually literal reading of incomplete documentation.
A separate field offers a more useful hypothesis for choosing donors. The leaked PerDocData description of onsiteProminence describes a 13-bit internal-importance measure calculated by propagating simulated traffic from the homepage and pages with strong click signals.
That suggests testing links from pages already earning search clicks, as well as the homepage. It does not prove that the top-click page is your strongest donor, or give an effect size. It supplies a reasoned selection method that can be checked against your own results.
Measured results that qualify the model
A model isolates assumptions; a search experiment measures an outcome under particular conditions. SearchPilot's published tests show that internal-link changes can help both destinations and linking pages, with results that resist simple “more links wins” advice.
In the Iceland Groceries category-link test, published on 3 August 2020, both category levels individually gained more than 20%. That matters because the linking pages benefited too, something a simple transfer metaphor can obscure.
The related-article test, published on 10 June 2021, reported an 11% combined gain at 90% probability. Its stronger donor result does not demonstrate that outgoing links generally improve rankings; it describes one content-hub experiment.
The homepage-footer test, published on 14 September 2021, measured organic traffic. It supports rejecting the blanket claim that footer links cannot help, but it did not measure PageRank transfer or establish a footer-link exchange rate.
Zyppy's anchor findings conflict
Zyppy's 23-million-link study examined approximately 520,000 URLs across 1,800 sites against Search Console clicks. Pages receiving zero to four links averaged two clicks, and the association reversed after approximately 45 to 50 inlinks. Sitewide navigation was a proposed explanation, not a demonstrated threshold.
Anchor variety was positively associated with clicks in that study. Pages with at least one exact-match internal anchor had at least five times more traffic, another association that cannot establish what adding an anchor would cause.
The 50-site follow-up updated on 1 September 2026 pointed the other way: internal anchor variations correlated negatively with traffic change through recent updates, at r = -0.337. External variations had r = -0.352, while raw link counts were not significantly correlated.
These findings conflict on anchor variety. The defensible practice is descriptive anchors with natural variation, without manufacturing synonyms to satisfy a quota. Zyppy also found navigation links seemed powerful mostly on larger, high-authority sites, limiting how confidently that finding transfers to a small company website.
An evidence ledger for common internal-linking rules
Use evidence grades to decide what deserves implementation time. Here, “documented” means Google's published guidance, “experiment” means a controlled traffic test, “correlation” means an observed association, and “convention” means a working preference without a verified threshold.
| Common rule | Evidence grade | Decision for a small service site |
|---|---|---|
| Every page must be within three clicks | Convention, with reported Google comments supporting relative homepage proximity | Investigate deep core pages; three is no universal ranking boundary |
| Never exceed 100 links per page | Historical guidance, superseded | No current hard cap; remove unnecessary destinations |
| Maximize anchor variety | Conflicting correlations | Use descriptive wording that fits each sentence |
| Footer links pass useful value | Organic-traffic experiment; mechanism unmeasured | Footer links can help; their PageRank contribution was not measured |
| Nofollow internal links to concentrate PageRank | Reported historical correction; current documented hint treatment | Do not use internal nofollow for sculpting |
| Google counts only the first link to a destination | Unconfirmed; stored order proves only order storage | Make navigation and body links independently useful |
| Every page needs 45 internal links | Misreading of a correlation | Set no inbound-link quota from the Zyppy curve |
| Redirected internal links are a major ranking problem | SearchPilot experiment was inconclusive, from -1% to +4% | Fix for hygiene and clearer paths; promise no traffic lift |
How many internal links should a page contain or receive?
There is no universal number for either direction. Google's published link guidance sets this minimum: “Every page you care about should have a link from at least one other page on your site.”
Receiving one link satisfies that documented minimum, but can leave a service dependent on one easily broken path. My working preference is a homepage route plus contextual links from genuinely relevant pages; three contextual donors can serve as an investigation target, never a Google requirement.
For outgoing links, inspect usefulness and destination concentration. A five-service menu is reasonable for hypothetical Northfield Maintenance, while listing every article on every service page would need a specific reader benefit.
Click depth measures routes, not URL slashes
A deeply nested URL can still be one click from the homepage. Reported Google comments distinguish homepage click distance from the number of slashes, so reorganizing folders alone does not shorten a link path.
For a 30-page site, a core service deeper than one click deserves inspection; an article beyond three clicks deserves a question about its discoverability. Both are working checks, not ranking cutoffs. Rendering requirements and inefficient paths belong in a broader technical SEO and crawl-cost assessment when the links exist but crawlers struggle to reach them.
Audit the actual graph before editing templates
Start with a homepage crawl, then compare its discovered URLs with a separate inventory from sitemaps, Search Console and CMS exports. An orphan page has no inbound internal hyperlinks; a page missing from one crawl is only an orphan candidate until crawl restrictions and rendering have been checked.
For hypothetical Northfield Maintenance, compare all 30 intended pages with discovered pages. Include tag, category and pagination pages in the crawl when present, because their links count only if the crawler collects them.
Screaming Frog columns that distinguish link problems
Use these fields from Screaming Frog's tabs and link exports. Run crawl analysis for Link Score, its relative internal-link metric from 0 to 100; it is not Google's PageRank.
| Field | Observable check |
|---|---|
Crawl Depth | Core pages have short homepage paths; redirects count as a level |
Unique Inlinks | Count distinct donors, avoiding repeated-link inflation |
Link Score | Compare relative importance after crawl analysis |
Type | Separate hyperlinks from canonical, image and other relationships |
Source, Destination | Identify the actual directed edge |
Anchor, Follow | Inspect descriptions and follow status |
Status Code | Separate direct success from redirects |
Link Position, Link Path | Check content placement against its XPath |
Link Origin | Compare source HTML with rendered discovery |
Link positions are classified using customizable XPath rules, so inspect examples before trusting every Content label. A template can fool a classification rule without fooling a human looking at the page.
Check the Sitemaps tab for Orphan URLs. GA and GSC orphan discovery also requires Crawl New URLs Discovered and crawl analysis; merely connecting an account does not finish the comparison.
Search Console supplies a cross-check, not the complete graph
Within Search Console's Links report, open the internal-links Top linked pages report and inspect the Top internally linked pages table. Important service pages should appear sensibly represented, but identical counts can hide very different link placements.
The Links report documentation describes sampled data, canonical grouping and combined duplicates. Individual tables export up to 1,000 rows; the report may omit non-indexed or deduplicated URLs, retain removed links, and provides neither internal anchor text nor nofollow status. An absent URL therefore cannot establish orphanhood.
Export an actionable per-page table
Export Bulk Export > Links > All Inlinks, retaining redirect relationship rows. Save additional known URLs one per line in urls.txt, using the same URL forms as the crawl.
This script keeps donors from every crawled internal source, including pages absent from urls.txt. Only Hyperlink rows count as donors; redirect rows support a separate reachability check.
import csv, sys
from collections import defaultdict, deque
from urllib.parse import urldefrag, urlsplit
export, inventory, homepage = sys.argv[1:]
norm = lambda u: urldefrag(u.strip())[0]
home = norm(homepage)
internal = lambda u: urlsplit(u).netloc == urlsplit(home).netloc
rows = list(csv.DictReader(open(export, encoding="utf-8-sig")))
known = {norm(u) for u in open(inventory) if u.strip()}
urls = {home} | {u for u in known if internal(u)}
links, travel, donors, content, anchors = [defaultdict(set) for _ in range(5)]
for r in rows:
    s, t = norm(r["Source"]), norm(r["Destination"])
    if not internal(s) or not internal(t) or s == t: continue
    urls.update((s, t))
    kind = r["Type"].strip().lower()
    if "redirect" in kind: travel[s].add(t)
    if kind != "hyperlink" or r["Follow"].lower() not in {"true", "yes", "1"}: continue
    code = r["Status Code"].strip()
    if not code.isdigit(): continue
    if 200 <= int(code) < 400: travel[s].add(t)
    if int(code) != 200: continue
    links[s].add(t); donors[t].add(s)
    if r["Link Position"] == "Content":
        content[t].add(s); anchors[t].add(r["Anchor"].strip())
def distances(graph):
    d, q = {home: 0}, deque([home])
    while q:
        s = q.popleft()
        for t in graph[s]:
            if t not in d: d[t] = d[s] + 1; q.append(t)
    return d
depth, via_redirects = distances(links), distances(travel)
out = csv.writer(sys.stdout)
out.writerow(["URL", "Depth", "Donors", "Content donors", "Anchors", "Flags"])
for u in sorted(urls):
    flags = []
    if u not in depth: flags.append("REDIRECT_ONLY" if u in via_redirects else "ORPHAN" if not donors[u] else "UNREACHABLE")
    if depth.get(u, 0) > 3: flags.append("DEEP")
    if len(donors[u]) == 1: flags.append("SINGLE_INLINK")
    if not content[u]: flags.append("NO_CONTENT_LINKS")
    out.writerow([u, depth.get(u, ""), len(donors[u]), len(content[u]), len(anchors[u]), "|".join(flags)])
Run it as python3 -I link_audit.py all_inlinks.csv urls.txt https://example.com/ > audit.csv. Normalize hostnames and trailing-slash conventions before comparing inventories, and review non-indexable destinations separately.
A page receiving links only through a 301 redirect looks unreachable in the direct-link calculation. With redirect relationships retained, it receives REDIRECT_ONLY, not ORPHAN; without those rows, that distinction cannot be established. The script skips self-links and computes no PageRank-like score, leaving relative scoring to Screaming Frog's Link Score.
The depth and single-donor flags are inspection prompts. NO_CONTENT_LINKS is expected for some utility pages; it warrants attention when attached to a core service that receives only menu links.
Once the audit identifies orphaned services, navigation-only money pages and generic anchors, the work is a graph rebuild tied to page purpose. Iron Goo's SEO service for rebuilding page relationships and contextual links addresses that combination.
Check JavaScript-only links before trusting the crawl
Inspect the original page source for an actual anchor with an href. Google can extract ordinary HTML links; script-driven controls without that markup are unreliable discovery paths.
<a href="/services/maintenance/">commercial maintenance</a>
Screaming Frog's Link Origin values are HTML, Rendered HTML, HTML and Rendered HTML (both), and Dynamically Loaded. Investigate primary navigation found only after rendering, and compare it with View Source, not only the browser's Elements panel.
Vercel and MERJ reported on 17 December 2024 that none of the major AI crawlers they examined rendered JavaScript. That dated observation gives another reason to serve key links in HTML, without assuming every crawler's behavior remains fixed.
If your CMS cannot produce crawlable anchors or editable contextual links, an AI-readable website foundation addresses the template constraint. Adding more destinations to an invisible menu leaves the underlying problem intact.
Turn the findings into a fixed state
For hypothetical Northfield Maintenance, scenario C becomes the chosen architecture, with reader-driven exceptions allowed. The modeled percentages remain illustrative; the acceptance checks are things someone can actually inspect.
| Starting problem on the hypothetical site | Accepted fixed state | Verification |
|---|---|---|
| Posts repeatedly promote the newest articles | Relevant service and sibling destinations | Inspect post links by subject |
| Core services depend on header links | Relevant body-copy routes supplement navigation | Content donor count and manual review |
| A service loses most header exposure | All five core services retain header access | Crawl templates and homepage paths |
| A service has zero inbound links | A relevant page links directly to it | No orphan flag; source anchor visible |
| Generic service anchors | Wording identifies the destination's purpose | Review anchor export in context |
Select donors using Search Console's Performance report, Pages view, with the last three months selected and pages sorted by clicks. Exclude the homepage and inspect the top ten click-earning URLs for natural opportunities to link to each service.
This is a hypothesis informed by onsiteProminence, not a proven donor ranking. For each candidate, record the source URL, destination, existing paragraph and proposed anchor; reject links that require inventing a connection between unrelated subjects.
A hypothetical inspection article could link to the maintenance service when explaining who performs the inspection. Use wording that names that service, with enough surrounding explanation to justify the destination. Repeating the same useful service name is acceptable; forced variation is not an editorial achievement.
If a target remains Crawled - currently not indexed, Google has already fetched it. Internal links may clarify its role, but they do not guarantee indexing or repair an indistinct page; repeated submission is not the prescribed response to that status.
Record each changed source and destination with its deployment date. Review destination indexing and Search Console clicks after four to eight weeks, keeping donor-page changes visible too; on a small site, low traffic and unrelated ranking changes can make the result inconclusive. Retain useful reader paths even when the traffic data cannot isolate their effect.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.