Entity SEO reference for IDs, attributes and schema

On this page
SEO
Entity SEO is the work of making a named thing unambiguous to search systems: in Google's Knowledge Graph, think of an entity as a node with a stable machine ID, a type and attribute values. The non-obvious consequence is that the ID carries identity, so your words, markup and outside references should resolve to one entity with consistent facts. Google's phrase was “things, not strings,” but strings still matter: they are how a query or page points to the thing.
Entity SEO quick reference
| Term | What it is | Exact format or value | The trap |
|---|---|---|---|
| Entity | An identifiable thing | A person, organization, place, product or concept | A repeated phrase does not establish identity |
| Knowledge Graph | Google's database of entities and facts | Over 500 billion facts about five billion entities, reported on 20 May 2020 | This dated figure is not a current inventory |
| Knowledge Graph MID | A machine identifier for an entity | /m/0dl567 | A name can change while identity stays the same |
/m/ ID | An identifier from the Freebase family | Wikidata property P646 | Wikidata stores it separately from /g/ |
/g/ ID | A Google Knowledge Graph identifier family | Wikidata property P2671 | Not every MID starts with /m/ |
kg: | A JSON-LD prefix in Google's sample | Expands to http://g.co/kg | It is not part of the bare MID |
| Knowledge Graph lookup | A search constrained to an ID | ids=/m/0dl567 | Finding a match does not expose its surrounding graph |
resultScore | Match quality for the request constraints | Google's sample returns 4850 | It is not entity authority |
| Wikidata reverse lookup | A free cross-check between identifiers | P646 or P2671 to a Wikidata item | An absent mapping does not prove Google lacks the entity |
| Entity analysis | Extraction of entities from document text | documents:analyzeEntities | API version changes the returned fields |
salience | Document-level entity centrality | v1 value from 0 to 1.0 | It is not a documented Search ranking score |
metadata.mid | An available Knowledge Graph MID | v1 metadata may contain /m/ or /g/ | Availability is conditional |
| v2 mention probability | Probability associated with a mention | A field on v2 mentions | It does not replace document salience |
| EAV triple | Entity, attribute and value | Subject, predicate, object | The value may be another entity |
| Root attribute | A defining field for a chosen class | Internal dimensions for a cold room | This is a content-design convention |
| Rare attribute | A characteristic of some class members | Blast-chilling capability | Rarity alone does not justify a page |
| Unique attribute | An entity-specific distinguishing fact | A proprietary system name | A warranty duration alone may be shared |
sameAs | A URL identifying the same thing | Reference-page URL | A relevant page is not necessarily an identity match |
about | The subject matter of an object | A Thing value | Every named entity is not a subject |
mentions | A reference within a creative work | A Thing value | A reference need not be the subject |
additionalProperty | A characteristic without a matching schema property | A PropertyValue | Invalid on plain Organization and Service |
| Knowledge panel claim | Verification for an existing panel | “Claim this knowledge panel” | Claiming does not create a panel |
Knowledge Graph identities and cross-checks
Knowledge Graph: entities with facts and relationships
The Knowledge Graph is Google's system for representing entities and facts about them. At its launch on 16 May 2012, Google reported more than 500 million objects and more than 3.5 billion facts and relationships.
On 20 May 2020, Google reported over 500 billion facts about five billion entities. Its explanation names material shared across the web, open-source databases and licensed databases among the sources; structured markup also supplies information. These are Google's dated size figures and explanation of its sources, not a live count.
A company does not control the complete graph entry through its website. Your practical task is to publish explicit facts, keep identity references consistent and make conflicting values easy to detect.
MID, /m/, /g/ and the kg: prefix
A Knowledge Graph MID is a machine identifier used to refer to an entity independently of its display name. /m/ identifiers belong to the Freebase family; Wikidata distinguishes these from Google's /g/ identifiers.
The useful operational distinction is where to look them up. Wikidata uses P646, Freebase ID, for /m/ values and P2671, Google Knowledge Graph ID, for /g/ values. Describing all /g/ entities as newer is an inference from their origin, not a reliable creation-date test.
Google's documented JSON-LD sample defines kg as http://g.co/kg. Consequently, kg:/m/0dl567 expands to http://g.co/kg/m/0dl567; the bare identifier remains /m/0dl567.
For a manual inspection, the search URL is https://www.google.com/search?kgmid=/m/0dl567. Treat the resulting search presentation as an inspection aid, not proof that your own site has been associated with that ID.
Wikidata: a free identifier cross-check
Wikidata is an independently maintained knowledge base that can connect a Google identifier to a named item. On 24 October 2026, we ran this reverse lookup through Wikidata Query Service without a Google API key:
SELECT ?item ?itemLabel WHERE {
  { ?item wdt:P646 "/m/0dl567" } UNION { ?item wdt:P2671 "/m/0dl567" }
  SERVICE wikibase:label { bd:serviceParam wikibase:language "en". }
}
It returned exactly one row:
| item | itemLabel |
|---|---|
http://www.wikidata.org/entity/Q26876 | Taylor Swift |
The union checks both identifier properties, although this particular /m/ identifier belongs in P646. A separate Wikidata API check confirmed P646 = /m/0dl567, matching Google's documented example.
We also ran the following count query, then repeated it with P646:
SELECT (COUNT(*) AS ?n) WHERE {
  ?item wdt:P2671 ?id
}
The counts were 8,180,418 P2671 values and 4,470,203 P646 values. That is about 8.2 million /g/ IDs and 4.5 million /m/ IDs recorded on Wikidata, counted on 24 October 2026; neither number measures the size of Google's graph.
The identity can agree across systems even when the identifier formats differ. Wikidata provides an independent cross-check; a Natural Language v1 MID is available only when the API returns one.
Knowledge Graph Search API requests and scores
Knowledge Graph Search API: individual matching entities
The Knowledge Graph Search API finds individual entities matching a request and returns JSON-LD using schema.org types. It does not return a connected neighborhood of graph nodes.
We had no Google Cloud API key or suitable OAuth token available for these checks. On 24 October 2026, both the Knowledge Graph Search API and Natural Language API returned HTTP 403 when called without credentials, with this exact message:
"Method doesn't allow unregistered callers (callers without established identity). Please use API Key or other form of API consumer identity to call this API."
The Google API requests and responses shown here are documented examples, not successful authenticated runs by us. The Wikidata results are the queries we actually ran on that date.
Google's documented Knowledge Graph request is:
https://kgsearch.googleapis.com/v1/entities:search?query=taylor+swift&key=API_KEY&limit=1&indent=True
The response below is Google's documented sample, trimmed: the image object and detailedDescription object were removed. Its score belongs to that sample.
{
  "@context": {
    "@vocab": "http://schema.org/",
    "goog": "http://schema.googleapis.com/",
    "resultScore": "goog:resultScore",
    "detailedDescription": "goog:detailedDescription",
    "EntitySearchResult": "goog:EntitySearchResult",
    "kg": "http://g.co/kg"
  },
  "@type": "ItemList",
  "itemListElement": [
    {
      "@type": "EntitySearchResult",
      "result": {
        "@id": "kg:/m/0dl567",
        "name": "Taylor Swift",
        "@type": ["Thing", "Person"],
        "description": "Singer-songwriter",
        "url": "http://taylorswift.com/"
      },
      "resultScore": 4850
    }
  ]
}
Request parameters: defaults and constraints
Request parameters determine which entities the API considers and how many matches it returns. The Knowledge Graph Search API reference specifies these controls:
| Parameter | Meaning or behavior |
|---|---|
query | Text to search for |
ids | Identifier lookup; repeat as ?ids=A&ids=B |
languages | Language codes using ISO 639 |
types | Restrict to schema.org types, such as Person |
limit | Default 20; maximum 500; high limits increase timeout risk |
prefix | Prefix matching, so Jung can match Jungle |
indent | Format the response for readability |
Once you have an identifier, a documented ID lookup avoids relying on a name alone:
https://kgsearch.googleapis.com/v1/entities:search?ids=/m/0dl567&key=API_KEY
We could not run that authenticated lookup without a key. Check the returned type and official website as well as the name before accepting any match.
resultScore: request match quality
resultScore indicates how well an entity matches the request constraints. It is not a measure of authority, popularity or readiness to rank.
A score attached to a broad name search is not meaningfully comparable with one attached to a tightly constrained request. Keep the query, language and type filters fixed if you are comparing results; there is no documented SEO target score to optimize.
Enterprise Knowledge Graph: the successor service
Google says it is migrating the Knowledge Graph Search API to Cloud Enterprise Knowledge Graph and tells new users to use that product instead. Google's warning about the older API is explicit: it is unsuitable for production-critical use.
The Enterprise Knowledge Graph search documentation describes Basic and Advanced services with OAuth bearer authentication. Basic uses publicKnowledgeGraphEntities; Advanced uses cloudKnowledgeGraphEntities, and Google recommends Advanced for new projects.
Its response adds identifiers such as googleKgMID; Advanced can also return wikidataQID and googlePlaceID. The documentation describes Preview terms and limitations, so assess those before making a business process depend on it.
Natural Language entity analysis and salience
Entity analysis: entities extracted from one document
Entity analysis identifies entities in supplied text and returns information about their mentions. In v1, an entity can include its type, a salience score and metadata containing a Knowledge Graph MID when available.
This v1 curl request uses Google's documented input sentence and request structure. It requires working application-default credentials:
curl -s -X POST "https://language.googleapis.com/v1/documents:analyzeEntities" \
  -H "Authorization: Bearer $(gcloud auth application-default print-access-token)" \
  -H "Content-Type: application/json; charset=utf-8" \
  -d '{"document":{"type":"PLAIN_TEXT","content":"President Trump will speak from the White House, located at 1600 Pennsylvania Ave NW, Washington, DC, on October 7."},"encodingType":"UTF8"}'
PLAIN_TEXT supplies extracted text; HTML is also supported. Language can be detected automatically when you omit the language field, and each request analyzes one document.
Salience: centrality within the supplied text
Salience is a v1 score from 0 to 1.0 expressing an entity's importance or centrality to the whole document. Google's documented example returns these values:
| Entity | Type | MID when supplied | Salience |
|---|---|---|---|
| Trump | PERSON | /m/0cqt90 | 0.7936003 |
| White House | LOCATION | /m/081sq | 0.09172433 |
| Pennsylvania Ave NW | LOCATION | /g/1tgb87cq | 0.085507184 |
| Washington, DC | LOCATION | /m/0rh6k | 0.029168168 |
| Address entity | ADDRESS | Not listed here | 0 |
| 1600 | NUMBER | Not listed here | 0 |
| October 7 | DATE | Not listed here | 0 |
| 7 | NUMBER | Not listed here | 0 |
The person who is the grammatical subject receives about 8.7 times the next entity's score in this sample. It also demonstrates both /m/ and /g/ MIDs in one analysis; neither observation establishes a universal rule for other documents.
The v2 Entity object has no salience field, and its metadata description no longer promises a Knowledge Graph MID. Google's current how-to curl uses v2, so use the v1 endpoint explicitly when your check requires salience or available MID metadata.
The v1 Entity reference documents salience and conditional MID metadata. In v2, probability belongs to mentions; reading it as document centrality changes the meaning of your measurement.
Salience research: a diagnostic proxy
Entity salience research concerns deciding which entities matter to a document. Dunietz and Gillick's 2014 Google paper on entity salience describes a classifier and reports beating a strong baseline by 34%.
The paper describes training labels derived from documents paired with abstracts, treating entities appearing in the abstract as salient. That research helps explain the task; it does not establish that today's Cloud API reproduces the paper's model or that Search uses its score.
My recommendation is to use salience as a diagnostic proxy for the apparent subject. If navigation or boilerplate dominates an extraction, inspect the input before rewriting the article; a higher Cloud API score is not a documented ranking objective.
Quotas and cost: count characters per request
Natural Language quotas limit document size and request volume independently. The published limits are 1,000,000 bytes per request, 100,000 tokens and 5,000 entity mentions, with pronoun references counting toward the mention limit.
Exceeding the byte limit produces an error; excess tokens or mentions are ignored. Published rate limits are 600 requests per minute and 800,000 per day, so keep both document-size checks and request throttling in a batch process.
Prices were read on 24 October 2026. Entity Analysis is free for the first 5,000 monthly units, then costs $1.00 per 1,000 units in the first paid tier. One unit is 1,000 Unicode characters, making the price $0.001 per unit; whitespace and HTML markup count.
The Natural Language pricing page has an ambiguous table header, so keep billing units separate from character counts. Its example of 800, 1,500 and 600 characters is worded for Sentiment Analysis and totals four units because partial units round up per request. The same unit rule applies to Entity Analysis.
units_per_request = ceil(unicode_characters / 1000) monthly_units = sum(units_per_request) paid_units = max(0, monthly_units-5000) monthly_cost_usd = paid_units * 0.001
Assume you send 1,000 pages containing exactly 9,000 Unicode characters each, with no other monthly usage. Each request costs nine units, so 9,000 total units leave 4,000 paid units: $4.
The free allowance covers 555 complete requests of that size, leaving five units. Higher-volume tiers fall to $0.50 per 1,000 units after one million units and $0.25 beyond five million; the formula above applies only within the first paid tier.
EAV triples and attribute-driven page design
EAV: entity, attribute and value
Entity-attribute-value, or EAV, is a way to express a fact as a subject, predicate and object. The subject identifies the entity, the predicate identifies the relationship or attribute, and the object supplies a literal value or another entity.
Google's Freebase dump documentation provides this real triple:
<http://rdf.freebase.com/ns/g.11vjz1ynm> <http://rdf.freebase.com/ns/measurement_unit.dated_percentage.date> "2001-02"^^<http://www.w3.org/2001/XMLSchema#gYearMonth> .
The final object is a typed year-month value. The punctuation belongs to RDF serialization; the reusable design idea is that every fact has an explicit subject and an explicit relationship.
For page planning, a spreadsheet can hold the same structure without RDF syntax. Add a source and an owner for each value so specifications can be corrected without searching every paragraph manually.
Root, rare and unique attributes: a content-design convention
Root, rare and unique attributes are practitioner labels for deciding where facts belong in content. They are a content-design convention, not Google terminology or documented ranking categories.
A root attribute is a field every member of your chosen class needs to be described. For a walk-in cold room, that includes internal dimensions and temperature range; the field is shared even when the values differ.
A rare attribute occurs in some members of the class and separates meaningful subtypes. Blast chilling or pharmaceutical temperature mapping can support a comparison or specialist requirement.
A unique attribute distinguishes the particular entity through an entity-specific fact. Apply the label carefully: a proprietary system name may be unique, while a ten-year warranty or a founding year can be shared by unrelated companies.
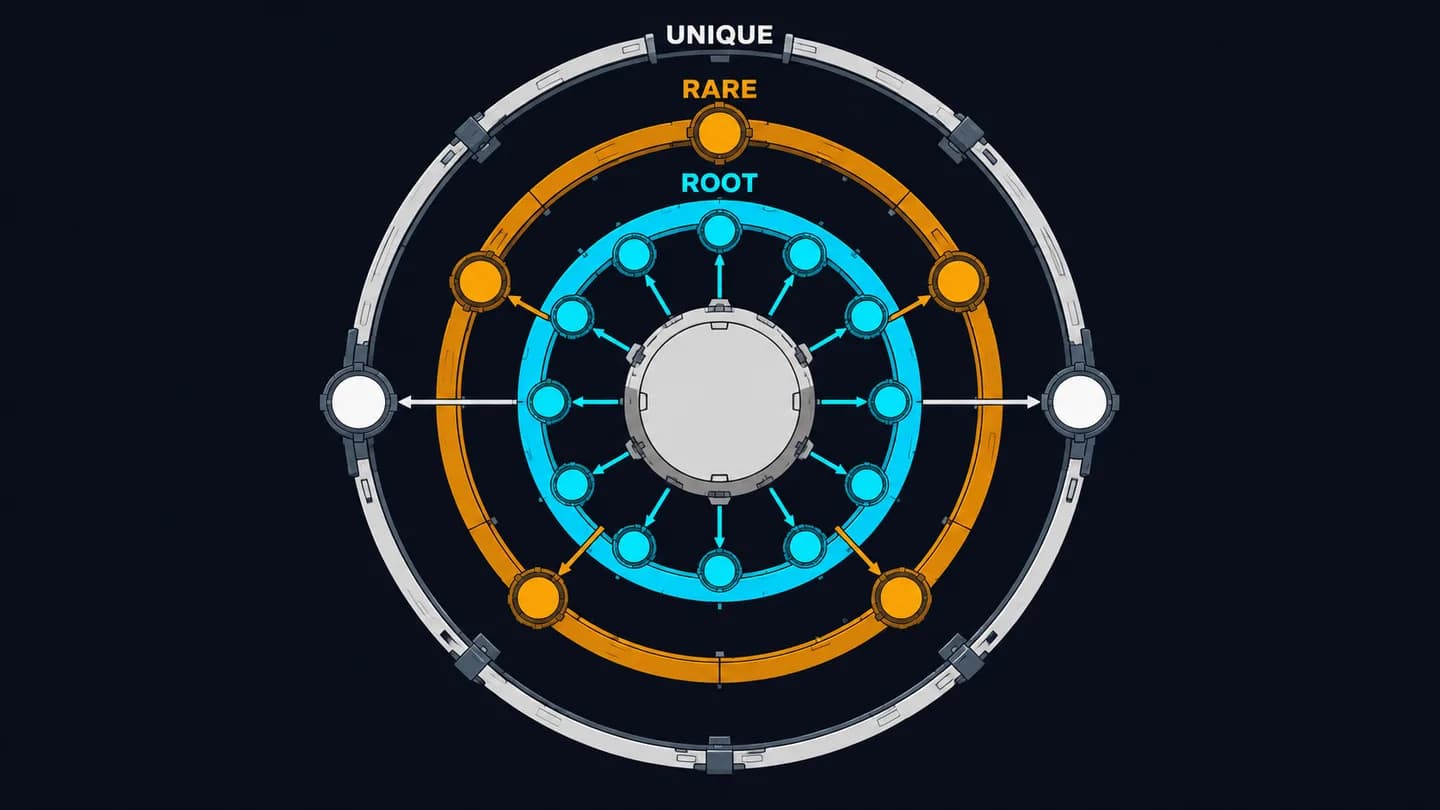
Root fields describe every member of the chosen class, rare fields identify some members, and unique facts distinguish the entity. Each branch still has the same entity, attribute and value structure.
Query-log attributes: evidence for demand-based decisions
Query-log attribute ranking is a patented mechanism for discovering which facts people request about entities. Google's US Patent 9,047,278, granted on 2 June 2015, describes splitting queries into an entity portion and an attribute suffix.
The mechanism counts requests for an attribute both for the individual entity and across entities of its type. A patent shows a mechanism exists; it does not establish its present deployment or ranking weight.
Google's Biperpedia research supplies a related class-level view. Its ontology contained 1.6 million class-attribute pairs and 67,000 distinct attribute names, extracted first from query streams and then text, with synonyms and text patterns retained.
My interpretation is that root fields resemble attributes with broad type-level demand, while rare attributes serve narrower demand. That is a planning analogy, not a claim that Google's systems use these three labels.
| Attribute situation | Publishing decision | Observable check |
|---|---|---|
| Required to describe every item of this type | Template field | Every relevant item has a labeled value |
| Applies to a subset, with limited independent demand | Section | The section answers a distinct requirement |
| Applies to a subset and has its own query demand | Separate page | The page resolves an independent search intent |
| Distinguishes the entity itself | Entity home or About page | The canonical fact agrees across references |
When a rare attribute has independent demand, use it as an input to building a topical map. For a product catalog, the root value belongs on each product page; a separate educational page still needs its own question to answer.
A hypothetical company's EAV table
An EAV table is a working inventory of facts before they become prose or markup. Assume Northfield Cold Rooms is a hypothetical 40-person manufacturer and installer, and every product value below is invented solely for this example.
| Entity | Attribute | Hypothetical value | Class | Placement |
|---|---|---|---|---|
| CR-80 cold room | Internal dimensions | 3,000 × 4,000 × 2,500 mm | Root | Product specification |
| CR-80 cold room | Temperature range | -25 to +10 °C | Root | Product specification |
| CR-80 cold room | Panel thickness | 100 mm | Root | Product specification |
| CR-80 cold room | Refrigerant | R290 | Root | Product specification |
| CR-80 cold room | Price | Quote after site survey | Root | Visible pricing explanation |
| CR-80 cold room | Pharmaceutical temperature mapping | Optional | Rare | Qualification section |
| CR-80 cold room | Panel system | Northfield SealCore | Unique | Product identity description |
| CR-80 cold room | Panel warranty | 10 years | Entity-specific | Warranty terms |
| Hypothetical manufacturer | Service area | A defined regional territory | Entity-specific | Company home |
“Quote after site survey” describes the pricing process, not a numeric price. Likewise, a regional territory must be replaced with its actual boundaries before publication.
Covering related attributes across pages can support topical authority through connected coverage. Each page still needs a distinct job, with links connecting the product to the relevant technical explanation.
Schema properties for identity and attributes
sameAs: identity, not topical relevance
sameAs is a URL reference that unambiguously identifies the same item. Schema.org defines it as “URL of a reference Web page that unambiguously indicates the item's identity,” with Wikipedia, Wikidata and official websites among its examples.
The property applies to Thing, and schema.org reports usage on 10M+ domains. A page discussing refrigeration does not identify a refrigeration company merely because their topics overlap.
Use official profiles or verified reference entries for the entity you are describing. Putting a kgmid search URL in sameAs is a practitioner habit with no documented Google benefit; a clear reference page gives you a better-supported identity assertion.
about and mentions: subject versus reference
about identifies the subject matter of an object, while mentions identifies a reference within a creative work. Schema.org's exact definition of about is “The subject matter of an object.”
For mentions, the definition is “Indicates that the CreativeWork contains a reference to, but is not necessarily about a concept.” Both expect Thing values, but their relationships differ.
Schema.org reports about on 10M+ domains and mentions on 10K to 100K domains. These are vocabulary usage bands, not evidence that one property improves rankings.
Suppose the hypothetical Northfield Cold Rooms publishes an article about Google's Knowledge Graph and refers to Google as the organization behind it. This illustrative Article block separates the subject from that reference:
{
  "@context": "https://schema.org",
  "@type": "Article",
  "headline": "Google Knowledge Graph identifiers explained",
  "about": {
    "@type": "Thing",
    "name": "Google Knowledge Graph",
    "sameAs": "https://www.wikidata.org/wiki/Q648625"
  },
  "mentions": [
    {
      "@type": "Organization",
      "name": "Google",
      "sameAs": "https://www.wikidata.org/wiki/Q95"
    }
  ]
}
Keep about focused on the actual subject; one or two values is a useful editorial constraint. Google documents no Article rich-result feature driven by these properties, so treat their purpose here as describing relationships.
additionalProperty: characteristics without a dedicated property
additionalProperty represents an extra characteristic for which schema.org has no matching property. Its exact definition is “A property-value pair representing an additional characteristic of the entity, e.g. a product feature or another characteristic for which there is no matching property in schema.org.”
Schema.org reports usage on 100K to 1M domains. The additionalProperty definition and domain list permits it on MerchantReturnPolicy, Offer, Place, Product, QualitativeValue and QuantitativeValue.
Plain Organization and Service are absent from that list. LocalBusiness inherits from both Organization and Place, which makes it a valid case through Place.
For the hypothetical Northfield Cold Rooms product, the following block uses the dedicated depth property and puts the remaining characteristics into PropertyValue objects. All values remain illustrative:
{
  "@context": "https://schema.org",
  "@type": "Product",
  "name": "Northfield CR-80 walk-in cold room",
  "brand": {
    "@type": "Brand",
    "name": "Northfield Cold Rooms"
  },
  "depth": {
    "@type": "QuantitativeValue",
    "value": 3000,
    "unitCode": "MMT"
  },
  "additionalProperty": [
    {
      "@type": "PropertyValue",
      "name": "Temperature range",
      "minValue": -25,
      "maxValue": 10,
      "unitCode": "CEL"
    },
    {
      "@type": "PropertyValue",
      "name": "Panel thickness",
      "value": 100,
      "unitCode": "MMT"
    },
    {
      "@type": "PropertyValue",
      "name": "Refrigerant",
      "value": "R290"
    }
  ]
}
MMT means millimeter and CEL means degree Celsius in UN/CEFACT Common Codes. PropertyValue supports fields including propertyID, value, minValue, maxValue, unitCode and unitText; use a specific schema property whenever one exists and you can populate it.
Validate vocabulary usage at validator.schema.org, then check Google's requirements separately. Choosing schema types and eligible rich results comes before filling a page with extra properties.
Once the attribute inventory is settled, site-wide SEO implementation turns those facts into template fields, useful sections and consistent markup. Keep each field tied to its visible source so a specification change reaches every published representation.
Knowledge panels and verification
Knowledge panel: an automatically generated presentation
A knowledge panel is an automatically generated presentation of information about an entity. Adding structured data does not provide a documented switch that creates one.
Google's Organization documentation says homepage Organization markup can help Google understand your organization's administrative details and disambiguate your organization, and can influence elements such as logos. That makes accurate identity data useful without making a panel an entitlement.
Claiming a panel: verification of an existing entity
Claiming a knowledge panel is Google's procedure for verifying a representative of an entity whose panel already exists. Google notes that not all panels can be claimed yet, and local businesses use Google Business Profile.
Follow the knowledge panel verification procedure:
- Find the existing panel and select “Claim this knowledge panel.”
- Sign in and authenticate through one of the official sites or profiles Google offers, such as Search Console or YouTube.
- After verification, submit corrections through Feedback with source links.
- Assign Owner, Manager or Contributor roles according to the access each representative needs.
For a disputed fact, publish a clear source before requesting a correction. Supply the exact value and the page supporting it, so the request can be checked against evidence.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.