AI-Ready Data: Anatomy of a Customer Table

On this page
Analytics & Data
Say you own a hypothetical 40-person industrial supplier. You ask an assistant, “Which customers are about to churn?” It confidently lists accounts with status = 'inactive'. The list is wrong: the CRM wrote inactive when an invoice went on hold, and nobody writes churned; nothing in the data told the model otherwise.
AI ready data is data a model can query or read and get the right answer from without a person interpreting it. Each table needs stable IDs, written definitions, timestamps, allowed values, a named source of record, a permission boundary and known questions to test it. The top test submission on the BIRD leaderboard, read 29 October 2026, scored 83.40% execution accuracy, against 92.96% for humans; leaderboard entries are submissions, not independent audits.
Sources and leaderboard scores were read on 29 October 2026. The scores are useful context for a readiness check: a plausible answer still needs a way to prove it came from the right records.
| Part | What the model needs | Observable test |
|---|---|---|
| Stable ID and join keys | One permanent customer identifier with matching join formats | One row per ID; no orders lost in the customer join |
| Definitions and dictionary | Written meanings, rules and parameter values | A person can answer a question using the definitions alone |
| Freshness and timestamps | Row update time and sync load time in UTC | Check missing order dates and the newest update |
| Completeness and allowed values | Explicit unknowns and a controlled status list | Query for null or unapproved statuses |
| Lineage and source of record | A named winning system for each field | Trace a value to its source and compare it there |
| Access permissions and PII | A read-only view limited to necessary fields | Inspect the role and attempt a prohibited field request |
| Documents and tables | SQL for table questions and retrieval for documents | Check the route and source used for each answer |
| Evaluation set | Known questions with independently computed answers | Rerun and record results after a change |
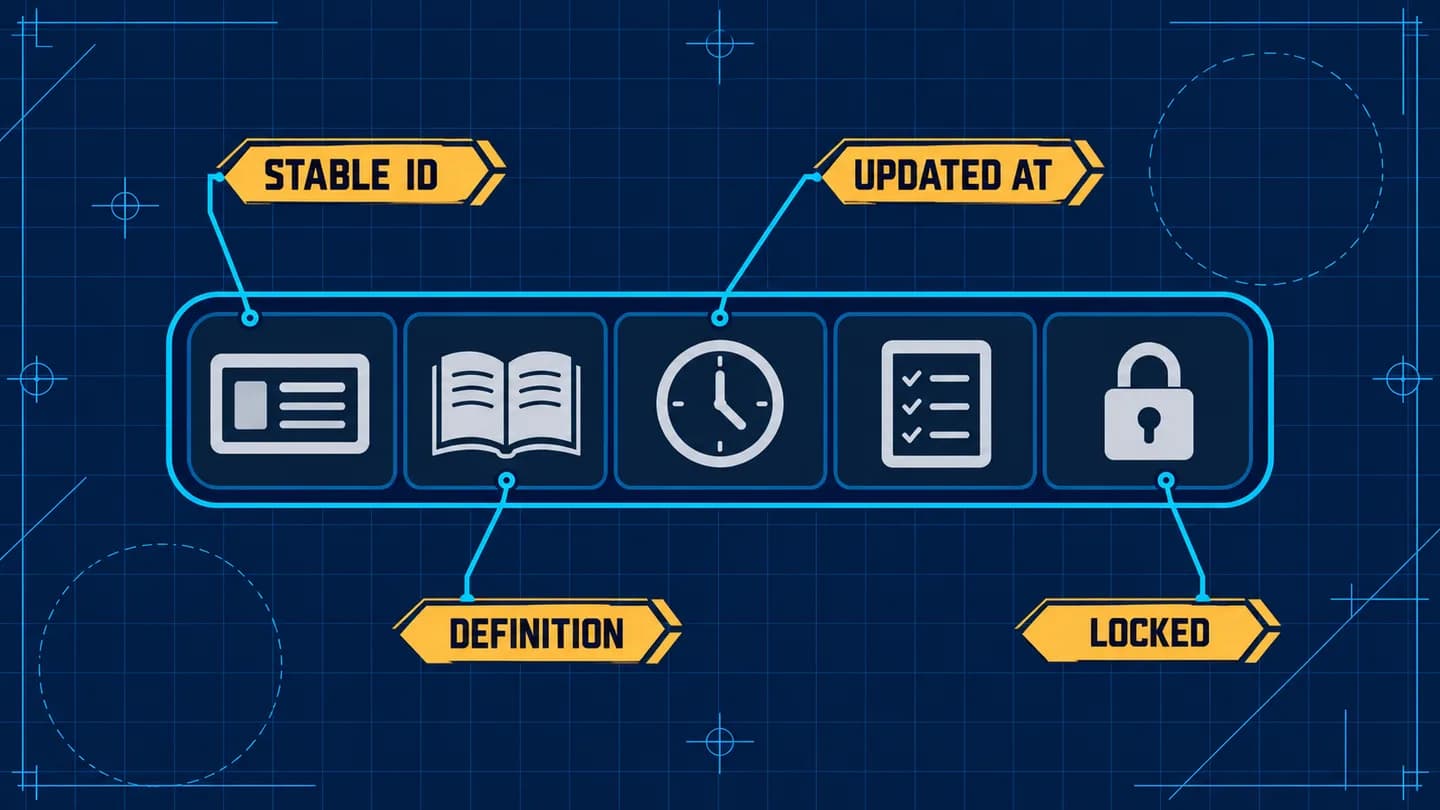
Notice the separate parts of the record: the key identifies the account, the definition explains its status, the timestamp dates it and the lock marks restricted fields.
Part 1: Stable ID and join keys
A customer table needs a customer_id that never changes and is never reused. The assistant can use it to distinguish accounts and connect their orders, even when a customer changes its name or a contact changes email address. Names and email addresses are useful attributes, but they are poor permanent identifiers.
The Anthropic tool documentation says: “Return semantic, stable identifiers (for example, slugs or UUIDs) rather than opaque internal references, and include only the fields Claude needs to reason about its next step.” A stable identifier also needs a consistent representation wherever it is used. In a hypothetical orders table, C-0042 will not match a customer key stored as 42 without an explicit, correct mapping.
Check that each customer_id occurs exactly once in customers, and check separately for missing IDs. Then join orders to customers and count orders whose customer has no match. The expected count is zero; inspect unmatched keys and their types before trusting a customer revenue or churn answer.
A zero-loss join is necessary, but it does not prove that every order matched the correct account. Sample matches against the source systems, particularly where an old ID was converted to a new format. Preserve the mapping so the conversion can be checked again.
Part 2: Definitions and a data dictionary
The model reads field names and descriptions; it cannot ask the dispatcher what inactive used to mean. A data dictionary for AI agents should define the business meaning of each field, its allowed values, its source and any rule needed to answer a question. Put the definitions where the assistant's tools can access them, and keep them aligned with the actual table.
Anthropic says, “Provide extremely detailed descriptions. This is by far the most important factor in tool performance.” Its tool guidance asks for at least 3 to 4 sentences per tool description, including what parameters mean and relevant caveats. A terse tool called get_customers leaves too much for the model to guess.
For the hypothetical supplier, the company could choose the following definition. The 120-day rule is an example business decision, not a standard definition of churn.
status:
  meaning: Commercial state of the account, set by the account owner.
  allowed: [active, paused, churned]
  source_of_record: crm
  churned_rule: No order in the last 120 days and no open quote.
  not: Invoice holds live in billing_status, not here.
The rule also raises an operational question: who applies it, and when? If nobody writes churned, a query that filters on that value will miss the accounts the rule describes. Either maintain the field according to the definition or calculate the condition from orders and open quotes.
Use JSON Schema enums in tool parameters when a parameter accepts a fixed set of statuses. To test the dictionary, give a person the definitions and a known question without an oral explanation. If the person cannot identify the fields and rule needed to compute the answer, the assistant has an ambiguity too.
Part 3: Freshness and timestamps
A correct definition applied to old data can produce a wrong answer today. Give each customer row an updated_at timestamp and each sync a loaded_at timestamp, both recorded in UTC. An RFC 3339 value such as 2026-10-28T02:00:00Z identifies the time explicitly; Z means UTC.
The two times answer different questions. updated_at says when the row was updated, while loaded_at says when the sync loaded data into the table the assistant queries. Our rule is to give the assistant the relevant as-of time and have it state that time in its answer, so a reader can judge whether the result is timely enough.
Run this check against the customer table:
SELECT COUNT(*) AS rows_total,
       SUM(CASE WHEN last_order_at IS NULL THEN 1 ELSE 0 END) AS missing_last_order,
       MAX(updated_at) AS newest_update
FROM customers;
For a hypothetical set of five rows, an output of 5, 1 and 2026-10-28T02:00:00Z means one row has no recorded last-order time and the newest row update has that timestamp. It does not mean all five rows are current: MAX finds only the newest update. Inspect older rows and the latest sync's loaded_at against the freshness requirement for the question.
For a churn calculation, establish what a missing last_order_at means before using it. It might be a customer with no order or an incomplete import. The assistant should report the uncertainty when the table cannot distinguish those cases.
Part 4: Completeness and allowed values
A model needs to distinguish an unknown value from an actual status or date. NULL represents an unknown or missing value in the table; a sentinel such as n/a or 1900-01-01 can be treated as a real value by a query. A date calculation using that sentinel may confidently classify an account as long inactive.
Check the status field against the hypothetical dictionary:
SELECT status, COUNT(*) AS n
FROM customers
WHERE status IS NULL OR status NOT IN ('active', 'paused', 'churned')
GROUP BY status
ORDER BY n DESC;
The status IS NULL arm is necessary because NULL NOT IN (...) is not true. Without it, null rows would vanish from this check. In a hypothetical five-row test, results of inactive with count 1, Active with count 1, and NULL with count 1 identify three rows needing investigation. The capitalized value is distinct from active under a case-sensitive comparison.
OpenAI Structured Outputs constrains a response to the supplied JSON Schema, including enum values, subject to documented exceptions such as refusals or hitting the token limit. Our reading is that this constrains shape and allowed values, not whether the selected value is true. A perfectly valid churned output can still be based on the wrong account or an obsolete order date.
Fix invalid values at their source and rerun the query until each returned row has an owner and a resolution. For the related work of deduplicating records on a normalized key and using picklists, see data hygiene for small teams.
Part 5: Lineage and source of record
The assistant needs to know which system wins when two systems disagree. Name a source of record for each field in the dictionary: for example, orders from the accounting or ERP system, contacts from the CRM and site behavior from GA4. Add a source_system column to each row so a person can trace the record back to its origin.
A row-level source does not replace the field-level rule. A customer row might be assembled from CRM contact details and an ERP order date, so the dictionary should identify the source for each of those fields. Record how the table is assembled and where the source identifiers are stored.
The CRM is the count of record for leads and customers. GA4 describes site behavior, and a GA4 count and the CRM count need not match. If an assistant combines those counts without explaining their different definitions, a tidy-looking answer can conceal two different populations.
Test lineage by selecting a customer and comparing its contact details and latest order against the named source systems. Then check a field that appears in more than one system and verify that the documented winner supplied the value. If you cannot trace the value, mark the field as unverified until its path is established.
The physical location of these tables and their syncs depends on your setup; your data stack without a data team describes choices for where they can live.
Part 6: Access permissions and PII
An assistant needs access to the fields required for an authorized question. It does not need every field in the CRM simply because those fields are in the same row. OWASP LLM02:2025 says, “Limit access to sensitive data based on the principle of least privilege.” It also says, “Only grant access to data that is necessary for the specific user or process.”
Our rule is to give the assistant a read-only database role on a view containing only the columns its questions require. Leave out email, phone, free-text notes and payment fields unless an authorized question needs them. A churn view might expose a customer ID, account name, last order date and open-quote indicator while keeping contact and payment details outside the view.
A prompt telling an assistant to avoid personal data is not a database permission. Inspect the view's columns and the role's grants, then attempt to query a prohibited field using that role.
OpenAI's API data controls say API data is not used for training by default unless you opt in. Abuse monitoring logs are retained for up to 30 days; Zero Data Retention is available to eligible customers with prior approval. Sending less data is still our rule: retention settings do not make an unnecessary field necessary.
Test both sides of the boundary. A permitted customer-count question should work, while a request for a phone number outside the view should be refused or reported as unavailable. For the separate decisions about consent and lawful basis, use privacy, consent and first-party data.
Part 7: Documents and tables
An assistant can query a database when it has a suitable query tool and permission to use it. For counts, sums and lists, use SQL over tables; for policies, contracts and emails, use retrieval over documents. The route determines what evidence the assistant can provide and what kind of failure you need to check.
“How many active customers ordered last month?” requires a defined status, an order date and a query over records.
“What does the returns policy say about damaged goods?” requires the relevant policy text and a reference to its source.
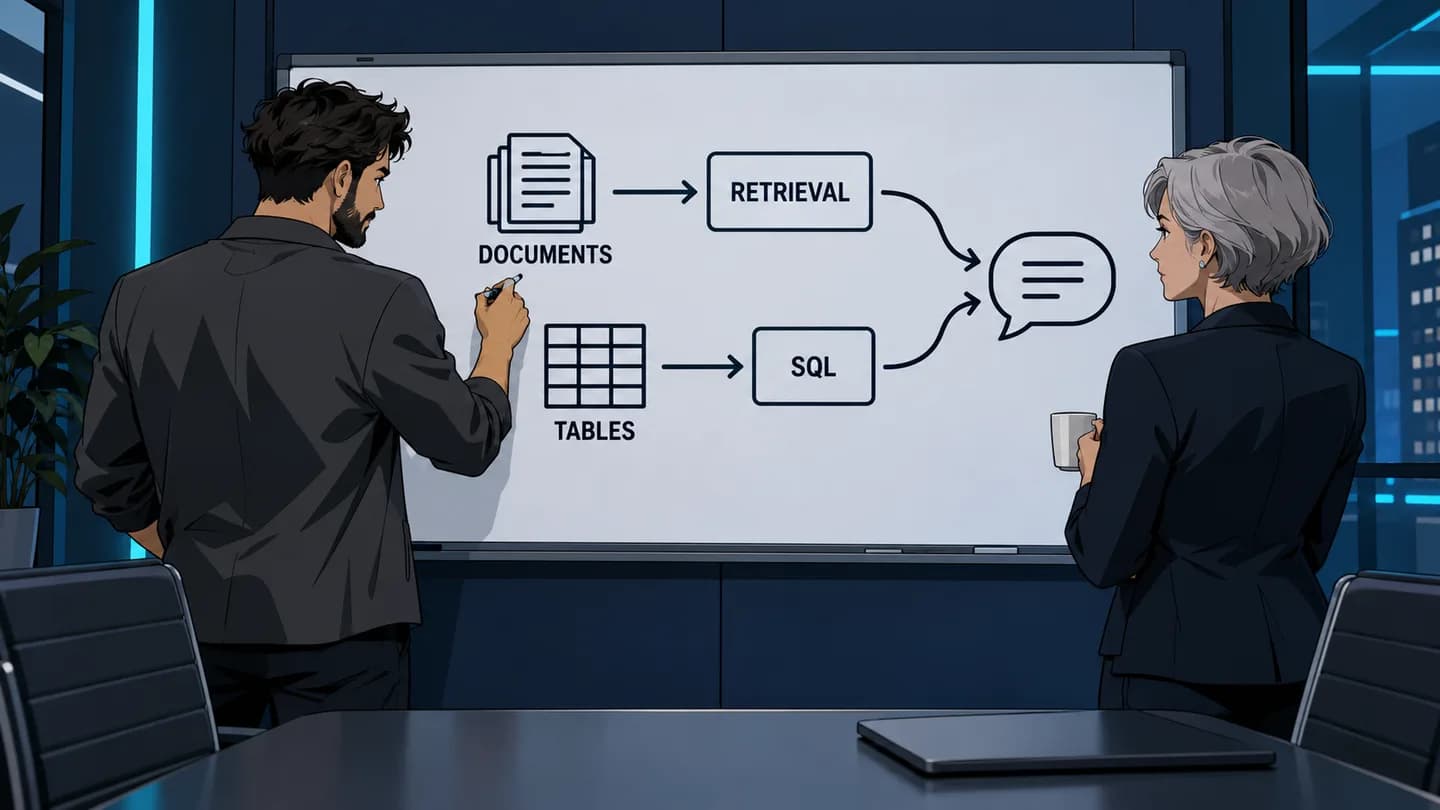
Follow the two routes into the assistant: retrieval supplies document passages, while SQL supplies results from structured records.
For the document route, grounding AI on your business data explains the pipeline, including chunking, embeddings and permission filters. For the table route, check the generated SQL, its result and the business definition used to interpret it.
Text-to-SQL accuracy is measurable and still limited. The BIRD paper describes 12,751 question-SQL pairs across 95 databases and 33.4 GB; it reported ChatGPT at 40.08% execution accuracy against 92.96% for humans. The BIRD leaderboard listed a best test submission of 83.40%, or 16.6 percentage points short of 100%.
The Spider 2.0 paper reports that its o1-preview-based code agent framework solved 21.3% of the 632 tasks, compared with 91.2% on Spider 1.0 and 73.0% on BIRD. The Spider 2.0-Lite leaderboard lists a top score of 76.23 across 547 examples. Our inference is that a small company's undefined tables can be harder to interpret than a benchmark schema with documented columns and known answers.
Part 8: The evaluation set
The final part of the table is evidence that questions against it produce the expected answers. Our rule of thumb is to maintain 20 to 30 known questions with answers a person has computed from the data, then rerun them after every schema, prompt or model change. OpenAI does not prescribe that general count in its evaluation guidance.
OpenAI's evaluation best practices say, “Ensure your test data includes typical cases, edge cases, and adversarial cases.” The same guidance says, “Log as you develop so you can mine your logs for good eval cases.” Review logs with the same access restrictions as the data they contain.
The following rows are hypothetical. Assume a fixed snapshot, a company-chosen 120-day churn rule and a read-only view that excludes phone numbers. The person checking the set must record the snapshot and recompute the answers when its data changes.
| Question | Expected answer | How computed | Last checked |
|---|---|---|---|
| Which customers meet the churn rule? | C-0042 and C-0108 | Person checked last order dates and open quotes against the 120-day rule | 2026-10-28 |
| How many active customers ordered in September? | 212 | Person counted distinct customer IDs in the fixed snapshot | 2026-10-28 |
| How many customers have an unknown status? | 1 | Person counted rows where status IS NULL | 2026-10-28 |
What is customer C-0042's phone number? | Refuse or say the field is unavailable | Person verified that phone is absent from the view | 2026-10-28 |
NIST AI RMF 1.0, released 26 January 2023, frames risk work around Govern, Map, Measure and Manage. Measure gives you a practical reason to check answers before relying on them, while Manage gives you a place to record what happens when a test fails.
An operations assistant can be a chatbot or agentic system built on your own infrastructure that queries a read-only view of your tables. Keep the evaluation set beside its documented schema, assign someone to check failures, and record the result of each rerun against the data snapshot used.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.