Common Data Analysis Mistakes: 12 Ways Numbers Fool You

On this page
- 1. A small sample looks like a real change
- 2. A calendar pattern looks like campaign impact
- 3. Two tools give different answers to the same question
- 4. The denominator changes and the rate jumps
- 5. An extreme week returns toward normal
- 6. A correlation gets promoted to a cause
- 7. One large order distorts the average
- 8. Repeated early checks produce a false A/B winner
- 9. One slice wins after enough comparisons
- 10. The missing cases create a survivorship story
- 11. The overall rate reverses the segment comparison
- 12. GA4 withholds rows or samples a large report
- Triage checks for a suspicious number
Analytics & Data
At Google and Bing, only about 10% to 20% of experiments generate positive results. That is the figure reported by Ron Kohavi and Stefan Thomke in Harvard Business Review; they also report that Microsoft experiments as a whole split roughly into thirds: effective, neutral and negative, a story discussed in decisions, not dashboards. Our inference is that an unplanned jump on a small company's dashboard deserves suspicion first. Common data analysis mistakes include treating small samples as proof, comparing different weekdays and assuming two tools count the same event.
The order here is our judgement of how often these failures appear in a small company's reports. Sources were read on 29 October 2026.
1. A small sample looks like a real change
Symptom. Your report shows 12 conversions this week after nine last week, and the increase looks large enough to justify changing the budget. The percentage increase is real arithmetic, but it does not tell you whether the underlying conversion rate changed.
Cause. Counts move even when the process producing them stays steady. As a rough rule for counts, the typical swing is the square root of the count: 16 leads a month swings by about four, so 12 or 20 is ordinary. The small-business analytics guide explains that rule and the interval arithmetic for a rate.
Confirm. Say, hypothetically, that a page gets 300 visits each week and its true conversion rate is 3%. It expects nine conversions. The square root of nine is three, giving an ordinary rough band of six to 12 conversions in a week.
expected conversions = 300 visits × 0.03 = 9 rough swing = sqrt(9) = 3 rough band = 9 minus 3 to 9 + 3 = 6 to 12
A week with nine followed by a week with 12 sits inside that band. This shortcut is a sense check, not a formal significance test, and it assumes the underlying conditions are reasonably stable.
Fix. Collect more observations before declaring a winner, and record both visits and conversions for each period. If you need an interval for the rate, use the normal-approximation (Wald) interval described in the linked guide and check whether its assumptions suit your data. A larger sample narrows uncertainty; it does not repair a broken event definition.
2. A calendar pattern looks like campaign impact
Symptom. Leads fall after a campaign change, or sales rise immediately after a new page goes live. The comparison pairs a weekday with a weekend, or a busy season with a quiet one.
Cause. The calendar affects when people research, contact suppliers and buy. Comparing Tuesday with Sunday can measure that difference even when the campaign has done nothing. A month-to-month comparison can also mix a business change with holidays, buying cycles or a different number of working days.
Confirm. Open the report's date comparison and line up the days of the week. Compare a Tuesday with earlier Tuesdays, a complete week with complete weeks, or the same period last year when seasonal context is available. Check the underlying counts as well as the rate: a comparison based on a handful of leads remains noisy even when the weekdays match.
Write down the launch date and identify which days actually received the change. If a new page went live halfway through a week, that week combines two conditions and is a poor clean comparison.
Fix. Choose a comparison period before judging the change. Use complete weeks for a weekly operating decision, and inspect the same period last year for a seasonal business where the historical data is comparable. A matched calendar removes one obvious explanation; other changes to traffic, pricing or tracking can still affect the result.
3. Two tools give different answers to the same question
Symptom. GA4 reports one number of key events, Google Ads reports another, and the CRM contains a third lead count. Someone adds the ad platform totals and concludes that more leads arrived than the sales team can find.
Cause. The tools may assign the event to different dates and apply different credit rules. Google's explanation of reporting differences states: “In Google Ads, to show which ad drove a key event, key events are reported based on ad interaction time reporting.” The page is labeled for the legacy UA to GA4 transition and says this timing effect also applies to imported GA4 events.
For Google's example, a key event on May 10 attributed to an ad click on May 5 generally appears on May 10 in Analytics and May 5 in Google Ads. The key event lookback window, attribution model and counting method, once or every time, can also change the answer.
Confirm. Pick one completed week and fill out a definition table alongside the reported counts. Ask whoever owns each tool to supply the settings; do not infer them from the number.
| Tool | Outcome counted | Date basis | Lookback and attribution | Once or every |
|---|---|---|---|---|
| GA4 | Record the key event name | Key event time | Record the configured settings | Record the method |
| Google Ads | Record the conversion action | Ad interaction time | Record the configured settings | Record the method |
| CRM | Record the lead or deal definition | Record the CRM date field | Record the source rule | Record duplicate handling |
Fix. Reconcile the largest gap first by tracing individual events or leads where the tools permit it. Ad platforms can each claim credit for the same lead, so their claims overlap. Our house rule is to use the CRM as the count of record for leads and use platform attribution to investigate contribution. A Foundation site is an example of a site built to capture events and lead sources with definitions that can be checked.
4. The denominator changes and the rate jumps
Symptom. Your conversion rate rises, but the sales team has no more leads. A rate can improve because its denominator shrank, even when the numerator did not move.
Cause. A consent banner, tag change or bot traffic can alter the sessions GA4 records. GA4 excludes known bots and spiders using Google research and the International Spiders and Bots List. You cannot disable that exclusion or see how much known bot traffic was excluded. Our inference is that bots that are not identified may still add sessions.
Without behavioral modeling, Analytics misses data for users who decline consent. Google's modeling requirements include at least 1,000 events a day with analytics_storage denied for at least seven days, and at least 1,000 daily users sending events with analytics_storage granted for at least seven of the previous 28 days.
Confirm. In a hypothetical month before and after a consent banner launch, say the CRM records 40 leads in each month while GA4 sessions fall from 2,000 to 1,400 because decliners are no longer recorded.
before: 40 leads / 2,000 sessions = 2.0% after: 40 leads / 1,400 sessions = about 2.86%
The reported rate rises while the lead count stays at 40. Check the date the rate moved against the dates of tag, consent and filter changes. Put the numerator and denominator on separate lines so a moving denominator cannot hide.
Fix. Keep a measurement change log with the date and definition of each tracking or consent change. Label a CRM-leads-per-GA4-session calculation as a cross-tool ratio, since its numerator and denominator have different collection rules. Compare lead counts and session counts separately before treating the ratio as an improvement.
5. An extreme week returns toward normal
Symptom. A strong week is followed by a weaker one, or a poor week improves immediately after an urgent intervention. It is tempting to assign the entire movement to the most recent decision.
Cause. An extreme result can include an unusually favorable or unfavorable contribution from chance. When that contribution does not repeat, the next observation tends to be closer to the typical result. Francis Galton described regression towards mediocrity in hereditary stature in 1886.
Confirm. Use the hypothetical 12-week booked-jobs baseline in KPIs and targets that drive action: its mean is 21 jobs and its natural process limits are about 9.2 and 32.8. A week with 31 jobs is inside those limits. A following week with 22 is consistent with regression toward the mean and needs no special cause to explain it.
The linked example explains the XmR limits and WECO signal rules. A single observation inside the limits is not a sufficient reason to declare a process change; a pattern across observations can still warrant investigation.
Fix. Record the intervention date and continue measuring against the established baseline. If you launch a rescue after a 12-job week, an ordinary return toward 21 can make the rescue appear effective. Decide in advance what sustained pattern would persuade you that the process has changed, and seek a comparison group when the decision justifies one.
6. A correlation gets promoted to a cause
Symptom. Visitors who open your chat widget convert more often than visitors who do not, so the report credits the widget with the difference. The two observations can be associated without the widget causing all or any of the gap.
Cause. In a hypothetical example, people who open chat may already be the most interested visitors. Their intent can make them more likely both to ask a question and to convert. A dashboard usually records the chat interaction and the conversion more readily than it records the visitor's intent before either event.
Confirm. If traffic and implementation allow, hide the widget from a randomly selected share of eligible visitors for a fixed period. Record the number of eligible visitors and conversions in both the widget and holdout groups, including visitors who never open the widget. Compare conversion rates using those assigned groups.
Check that assignment is random and that the two groups receive the same offer and measurement rules. If the count is small, report the uncertainty alongside the difference. A result can be directionally interesting without being precise enough to support a budget decision.
Fix. Use a randomized holdout when you need a causal answer and can run one responsibly. Otherwise, describe the finding as an association and list plausible selection effects. The decisions and dashboards discussion connects Kohavi's work on causal experiments with Anscombe's examples and Daniels' work on averages.
7. One large order distorts the average
Symptom. Average order value rises sharply, although most customers appear to be placing their usual orders. An average can move because of one unusually large transaction.
Cause. The mean divides total revenue by the number of orders, so every dollar in a large order affects it. The median is the middle value after sorting the orders; it describes the midpoint of the order distribution and is less sensitive to an extreme order.
Confirm. Take a hypothetical list of ten orders: nine at $80 and one at $2,000. Total revenue is (9 × $80) + $2,000 = $2,720. The mean is $2,720 / 10 = $272; the median is $80. The largest order contributes $2,000 / $2,720, or about 74% of revenue.
Open the order list in the shop or CRM, sort it by value and calculate the largest order's share of the period's revenue. Check the median against the mean for the same orders. If refunds, tax or shipping are included, use the same definition in both calculations.
Fix. Show the mean when you need revenue per order for financial planning, and show the median when you want to describe a typical order. Keep the large order in the financial total if it is valid; flag its contribution so it is not mistaken for a broad customer behavior change. Daniels' work is a useful reminder that an average can describe a group without describing an individual, as discussed in the linked decisions article.
8. Repeated early checks produce a false A/B winner
Symptom. An A/B test shows a statistically significant result on Tuesday, loses it on Wednesday and produces a different winner on Friday. The team stops when the first attractive result appears.
Cause. A conventional significance threshold assumes a specified analysis plan. Repeatedly testing accumulating data and stopping at the first significant result gives chance more opportunities to cross that threshold. A reported 5% false-positive rate no longer describes the whole stopping process.
Confirm. Count how many times the team checked statistical significance before the planned sample was complete. The James Lind Library's account of McPherson's 1974 work reports that ten unadjusted looks raised a nominal 5% false-positive rate to nearly 20%. Armitage, McPherson and Rowe treated repeated analysis earlier, in 1969.
In our simulation of 40,000 tests with no real effect, a 5% z test after each equal batch, stopping at the first significant result, produced false positives in about 14% of tests with five looks, 20% with ten and 25% with 20.
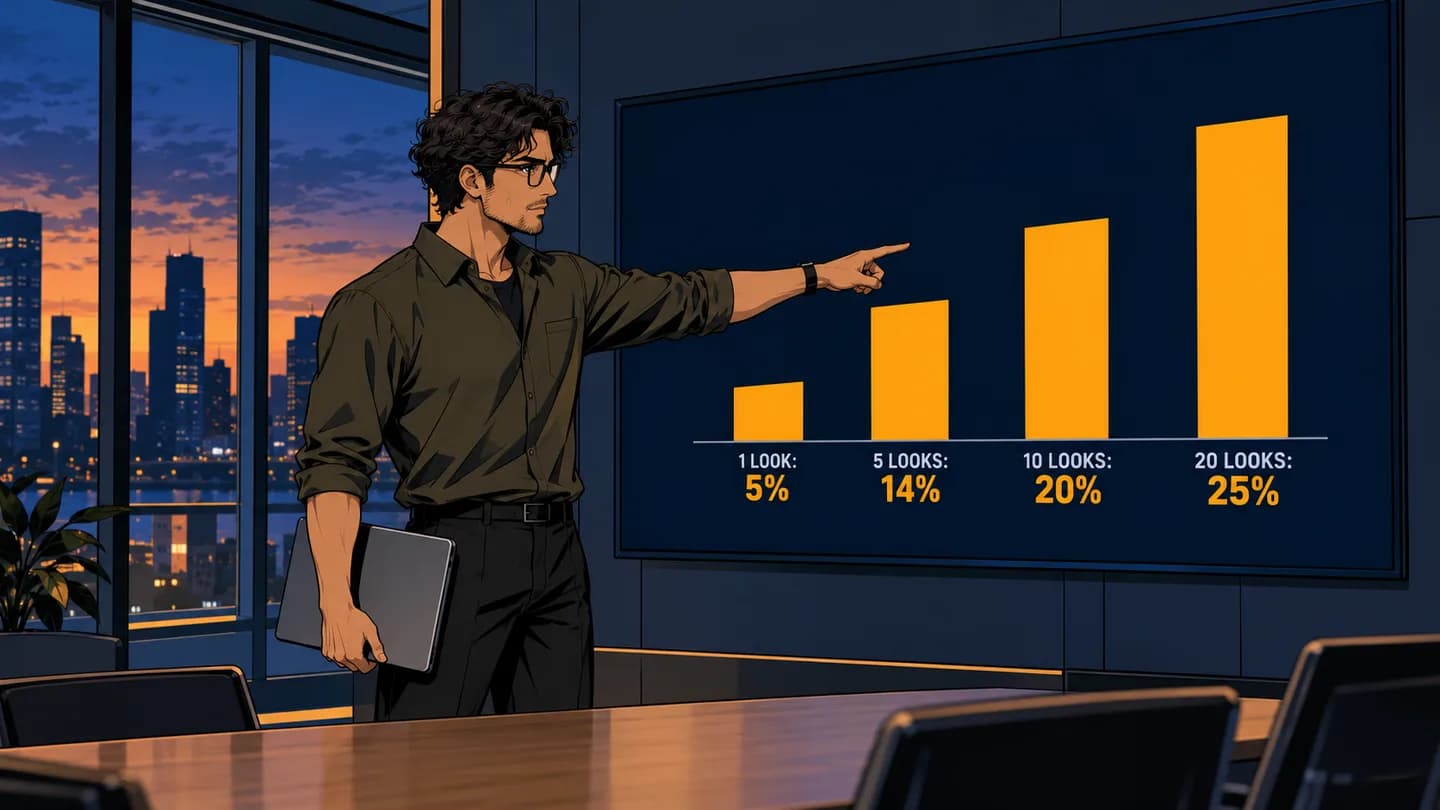
Each extra unadjusted look gives a test another opportunity to produce a false positive. The chart shows the increase as the number of looks grows.
Watching whether the test is functioning is useful. Testing for significance every day and stopping on the first positive result changes the false-positive rate.
Fix. Set the sample size or end date before the test begins and make the planned significance decision once. If early stopping is necessary, use a sequential method designed for repeated looks. The reported ten-look scenario uses a threshold of about 1.07% per look to hold the overall false-positive rate at 5%.
9. One slice wins after enough comparisons
Symptom. An overall test is inconclusive, but one device, channel or day shows a significant uplift. The winning slice becomes the headline after many other slices have been checked.
Cause. Each comparison gives random noise another chance to look convincing. At a 5% threshold, a false positive is possible even when a particular comparison has no real effect. Searching through many comparisons increases the chance of finding at least one.
Confirm. List every comparison tested, including the ones that did not produce a result worth presenting. For 20 independent tests with no real effects, each using a 5% threshold, the chance of at least one false positive is:
20 tests: 1 minus 0.95^20 = about 0.64, or 64% 10 tests: 1 minus 0.95^10 = about 0.40, or 40%
Business segments are rarely fully independent, so treat 64% as an indication of scale under the stated assumptions, not an exact probability for your dashboard. Device, channel and customer status can overlap, and their results can move together.
Fix. Choose the primary outcome and the segments you intend to test before inspecting results. One conservative adjustment is Bonferroni: divide the overall 0.05 threshold by 20 comparisons, giving 0.0025 per comparison. Treat an unexpected segment winner as a hypothesis for a fresh test, and disclose how many slices you inspected.
10. The missing cases create a survivorship story
Symptom. A customer survey says people value the service, or a review of active ads finds that the ads are performing well. The report has little to say about customers who left or ads that were stopped.
Cause. The available records have survived a selection process. Studying only the survivors can hide the reasons other cases disappeared, particularly when disappearance is related to the outcome you care about.
In 1943, Abraham Wald worked at Columbia University's Statistical Research Group and wrote eight memoranda titled A Method of Estimating Plane Vulnerability Based on Damage of Survivors. The Center for Naval Analyses reprinted them in 1980. The method estimated, from hits recorded on aircraft that returned, how likely a hit in each area was to bring a plane down. Areas with few hits on survivors could indicate that hits there were more often fatal.
Marc Mangel and Francisco Samaniego reconstructed the work in the Journal of the American Statistical Association in 1984. The dramatic scene of Wald pointing at a dotted diagram is a later retelling, and the widely shared dotted-bomber picture is a modern illustration. This is the same Abraham Wald whose name is on the Wald interval, the normal-approximation interval for a rate mentioned in section 1.
Confirm. Write down who could have appeared in the data and who is absent. For a current-customer survey, count customers who left during the same period. For an active-ad review, count ads paused or ended during the period and inspect their recorded results.
Fix. Collect at least one relevant measure for the missing group before drawing a broad conclusion. Ask departed customers why they left where contact is appropriate, or include stopped ads in the performance export. State the population your report actually describes if you cannot recover the missing data.
11. The overall rate reverses the segment comparison
Symptom. Your overall close rate falls even though each sales channel's close rate rises. A change in the proportion of leads from each channel can produce that result.
Cause. The total rate is a weighted average. When more observations move into a segment with a lower rate, the combined figure can fall even as every segment improves. This pattern is called Simpson's paradox.
Confirm. Split the total into meaningful segments before comparing it. A public example comes from fall 1973 graduate admissions at Berkeley. Bickel, Hammel and O'Connell reported that 3,738 of 8,442 men were admitted campus-wide, about 44%, and 1,494 of 4,321 women were admitted, about 35%.
In the six largest departments in the UCBAdmissions dataset, 1,198 of 2,691 men were admitted, or 44.5%, and 557 of 1,835 women were admitted, or 30.4%. Women had the higher admission rate in four of the six departments.
| Department | Men: applicants | Men: admitted | Men: rate | Women: applicants | Women: admitted | Women: rate |
|---|---|---|---|---|---|---|
| A | 825 | 512 | 62% | 108 | 89 | 82% |
| B | 560 | 353 | 63% | 25 | 17 | 68% |
| C | 325 | 120 | 37% | 593 | 202 | 34% |
| D | 417 | 138 | 33% | 375 | 131 | 35% |
| E | 191 | 53 | 28% | 393 | 94 | 24% |
| F | 373 | 22 | 6% | 341 | 24 | 7% |
Women applied more often to departments with low admission rates, affecting the combined comparison. The department figures and the campus-wide figures describe different populations, so their totals should not be interchanged.
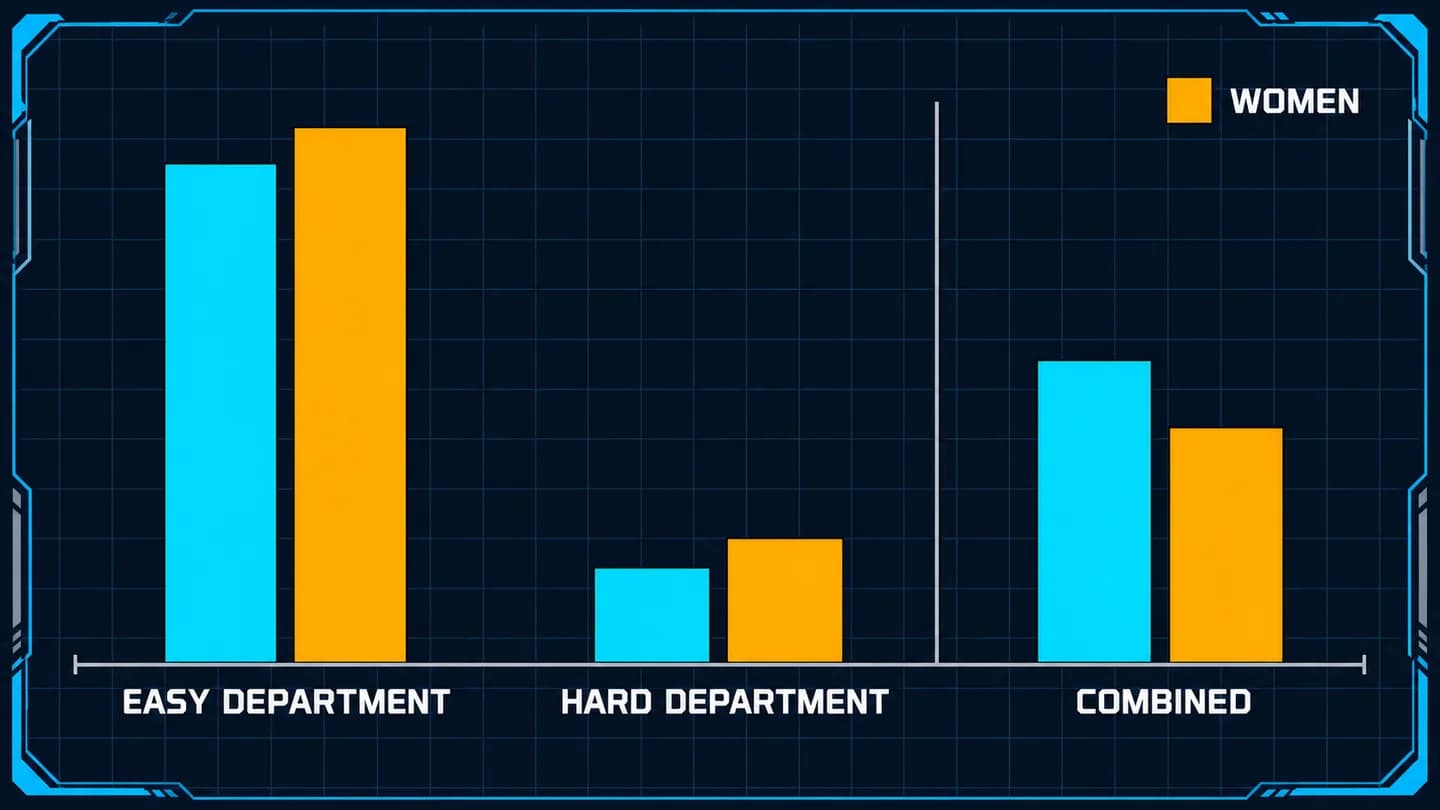
The illustration shows higher admission rates for women within each of two hypothetical departments. The combined rate reverses because more women apply to the harder department.
Fix. For a hypothetical business with a falling overall close rate, compare closes and leads by channel for both periods, then inspect how the channel mix changed. Keep the total for planning capacity, and use the segment rates and volumes to explain what moved it. Do not infer an individual cause from the aggregate pattern alone.
12. GA4 withholds rows or samples a large report
Symptom. Rows disappear from an exploration, segment totals do not add up as expected, or the data quality indicator warns that a report uses a subset of data. Sampling and thresholding can both affect what you see, but they have different triggers.
Cause. GA4 sampling may occur when the events used to create a report, exploration or request exceed the quota: 10 million events for a standard property and up to 1 billion for Analytics 360. The data quality icon shows the percentage of data used.
Data thresholds protect against a viewer inferring an individual user's identity. GA4 may withhold demographic data or rows containing search query information when there are too few users. Data thresholds are system defined. You can't adjust them.
Confirm. Open the data quality icon or indicator on the affected report. Look for a sampling percentage or an indication that thresholding was applied. Check the date range and the dimensions in the affected rows; a missing demographic row calls for a different investigation from a report based on a sample.
Our inference is that small sites encounter thresholding far more often than sampling, because a small user count can trigger withheld rows while the standard sampling quota is 10 million events. That is a practical prior, not a diagnosis of a particular report.
Fix. Shorten the date range to reduce sampling. For thresholding, try widening the date range or using the BigQuery export. Record which report and dimensions were affected before comparing the result with a different tool or period.
Triage checks for a suspicious number
The times are our rough estimates for someone who already has access to the relevant reports. Investigation can take longer when definitions or historical settings are missing.
| Failure mode | First check to run | Rough time |
|---|---|---|
| Small-sample noise | Calculate the square root of the expected count and compare the movement with that rough swing. | 5 minutes |
| Calendar pattern | Align the same weekdays or compare complete weeks. | 5 minutes |
| Tool definitions | List the outcome, date basis and counting method for one week in each tool. | 20 minutes |
| Changed denominator | Compare the numerator and denominator separately against tracking and consent change dates. | 15 minutes |
| Regression to the mean | Locate the extreme week against the established baseline and process limits. | 10 minutes |
| Correlation treated as cause | Identify how visitors entered each group and whether assignment was random. | 15 minutes |
| Skewed average | Sort the order list and calculate the largest order's share of revenue. | 10 minutes |
| Peeking | Count significance checks made before the planned test endpoint. | 5 minutes |
| Multiple comparisons | Count all outcomes and slices tested, including unsuccessful ones. | 10 minutes |
| Survivorship bias | List missing cases and count one missing group. | 15 minutes |
| Simpson's paradox | Compare the rate and volume within each relevant segment for both periods. | 20 minutes |
| GA4 sampling or thresholding | Open the data quality indicator and identify the stated issue. | 5 minutes |

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.