Data-Driven Decision Making: 9 Myths

On this page
- Myth 1: More data means better decisions
- Myth 2: A dashboard tells you what to do
- Myth 3: Real-time data is better
- Myth 4: If a metric went up, the change worked
- Myth 5: Averages describe a typical customer
- Myth 6: The data speaks for itself
- Myth 7: A correlation in the dashboard is a cause
- Myth 8: Making a number a target improves what it measures
- Myth 9: We need a data scientist before we can use data
- A decision card for a Saturday staffing choice
Analytics & Data
The most important figures needed for management of any organization are unknown and unknowable.
W. Edwards Deming wrote that sentence in the reissue of Out of the Crisis, on page 19, as quoted by the W. Edwards Deming Institute. It is a useful warning against treating the numbers on a screen as a complete account of a business.
Data-driven decision making starts with a named decision, a threshold that would trigger action, an owner who acts, and a number relevant to that choice. A number that could not change any decision is decoration. Sources for the claims that follow were read on 29 October 2026.
Myth 1: More data means better decisions
The claim. If a decision feels uncertain, collect more information until the answer becomes obvious. A larger collection of facts should give the owner a better chance of choosing correctly.
What the source says. Tsai, Klayman and Hastie's research on information and judgment reported three studies in which people predicted college football results using team statistics. As judges received more relevant information, their confidence rose more than their accuracy, opening a substantial gap between the two. More information appeared to make them surer without producing a comparable improvement in their predictions.
Deming's fifth deadly disease was: “Management by use only of visible figures, with little or no consideration of figures that are unknown or unknowable.” He also rejected the popular claim that you cannot manage what you cannot measure, a line often wrongly attributed to him. A screen can show recorded complaints without revealing how many unhappy customers quietly stopped recommending the company.
What to do instead. Name the decision before requesting another report. Write down the threshold that would change the owner's action, then ask whether the proposed data could plausibly put the result on a different side of that threshold.
For a hypothetical staffing decision, an operations manager might need the number of jobs turned away each Saturday. A new chart of website sessions would need a clear connection to that choice before it earned space in the review. The manager should also record relevant unknowns, such as whether customers who could not book later called a competitor, without pretending that an empty cell means zero.
Myth 2: A dashboard tells you what to do
The claim. Give a manager a dashboard and the right decision will emerge from the charts. The more tiles the dashboard contains, the more useful it becomes.
What the source says. Our definition of a dashboard is a standing view of a few numbers reviewed on a cadence by an owner. Our definition of a report is an answer to one question, produced once and ending in a decision. The distinction is practical: a dashboard keeps a decision visible, while a report resolves a particular question.
A dashboard without an owner or a decision rule becomes decoration. The small business analytics guide sets out these definitions alongside a source-of-truth map and sample-size arithmetic. Money belongs in the payment processor or accounting records, leads and customers in the CRM, and on-site behavior in GA4.
What to do instead. Apply a value-of-information test to each number: is there any possible value that would change what the owner does? If the answer is no, drop it from that decision view. If the answer is yes, record the value or range that triggers action and the person responsible for acting.
Suppose a service manager reviews unanswered inquiries every Monday. The decision might be whether to change the coverage schedule, with a threshold agreed before the review. A chart of total page views can stay elsewhere unless the manager can name a value that would change that schedule.
Myth 3: Real-time data is better
The claim. A current number is always more useful than a number from yesterday. A live chart gives the owner a head start on every decision.
What the source says. For standard properties, Google's GA4 data freshness documentation gives typical processing times of a few minutes for Realtime, 2 to 6 hours for intraday data, and 12 hours for daily data. Processing can take 24 to 48 hours, and report data may change during that window. The GA4 Realtime report displays user activity over the last 30 minutes.
A live view earns its place when someone can act within minutes. After a hypothetical checkout deployment, the owner could watch for a broken path and investigate immediately if expected activity stops. A weekly staffing decision has a different clock; reading a 30-minute window for it is likely to emphasize noise.
What to do instead. Match the refresh rate to the decision and name the owner who can respond. For counts, a rough typical swing is the square root of the count: at 16 leads a month, that is about 4 leads, making 12 or 20 an ordinary swing under this rule. For a hypothetical lead review, the owner can set an action threshold outside that band before looking, then use settled monthly data to decide whether to investigate.
This square-root rule is a rough check, not proof that a change outside the band has a particular cause. It gives the owner a reason to avoid treating every small movement as an instruction.
Myth 4: If a metric went up, the change worked
The claim. A company makes a change, the dashboard number rises, and the change gets the credit. The before and after values seem to tell a complete story.
What the source says. In Online Experimentation at Microsoft, Kohavi and colleagues wrote: “Evaluating well-designed and executed experiments that were designed to improve a key metric, only about one-third were successful at improving the key metric!” The paper also says that ideas believed to be good but found to hurt their intended metric represented about one third of experiments.
A rising metric after a change can have several explanations. A seasonal shift, another campaign or ordinary variation may have contributed. A before and after comparison alone cannot separate those explanations from the effect of the change.
Write down what else changed during the period. An increase after a launch is an observation; it does not establish that the launch caused the increase.
What to do instead. Before making the change, have the decision owner write the intended action, metric, comparison and threshold. For example, a hypothetical manager considering a new booking message could decide in advance what difference in completed bookings would justify keeping it and when the result will be reviewed.
Record other changes that coincide with the trial, including campaigns or pricing changes. If there is no credible comparison, describe the result as an observation and decide whether the uncertainty justifies another test. The guide to reading data without fooling yourself explains noise, comparisons and before and after traps.
Myth 5: Averages describe a typical customer
The claim. An average customer value describes what most customers spend. An average set of measurements describes a person close enough to typical for every design decision.
What the source says. In The “Average Man”?, Gilbert Daniels studied 4,063 men in a sample of Air Force flying personnel. He defined approximately average for each measurement as the band that held roughly the middle 30% of the men on that measurement. Applying the ranges successively left no person who was approximately average on all ten measurements.
| Successive measurements applied | Men remaining |
|---|---|
| Stature | 1,055 |
| Plus chest circumference | 302 |
| Plus sleeve length | 143 |
| Plus crotch height | 73 |
| Plus torso circumference | 28 |
| Sixth measurement | 12 |
| Seventh measurement | 6 |
| Eighth measurement | 3 |
| Ninth measurement | 2 |
| Tenth measurement | 0 |
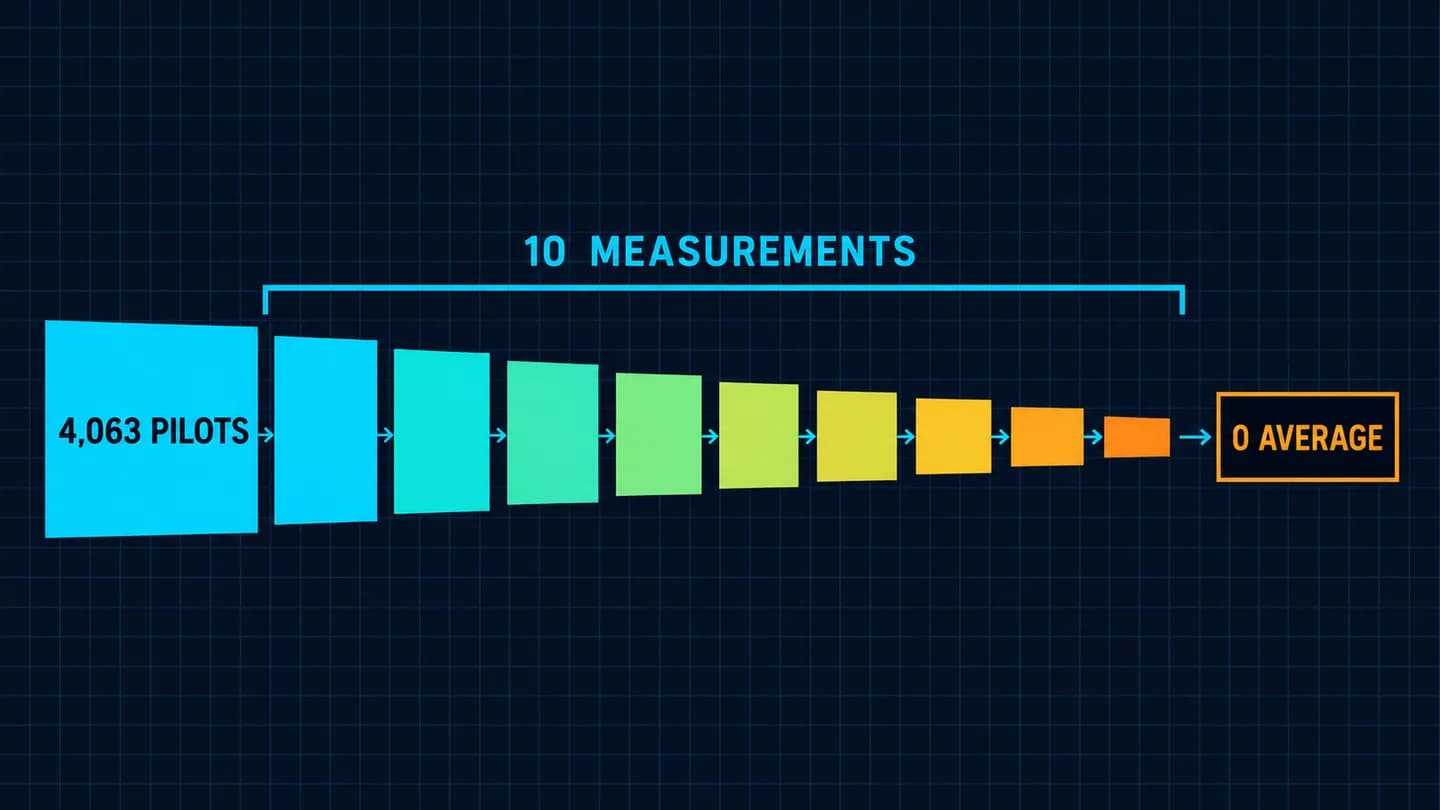
Each filter keeps only men already within the preceding average ranges. None of the 4,063 men remained after all ten measurements.
A mean can also be far from a typical order. Assume a hypothetical company has ten orders: nine at $80 and one at $1,200. The mean is $192, while the median, the middle value after ordering the amounts, is $80. No order is close to $192.
mean = (9 x $80 + $1,200) / 10 = $1,920 / 10 = $192 median = ($80 + $80) / 2 = $80
What to do instead. Name the decision first: an owner planning for total revenue may need the mean, while an owner deciding what a typical order looks like should inspect the median and the individual amounts. Set a threshold for the chosen decision before reviewing the values. If the threshold concerns a typical order, check whether a few large orders are pulling the mean across it.
The median does not make the $1,200 order disappear. Keep the distribution visible when the action depends on both the usual order and the occasional large one.
Myth 6: The data speaks for itself
The claim. Once the summary statistics are calculated, the numbers explain the situation without further inspection. Two datasets with the same summary should support the same decision.
What the source says. Anscombe's quartet consists of four datasets with 11 points each. They share a mean of x of 9, variance of x of 11, mean of y of 7.50, variance of y of about 4.12, correlation of about 0.816, and regression line y = 3.00 + 0.500x.
Plot them and the shapes differ: one is a linear cloud, one a smooth curve, one a straight line with an outlier, and one a vertical stack with one distant point. The shared summary does not reveal which arrangement produced it. A single correlation tile can hide a point with an outsized influence on the result.
What to do instead. Give the owner a decision and an action threshold, then inspect the underlying rows or a plot before applying the rule. If a hypothetical manager would change a sales process when the relationship between inquiries and orders crosses a threshold, the manager should first check whether one unusual observation dominates the relationship.
Ask whether the plotted shape supports the calculation being used for the decision. Record unusual rows and investigate their source before removing them; an unusual order may be a recording error or a real part of the business.
Myth 7: A correlation in the dashboard is a cause
The claim. Two lines rise together, so the activity represented by one line caused the other. A channel receiving attribution credit caused the credited leads.
What the source says. Kohavi and colleagues say randomized controlled experiments allow causality to be established scientifically. A dashboard correlation by itself does not provide that comparison. Both measures might respond to another change, or their apparent relationship might be accidental.
GA4 data-driven attribution distributes credit for a key event. Our reading is that this credit assignment does not itself measure cause. Ad platforms can each claim credit for the same lead, so adding their claims can overstate the count; use the CRM as the count of record.
What to do instead. Have the owner name the decision, predict the result and write an action threshold before looking at the outcome. Where a randomized controlled experiment is practical, use one. For a smaller hypothetical test, change one thing and hold one comparable thing back, such as a region, product line or alternate week.
For example, an owner considering a new follow-up message could use it in one region while keeping the existing message in a comparable region. Agree on the difference that would justify adoption and the review date beforehand. A nonrandom comparison is useful working evidence, but differences between regions or weeks can still explain part of the result.
Myth 8: Making a number a target improves what it measures
The claim. Set a target, attach responsibility to it and the underlying outcome will improve. A stronger incentive for the number should produce a stronger result.
What the source says. Donald T. Campbell wrote in his paper on planned social change:
The more any quantitative social indicator is used for social decisionmaking, the more subject it will be to corruption pressures and the more apt it will be to distort and corrupt the social processes it is intended to monitor.
Campbell discussed the Vietnam-era body count and achievement tests that lose value as indicators when test scores become the goal of teaching. The familiar line about a measure ceasing to be good when it becomes a target is a later popular paraphrase of Goodhart's law, not Campbell's wording.
What to do instead. Give the target an owner, a decision threshold and a counter-metric that can expose an unwanted tradeoff. For a hypothetical service team, an owner trying to reduce response time could also review reopened cases. A lower response time accompanied by more reopened cases would prompt the owner to inspect how inquiries are being handled before declaring the change successful.
Specify what the owner will do when either measure crosses its threshold. The guide to KPIs and targets that drive action sets out how to choose targets and thresholds for that review.
Myth 9: We need a data scientist before we can use data
The claim. A company must hire a specialist and buy a data warehouse before it can make a sound decision with data. Until then, useful analysis is out of reach.
What the source says. In our opinion, a data warehouse is usually not the first purchase for a company of 10 to 200 people. A CRM report or spreadsheet can answer many early questions if someone owns the records and knows which decision the answer will affect. The mean, median and rough square-root checks used here are spreadsheet arithmetic.
Specialist work can be justified by a specific need. It should have a named decision or technical problem attached to it, just as a report should. Buying infrastructure does not supply the owner or action rule.
What to do instead. Start with one recurring decision and appoint the person who will act. Identify the source of truth, agree on the threshold and put the review date on the calendar. If the necessary records are missing or inconsistent, assign an owner to improve their collection before expanding the reporting system.
A spreadsheet can hold the decision card, the observations and the dates of each review. It should show when the threshold was crossed and what the owner decided, including occasions when the owner chose to investigate before acting.
A decision card for a Saturday staffing choice
Assume a hypothetical 30-person plumbing company records Saturday jobs it cannot take in its CRM. The company wants to decide whether demand justifies a trial of a second Saturday crew. The operations manager owns both the count and the staffing decision.
| Field | Decision card |
|---|---|
| Decision | Add a second Saturday crew |
| Owner | Operations manager |
| Metric and source of truth | Saturday jobs turned away, logged in the CRM |
| Threshold | 8 or more turned-away jobs on each of 4 consecutive Saturdays |
| Action if crossed | Rotate a second crew onto Saturdays for a trial month |
| Review date | One month after the trial starts |
The threshold requires all four Saturdays to reach eight; a total of 32 across four weeks does not meet the stated rule if one Saturday falls short. Before the count begins, the owner should make sure staff record each turned-away job consistently and can distinguish Saturday requests from work scheduled on other days.
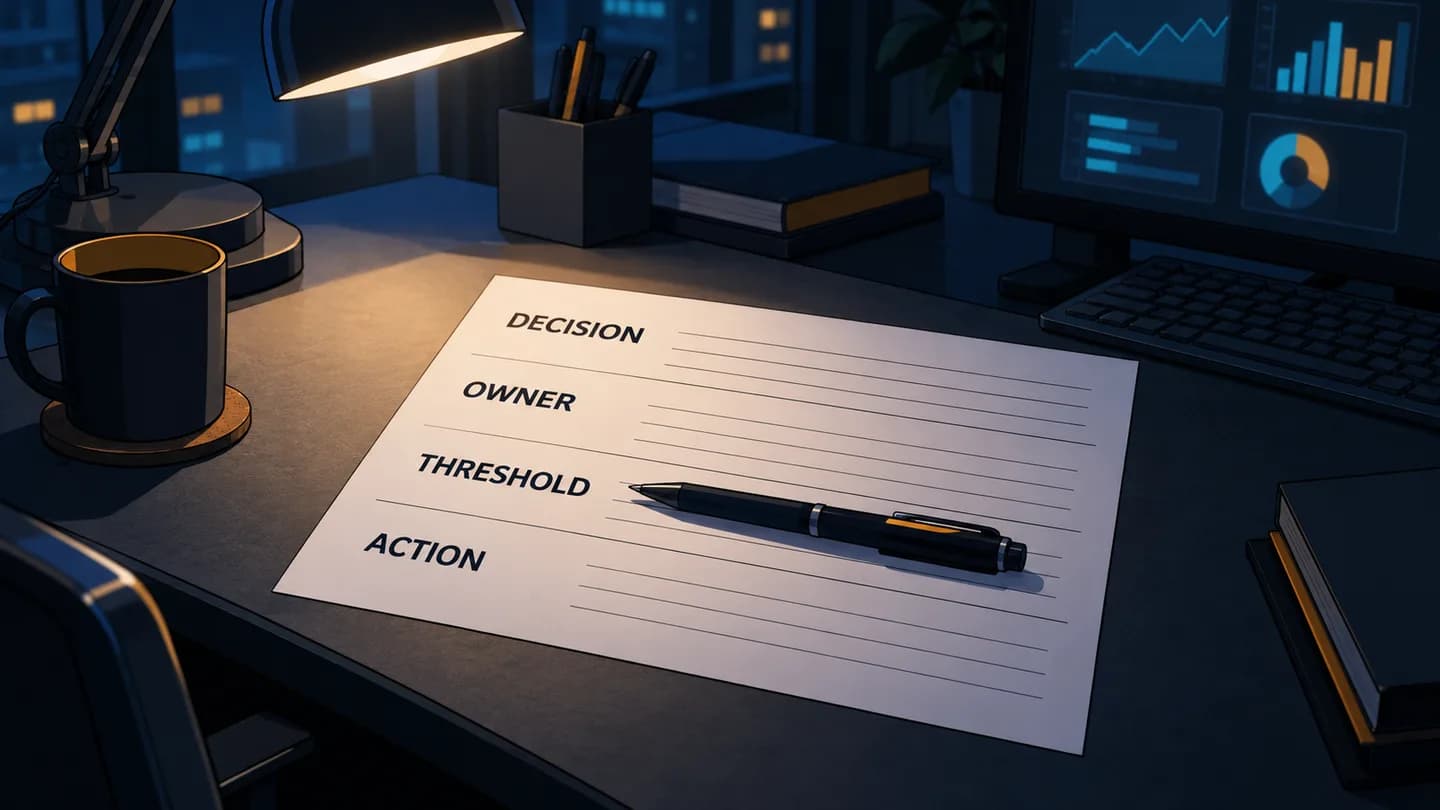
The card puts the decision and its owner beside the threshold and action. The charts behind it need an owner and a rule before they can direct work.
At the review, the operations manager records what changed during the trial and decides what ships next. Iron Goo's operations service uses that reporting pattern for chatbot deflection, escalation and agent operations.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.