AI Automation Running Costs per 1,000 Runs
Table of contents
AI automation running costs vary 100x for the same task: at 10,000 runs a month, with an assumed 1,500 input and 300 output tokens per run, gpt-6-luna or Claude Haiku 5.5 costs $3.00 versus $300.00 for gpt-6-astra, by our calculation. Assuming a person reviews 5% of runs for one minute each, review costs $256.33 at a $30.76 loaded hourly rate, also by our calculation. The model is often a small part of the bill.
Prices were read on 1 November 2026 in US dollars, except n8n and Hetzner prices, which are in euros as published; check vendor pages before relying on them.
How much do model tokens cost per 1,000 runs?
Model token costs for the assumed AI step range from $0.27 to $30.00 per 1,000 runs across the models listed here. The table uses 1,500 input tokens and 300 output tokens per run, with no caching; the figures are our own working using standard prices.
| Model | Per 1,000 runs | 10,000 runs per month | 100,000 runs per month |
|---|---|---|---|
| gpt-6-luna or Claude Haiku 5.5 | $0.30 | $3.00 | $30.00 |
| Gemini 2.5 Flash-Lite | $0.27 | $2.70 | $27.00 |
| Claude Sonnet 5.5 or gpt-6.1-sol | $6.00 | $60.00 | $600.00 |
| Claude Opus 5.5 | $12.00 | $120.00 | $1,200.00 |
| gpt-6-astra | $30.00 | $300.00 | $3,000.00 |
The 100x comparison in the opening uses gpt-6-luna or Haiku against gpt-6-astra; Gemini Flash-Lite costs slightly less for this token mix.
The calculation multiplies 1.5 million input tokens and 0.3 million output tokens by each model's respective per-million-token prices. For example, gpt-6-luna costs (1.5 × $0.10) + (0.3 × $0.50) = $0.30 per 1,000 runs, using OpenAI API pricing.
Anthropic's Batch API halves input and output token prices. US-only inference on Claude 4.6 and later applies a 1.1x multiplier to token prices, according to Claude pricing.
The AI automation cost guide has full line-item receipts for email triage, invoice extraction and a support chatbot. At 10,000 runs, gpt-6-luna or Haiku costs $3 a month versus $60 for Sonnet 5.5 or gpt-6.1-sol, a $57 difference on our subtraction. I would choose based on whether the small model's output passes review, because the price gap is relatively small at that volume.
Platform plans count different units
Zapier counts each successful action as a task; n8n counts one execution per whole workflow run, regardless of steps. At three successful billable actions per Zap, 10,000 runs require 30,000 Zapier tasks versus 10,000 n8n executions. Zapier triggers, Formatter, Paths and Filter do not count as tasks.
The table uses the smallest listed Zapier Pro annual tier covering each volume and the published n8n Cloud plans.
| Runs per month | Zapier tasks | Zapier Pro, annual billing | n8n Cloud, annual billing |
|---|---|---|---|
| 1,000 | 3,000 | 5,000 tasks, $89 per month | Starter, €20 per month, 2,500 execution cap |
| 10,000 | 30,000 | 50,000 tasks, $289 per month | Pro, €50 per month, 10,000 execution cap |
| 100,000 | 300,000 | 300,000 tasks, $1,069 per month | Beyond the Pro plan |
At 10,000 runs, n8n Pro is exactly at its cap. Starter and Pro are capped with no overages; self-hosting on Hetzner starts at €6.49 a month excluding VAT, plus your own upkeep.
Make's Free plan includes 1,000 credits a month. Most actions use one credit, while Make's AI Provider features may use more; paid-plan prices were not readable on its pricing page on 1 November 2026.
Bought helpdesk chatbots can bill per outcome or session. The chatbot cost sheet accounts for those units.
Tracing and human review add their own monthly bills
Tracing tools bill for records of automation activity, and their units differ from workflow runs. Langfuse Hobby includes 50,000 tracing units a month for free; Core costs $29 a month for 100,000 units, plus $8 per additional 100,000 units. A unit is a trace, an observation or a score.
Assume five Langfuse units per run. At 10,000 runs a month, 50,000 units fit Hobby; at 100,000 runs, 500,000 units cost $61 a month on Core, our sum of $29 plus four lots of $8. LangSmith Plus costs $39 per seat per month with 10,000 base traces, which it retains for 14 days.
Human review has a bill even when the reviewer is already on payroll. The Bureau of Labor Statistics reported a $21.53 median hourly wage for customer service representatives in May 2025; dividing by the 70.0% private-industry wage share of compensation in June 2026 gives a loaded rate of $30.76 per hour, which we derived from those figures.
At that rate, assuming a 5% review rate and one minute per review, review costs $25.63 for 1,000 monthly runs, $256.33 for 10,000 and $2,563.33 for 100,000, on our working.
For the hypothetical 10,000-run month, Claude Haiku 5.5 costs $3.00, Zapier costs $289, Langfuse Hobby costs $0 and review costs $256.33. We add up $548.33 a month, with the model accounting for about 0.5%; the total does not yet include a migration allowance.
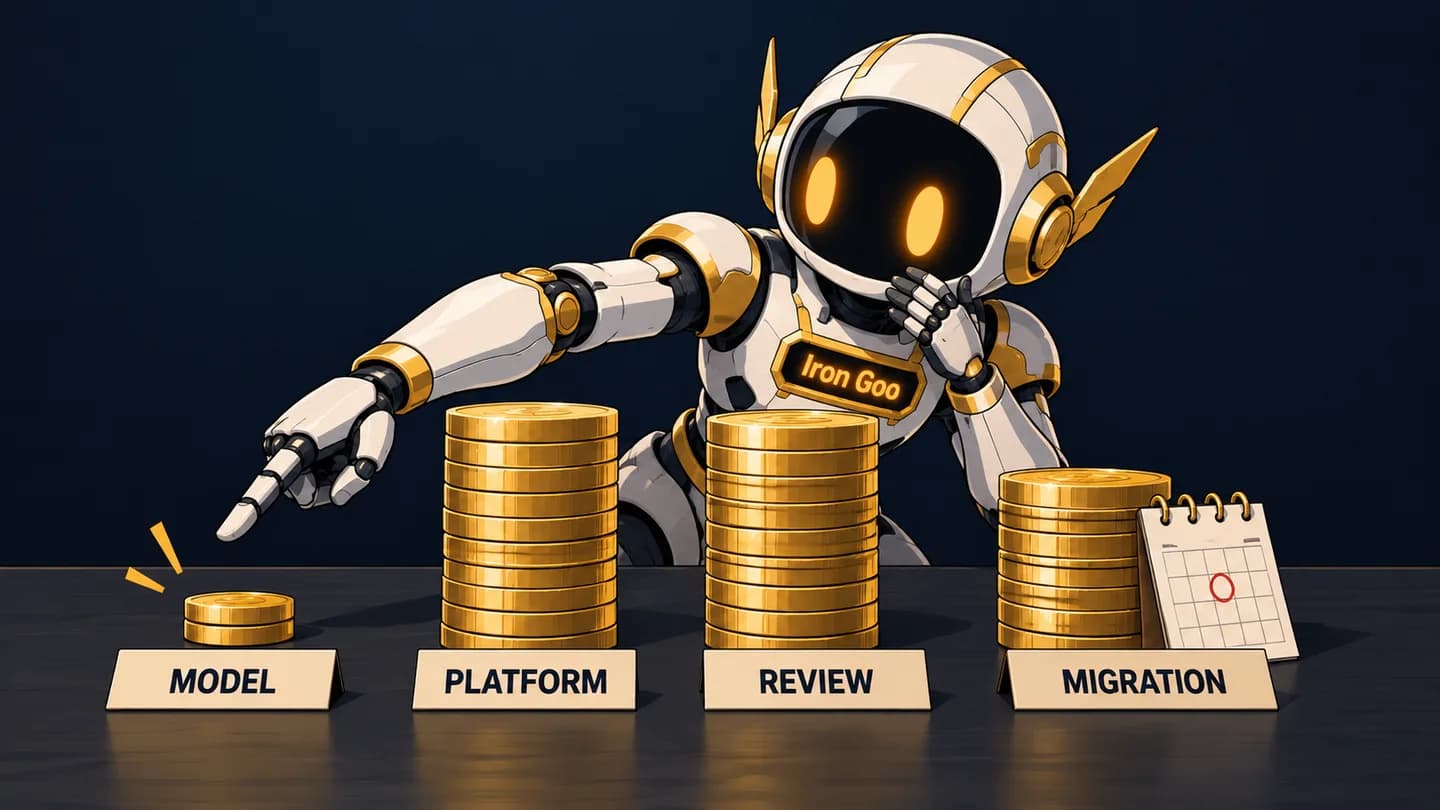
The model charge is small beside platform billing and human review. A yearly migration allowance adds another cost to plan for.
Model retirement adds a re-testing bill
Model retirement creates a re-testing cost when an automation needs a replacement. Anthropic's model deprecations page says customers with active deployments receive at least 60 days' notice before a publicly released model retires. Anthropic notified developers using Sonnet 4.5 on 30 September 2026 of its retirement on 30 November 2026, a 61-day gap by our count.
Requests to retired Claude models fail; ways live automations break covers the wider consequences. Anthropic retired seven models in the 12 months through 31 October 2026, on our tally of that page.
OpenAI's deprecations page says generally available models receive at least six months' notice unless safety or compliance concerns require a faster timeline. On 14 October 2026, OpenAI notified developers of the 14 January 2027 removal of dated GPT-4o, GPT-4o mini, GPT-4.1 and GPT-4.1 mini snapshots and their fine-tuned versions, a gap we counted as 92 days. The page does not say which notice tier those dated snapshots fall under.
Google's deprecations page says its listed dates are the earliest possible shutdown dates and that it will give advance notice; Google also scheduled Gemini 4 Argon token prices to double on 1 December 2026 and Gemini 3.8 Flash token prices to double on 1 January 2027.
A successor can cost less per million tokens: GPT-4.1's $2 input and $8 output compare with $0.10 and $0.50 for gpt-6-luna; Sonnet 4.5's $3 and $15 compare with $2 and $10 for Sonnet 5.5. In my view, re-testing can cost more than a small model's monthly token bill.
Our rule of thumb is to budget one forced migration per model per year. At a hypothetical six hours and $100 an hour, that is $600 a year or $50 a month, about 17 times the $3.00 monthly token bill for 10,000 Haiku runs, using our own division. A team that runs the automation can handle review and migration.
For a ten-minute check, find the exact model ID in each automation, look it up on the vendor's deprecation page and note any retirement or earliest possible shutdown date. Count last month's runs and the billable tasks per run, then multiply them to compare your volume with the platform tier you pay for.
Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.