Do I Need llms.txt?
Table of contents
llms.txt is often sold as a file AI assistants need before they can see your company. If you are asking “do I need llms.txt” for a company marketing site, the answer is no: the file is optional and cheap to add, Google Search ignores it, and no major assistant vendor documents reading it on other sites. Developer documentation or an API that coding agents read is the case where it has a clearer use.
The history explains the gap between the sales pitch and the evidence. A proposal for helping language models use websites became common on documentation platforms, while the search and assistant crawler record stayed much less convincing.
llms.txt is a curated reading list
An llms.txt file is a Markdown file, usually at the root of a site, that offers language models a curated overview and links to useful pages. The site or project name as an H1 is the only required section; a summary and lists of links are optional.
A minimal file can look like this:
# Example Co

> Industrial pump maintenance for food plants in Ohio.

## Services

- [Pump repair](https://example.com/services/pump-repair): response times, coverage area
robots.txt states crawl access rules; llms.txt is a curated reading list with no access rules. A separate file called llms-full.txt is a documentation-platform convention, not part of the llmstxt.org proposal.
The proposal moved toward documentation and agents
The llms.txt record runs from a proposal for language models using websites to a revised proposal aimed at agents. The dates also show when publisher adoption, Google's statements, and actual request measurements entered the discussion.
- 3 September 2024Jeremy Howard proposes llms.txt
Jeremy Howard of Answer.AI proposed a root file to give language models information for using websites.
- 20 November 2024Mintlify generates documentation files
Mintlify announced that it generates llms.txt and llms-full.txt for the documentation sites it hosts.
- 16 April 2025Mueller compares the file to a keywords tag
Search Engine Journal reported that Google's John Mueller compared llms.txt to the keywords meta tag, a site owner's own description of a site.
- 17 June 2025Mueller comments on AI system use
Mueller wrote on Bluesky: “FWIW no AI system currently uses llms.txt.”
- 7 May 2026Lighthouse adds agentic browsing to its default audits
Lighthouse 13.3.0 added agentic browsing to its default configuration, including an llms.txt audit.
- 15 May 2026Google publishes its AI optimization guide
Google's Search Central changelog recorded the publication of its guide to optimizing for generative AI features.
- 31 May 2026Mueller calls the file speculative
Search Engine Journal reported that Mueller called llms.txt “purely speculative for now” and suggested a client-sending AI platform asking for the file would change his recommendation.
- 15 June 2026Google clarifies its position and Ahrefs publishes measurements
Google's changelog records an llms.txt clarification, while Ahrefs published a study of 137,210 domains with traffic in May.
- 10 August 2026Howard revises the proposal
The v2 changes point the file toward agents finding and following relevant links; Howard claims coding agents use the files reliably.
The distinction between publishing a file and having a consumer fetch it runs through that sequence. Documentation platforms can generate files automatically, but generation alone does not establish that search crawlers or assistants request them.
Does Google use llms.txt?
Google Search ignores llms.txt, including for its generative AI capabilities. Chrome's Lighthouse checks the file for a different purpose, in an agentic browsing audit.
Google's AI optimization guide states: “It's completely fine if you decide to create and maintain LLMS.txt files (or other similar files) for other services or systems that use these files. Doing so will neither harm nor help your site's visibility or rankings in Google Search, as Google Search ignores them.”
The guide was first published on 15 May 2026, the clarification was added on 15 June 2026, and the guide was last updated on 10 July 2026. That is a direct answer to the Google Search ranking question, including the claim that the file improves visibility in Google's AI features.
Lighthouse's audit documentation describes a different check. It flags a server error when fetching the file and marks a 404 as not applicable because the file is optional. The audit documentation says nothing about Google Search, and the presence of the audit is not a Search ranking signal.
Vendor files and server logs show different things
AI vendors publish llms.txt files for their own developer documentation, but their published crawler documentation does not establish that their bots fetch the file on your site. On 1 November 2026, we read the files for OpenAI, Anthropic, Google's Gemini API, and Perplexity.
None of the crawler documentation pages we read for those vendors says their bots fetch llms.txt on other sites. Publishing a reading list for your own documentation does not establish that your crawler reads everyone else's. It also does not establish that ChatGPT requires the file to find a company.
The irongoo.com logs give that distinction a local test. From 18 October to 1 November 2026, requests carrying OpenAI, Anthropic, and Perplexity user agents made 3,276 requests to the site, our sum of the per-bot counts, and zero requests to /llms.txt. The same logs show repeated requests for /robots.txt: 177 carrying the ClaudeBot user agent and 59 carrying OAI-SearchBot.
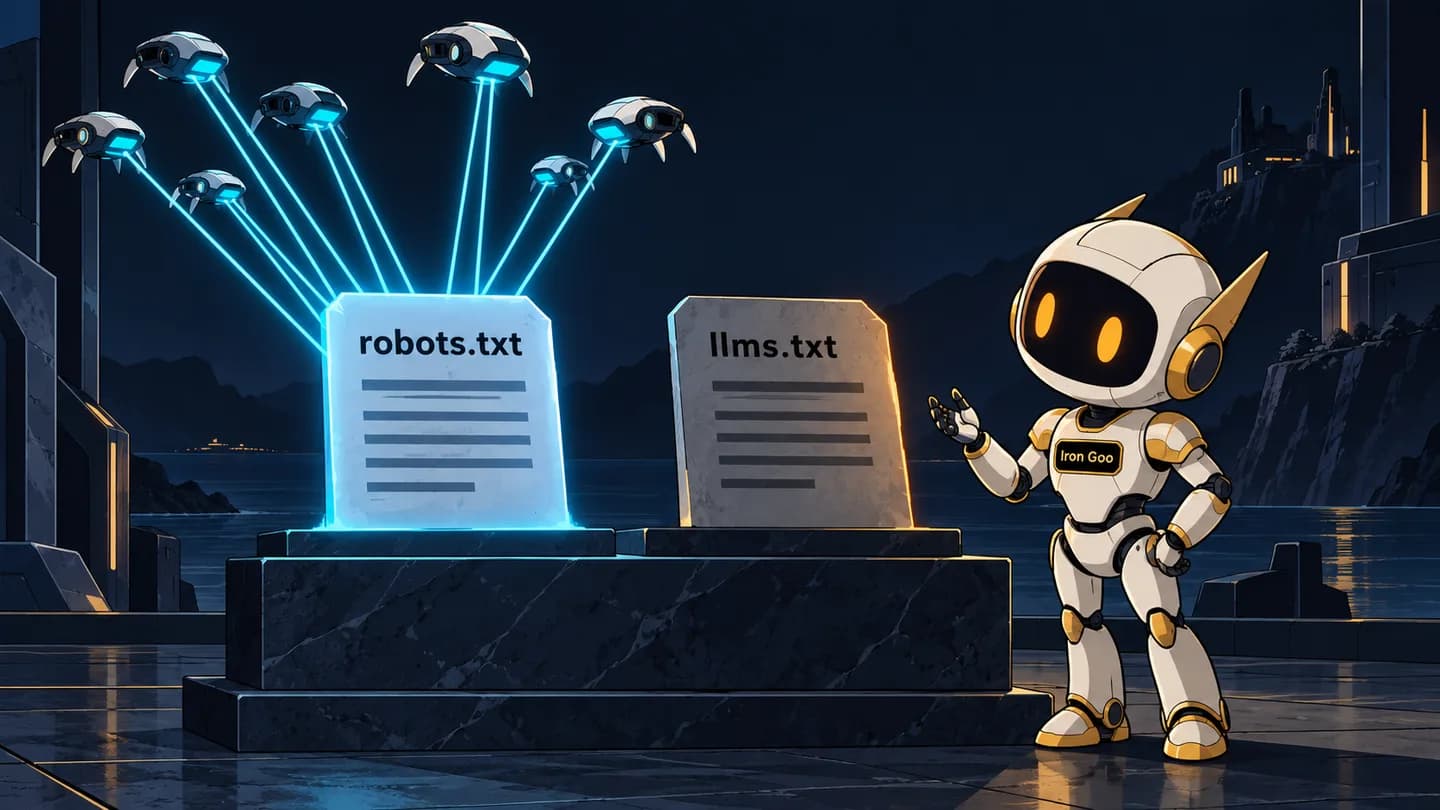
The vendor user agents repeatedly fetched robots.txt during the log window; none requested llms.txt. The counts describe requests carrying those user agents, which were not verified by IP.
The nine external requests to /llms.txt or /llms-full.txt came from SEO and web-data crawlers, six requests, and ordinary browser user agents, three requests. This is one site over about two weeks, and we did not verify the user agents by IP.
For a broader comparison, Ahrefs found that 97% of roughly 38,000 valid files received no requests in May 2026, although its sample skews technical. If your pages rank in Google but do not appear in assistant answers, the distinction between Google rankings and AI visibility deserves more attention than the presence of one file.
A ten-minute log test shows who requests the file
A server log can show whether requests carrying a given user agent reach llms.txt during the period you retain. On an nginx server using combined log format, run these commands to count user agents for the two paths:
zcat -f /var/log/nginx/access.log* | grep '"GET /llms.txt' | awk -F'"' '{print $6}' | sort | uniq -c | sort -rn
zcat -f /var/log/nginx/access.log* | grep '"GET /robots.txt' | awk -F'"' '{print $6}' | sort | uniq -c | sort -rn
Compare the user agents in the two outputs and check the dates covered by your available logs. If an agent requests robots.txt but never requests llms.txt in that window, the file cannot have supplied that agent with information during those observed requests. A request alone also does not prove that a system used the file's contents.
The current rule depends on the audience
My opinion is that a company should add llms.txt when its CMS makes the file trivial to maintain or when it publishes developer documentation that coding agents read. The first case is cheap, and the second has a defined audience; neither is a reason to pay a retainer for a file that Google Search ignores and major assistant vendors do not document fetching on other sites.
Keep your priorities on crawlable server-rendered pages, search crawler access, and Bing indexing; the AI-readable site checks address the pages, and the guide to AI search and answer engines covers crawler access, retrieval, and passages.
Revisit the file if a vendor documents reading it or your logs show its bot fetching it. That is close to Mueller's reported trigger: an AI platform that sends you clients asks for the file. If you want to measure whether assistants can read and name your company, Iron Goo's AI search visibility service focuses on that work, with llms.txt available as part of a build rather than sold as a visibility lever.
Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.