How to Measure UX and Fix What Is Failing

On this page
- Procedure 1: Pick task metrics with HEART
- Procedure 2: Build the reservation funnel in GA4
- Procedure 3: Find reservation friction in Clarity
- Procedure 4: Ask about task ease and score the whole visit
- Procedure 5: Check field performance on the task pages
- Procedure 6: Watch five people attempt the task
- Procedure 7: Rank problems with three evaluators
- Procedure 8: Re-measure the fix across complete weeks
UX
To decide how to measure UX, pick one task that matters, track three to five task-level numbers, find the drop-off with GA4 and Clarity, watch five people attempt it, rank the problems, fix one, and re-measure across complete weeks with a noise check. Useful numbers include task success, time on task, errors, and abandonment at a defined step.
The example throughout is hypothetical: a self-storage company has two facilities, and visitors reserve a unit online without paying on the website. Its chosen task is reserving a unit on a phone. All company figures and test observations in the example are hypothetical. Sources were read on 30 October 2026.
Procedure 1: Pick task metrics with HEART
Run this
Write the task as an outcome the visitor can complete, then agree on the business goal and the observable signals that would show progress toward it. Give each signal a precise metric with a numerator, denominator, population, and collection method. Four measurements are enough for this reservation task: completion, abandonment, interaction errors, and reported ease.
Kerry Rodden, Hilary Hutchinson, and Xin Fu introduced the HEART framework in their CHI 2010 paper. Happiness, Engagement, Adoption, Retention, and Task success are categories from which teams define specific metrics. The authors say teams need not use every category; Engagement, for example, may not be meaningful in an enterprise context.
The paper's Goals, Signals, Metrics process starts with a goal, identifies a signal that indicates success, and then defines a metric. Its authors argue that a metric is unlikely to be useful unless it relates to a goal. Task success can include effectiveness, such as the percentage completing a task; efficiency, such as time to complete it; and error rate.
The artefact
| Goal | Signal | Metric | Collection and population |
|---|---|---|---|
| Visitors can reserve a unit on a phone | A started reservation reaches confirmation | generate_lead users divided by form_start users | GA4 closed funnel, mobile, complete weeks |
| Visitors can get through the reservation step | People who start do not reach confirmation | 1 minus the generate_lead to form_start rate | GA4 closed funnel, mobile, same period |
| Reservation controls respond when used | Clicks receive no feedback or trigger errors | Mobile sessions with dead clicks on /reserve divided by mobile sessions visiting /reserve; click errors as a separate rate | Clarity filters, reported separately by signal |
| The reservation feels manageable | People report ease immediately after an attempt | Mean Single Ease Question score, 1 to 7 | Post-task question in the phone test |
Completion and abandonment describe opposite sides of the same funnel step. Keep both if different people use the sheet, but do not mistake them for independent evidence. Clarity's session rate is a signal to investigate, not a count of distinct defects.
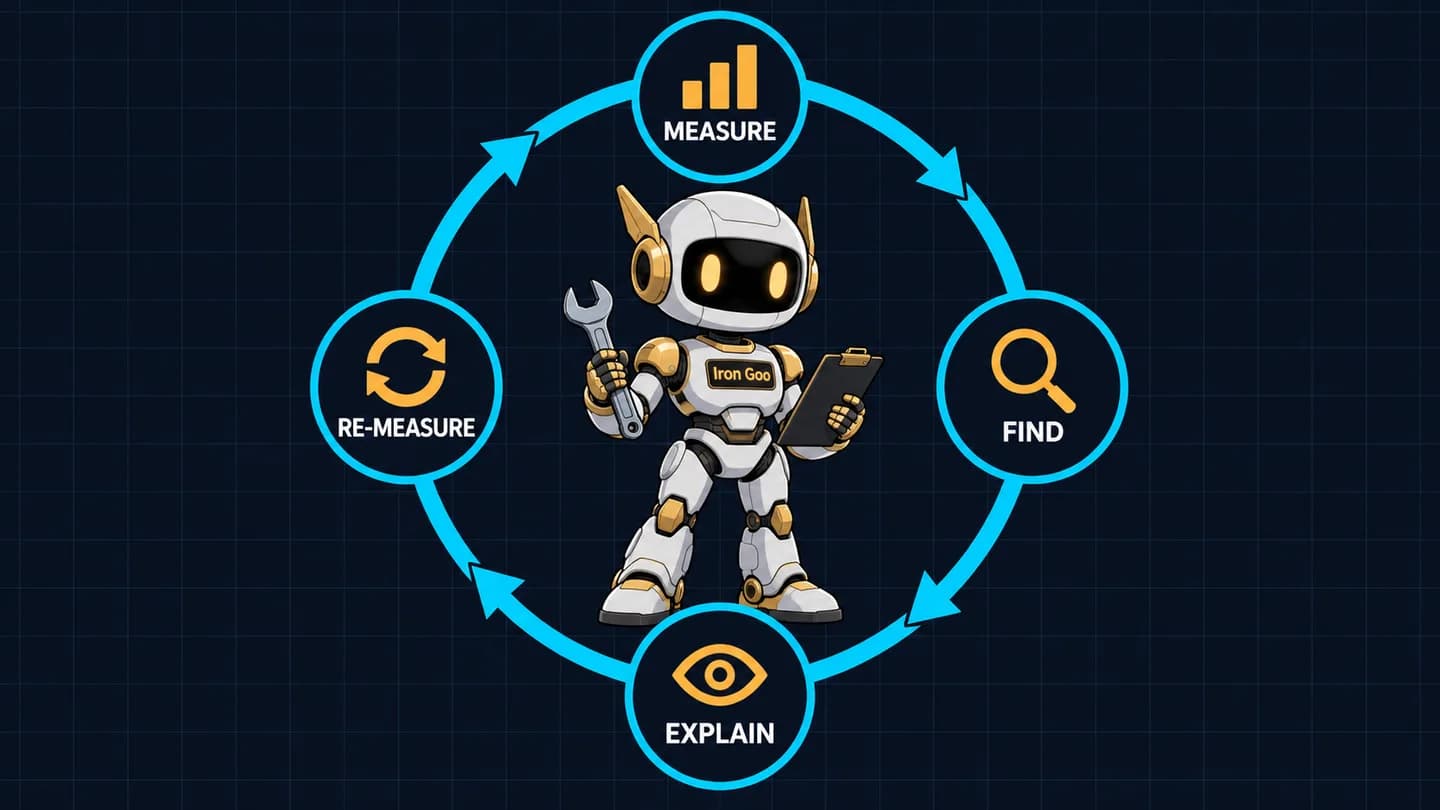
Follow the same reservation task around the loop. The measurement identifies a problem to investigate, and the later measurement checks the chosen fix.
Expected output
The team can name the confirmation state and explain exactly which visitors enter each calculation. For the hypothetical company, mobile generate_lead divided by mobile form_start measures completion among people who began the form. The SEQ records the participant's assessment of the task, including an unsuccessful attempt.
A reference can help you judge the question to ask next, but it cannot set a universal target. Jeff Sauro's task-completion analysis found an average of 78% across 1,189 tasks, mostly from lab tests. Observed lab participants and visitors moving through a web funnel are different populations, so 78% is a reference point, not a pass mark for the GA4 rate.
Bad result
A dashboard lists page views, session duration, and a satisfaction score without tying any of them to the reservation goal. Those numbers may describe activity, but they cannot tell you whether a visitor who started a reservation reached confirmation. A denominator that changes between reporting periods makes the apparent improvement equally hard to interpret.
Procedure 2: Build the reservation funnel in GA4
Run this
Confirm that generate_lead fires when the reservation is confirmed and designate it as the lead key event. Do not make form_submit the lead key event: a submission can occur before validation or booking succeeds. Reconcile confirmed reservations against the CRM or booking system, which is the count of record.
In GA4, open Explore, select Funnel exploration, and configure the four steps in the recipe. A funnel can have up to 10 steps. Choose a closed funnel so users enter at step 1, use indirectly followed by so other actions may occur between steps, and turn on elapsed time to see the average time between steps.
Break down the funnel by Device category and add the Next action dimension. Inspect the top next actions, including (no next action), at the steps where people leave. Use complete weeks for comparisons. The GA4 funnel exploration documentation describes the funnel settings; the conversion path setup gives the fuller form-path setup and ways to fix its steps.
The artefact
Exploration: Funnel exploration
Date range: Four complete weeks
Funnel type: Closed
Step transitions: Indirectly followed by
Elapsed time: On
Breakdown dimension: Device category
Next action dimension: Add and inspect Top 5 Next Actions

Step 1: event_name = page_view
        page path = /units

Step 2: event_name = page_view
        page path = /reserve

Step 3: event_name = form_start
        reservation form on /reserve

Step 4: event_name = generate_lead
        fired when the reservation is confirmed

Compare: Mobile and Desktop
Inspect: Step counts, completion and abandonment rates,
         average elapsed time, and (no next action)
Count of record: Confirmed reservations in CRM or booking system
Check the actual page path and event parameters used by your implementation when entering the conditions. A label in this recipe is not proof that an event fires at the right moment. Test a successful reservation and a validation failure, then check the events each attempt produced.
Expected output
For the hypothetical four-week baseline, the mobile funnel has the following counts. Each step rate divides that row's count by the previous row's count.
| Mobile step | Users | Rate from previous step |
|---|---|---|
/units page view | 2,400 | Entry |
/reserve page view | 960 | 40.0% |
form_start | 610 | 63.5% |
Confirmed generate_lead | 214 | 35.1% |
Overall, 214 of 2,400 entrants reach confirmation, or 8.9%. The reservation form step is the first place to investigate: 396 of the 610 mobile starters do not reach confirmation in this funnel, an abandonment rate of 64.9%. On desktop, 209 of 380 form starters reach confirmation, or 55.0%.
The device comparison gives you a reason to inspect the phone experience; it does not prove the cause. Elapsed time is an average between steps, so a few long attempts can affect it. (no next action) appears when many users at a step did not move on, but with a page dimension it can also mean the page value did not change, so it is not proof of a drop-off.
Bad result
generate_lead fires when someone clicks the reservation button, so attempts that fail validation count as successful reservations. The resulting completion rate can rise even while the form is broken. An open funnel also changes the population because visitors may enter at later steps, making its counts unsuitable for the closed-funnel baseline.
Procedure 3: Find reservation friction in Clarity
Run this
Open Clarity and filter recordings to mobile visitors who encountered dead clicks on the reservation page. Save the filter combination as a segment so another reviewer can reproduce it. Watch recordings in context and record what the visitor tried to do, what the page did, and whether the task continued.
Microsoft defines a dead click as a click on an element that produces no feedback within a reasonable time. A rage click is a cluster of rapid clicks in the same area. A quick back occurs when someone leaves for another page and returns under a time threshold based on that page's dwell time; excessive scrolling means more vertical scrolling than the expected average.
Click errors are JavaScript errors that occur after a click, and Clarity tags the sessions automatically. These signals are useful filters, not diagnoses. Microsoft's semantic metrics documentation defines the signals and their limits.
The artefact
Clarity segment: Mobile reservation dead clicks

User info > Device: Mobile
User actions > Insights: Dead clicks
Path > Visited URL: contains /reserve
Save as segment

Recording notes
Recording or session reference:
Page and control:
Visitor's apparent goal:
What happened after the click:
Could the visitor continue?
Other signal observed:
Question to check in a task test:
For a second pass, change the insight filter to Rage clicks or another signal and save or record that filter separately. Check click errors as well when investigating a control that appears unresponsive. Do not combine counts from different signal types and call the total a count of people who failed.
Expected output
In the hypothetical recordings, dead clicks cluster on the move-in date field. Notes show the field and the action preceding the signal, giving the team a specific control to put in front of test participants. The recordings do not yet establish whether the date picker is the only reason visitors abandon the form.
A useful notes sheet also contains counterexamples: recordings where the date control works and people continue. Those examples help distinguish a problem affecting some phones or conditions from a problem affecting every attempt.
Bad result
A report labels every rage click as an angry customer without watching the recording. Rapid clicks are a detected pattern; a recording is needed to understand what the person was trying to do and whether the pattern reflects a problem. A dead-click filter alone cannot tell you how many reservations the issue prevented.
Procedure 4: Ask about task ease and score the whole visit
Run this
Ask the Single Ease Question, or SEQ, immediately after each reservation attempt, including attempts that do not succeed. Use a seven-point scale with endpoints labelled from difficult to easy. Ask anyone scoring below 5 why they gave that answer, and record their explanation without supplying one.
Use the System Usability Scale, or SUS, after a session when you want a score for the whole visit. John Brooke created SUS in 1986 and published it as a book chapter in 1996. It has 10 statements and five response options, from strongly disagree to strongly agree; do not administer the whole scale for a single date field.
The artefact
Single Ease Question, immediately after the task attempt

Overall, how difficult or easy was the task to complete?

1  2  3  4  5  6  7
Very difficult       Very easy

If the answer is below 5: Why did you give that answer?


System Usability Scale, after the session

For each statement, choose a response from 1 to 5:
1 = strongly disagree; 5 = strongly agree.

1. I think that I would like to use this system frequently.
2. I found the system unnecessarily complex.
3. I thought the system was easy to use.
4. I think that I would need the support of a technical person
   to be able to use this system.
5. I found the various functions in this system well-integrated.
6. I thought there was too much inconsistency in this system.
7. I would imagine that most people would learn to use this system
   very quickly.
8. I found the system very cumbersome to use.
9. I felt very confident using the system.
10. I needed to learn a lot of things before I could get going
    with this system.
Some teams replace “system” with “website” when administering SUS. Keep the same wording across the sessions you intend to compare, and retain the order and five response options. The SEQ endpoint labels above explain the direction of the scale; they are not a claim that those are the instrument's exact prescribed labels.
For odd items: contribution = response - 1 For even items: contribution = 5 - response SUS score = sum of all 10 contributions × 2.5
Expected output
For the worked response set 4, 2, 4, 1, 4, 2, 5, 2, 4, 2, the odd-item contributions are 3, 3, 3, 4, 3, totaling 16. The even-item contributions are 3, 4, 3, 3, 3, also totaling 16. The sum is 32, and 32 × 2.5 = 80 on the 0 to 100 SUS scale.
Sauro reports that the average SUS score across 500 studies is 68, approximately a C. His SUS scoring explanation supplies the scoring method and reference. MeasuringU reports an average SEQ around 5.5, which is useful context for a task score rather than a guarantee about any particular task.
The score runs from 0 to 100, but it is not the percentage of people who succeeded or the percentage of usability achieved. A score of 68 is the reported average across 500 studies.
Bad result
The team reports a SUS score of 80 as “80% of visitors succeeded,” or averages only the SEQ answers from people who finished. The first changes the meaning of the scale; the second leaves out people whose difficulty may be most useful to investigate. Keep unsuccessful attempts in the task record and ask the ease question after each one.
Procedure 5: Check field performance on the task pages
Run this
Test /units and /reserve in PageSpeed Insights, then inspect mobile and desktop results separately. Record whether the field data applies to the URL, falls back to the origin, or is unavailable. Read the field measurements before treating a Lighthouse score as evidence of what visitors experience: Lighthouse is a lab measurement.
At the 75th percentile, good Largest Contentful Paint, or LCP, is 2.5 seconds or less; over 4.0 seconds is poor. Good Interaction to Next Paint, or INP, is 200 milliseconds or less; over 500 milliseconds is poor. Good Cumulative Layout Shift, or CLS, is 0.1 or less; over 0.25 is poor.
Open the Core Web Vitals report in Search Console too. It groups similar indexed URLs, and the group status is the slowest status for that device type. A group needs threshold data for both LCP and CLS to appear. The Search Console report documentation explains the grouping and validation process.
The artefact
Core Web Vitals check

[ ] Enter /units in PageSpeed Insights.
[ ] Enter /reserve in PageSpeed Insights.
[ ] Record field data scope for each: URL, origin, or none.
[ ] Record mobile and desktop separately at the 75th percentile.
[ ] Record LCP: good <= 2.5 s; poor > 4.0 s.
[ ] Record INP: good <= 200 ms; poor > 500 ms.
[ ] Record CLS: good <= 0.1; poor > 0.25.
[ ] Record the Lighthouse score as a lab result.
[ ] Check Search Console mobile and desktop URL groups.
[ ] Record affected groups and their reported status.
[ ] After a fix, use Start Tracking for the 28-day monitoring session.
The mobile performance guide explains the individual Web Vitals terms and fixes. If the fault sits in a shared template, such as a slow script or broken form component, a site rebuild is one possible route to fixing it.
Expected output
In the hypothetical example, /reserve has mobile field INP of 380 milliseconds, in the needs-improvement range. The date picker script is suspected, and the team can investigate it alongside the recording and task-test evidence. The field result points to interaction latency; it does not establish which script caused it by itself.
After changing the component, use Start Tracking in Search Console for its 28-day monitoring session. Preserve the original field scope and device category in the record so the later reading is comparable. Origin-level data can be useful context, but it is not a page-specific measurement.
Bad result
A green Lighthouse score is presented as proof that customers have a good experience, or a small site is declared fast because PageSpeed Insights has no field data. A lab score and missing field data answer different questions. If URL and origin field data are unavailable, record that absence and use the other observations to investigate the task.
Procedure 6: Watch five people attempt the task
Run this
Recruit five people who resemble the visitors expected to reserve a unit on a phone. Give each person the same goal, let them attempt it on a phone, and observe the actions and outcome. Ask the SEQ immediately after each attempt, including a failed attempt.
Do not name the control you suspect in the task instructions. The five-user research method provides the test procedure and the arithmetic behind using five comparable participants. The purpose here is to explain the observed funnel and recording signals with direct observations.
The artefact
Task card

You need storage at the north facility. Reserve a 5x10 unit
for a move-in date next Saturday using your phone.

Observer record
Participant:
Attempt completed: Yes / No
Could set move-in date: Yes / No
Actions and page response:
Where the attempt stopped:
Assistance given, if any:

Immediately after the attempt:
Overall, how difficult or easy was the task to complete?
Score from 1, very difficult, to 7, very easy:
If below 5, ask why:
Keep the task card focused on the outcome. Record assistance if you give it, since an assisted completion is different evidence from an independent completion. Write down what happened at the date field before discussing a possible fix.
Expected output
In the hypothetical test, three of five people cannot set the move-in date on a phone. Their SEQ scores are 6, 4, 3, 5, 2: the sum is 20, so the mean is 20 / 5 = 4.0. That is below the reported approximate average of 5.5 and supports investigating the date control.
Five observations do not estimate the site's exact failure rate. They do provide a concrete account of what participants tried and where their attempts stopped. Compare those observations with the mobile funnel and Clarity recordings before deciding which component to change.
Bad result
The task says “tap the calendar button and select a date,” directing everyone to the control under investigation. Successful completion under those instructions does not establish that visitors can find and use the control unaided. A test in which an observer supplies the next step needs that assistance recorded.
Procedure 7: Rank problems with three evaluators
Run this
Give three evaluators the same problem descriptions and evidence. Ask each to rate impact and persistence on the 0 to 4 scale, then calculate the mean. Separately assign an observed frequency score: 1 for rare, 2 for some, and 3 for most of the test users or sessions you reviewed.
Jakob Nielsen's severity rating article, dated 1 November 1994, describes severity as a combination of frequency, impact, and persistence, with market impact also relevant. Nielsen says a single evaluator's ratings are too unreliable and recommends the mean of three evaluators. His scale labels are:
0  I don't agree that this is a usability problem at all
1  Cosmetic problem only
2  Minor usability problem
3  Major usability problem
4  Usability catastrophe
The multiplication in the following sheet is Iron Goo's convention, not Nielsen's method. Because Nielsen's severity already includes frequency, evaluators using this sheet rate impact and persistence only; the separate frequency score is then applied once. Record the observed basis for frequency so “most” means most of a named set, not a guess about all customers.
The artefact
| Hypothetical problem | Rater 1 | Rater 2 | Rater 3 | Mean | Observed frequency score | Mean × frequency |
|---|---|---|---|---|---|---|
| Date picker prevents setting move-in date | 3 | 4 | 3 | 3.33 | 3 | 10.0 |
| Unit size labels such as 5x10 have no picture | 2 | 2 | 3 | 2.33 | 2 | 4.67 |
| Banner shifts the page layout | 1 | 2 | 1 | 1.33 | 2 | 2.67 |
Calculate from the unrounded mean, then round the displayed result. For the date picker, (3 + 4 + 3) / 3 × 3 = 10.0. Keep the evidence alongside the sheet, including which test users or reviewed sessions support each frequency score.
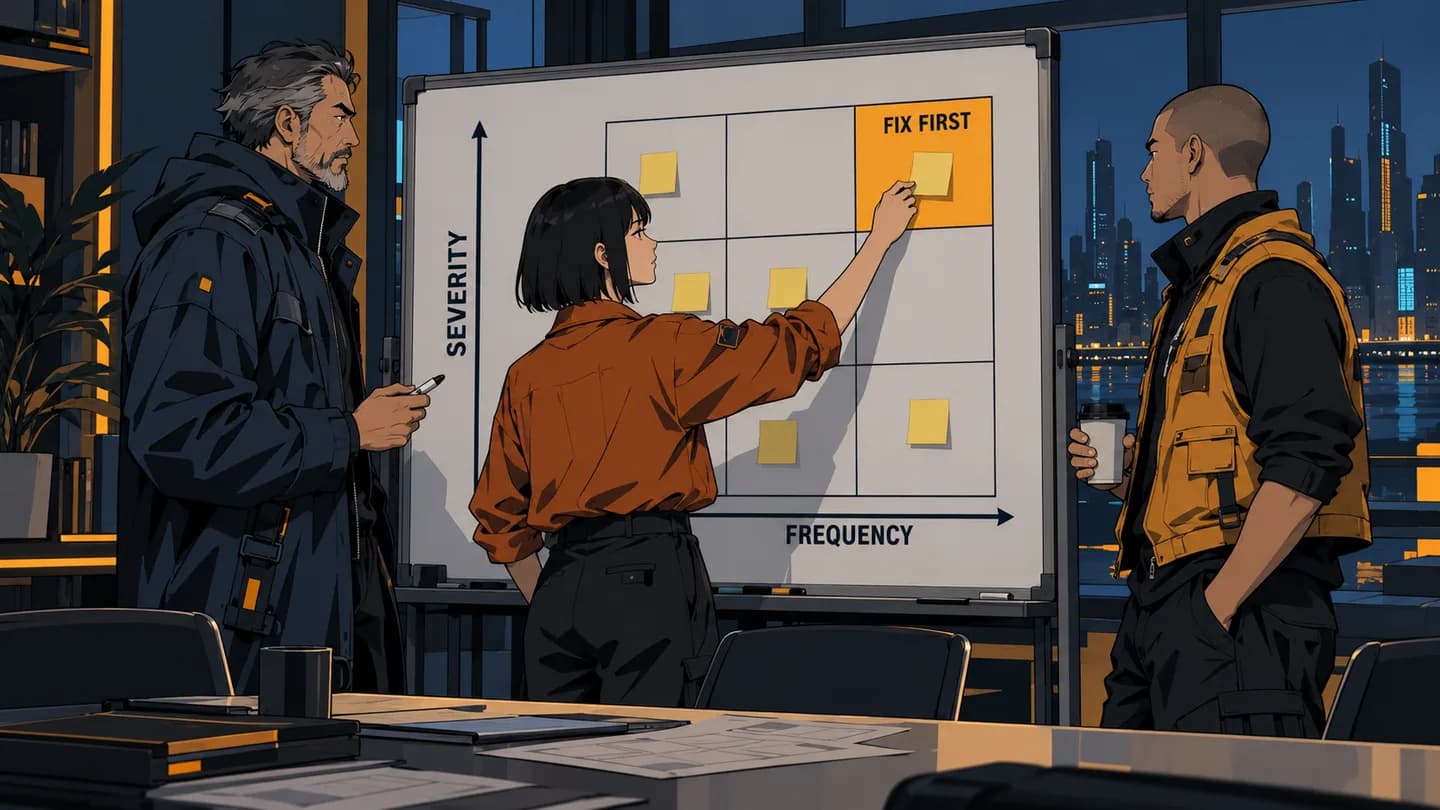
Notice how problems with higher severity and frequency move toward the top right. The three raters' assessments inform the sheet, and the highest-priority problem is fixed first.
Expected output
The hypothetical date picker ranks first at 10.0, so the team fixes that row first. The missing size pictures rank second and the banner shift third. The sheet makes the decision reviewable: another person can see the individual ratings, the frequency score, and the calculation.
The score is an ordering aid, not a precise estimate of revenue or a substitute for judgment. If a problem has an exceptional market impact or prevents the reservation entirely, discuss that evidence alongside the calculated order. Keep the raters' disagreement visible rather than recording only the mean.
Bad result
One person assigns a severity score that already includes frequency and then multiplies it by frequency again. The same evidence has been counted twice. A sheet with three identical ratings copied from one evaluator also does not provide three independent assessments.
Procedure 8: Re-measure the fix across complete weeks
Run this
In the hypothetical example, replace the date picker with a native date input and annotate the fix date. Set the comparison period before inspecting the result, wait at least four complete weeks, and compare complete weeks with matched weekdays. Check that the event definitions and traffic mix did not change, and use desktop as an unchanged comparison.
Use the same closed funnel, device breakdown, and confirmation-state generate_lead definition as the baseline. Check the booking system counts as well. Then compare the mobile form-start-to-confirmation rate and run both the interval calculation and the count sense check.
The artefact
Fix record
Change: Replace date picker with native date input
Fix date and annotation:
Baseline: Four complete weeks before the change
Follow-up: At least four complete weeks after the change

Comparison checks
[ ] Weekdays match across periods.
[ ] form_start definition is unchanged.
[ ] generate_lead still fires on confirmed reservation.
[ ] CRM or booking counts remain consistent with the event.
[ ] Mobile traffic mix has been checked for changes.
[ ] Desktop funnel rate is recorded as an unchanged comparison.
[ ] Baseline and follow-up counts and rates are recorded.
[ ] Interval and square-root count checks are calculated.
[ ] Five new users attempt the task and answer the SEQ.
p = completions / form starts interval = p ± 1.96 × sqrt(p × (1 - p) / form starts)
The Wald interval is a rough normal approximation, not a promise that the true rate sits inside a particular interval. Calculate it separately for each period using that period's starts and completions. The guide to reading data without fooling yourself explains small samples, matched weeks, and why repeatedly checking a running result inflates false positives.
Expected output
Before the hypothetical fix, 214 / 610 = 35.1%, with an approximate interval of 31.3% to 38.9%. In the next four complete weeks, 301 / 590 = 51.0%, with an approximate interval of 47.0% to 55.1%. Desktop stays near 55%, providing a useful comparison while not proving that every other condition stayed constant.
For a second, rough count check, apply the old rate to the 590 follow-up starts: 0.3508 × 590 gives about 207 expected completions. The square root of 207 is about 14, giving a rough band of 193 to 221; the observed 301 is far outside it. This square-root rule is a sense check for counts under stable conditions, not a significance test.
Finally, give the same task to five new users and ask the SEQ after each attempt. Record their scores and whether they can set the date without assistance. The funnel tells you what changed at scale; the new attempts check whether people can now use the control that was fixed.
Bad result
The team declares victory after one good week, checks the running number every day until it looks favorable, or compares a new event definition with the old one. Repeated unadjusted checks inflate false positives, and a changed event can manufacture a change in the rate. If traffic mix or tracking changed, record the difference and investigate it before attributing the result to the date input.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.