How to Make Your Website AI Agent Friendly

On this page
- What is an AI agent visiting my website?
- How do AI agents actually read a page?
- Should I block AI agents in robots.txt?
- Are the AI agents in my logs real?
- Do CAPTCHAs and bot protection block legitimate agents?
- How do I make forms and checkout work for AI agents?
- How do I test whether an agent can finish my booking?
- Do I need WebMCP, an MCP server or llms.txt?
- Does structured data help AI agents?
- Can I see AI agent traffic in GA4?
- Who is responsible when an AI agent books or buys for someone?
- What should the final purchase confirmation look like?
- Should I worry about prompt injection on my own pages?
UX
To make your website AI agent friendly, design for software acting on a person's behalf. An agent may interpret a screenshot, inspect the page's HTML, or read its accessibility tree, so a control that looks obvious to a person also needs a usable structure and name.
Much of that work overlaps with accessibility. Two further decisions deserve attention: how you verify that a request claiming to be an agent is real, and how the person confirms a purchase that the agent has prepared. The three ways browser agents read a page explain the screenshot, DOM and accessibility tree approaches.
What is an AI agent visiting my website?
An AI agent is software that performs a task for a person, such as finding an appointment or preparing an order. Google describes AI agents as autonomous systems that can perform tasks on behalf of people.
That purpose differs from a crawler collecting pages for search or training. OAI-SearchBot supports ChatGPT search, GPTBot is used for foundation-model training, Claude-SearchBot supports search quality, ClaudeBot supports training, and PerplexityBot surfaces sites in search.
A user-triggered fetcher or agent acts in response to a person's request. ChatGPT-User fetches on that basis, Claude-User retrieves content when people ask Claude questions, and Perplexity-User supports user actions. Google's documentation says: “Google-Agent is used by agents hosted on Google infrastructure to navigate the web and perform actions upon user request.”
A user-agent name is a claim in a request header. It tells you what the requester says it is; it does not prove who sent the request.
How do AI agents actually read a page?
Agents can read a page through screenshots, the DOM, or the accessibility tree, depending on the agent. A control that works through one route can still fail through another.
Anthropic's computer use tool sees the screen through screenshots and acts using pixel coordinates. It has a zoom action for small text or dense interfaces that are hard to read in a downscaled screenshot. A covered control, a tiny target or a layout that shifts between the screenshot and the click can therefore interrupt the task.
DOM and accessibility tree readers need controls with names and roles they can determine. The accessibility tree exposes a browser's semantic representation of the page, including information used by assistive technology. As web.dev's agent design advice puts it, agents do not look at your website on a monitor.
Should I block AI agents in robots.txt?
Use robots.txt to express your preferences for crawlers, and check each vendor's rules before assuming it controls a user-triggered agent. Some vendors say a person's request changes whether their fetcher follows those rules.
OpenAI says robots.txt rules may not apply to ChatGPT-User because its actions are initiated by a user. Google says its user-triggered fetchers generally ignore robots.txt, and Perplexity-User generally ignores it. Anthropic says disabling Claude-User prevents its system from retrieving your content in response to a user query.
Vendor documentation was read on 30 October 2026. The verification column identifies where to start checking identity; a user-agent string alone is not verification.
| Agent or bot | Operator | Acts for | Robots.txt per the vendor | Where to verify |
|---|---|---|---|---|
| ChatGPT-User | OpenAI | A user's request | Rules may not apply | openai.com/chatgpt-user.json |
| OAI-SearchBot | OpenAI | ChatGPT search | Honors crawler rules | OpenAI's published IP list |
| GPTBot | OpenAI | Model training | Honors crawler rules | OpenAI's published IP list |
| Claude-User | Anthropic | A user's question | Honors rules | Anthropic's published IP list |
| Claude-SearchBot | Anthropic | Search quality | Honors rules | Anthropic's published IP list |
| ClaudeBot | Anthropic | Model training | Honors rules | Anthropic's published IP list |
| Perplexity-User | Perplexity | A user's action | Generally ignores rules | www.perplexity.ai/perplexity-user.json |
| PerplexityBot | Perplexity | Search, not training | Honors crawler rules | Perplexity's published IP list |
| Google-Agent | A user's requested action | Generally ignores rules | user-triggered-agents.json or Web Bot Auth signature | |
| Google-Extended | Gemini training and grounding | Product token for controlling use | Not a fetcher; no separate request to verify |
Google-Extended does not control AI Overviews, and it is a different token from Google-Agent. The crawler robots.txt rules and verification script are useful when you are setting search and training preferences. OpenAI explains its crawler distinctions in its bot documentation, and Anthropic documents how its three bots use site content.
Are the AI agents in my logs real?
Some may be real, but the name in the user-agent field is not enough to establish identity. Check the source address against the operator's published ranges or verify a supported signature before granting an exception.
Iron Goo's own nginx access logs show why this matters. From 16 October 2026 at 00:00 UTC to about 02:45 UTC on 30 October 2026, 216 requests claimed ChatGPT-User, and five came from OpenAI's published ChatGPT-User ranges. The other 211 did not.
There were also 187 requests claiming Claude-User and 209 claiming Perplexity-User. None came from the respective vendors' published ranges, and there were zero requests claiming Google-Agent. These are request counts, not visit counts.
The method was a user-agent substring match followed by a source-address check against vendor IP lists fetched on 30 October 2026. A firewall rule that allows every request containing ChatGPT-User would have allowed the 211 unverified claimants in this sample. Keep your vendor lists current and treat a match as an identity check, not permission for unlimited requests.
Do CAPTCHAs and bot protection block legitimate agents?
They can interrupt an agent, depending on the challenge and the agent's behavior. Anthropic says its bots will not attempt to bypass CAPTCHAs on sites they crawl. Whether a given agent hands a CAPTCHA back to its person is not documented in the vendor material we read.
Cloudflare's Verified bots include bots and agents whose identity and purpose Cloudflare has confirmed. According to Cloudflare's Verified bots documentation, verification can use a Web Bot Auth signature, a published IP list with a stable user agent, or reverse DNS. The Direct versus Intermediary access field matters: an intermediary can act for different end users, so trusting the intermediary does not establish that every end user is trustworthy.
Web Bot Auth uses HTTP message signatures: Signature-Input carries the web-bot-auth tag, Signature carries the signature, and Signature-Agent points to a public key directory at /.well-known/http-message-signatures-directory. It uses Ed25519 keys and builds on RFC 9421; the Web Bot Auth specifications are Internet drafts. Cloudflare validates these signatures by default; turning validation off for a zone requires a request to Cloudflare Support. Google is experimenting with the https://agent.bot.goog identity.
Cloudflare marked its legacy Block AI bots toggle as deprecating on 15 September 2026. From that date, Cloudflare says new domains block Training and Agent bots on pages with ads by default. Agents acting for a person have their own Agent preset in AI bot policies, so check that preset before assuming what your site permits.
Our rule is to place challenges on login, signup and high-volume form posts, where abuse is a practical concern. Keep price, service and booking pages accessible to verified agents, and rate-limit other traffic according to your site's needs.
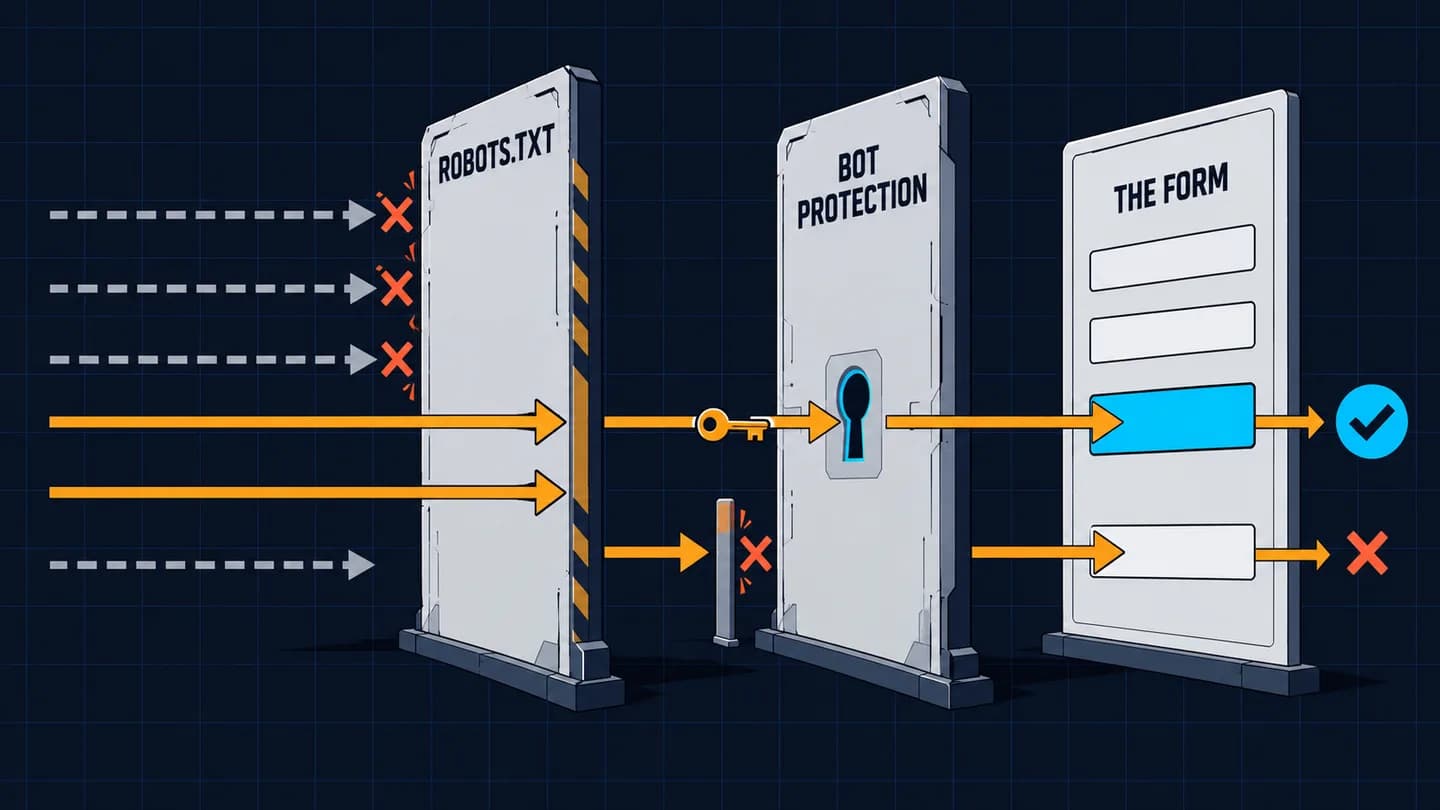
Notice the separate gates: robots.txt gives crawlers instructions, while bot protection and the form determine whether a user-triggered agent can proceed.
How do I make forms and checkout work for AI agents?
Use native HTML controls with clear names, visible labels and predictable behavior. A booking slot should expose a button, and an email field should expose both its label and its purpose.
For a hypothetical appointment form, compare these controls:
<!-- A div with a click handler has no native button role or clear name. -->
<div class="slot" onclick="selectSlot()">10:00</div>

<!-- The button exposes its role and a specific accessible name. -->
<button type="button" aria-label="Wednesday 4 November, 10:00, available">
  10:00
</button>

<label for="booking-email">Email address</label>
<input id="booking-email" name="email" type="email" autocomplete="email">
Use <a href> for links, <select> where a native selection fits, and appropriate input types and autocomplete tokens. Avoid transparent overlays over controls and keep the layout stable. Our reading is to avoid hover-only menus too: a person or agent using keyboard or click actions needs another way to open them.
WCAG 2.2 success criterion 4.1.2, Name, Role, Value, is Level A. It requires component names and roles to be programmatically determinable, user-settable states, properties and values to be programmatically settable, and changes to be available to user agents, including assistive technology. Our reading is that this is also useful information for agents inspecting page structure. Use the accessibility and inclusive design checklist for the wider audit.
How do I test whether an agent can finish my booking?
Test the booking as a sequence of observable actions, including the final confirmation. You can find many structural failures with browser tools and a keyboard before trying a specific agent.
- Inspect the main booking and final confirm buttons in your browser's accessibility pane. Each should have a meaningful accessible name and a button role.
- Complete the form using only the keyboard. Check that focus is visible, every required field is reachable, and errors identify the field that needs attention.
- Open the page at 390 CSS pixels wide. Check that banners, transparent layers and sticky controls do not cover the booking controls.
- Inspect the rendered HTML for the price and available appointment information. They should be present as text that can be selected and read, with the same values shown visually.
- Reach the last step and check for a named confirmation button, such as “Confirm booking,” alongside the price and cancellation terms.
Run the same checks after a booking widget or consent banner changes. If you want help making a site and booking flow legible to assistants and browser agents, Iron Goo offers AI optimization for AI search and agents.
Do I need WebMCP, an MCP server or llms.txt?
No. A usable site does not depend on any of those three, and WebMCP is still a draft.
WebMCP is a Draft Community Group Report dated 27 October 2026, not a W3C Standard. It lets a web application offer JavaScript-based tools to agents through document.modelContext and registerTool(). Chrome has an origin trial, and the API is in active development and may change.
MCP connects AI applications to tools and data. In our opinion, an MCP server becomes a sensible product decision when you already have a real booking or inventory API and a reason to expose controlled actions through it. It is not a prerequisite for an agent to use a well-built booking page.
Google Search says it does not use llms.txt. Ahrefs found that 97% of the llms.txt files in its study received no requests during May 2026. No major AI search provider documents reading the file, so prioritize usable pages and forms before creating another file to maintain.
Does structured data help AI agents?
Structured data remains useful for SEO, but a general benefit to browser agents is not documented in the sources we read. Google says generative AI search needs no special schema.org markup.
Keep your existing structured data accurate and consistent with visible page text. A price in markup that disagrees with the price a person sees creates a problem for anyone relying on the page. The structured data guide explains how to check that alignment.
For sellers, Google's Universal Commerce Protocol uses Merchant Center feeds for its supported commerce flow. That is a specific integration, not evidence that adding schema alone makes an arbitrary agent complete a purchase. Google describes its search requirements in its AI optimization guidance.
Can I see AI agent traffic in GA4?
GA4 is not a complete count of agents visiting your site. Known bots are excluded, and a fetcher that does not run JavaScript cannot send a GA4 event.
The AI Assistant channel measures people arriving from assistant sources, not agents acting on their behalf. Find it under Reports > Acquisition > Traffic acquisition, using the Session default channel group dimension. Google's Analytics channel definitions put clicks from AI Overviews and AI Mode in Organic Search.
A browser agent running a real browser may execute your analytics tag and appear as an ordinary session. That is our inference, and we have not tested it. GA4 does not show how much known-bot traffic it removes.
Use server logs to count requests and examine their user-agent fields, timestamps, requested paths and response status codes. Then verify the claimed agent against the vendor's published IP ranges or a supported signature. A request count tells you how often the server was contacted; it does not tell you how many people completed a booking.
Who is responsible when an AI agent books or buys for someone?
The merchant can still be responsible for the transaction when an agent helps a person buy. Google's UCP and the Agentic Commerce Protocol both keep the business as merchant of record.
Google's UCP merchant documentation describes direct buying in AI Mode and Gemini, with merchants joining through a waitlist and reusing Merchant Center feeds. Stripe and OpenAI developed the Agentic Commerce Protocol; its Shared Payment Token passes payment credentials without exposing them. The protocol page does not describe how buyers authorize agents.
AP2 addresses evidence of authority through tamper-evident, cryptographically signed Checkout and Payment Mandates. Those records are designed to show what authority a user gave for a particular purchase.
Amazon sued Perplexity over its Comet browser agent in November 2025. A district court granted a preliminary injunction on 9 March 2026, but the order was put on hold for the appeal, and the Ninth Circuit vacated it, as Engadget reported on 4 August 2026, reasoning that the Comet user was the one accessing Amazon's computers. The case is not closed, and that preliminary ruling does not settle the wider question.
Unknown: whether an agent clicking “I agree” binds the person, and who carries a chargeback for an agent's mistaken purchase outside a protocol. This is not legal advice.
What should the final purchase confirmation look like?
Show the person an order summary with the price and cancellation terms as text, then ask for a clearly named confirmation. Send the confirmation email to the person and make cancellation easy.
That is our recommendation for a commit step after an agent has prepared the order. It gives the person a chance to inspect what will happen before the action has financial consequences.
Anthropic gives developers building agents this advice:
Asking a human to confirm decisions that might result in meaningful real-world consequences and any tasks requiring affirmative consent, such as accepting cookies, completing financial transactions, or agreeing to terms of service.
The advice is a design recommendation, not a law. Apply the same care when a chatbot or other AI feature on your own site prepares an action for a customer.
The agent can fill in the order details, while the person reviews the price and terms before confirming the purchase.
Should I worry about prompt injection on my own pages?
Yes. Instructions embedded in a page or image can attempt to steer an agent away from the person's request, and agent vendors scan for potential attacks.
Anthropic warns that page or image instructions might override a user's instructions or cause mistakes. Its computer use documentation says classifiers scan screenshots for potential prompt injections.
Keep page instructions visible and relevant to the task a person is performing. Never hide agent-directed instructions in invisible text. Check third-party widgets and user-submitted content as well as your own page copy, particularly where they appear beside forms or purchase controls.

Put your next steps in order
Build on what you have just read with a free ebook on semantic SEO and AI visibility. Get worked examples, decision rules, checklists and a do-this-week action in every chapter, plus a six-week plan for your site.